Results for “Robot”

Tech.eu Cate Lawrence Startups

Ukrainian drone engineering meets German manufacturing as QFI ramps up production

Quantum Systems and Frontline Robotics are expanding their industrial cooperation through a programme for long-term support capacity in Ukraine aimed at systems developed by Frontline Robotics and pro...
Read at Tech.eu

Semiconductor Digest Shannon Davis

Boston Dynamics & GlobalFoundries Expand Robotics Collaboration

Boston Dynamics, the global leader in mobile robotics, and GlobalFoundries(opens in new tab) (GF), a manufacturer of essential semiconductors, today announced an expansion of their collaboration to deploy Spot for autonomous enterprise asset management across GF’s global semiconductor fabs.

Read at Semiconductor Digest

9to5Mac Sponsored Post

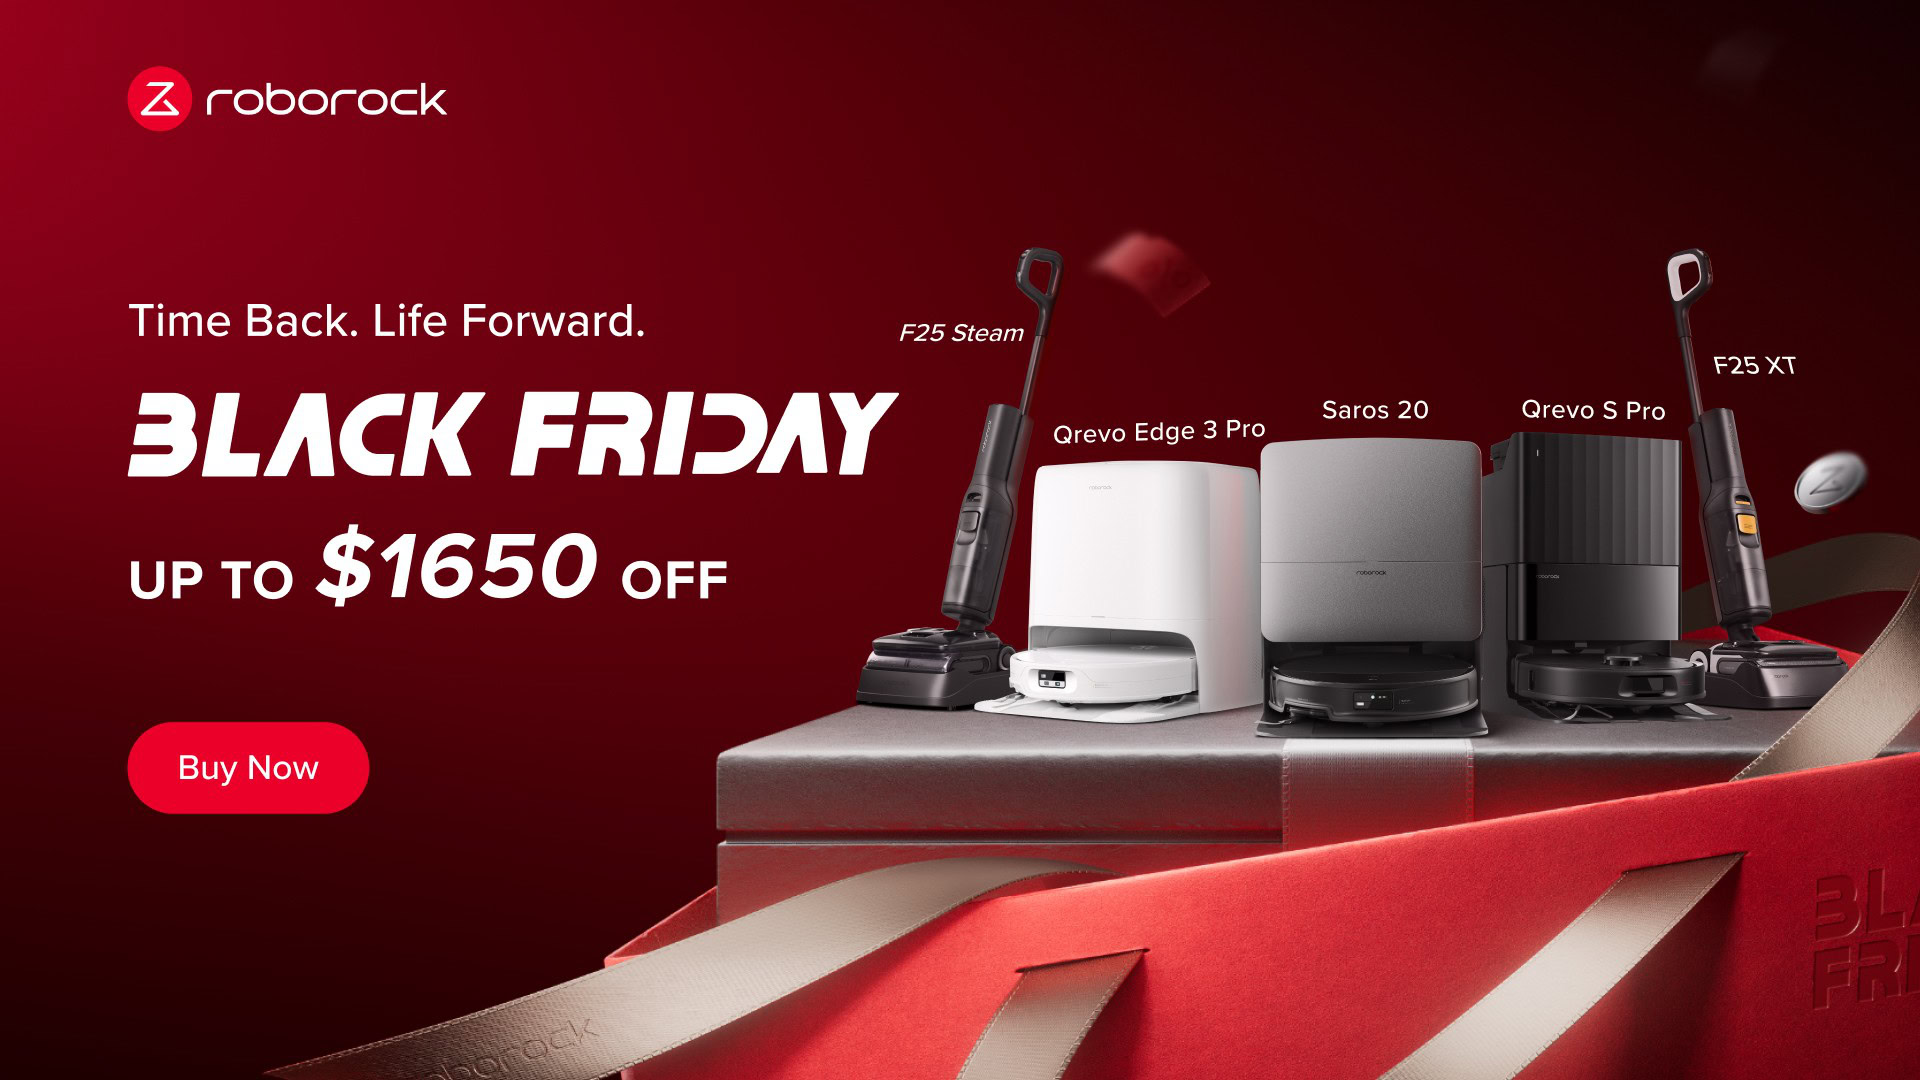
Roborock’s Black Friday deals make smarter cleaning more affordable than ever

Cleaning our homes is never going to make anyone’s list of favorite activities, but with the right technology, the task can be made almost effortless. Whether you’re looking for an affordable robot vacuum for a small apartment or the ultimate flagship model capable of coping with the challenges of a large home, pet hair, and more, there’s a Roborock model for you – and with Black Friday savings of up to $1,650, there’s never been a better time to buy.

Read at 9to5Mac

The Spoon (food tech) Michael Wolf

Vale Wants to Turn the PNW into the Napa of Matcha, Complete With Robots

While my kids have always loved matcha, I’ve viewed drinks made from the fine green powder much the same way I view cilantro: as having a flavor that a person

Read at The Spoon (food tech)

arXiv (research papers) Yiyang Du

AgentRoboCritic: Understanding the Capability of Frontier Agents on Direct Robot Control

Frontier multimodal language agents such as GPT-6 Astra have demonstrated strong capabilities in controlling robots directly via low-level numerical actions without high-level primitives. However, existing benchmarks report only episode-level success rates, which show neither how these agents succeed nor where they fail. In this paper, we present a systematic action-level analysis of frontier agents on direct robot control across 12 manipulation benchmarks. We introduce…

Read at arXiv (research papers)

arXiv (research papers) Onur Beker

A Tutorial on Complementarity-Based Contact Models for Robotics

Simulating rigid-body dynamics with contact is fundamental to robotics, from motion synthesis and control to mechanism design. Many widely used simulators rely on cone complementarity formulations, whose physical assumptions and numerical solution require substantial background. While excellent surveys, monographs, and course notes exist, they mostly address computational mechanics or computer graphics or document a single simulator. To the best of our knowledge, a…

Read at arXiv (research papers)

arXiv (research papers) Kai Lu SI

PGX: Physically Grounded Execution for Long-Horizon Humanoid Loco-Manipulation

Robotic vision-language-action (VLA) models can execute diverse individual manipulation skills, yet they still struggle with long-horizon loco-manipulation tasks, where temporal structure, skills, and precision are tightly coupled within a monolithic model. We propose Physically Grounded Execution (PGX), a framework that offloads temporal and precision control to two classical training-free components, allowing the VLA to focus on stage-specific skill dynamics. PGX…

Read at arXiv (research papers)

arXiv (research papers) Hao Vo

PhyDEX: A Benchmark for Physical Reasoning in Vision-Language-Action Models via Dynamic Extrinsic Dexterity

Vision-Language-Action (VLA) models have advanced rapidly in language-conditioned robotic manipulation, yet existing benchmarks mainly evaluate gripper--object contact and largely ignore how objects interact with the environment through gravity, friction, inertia, and mass distribution. As a result, it remains unclear whether current policies truly understand physics or merely interpolate from their training data. We address this gap through the lens of dynamic extrinsic…

Read at arXiv (research papers)

arXiv (research papers) Yinhe Wang

ACE-Brain-0.7: Learning Execution-Grounded Reasoning for Embodied Agents

Reliable reasoning for long-horizon embodied tasks requires predictions grounded in the observed execution state. We present ACE-Brain-0.7, a 9B vision--language model that combines spatial grounding, task understanding, and progress estimation. To train the model, we curate 3.7 million question--answer pairs, drawing execution supervision from egocentric human videos, robot episodes, and simulation. These questions span different stages of an execution and connect…

Read at arXiv (research papers)

arXiv (research papers) Shibo Zhou

JARVIS: An Agent That Designs, Builds, and Tests Circuit Boards on Its Own

Power electronics is central to the energy transition, but developing new hardware still relies on human-led design, fabrication, testing, and iteration. We present JARVIS, an embodied AI agent that autonomously closes this loop for circuit boards. JARVIS maintains machine-specific capabilities and constraints, scans its workspace using a robot-mounted 3D scanner, and constructs an executable digital twin in which it rehearses robot motions, fabrication steps, and circuit…

Read at arXiv (research papers)

arXiv (research papers) Yuzhi Huang SI

Mind2Act World: A Diagnostic Benchmark for Embodied Mind, Physical Action, and Mind-Action Composition in Robotic Manipulation

Embodied intelligence aims to let robots perform complex physical tasks with human-like adaptability and reliability, which requires three complementary capabilities: history-based cognitive reasoning, precise and timely physical execution, and the composition of reasoning and execution through environmental feedback. Yet existing benchmarks either evaluate reasoning and execution within the same tasks or assess them separately without their composition, so they reveal…

Read at arXiv (research papers)

arXiv (research papers) EngineAI

Awaken-HI: Scaling Humanoid Intelligence with Whole-Body Human Experience

A central goal of humanoid robotics is for robots to perform the everyday work people do in homes and workplaces. Existing egocentric video datasets cover many of these activities but provide little synchronized whole-body motion data for learning loco-manipulation at scale. We build Awaken-Human, which pairs approximately 50,000 hours of egocentric stereo video with synchronized whole-body human motion and covers more than 100 skills. Building on this, we also introduce…

Read at arXiv (research papers)

9to5Google Sponsored Post

Roborock’s Black Friday deals save over $1650 on select robot vacuums

Roborock has launched its Black Friday 2026 deals with some killer discounts including up to half off select models, and over $1650 off its flagship offering.

Read at 9to5Google

arXiv (research papers) Ziyue Wang

Alignment Drives Reuse: Learning Generalizable Robot-Use Agents from Heterogeneous Experience

Vision-language models (VLMs) demonstrate broad generalization across tasks and domains. However, comparable generalization in robot manipulation remains challenging. Heterogeneity in robot embodiments, task formulations, geometric conventions, and action interfaces fragments interaction experience across benchmarks and hardware. We rethink robot skill learning through alignment: Can heterogeneous interactions across benchmarks and embodiments jointly improve one shared…

Read at arXiv (research papers)

arXiv (research papers) Mahika Vats

PUPPET: Physical-Unified Platform for Presence, Embodiment, and Teleoperation

Remote access to robotics hardware does not by itself guarantee usable experimental data. A teleoperated trial can complete the task and still produce an incomplete or inconsistent record. PUPPET aims to solve this problem by presenting a cyber-physical framework that opens a physical robotics laboratory through a continuously synchronized VR replica of the robot, stranding environment, and task objects. In addition, PUPPET integrates a trial validation pipeline built into…

Read at arXiv (research papers)

arXiv (research papers) Zilang Cen

Reasoning on Call: Efficient Agentic Robot Control for Long-Horizon Robot Manipulation

Large multimodal models can support long-horizon robot manipulation, but frequent model calls incur substantial latency and token costs. The central challenge is determining when agent assistance or intervention is needed and whether errors require correcting robot execution, subtask planning, or both. To address this problem, we propose RoC (Reasoning on Call), an efficient framework that coordinates a low-level policy and a high-level reasoning agent through an online…

Read at arXiv (research papers)

arXiv (research papers) Jonathan Lichtenfeld

I See You: Initial Multi-Robot LiDAR Registration with Mutual-Observation Checks

Compared to single-robot deployments, multi-robot teams can significantly improve search-and-rescue (SAR) mission success by covering large areas in parallel. To collaborate effectively, these robots must be registered in a common reference frame. Standard registration methods typically rely on external infrastructure or significant map overlap, but real deployments require infrastructure-free, stationary initial alignment for immediate operation. While global LiDAR point…

Read at arXiv (research papers)

arXiv (research papers) Zheyuan Liu

Teaching Vision-Language-Action Models to Stop Safely

Vision-language-action (VLA) models enable robots to perform diverse tasks from visual observations and language instructions. While prior work has explored task suppression and refusal, stopping prohibited behavior once execution is underway and controlling the resulting physical response remain challenging. Our evaluation reveals that policies which suppress a task from its initial state can still complete it when taking over partway through execution. Even when the task…

Read at arXiv (research papers)

arXiv (research papers) Wei Dai

EmbodyAgent: Post-Training Embodied VLM Agents via Distillation, SFT, and RL

Vision-language models (VLMs) can act as closed-loop robot-use agents (RUAs) by writing and executing control code through tool interfaces. However, turning an open-weight VLM into a high-performing embodied agent requires a complete post-training stack: out-of-the-box open VLMs fail completely at interactive tool contracts, strong frontier teachers are accessible only as black-box endpoints without exposed weights or token probabilities, and supervised imitation alone…

Read at arXiv (research papers)

arXiv (research papers) Runtian Zheng

Planning to Stop: Factored Certification and Terminal Repair for Noncircular Robots

Tight-space navigation requires a robot to clear obstacles and stop inside its goal despite uncertainty. We present GeoDiff, a motion-program planner coupling original-goal stopped-set inclusion, witness-guided terminal repair, and factored proof compilation. An exact feasible-translation characterization guides repair; request-local reuse reduces repeated geometric work. We establish conditions for compiler equivalence and reach-and-stop soundness. Across 11,440…

Read at arXiv (research papers)

arXiv (research papers) Jinxi Liu

One View, One Action: Spatially Generalizable VLAs through Observation-Aligned Experts and Cross Graph Consistency

Multi-view vision-language-action (VLA) models still face challenges in spatial generalization, particularly under changes in camera viewpoints and robot initial states. These models typically receive action supervision only in the robot base frame, requiring them to implicitly learn the spatial correspondence between observations from each view and base-frame actions. We propose One View, One Action (OVOA-VLA), which learns to predict actions in each view's camera frame…

Read at arXiv (research papers)

arXiv (research papers) Ganeshvar Soenessardien

Reference-Free Humanoid Skateboarding via Termination-Shaped Reinforcement Learning

Humanoid locomotion research has advanced rapidly on walking and running, but \emph {object-mediated} locomotion, in which a robot must coordinate its body with a passive external object, remains difficult. One challenging task is skateboarding, which requires simultaneous interaction with the ground and a passive but movable platform to achieve forward motion. Current methods for tackling skateboarding with humanoid robots either require human demonstrations or utilise…

Read at arXiv (research papers)

arXiv (research papers) Kang Wang

Agentic Scaling of Embodied Tasks in Simulation for Synthetic Data Collection and Policy Evaluation

Scaling embodied interaction data requires a broad collection of usable tasks, yet specifying and validating each task instance remains costly. We present AgenticTask, an agent-based framework that expands existing task collections under human intent. Its central representation links interaction requirements to object and part bindings, scene and robot configurations, initial conditions, and completion criteria. A task-generation agent reuses interaction structure to…

Read at arXiv (research papers)

arXiv (research papers) John Won

Learning What Actions Change: Action Effect Matching for Dynamics-Faithful World Models

World models aim to predict environment dynamics under actions, enabling the prediction of action consequences without executing them in the real world. Yet despite producing increasingly realistic videos, current world models often fail to capture how small action changes affect future observations. This limits their use in tasks such as robotic policy evaluation and model-based planning, where nearly identical actions can lead to qualitatively different outcomes. To…

Read at arXiv (research papers)

Future Farming Bas Van Hattum

In pictures | Eima focuses on batteries, autonomy and robotics

After Agritechnica, Eima is Europe's second-largest agricultural machinery exhibition. For 5 days, the Italian city of Bologna is packed with machinery and innovations, with a strong focus on batteries, autonomy and robotics.

Read at Future Farming

arXiv (research papers) Guillaume Bellegarda

Learning optimal gaits and styles for terrain-adaptive quadruped locomotion

Animals use many different gaits to locomote at different speeds across varying terrains. A longstanding question in biology and robotics is: which gait is best? This question is most often addressed from an energy-efficiency perspective on flat terrain, leaving open how the answer depends on terrain and on the criterion optimized. Here we show that gait optimality is determined jointly by terrain, performance metric, and velocity. We use deep reinforcement learning and…

Read at arXiv (research papers)

arXiv (research papers) Wai Ka Sun

Collision-Free Is Not Enough: Passage-Conditioned Navigation for Wheeled-Legged Robots

A collision-free detour can still bring a legged robot to the next stair or ledge a few centimetres or degrees off, and a fixed locomotion skill, factory or learned, can stall or fall. Existing methods prevent this with a robot model or extensive trial and error, but on a new site with unknown skills neither is available, so they cannot be used. We find that a single 27-minute teaching session already supplies what these methods have to derive or learn: for every stair and…

Read at arXiv (research papers)

arXiv (research papers) Haisen He

Hindsight Self-Distillation: Teaching Robots to Act from the Present

A robot must choose an action before it can see the outcome. In a recorded demonstration, later camera frames show what happened after the robot moved. Hindsight Self-Distillation (HSD) uses these later frames to teach a policy what to extract from current images. During training, a teacher sees both the current and later frames, while a student sees the current frames. They share a visual encoder and an action predictor. Each branch summarizes its images with a small set of…

Read at arXiv (research papers)

Android Authority Ankit Banerjee Gadgets

Roborock Black Friday 2026 deals: Save up to $1,650 on robot vacuums and wet-dry handhelds

From flagship robot vacuums that take care of themselves to powerful wet-and-dry handhelds, everything gets big discounts.

Read at Android Authority

Older stories