Results for “Prompt”

arXiv (research papers) Mark Heimann SI

Notwithstanding Anything to the Contrary, Ignore All Instructions: Measuring Prompt Injection Guards on Legal Contract Review Attacks

Specialized prompt injection guards are deployed in front of document analysis systems, but no false positive rate has been published for any of them on legal contracts. We measure eleven open-weights guards on two corpora of legal contracts and find that existing guards struggle: document-level false positive rates are as high as 92.39%; two guards fall below chance on paired AUC; and a five-regex baseline is not Pareto-dominated by any guard in the panel. Controlled probes…
Read at arXiv (research papers)

Journal articles (OpenAlex) David Stehlík · Management Teaching Review Tech policy

Castmagic Alchemy: Turning Transcripts Into Teaching Tools for Facilitators of Discussion-Based Courses

This Resource Review explores the instructional utility of Castmagic (castmagic.io), a transcript-driven prompting tool, for enhancing student learning in synchronous, discussion-based courses. Grounded in evidence-based teaching principles, including retrieval practice, reflection, and feedback, the article evaluates Castmagic’s use across live, in-person, and online environments to support student engagement and post-session reflection. The article’s core is classroom…

Read at Journal articles (OpenAlex)

The Guardian Ukraine Editorial Geopolitics

The Guardian view on the midterms and foreign policy: American voters spoke, and now the world waits anxiously | Editorial

The Democrats have gained new powers to constrain Donald Trump. But the drubbing that Republicans received could yet prompt him to new excesses Donald Trump is a president without parallel, but history can still be instructive. Lame duck presidents often focus on foreign policy to escape domestic discontent and establish a legacy in an area where a hostile Congress offers less of an obstacle. Mr Trump, who was stunningly rebuffed by voters in Tuesday’s midterms, might seek…

Read at The Guardian Ukraine

The New Stack Frederic Lardinois

Raindrop simulates your agent’s world to catch what your changes break

Raindrop wants developers to know what else will change when they edit an agent’s prompt, swap its model, or give

Read at The New Stack

The Hacker News Security

Researchers Bypass ChatGPT Lockdown Mode to Exfiltrate Chats Without User Interaction

Cybersecurity researchers have disclosed details of a now-patched vulnerability that could be exploited to bypass Lockdown Mode protections in OpenAI ChatGPT. Lockdown Mode was introduced by the artificial intelligence (AI) company in June 2026 as an optional setting to minimize data exfiltration risks arising from prompt injections. "The flaw could enable silent chat data theft, phishing,

Read at The Hacker News

The Register Richard Speed SI

Copilot Chat has usage caps, and Microsoft would rather you found them by hitting them

Mystery limits expand for users without the paid add-on, with upgrade prompts ready when features run dry

Read at The Register

Asia Times Nicholas Westcott Geopolitics

Trump, Putin and Xi can’t carve up the world like its 1945

Discussions are underway for a potential meeting between Donald Trump, Xi Jinping and Vladimir Putin on the margins of the Asia-Pacific Economic Cooperation summit on November 18-19. The prospect has prompted comparisons with the “Big Three” summit in Yalta in February 1945, at which the leaders of Britain, the US and the Soviet Union discussed

Read at Asia Times

arXiv (research papers) Rongting Zhang SI

Beyond Instruction Override: Benchmarking Indirect Prompt Injection with Task-Tampering Attacks

Indirect prompt-injection (IPI) benchmarks predominantly test planted instructions that redirect a tool-using agent toward an attacker-chosen task. Yet attacker-controlled content can instead tamper with the outcome of the task already in progress. A buyer's dispute evidence can cite a false refund policy to inflate a refund without changing the task. We define IPI by authority rather than instruction-like wording: planted content constitutes an attack when it attempts to…

Read at arXiv (research papers)

arXiv (research papers) Peiran Wang SI

MetaPI: Constructing Prompt Injection Benchmarks from LLM Agent Benchmark

Large language model (LLM) agents increasingly perform complex tasks using high-privilege tools, making indirect prompt injection (IPI) a critical security risk. However, IPI benchmarks lag behind their rapidly evolving utility counterparts, only offering limited task and environment coverage and relying on narrow, static attack scenarios. In this paper, we propose meta-benchmarking for IPI: transforming existing utility benchmarks into end-to-end IPI evaluation suites that…

Read at arXiv (research papers)

TechCabal Opeyemi Kareem Startups

👨🏿‍🚀TechCabal Daily – A Chinese plot twist

In today's edition: China inquiry prompted OPay to halt US IPO || Kenyan Treasury calls for cheaper bank loans || Africa’s credit rating agency to debut in 2027 || Helium Health raises $2.5 million

Read at TechCabal

Journal articles (OpenAlex) Jan Waligórski · Convergence The International Journal of Research into New Media Technologies Geopolitics

Banal nationalism in virtual reality: An ethnographic study of the (re)production of digital national identities in social VR based on the case of Polish users

The emergence of each new digital medium prompts debates about its potential to foster cosmopolitanism or reinforce new forms of nationalism. To date, social virtual reality (VR) platforms have often been portrayed through a cosmopolitan lens. This article challenges that view by demonstrating how banal nationalism is (re)produced within social VR, drawing on multi-sited ethnographic research conducted among Polish users. Polish users, navigating power inequalities in access…

Read at Journal articles (OpenAlex)

arXiv (research papers) Woosang Lim SAINT Machines KAIST SI

SPILLWAY: Separating Target Admission from Sanitization to Defend Tool-Using Agents against Prompt Injection

Tool-using agents act on email, files, and payments, so an instruction hidden in a web page or a shared document can make an agent send data or money to an attacker. Many runtime defenses put a language model on the decision that lets an action through, so the decision depends on a model that may read the attacker's text and adds model calls to every step. Provenance defenses keep the model off the final check but need a model to plan or route each task first. Where an…

Read at arXiv (research papers)

arXiv (research papers) Woosang Lim SAINT Machines KAIST SI

SPILLWAY: Separating Target Admission from Sanitization to Defend Tool-Using Agents against Prompt Injection

Tool-using agents act on email, files, and payments, so an instruction hidden in a web page or a shared document can make an agent send data or money to an attacker. Many runtime defenses put a language model on the decision that lets an action through, so the decision depends on a model that may read the attacker's text and adds model calls to every step. Provenance defenses keep the model off the final check but need a model to plan or route each task first. Where an…

Read at arXiv (research papers)

arXiv (research papers) Woosang Lim SAINT Machines KAIST SI

SPILLWAY: Separating Target Admission from Sanitization to Defend Tool-Using Agents against Prompt Injection

Tool-using agents act on email, files, and payments, so an instruction hidden in a web page or a shared document can make an agent send data or money to an attacker. Many runtime defenses put a language model on the decision that lets an action through, so the decision depends on a model that may read the attacker's text and adds model calls to every step. Provenance defenses keep the model off the final check but need a model to plan or route each task first. Where an…

Read at arXiv (research papers)

The Decoder Matthias Bastian SI

ChatGPT can now turn text prompts and photos into animated GIFs with OpenAI's Images 2.6 model

OpenAI is adding a GIF feature to ChatGPT. With the new Images 2.6 model, users can create animated GIFs from text prompts or photos and then adjust speed and individual frames. The model's image consistency is strong enough to keep characters recognizable across frames, making flipbook-style animation possible. According to OpenAI, users now generate more than four billion images per week. The article ChatGPT can now turn text prompts and photos into animated GIFs with…

Read at The Decoder

The Verge Emma Roth SI

ChatGPT will now make you animated GIFs

ChatGPT can now create GIFs using a prompt or a photo uploaded to the AI chatbot. The update, which is rolling out alongside OpenAI's new Images 2.6 model, allows you to adjust the GIF's animation speed, edit individual frames, and share…

Read at The Verge

The Hacker News Security

Researchers Uncover Prompt Adware Hidden in OpenAI Codex Jailbreak Toolkit

Cybersecurity researchers have disclosed details of an OpenAI Codex jailbreak bundle that's designed to modify an artificial intelligence (AI) agent's trusted instructions to insert advertisements for a third-party AI gateway. The phenomenon has been codenamed prompt adware by Check Point Research. Called Haiou (meaning Seagull in Chinese), the jailbreak modifies OpenAI Codex's configuration

Read at The Hacker News

arXiv (research papers) Guoqin Xiong SI

SecureGARD: Dynamic Ontology-Guided Governance for Secure Tool-Using LLM Agents

Tool-using large language model (LLM) agents translate model outputs into consequential actions, turning indirect prompt injection into an execution-security problem. Existing defenses constrain tool calls, trajectories, or information flows, but often leave action semantics, state dependencies, and evidence relations implicit, limiting generalization across heterogeneous tools and complicating safe updates. We present SecureGARD, a dynamic ontology-guided governance…

Read at arXiv (research papers)

SiliconANGLE AI Duncan Riley SI

Oumi’s Frontier AI Engineer now builds AI agents and retrains the models behind them

Enterprise artificial intelligence platform company Oumi PBC today extended its Frontier AI Engineer agent so it can build AI agents for customers and retrain the models those agents run on. The release goes after a problem that tends to surface once agents leave the demo stage. A failing agent might have a bad prompt, a

Read at SiliconANGLE AI

The Moscow Times

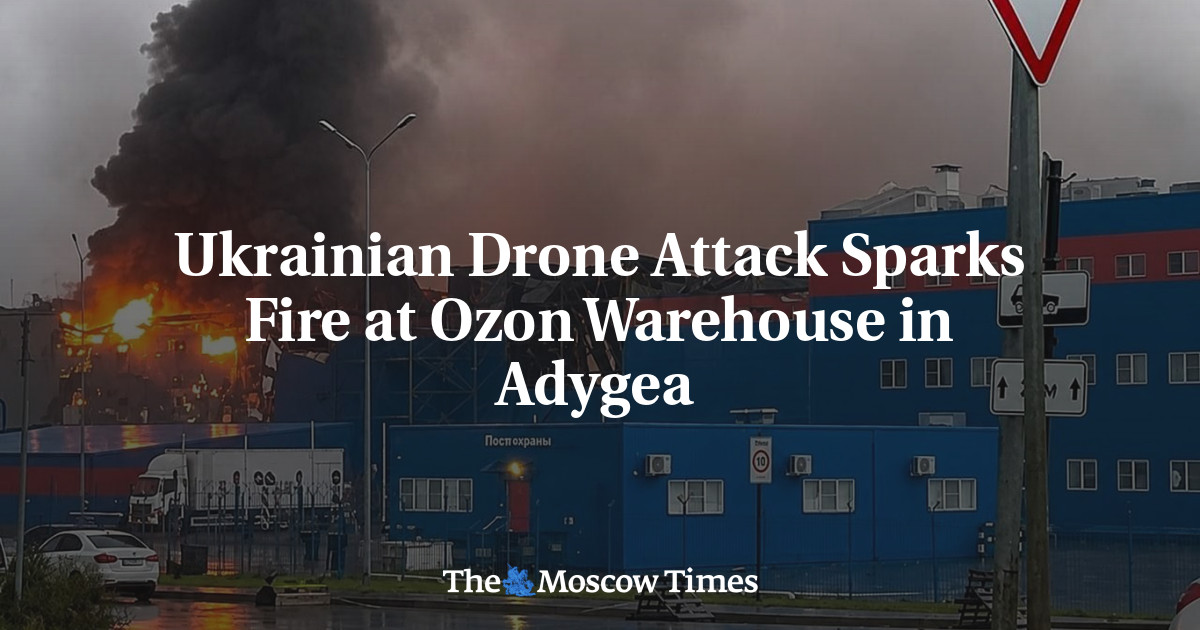
Ukrainian Drone Assault Sparks Fire at Ozon Warehouse in Adygea

The e-commerce giant said it “promptly evacuated all workers” from the facility in the town of Adygeysk, adding that no one was hurt.

Read at The Moscow Times

Inquirer Global Nation mmercado Geopolitics

At least 11 European countries snared in freezer cyberattacks

ROME, Italy — Germany, Romania, and the United Kingdom on Tuesday joined the growing list of European countries hit by cyberattacks on supermarket refrigeration systems in recent days. Italy’s government held emergency talks with intelligence chiefs on Tuesday following the incidents, which prompted the European Union (EU) to warn of a deliberate attempt to disrupt

Read at Inquirer Global Nation

arXiv (research papers) Annabella Chow SI

Securing Web Agents with the Compile-Then-Execute Paradigm

Web agents commonly follow the ReAct paradigm, selecting each action from runtime observations that inherently mix trusted and untrusted content. This design makes their control flow vulnerable to prompt injections embedded in webpages. We introduce Baya, a compile-then-execute web agent designed to prevent prompt-injection-driven control-flow hijacking by design. Before accessing the live website, Baya compiles the user's request into an executable Python program that calls…

Read at arXiv (research papers)

Simon Willison SI

datasette-agent 0.5a0

Release: datasette-agent 0.5a0 This is a significant release of Datasette Agent. The most notable new feature is called the panel - it lets the agent chat open and then sit next to pages from Datasette, for example a table or query page. When combined with datasette-apps this means you can prompt a database-backed app into existence and then modify it from the chat that sits next to that app. You can try it by signing in with your GitHub account to agent.datasette.io. Tags…

Read at Simon Willison

The Moscow Times

Norway, Denmark, Sweden, Latvia and Czech Republic to Boycott Russia at 2027 Ice Hockey World Championship

The CAS decision has also prompted several corporate sponsors to threaten to pull their support from future events.

Read at The Moscow Times

arXiv (research papers) Yutao Wu SI

ScamWorld: An Interactive Environment for Evaluating Web Agents Against Online Fraud

Web agents increasingly browse, shop, and manage accounts on behalf of their users. Prior work has shown that they can be misled by adversarial content, including prompt injections and deceptive interfaces. Beyond such attacks, agents operating on the open web also encounter online fraud designed to deceive humans, including fraudulent online stores, fake investment platforms, and advance-fee schemes. How web agents respond to such fraud during task execution remains…

Read at arXiv (research papers)

arXiv (research papers) Yao Wang SI

Right Tool, Wrong Parameters: Defending LLM Agents Against Parameter Poisoning

Indirect Prompt Injection (IPI) poses a critical threat to LLM agents. Existing defenses largely focus on whether an injection induces a new tool invocation or unintended action. In this paper, we study a different attack surface, parameter poisoning, where the attacker preserves the intended action but manipulates one or more tool arguments, such as a recipient or other task-critical value. Such attacks are difficult to detect because no new action is introduced, while…

Read at arXiv (research papers)

arXiv (research papers) Jiamin Chang SI

The Devil is in the Context: Nine Dimensions of Prompt Injection Attacks

Prompt injection is usually discussed and evaluated as a single, homogeneous type of attack. However, vulnerabilities reported in real-world systems show that prompt injections vary widely. Moreover, the same instruction can be a prompt injection in one context and a legitimate request in another, depending on the user's intent and the system's policies. Ignoring this variation leaves gaps in how defenses are evaluated, and can give a false sense of security against…

Read at arXiv (research papers)

arXiv (research papers) Gia Phong Tran SI

From Guidelines to Practice: Defining Requirements for AI Red-Teaming Tools

Artificial Intelligence (AI) has seen significant developments and increased usage in recent years. AI benefits various tasks, automates decision-making, and enhances efficiency. However, AI also introduces additional attack surfaces for threat actors to perform attacks like prompt injection and jailbreaking, making security a great concern. AI security testing aims to imitate adversarial attacks or malicious inputs via manual testing or with the assistance of tools. Thus…

Read at arXiv (research papers)

arXiv (research papers) Xu Zhang SI

ATrust: Adaptive Trust Boundary Expansion for Securing LLM Agents

As large language model (LLM) agents take on more complex tasks with greater autonomy, security has become a major obstacle to their broader deployment. Unlike in attacks that require complex exploitation of operating system vulnerabilities, attackers can easily hijack agents through indirect prompt injection (IPI), leading to privacy leakage, financial loss, and destructive operations. However, existing defenses often make security decisions based on limited static trusted…

Read at arXiv (research papers)

arXiv (research papers) Kainan Zhou SI

SearchInject: Retrieval Exposure Control for Indirect Prompt Injection in Language-Model Search

An indirect prompt injection can affect a search-augmented large language model only after its carrier page reaches model context. SearchInject controls this admission decision with a joint score combining retrieval relevance, search-abuse cues, instruction likelihood, and two relevance interactions. A quarantine threshold is selected under an empirical 0.5% clean-candidate false-quarantine constraint on a calibration split. Evaluation uses 300 held-out SciFact queries and…

Read at arXiv (research papers)

Older stories