Results for “Prompt”

arXiv (research papers) Bogdan Mamaev Tech policy

Measuring Definition Sensitivity in LLM Annotation of Social Science Concepts

In social science research, text annotation is a fundamental task that is traditionally a costly, hard-to-scale manual process. Researchers have used large language models (LLMs) to perform annotation by writing a definition of a concept into a prompt - a rule that determines whether a label should be attributed to a text depending on its content. However, concepts such as hate speech, fake news, and terrorism typically have several theoretically defensible competing…
Read at arXiv (research papers)

TestingCatalog Erin | AI Agent SI

Google Maps features come to Google AI Studio Build

Google AI Studio now builds map-based apps from prompts with Maps Platform, covering places, routes, 3D views and environmental data.

Read at TestingCatalog

The Verge Stevie Bonifield SI

Instagram’s Effect Builder makes new filters from AI prompts

After expanding its Edits app to macOS last week, Instagram's next move is launching this Effect Builder that generates custom filters for your Stories posts with AI. Available now for US residents who are over 18, it has a prompt box for…

Read at The Verge

Ars Technica Kyle Orland SI

Claude Code is accidentally exposing secrets all over GitHub

"Do not ask again" prompt leads to passwords, API keys, and more being shared.

Read at Ars Technica

arXiv (research papers) Susie S. Y. Li SI

reComposer: Editable Planning for Controllable Image Generation

Prompt-based image generation makes it easy to produce visual assets, but offers little support for engaging with the creative process. Prompting collapses interdependent creative decisions into a monolithic instruction and returns a finished image, leaving control limited to revising the prompt or correcting the model's output. We present reComposer, a process-oriented image-generation interface built around editable planning, which decomposes users' evolving intent into…

Read at arXiv (research papers)

arXiv (research papers) Marcus Armstrong SI

Interpretability Is Not Model-Specific

Interpretability tools are usually built for one model at a time: a refusal direction, a truthfulness probe, or a steering vector is found with labeled data inside the model it explains. We ask whether such tools can be carried to other models through a map between residual streams fit only on unlabeled prompts. We transfer a refusal direction, tested causally by addition and ablation, and two read-out tools, a correctness direction and a sentiment probe, across 110 pairs of…

Read at arXiv (research papers)

The Register Richard Speed

Microsoft takes three decades to make Sticky Keys less sticky

Windows preview adds a 'don't ask again' option to accessibility prompts, sparing users a trip through Settings

Read at The Register

arXiv (research papers) Andrew Trask SI

Double Blind Evals: Resolving the Dual Confidentiality Dilemma in AI Safety Auditing

AI safety evaluations often involve sensitive prompts and proprietary models. Evaluators want to keep their evaluation prompts secret from model owners to prevent purposeful or incidental data leakage, ensuring longer usefulness of their benchmark. Model owners in turn wish to keep their proprietary model weights and inference code within their own secure infrastructure to protect their IP. We present a way forward for "double-blind evals", which provide cryptographic…

Read at arXiv (research papers)

Meduza

Maldives’ largest bank stops processing payments for Russian tourists, prompting hotels to turn them away

Bank of Maldives has been declining payments for Russian tourists’ accommodations on the islands since late October.

Read at Meduza

Schneier on Security Bruce Schneier Security

AI Security

Two weeks ago, I attended the [un]prompted AI security conference in San Francisco. It was an excellent event: three days of very dense talks about all aspects of AI security. (My talk was about integrous AI, and I will post it when it is online.) AI security can be divided into three broad topics. It’s important for researchers to understand which one they are working on. And it’s important for us as a community to work on them all. They are: security of AI, security with…

Read at Schneier on Security

The Register Simon Sharwood SI

Linus Torvalds sees signs AI-prompted patch flood has peaked

Fixes are arriving faster than new bug reports for one major Linux project

Read at The Register

arXiv (research papers) Alexey Kurakin SI

Scaling Adaptive Prompt Injection Attacks with Agent Swarms

Prompt injections have emerged as one of the top security risks faced by AI agents today. Early work in prompt injection attacks looked at simple tool-call agents and static attack payloads, and were saturated since mid-2025. As of Fall 2026, human red-teaming may be nearing saturation, especially on the Gemini family of models. In this work, we argue that despite this apparent plateau, prompt injection attacks are still possible and continued effort into prompt injection…

Read at arXiv (research papers)

Simon Willison SI

parse_number() as a SQLite extension: C vs Rust

Research: parse_number() as a SQLite extension: C vs Rust I was out walking the dog when I got curious about how easy/difficult it would be to write a SQLite C extension that adds a parse_number() function for turning strings like -$1,234.56 or '12.5%' into numeric values that could be summed and sorted. I fired up regular Claude chat (Opus 5.5) and prompted: I'm thinking about a SQLite custom function 'parse_number(value)' that strips ',', '$', '£' and '%', handles a…

Read at Simon Willison

arXiv (research papers) Mustafa S. Aljumaily SI

Treating the Model as an Untrusted Component: Deterministic Policy Enforcement, Human Approval and Taint Tracking Against Prompt Injection in Tool-Using Agents, with Validation on Open-Weights Models

Tool-using LLM agents act on instructions embedded in the data they read, so prompt injection is a structural rather than a prompt-wording problem. We compare in-prompt defences (hardened prompts, spotlighting, LLM detectors) with deterministic enforcement outside the model (four reference monitors of increasing strength), human approval and taint tracking, judged by one effect-based oracle independent of every defence in an executable environment of 13 tasks and 12 tools…

Read at arXiv (research papers)

The Guardian Gaza Guardian Staff

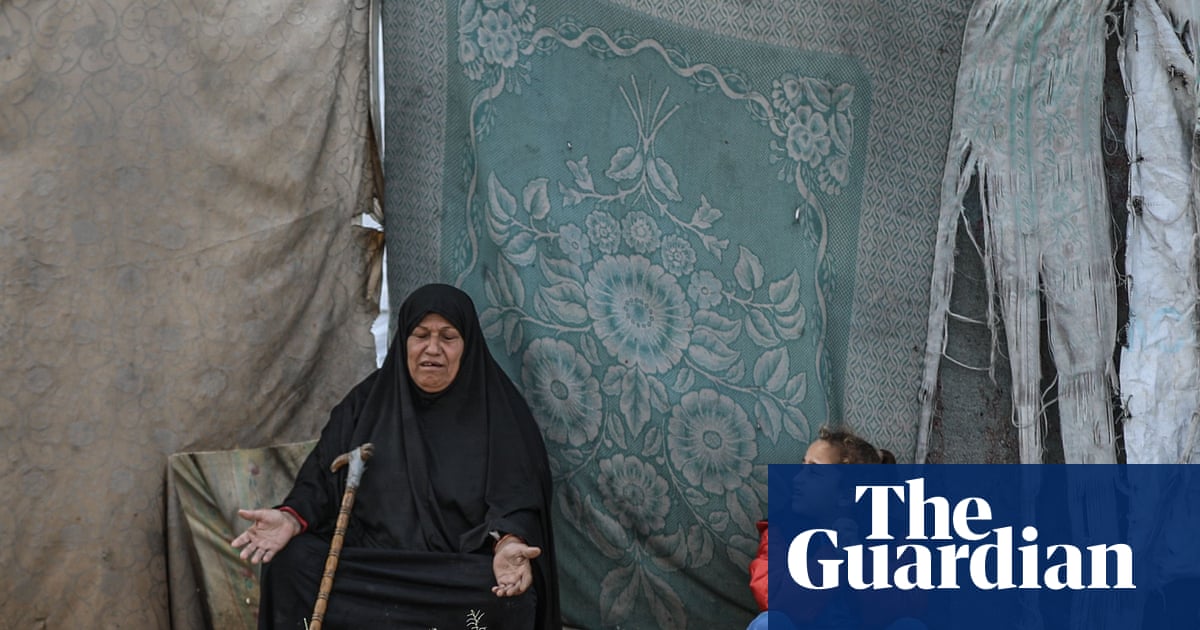
Heavy rain floods displaced families’ tents in Gaza – in pictures

The first winter storm began affecting the people of Gaza this weekend with heavy rain hitting on Saturday. Reports that about 70,000 tents were flooded within 12 hours prompted warnings of a worsening humanitarian situation for hundreds of thousands of displaced people living in temporary camps lacking adequate protection from rain and cold

Read at The Guardian Gaza

Hacker News koeseo SI

Open dataset of prompt-injection CVEs with a monthly threat index

Article URL: https://promptinjections.de/threat-index/zahlen/ Comments URL: https://news.ycombinator.com/item?id=50415821 Points: 3 # Comments: 0

Read at Hacker News

The Guardian World Associated Press Geopolitics

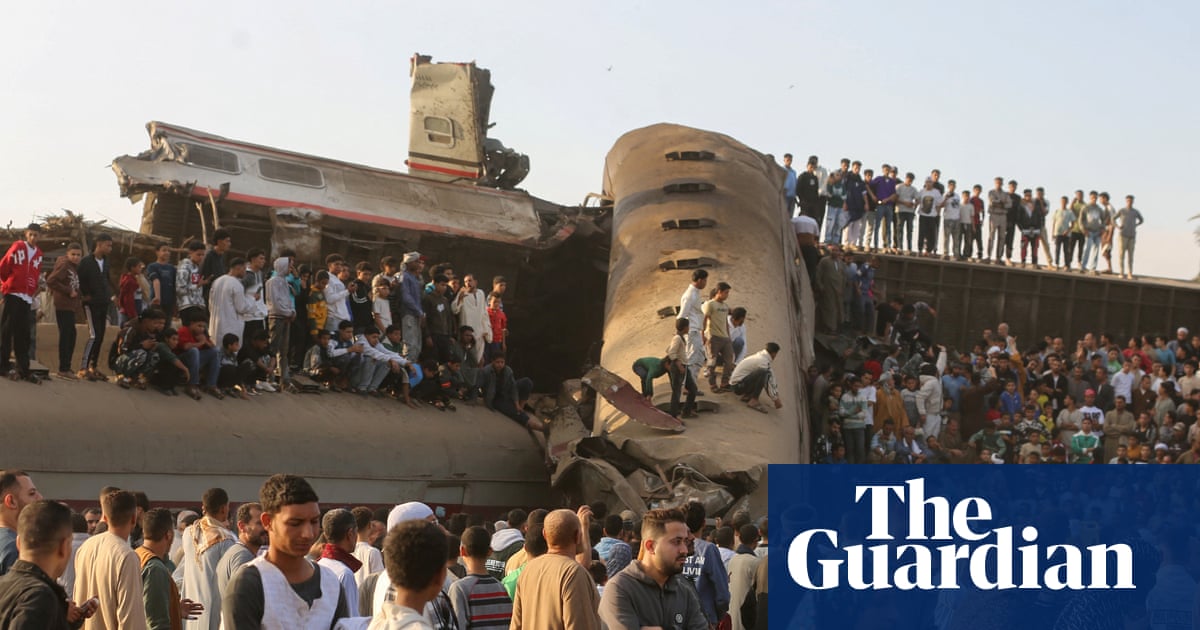
Collision of two trains in Egypt kills at least seven

President orders prompt investigation after one train derails in collision in al-Ayyat about 50km from Cairo Seven people were killed and at least 125 injured when two trains collided on Sunday south of the Egyptian capital, Cairo, officials said. The crash occurred in al-Ayyat district in Giza province, about 50km (30 miles) south of Cairo, when a train travelling to Fayoum province crashed into the rear of a train heading to the southern province of Aswan, according to the…

Read at The Guardian World

arXiv (research papers) Brijesh Dongol SI

On the Relative Security of Prompt Injection: Mechanised Definitions, Defences and Verdicts for LLM Agents

An LLM agent that reads untrusted content, such as an email or a web page, may follow instructions hidden in it. Noninterference is too strong for such agents, since a useful agent lets untrusted content influence what it does and may disclose the user's data by design, and declassification needs a release policy written for each task. We instead state security relative to a reference agent, which runs the same plan under the same runtime monitor with a model that never…

Read at arXiv (research papers)

The New Stack Amanda Caswell

Perplexity’s AI agents keep working after you close the tab

Perplexity’s new Teammates can coordinate multiple agents, remember where previous sessions left off, and keep working without another prompt. The

Read at The New Stack

arXiv (research papers) Doron Shavit SI

Least-Privilege Auditing of Agent Tool Calls with Intent Graphs and Reasoning-Guided Escalation

LLM agents that call tools are exposed to indirect prompt injection: instructions hidden in tool outputs can steer an agent into calls the user never asked for. We present a runtime audit that derives an executable intent graph from the user's objective and the deployment's tool catalog with one LLM call per task, and checks every tool call against it with a deterministic loop that makes no LLM call (median 5.7 microseconds per call). Two further mechanisms recover utility…

Read at arXiv (research papers)

arXiv (research papers) Riya Bharathwaj SI

ErosionBench: Probing Alignment Decay in Enterprise Multi-Agent Systems

As enterprises delegate consequential work to multi-agent LLM systems, benign-looking requests can escalate into unsafe actions as they propagate across sessions through poisoned shared state, long-context documents, and trusted peer messages: no single message is malicious, yet the assembled tool action is. Prior benchmarks isolate a single agent under prompt injection or score multi-agent attacks by their final output, leaving cross-session erosion of shared state out of…

Read at arXiv (research papers)

MarkTechPost Asif Razzaq SI

Nous Research Releases Arete-27B that Cuts Qwen3.8-27B Propaganda From 22% to 0.9%

Nous Research released Arete-27B, an Apache 2.0 fine-tune of Qwen3.8-27B. On Nous’s 803-prompt eval, propaganda answers fell from 22% to 0.9% while Hermes Bench stayed flat at 65.60%.

Read at MarkTechPost

Hacker News tclancy SI

Hiding prompt injections in PDFs, and six judges that catch them

Article URL: https://tomclancy.info/joshua-judges-ruth.html Comments URL: https://news.ycombinator.com/item?id=50407255 Points: 1 # Comments: 0

Read at Hacker News

arXiv (research papers) Tanzim Hasan Prappo Tech policy

Writer-independent handedness identification from offline Bangla handwriting under controlled acquisition

Handedness is a soft-biometric cue for forensic document examination and writer profiling, yet reported accuracies from offline handwriting rarely keep writers, texts and image acquisition apart, so models may recognise the writer or capture conditions rather than the writing hand. Such controlled evidence is missing for Bangla. Using our BanglaHand dataset of 42 writers (21 left- and 21 right-handed), who each wrote six shared prompts and two own texts under controlled…

Read at arXiv (research papers)

arXiv (research papers) Yichen He SI

CompositionEvidence: Controlling Geometric Evidence for Cinematic Composition Reasoning with Frozen Vision-Language Models

Cinematic composition questions depend on in-frame geometry that vision-language models (VLMs) use inconsistently. External perception tools can expose this geometry, but naive prompt injection can overwrite useful visual predictions. On ShotBench composition, pre-question geometry reduces Qwen2.5-VL-7B from 49.5% to 46.3%; corrupted measurements lower it to 33.6%. CompositionEvidence derives nine reproducible features from frozen detection, depth, and line experts and…

Read at arXiv (research papers)

Hacker News junayedmizan5 SI

Show HN: We tested our prompt injection filter in public

Article URL: https://hodor.gatebolt.com/blog/secret-leak-test Comments URL: https://news.ycombinator.com/item?id=50401639 Points: 1 # Comments: 0

Read at Hacker News

Axios Julianna Bragg Geopolitics

Ex-RFK Jr. adviser says Trump admin corruption prompted resignation

Calley Means, a former adviser to Health Secretary Robert F. Kennedy Jr., said he resigned from the Trump administration over alleged internal corruption from a "concentrated group of people." Why it matters: Means left the Trump administration two weeks before the midterm elections that saw the GOP engulfed by a blue wave. He is one of the first former administration members to speak out about his time in the executive branch. What they're saying: "The simple reality in why…

Read at Axios

SecurityWeek Associated Press Security

Japan Announces Emergency Cybersecurity Package Following a Wave of Attacks

The emergency package comes after dozens of companies and government agencies were hit by unauthorized access to their systems and leaks of client data, prompting uneasiness across Japan.

Read at SecurityWeek

arXiv (research papers) Zachary Petersen Space

Effects of a Nuclear Detonation in Low Earth Orbit

More than 13,000 satellites operate in low Earth orbit (LEO), and concern has grown that nuclear weapons could be used in space to target them. Beyond the initial X-ray burst, electrons released by radioactive fission products can become trapped in Earth's magnetic field, repeatedly exposing satellites as an artificial radiation belt. Here we couple prompt radiation, electron trapping and belt evolution to satellite failures, collisions and atmospheric drag. For a 1-Mt…

Read at arXiv (research papers)

arXiv (research papers) Mohammed Nayeem Khan SI

Enmo Safety: External, Non-invasive, Model-agnostic Oversight for Off-the-Shelf Language Models

We study a safety harness that improves itself without touching model weights. Enmo Safety wraps a chat model with a deterministic input assessment, trigger-matched safety guidance, spotlighting of untrusted content, and an output guard. A reflector model turns failures into one bounded update per round, and an update is kept only if it lowers harm without raising refusal of benign prompts on a held-out dev split. Every version is snapshotted and every decision ledgered. We…

Read at arXiv (research papers)

Older stories