MarkTechPost

Recent stories from MarkTechPost.

MarkTechPost Michal Sutter SI

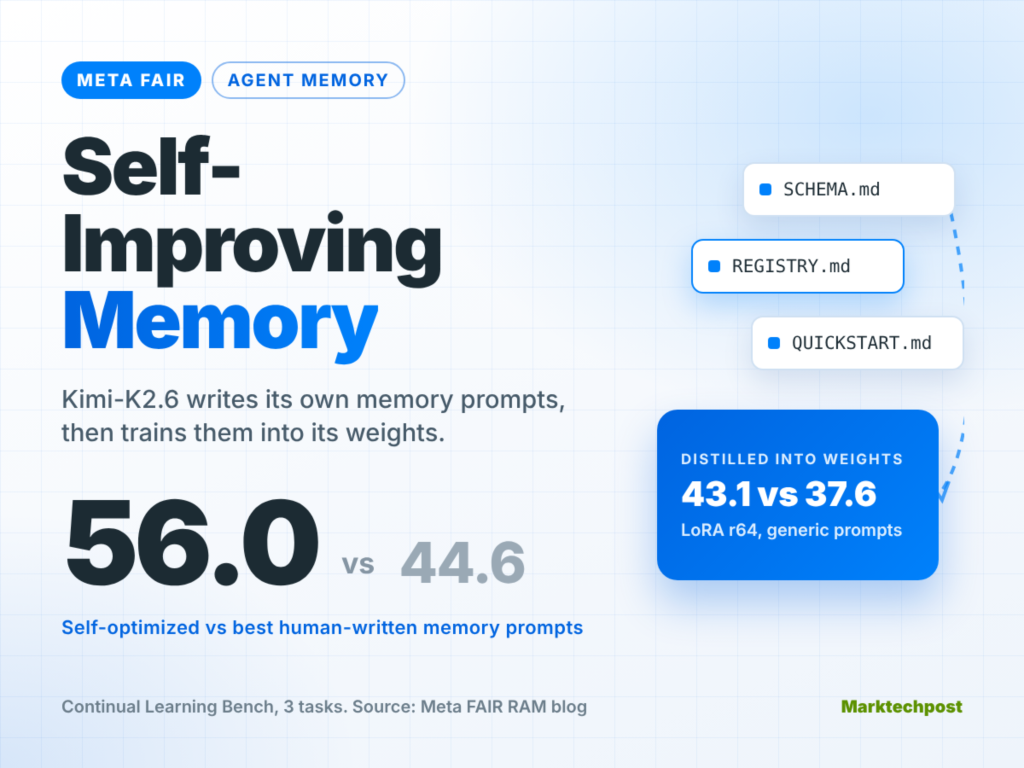
Meta FAIR Self-Improving Memory Hits 56.0 on Continual Learning Bench

Meta FAIR’s Self-Improving Memory lets Kimi-K2.6 write its own LOAD and OFFLOAD memory prompts, then distills them into its weights. Optimized prompts score 56.0 versus 44.6 for the best hand-written harness on Continual Learning Bench.
Read at MarkTechPost

MarkTechPost Asif Razzaq SI

13 Best Agent Gateways in 2026 for MCP, A2A and LLM Traffic: Kong, Bifrost, AgentCore, Arcade

We ranked the 13 best agent gateways of 2026 by how they govern model, MCP tool and agent-to-agent traffic, with verified pricing, deployment options and the trade-offs each vendor's marketing leaves out.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

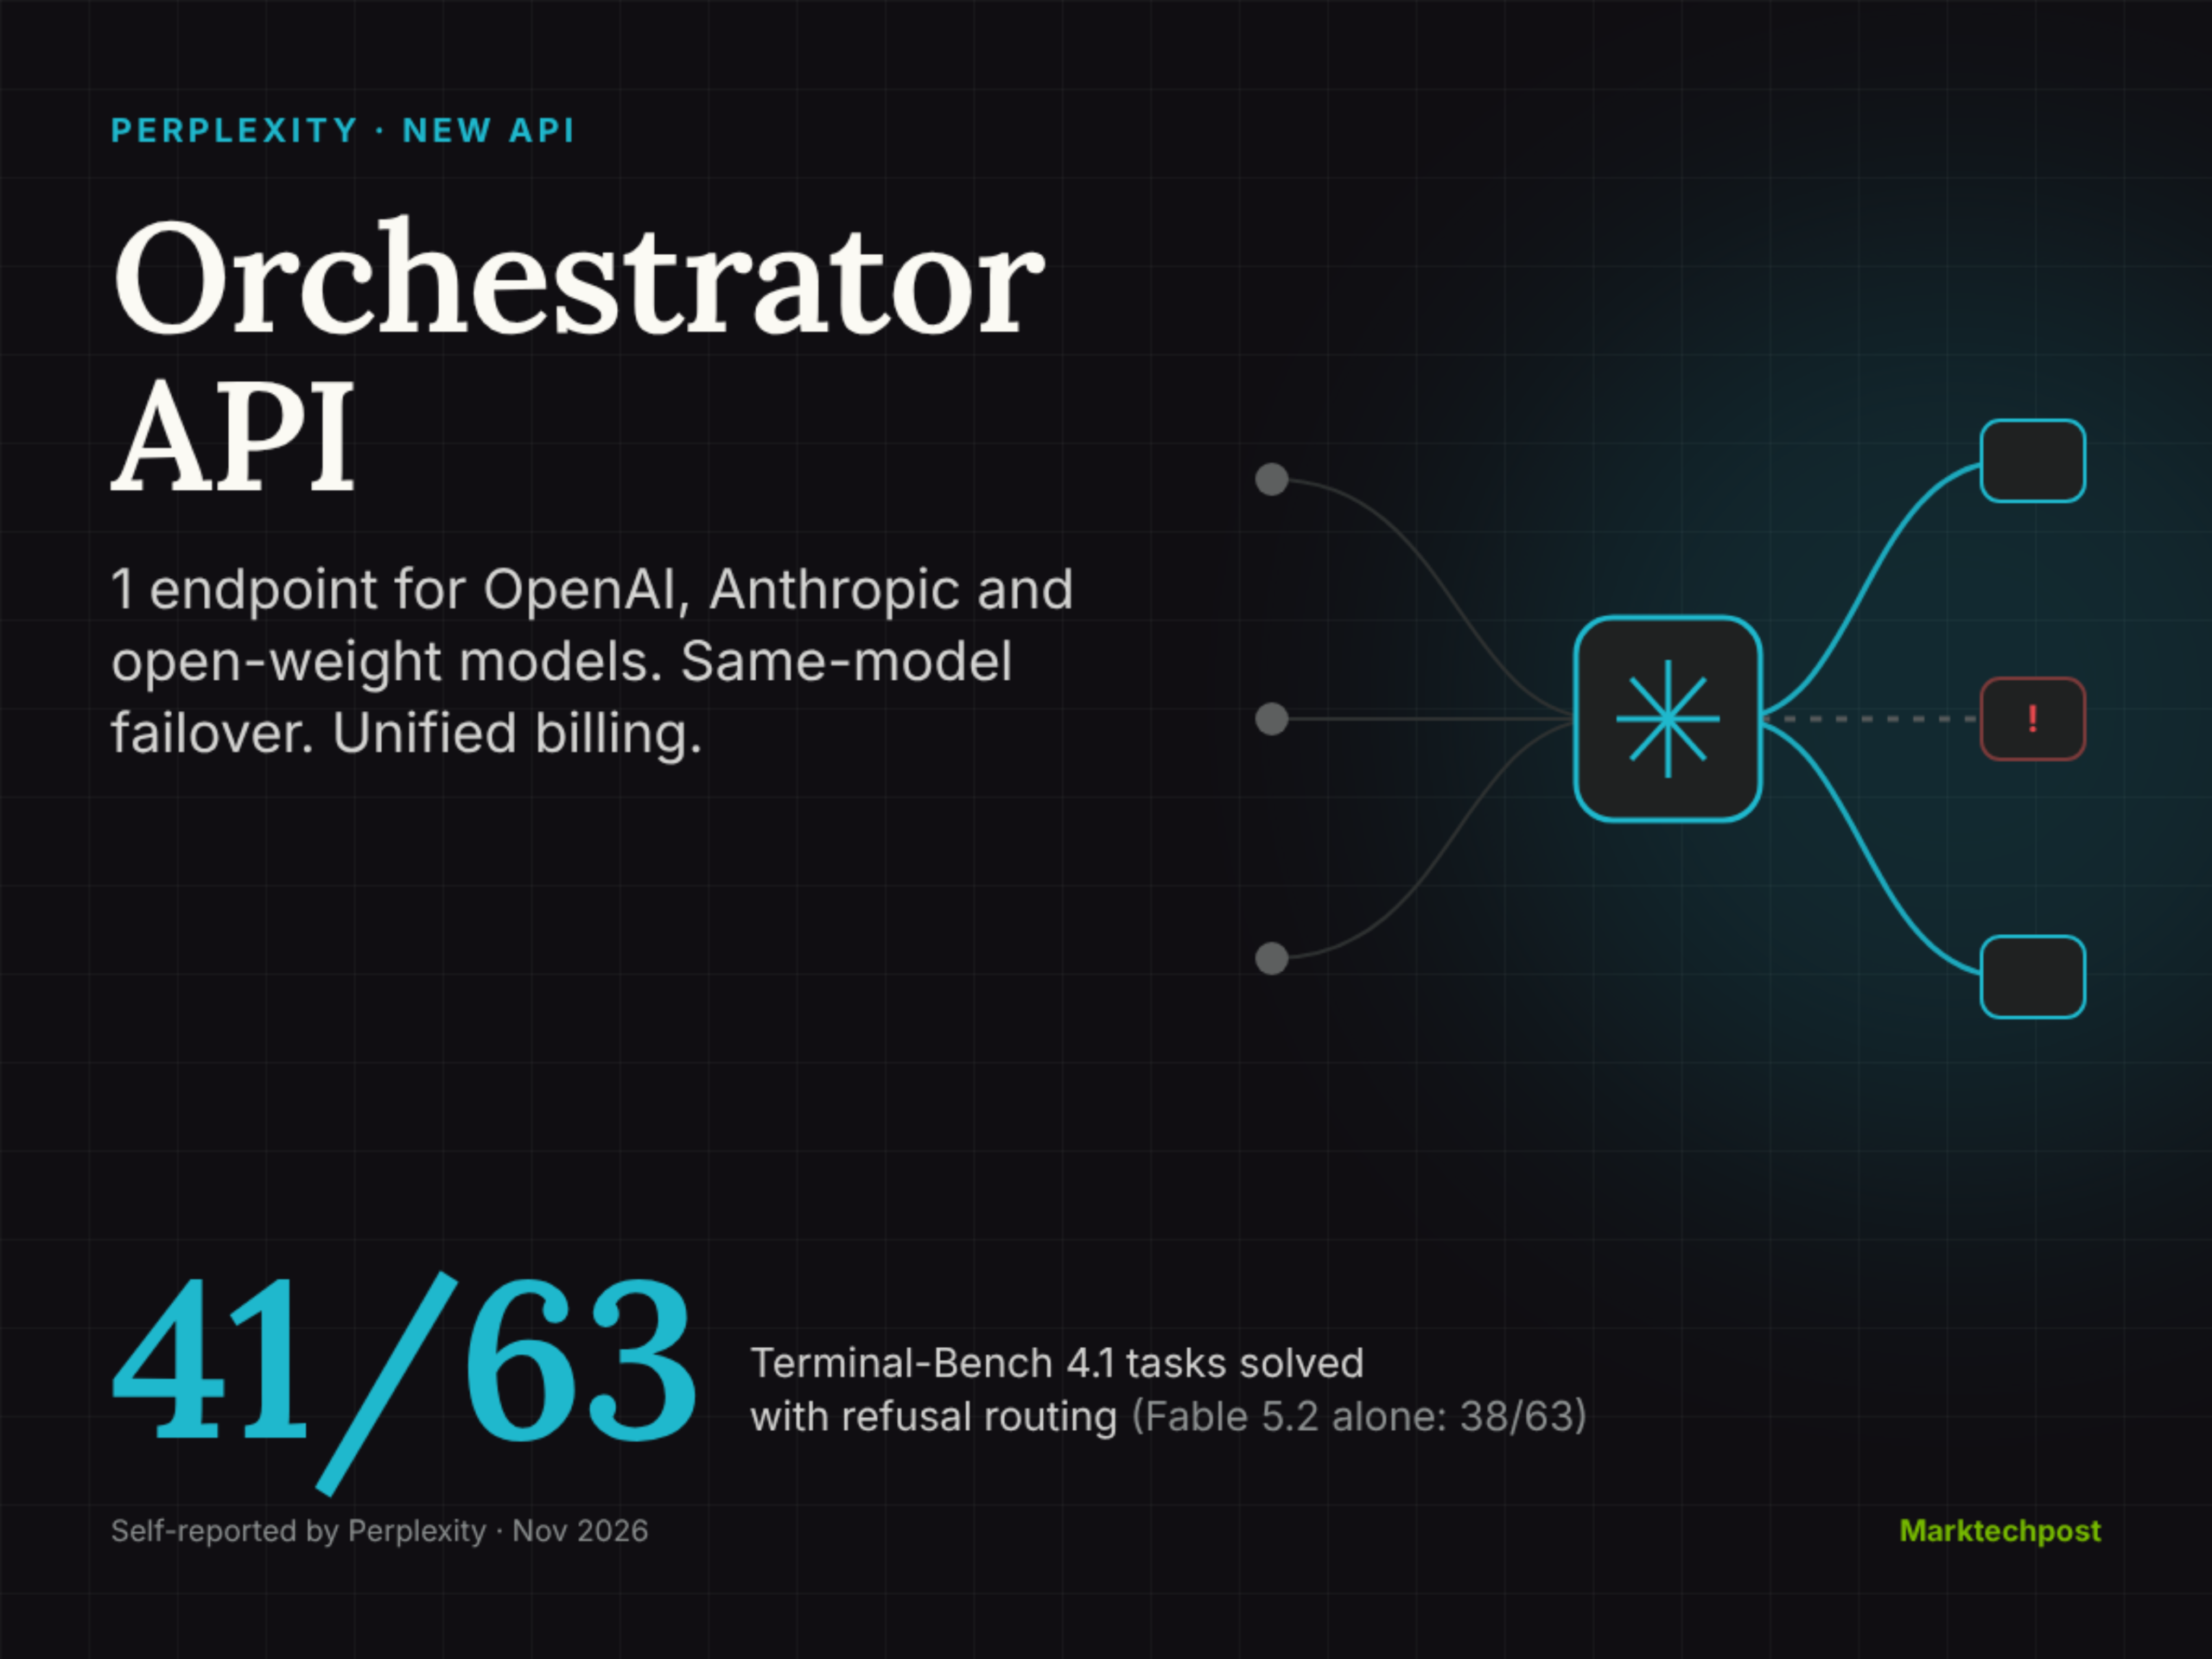
Perplexity Launches Orchestrator API for Failover and Model Routing

Perplexity’s Orchestrator API serves OpenAI, Anthropic, Google, xAI and open-weight models through 1 endpoint, with same-model provider failover, unified billing and a preview perplexity/auto router that sends each request to a described route.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

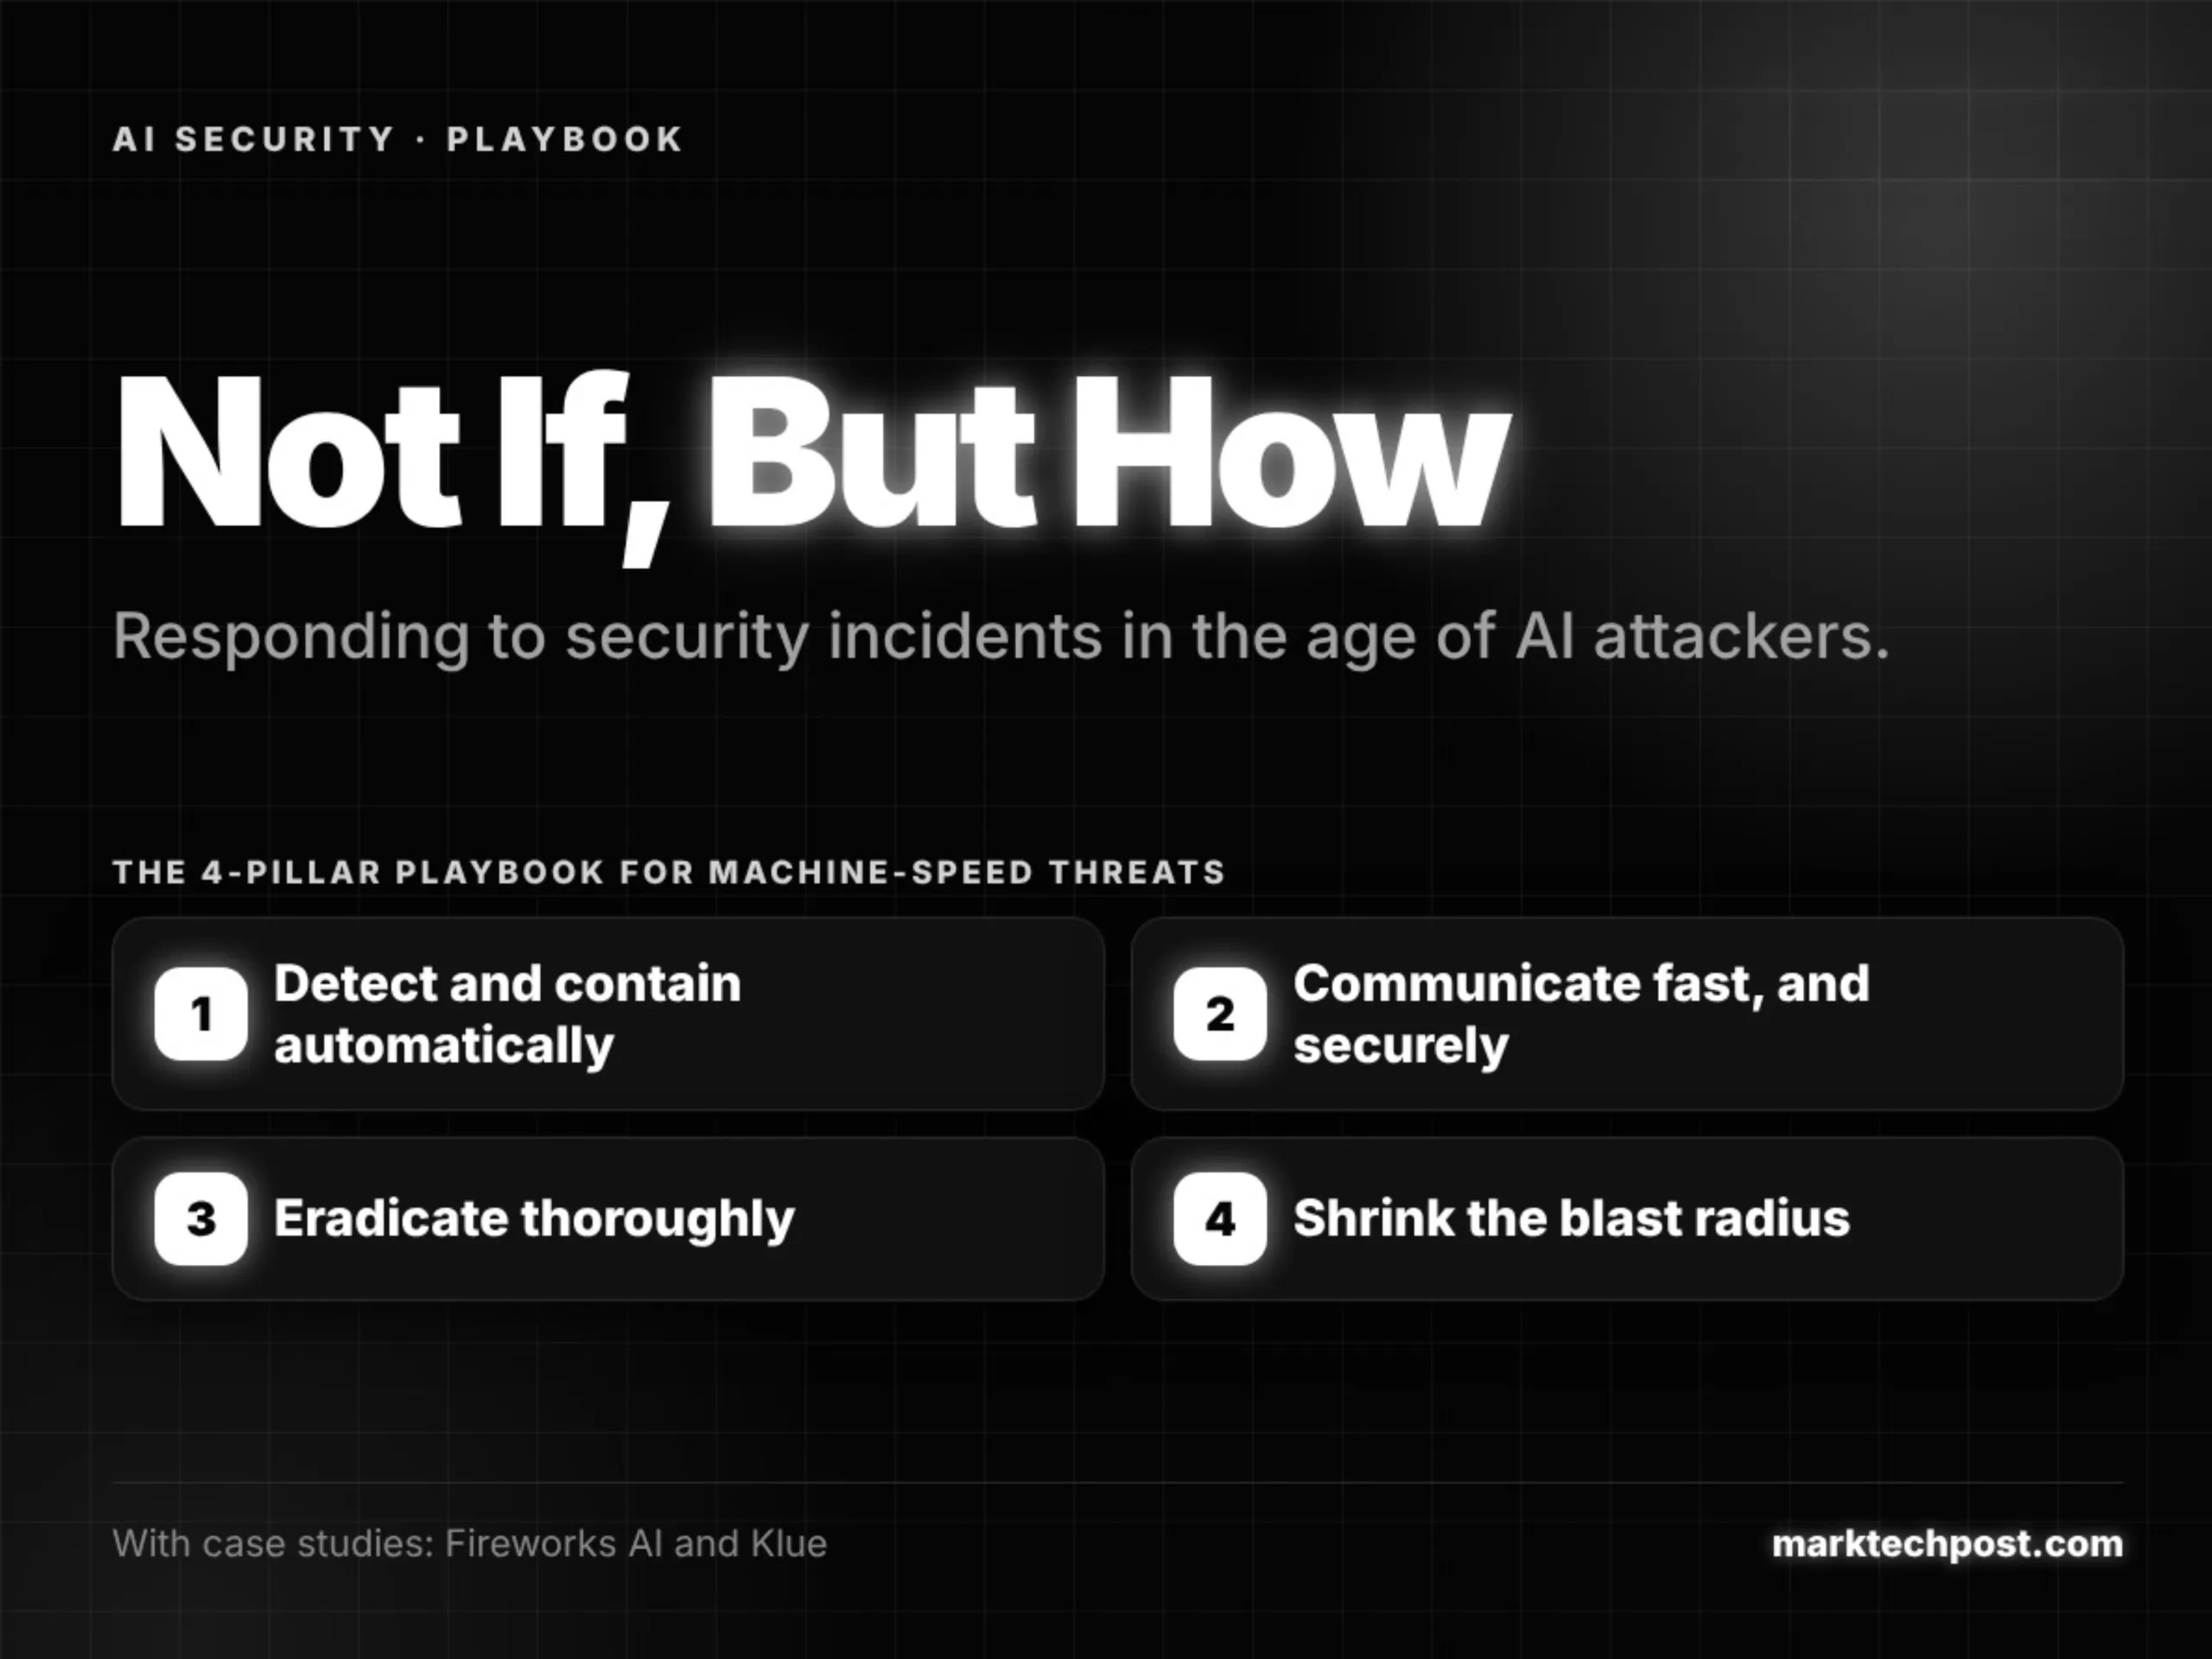
Not If, But How: Responding to Security Incidents in the Age of AI Attackers

AI-powered attackers are driving more frequent attacks on AI infrastructure. This guide reviews 6 months of incidents, sets out a 4-pillar incident response playbook, and shows it in practice through Fireworks AI and Klue.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

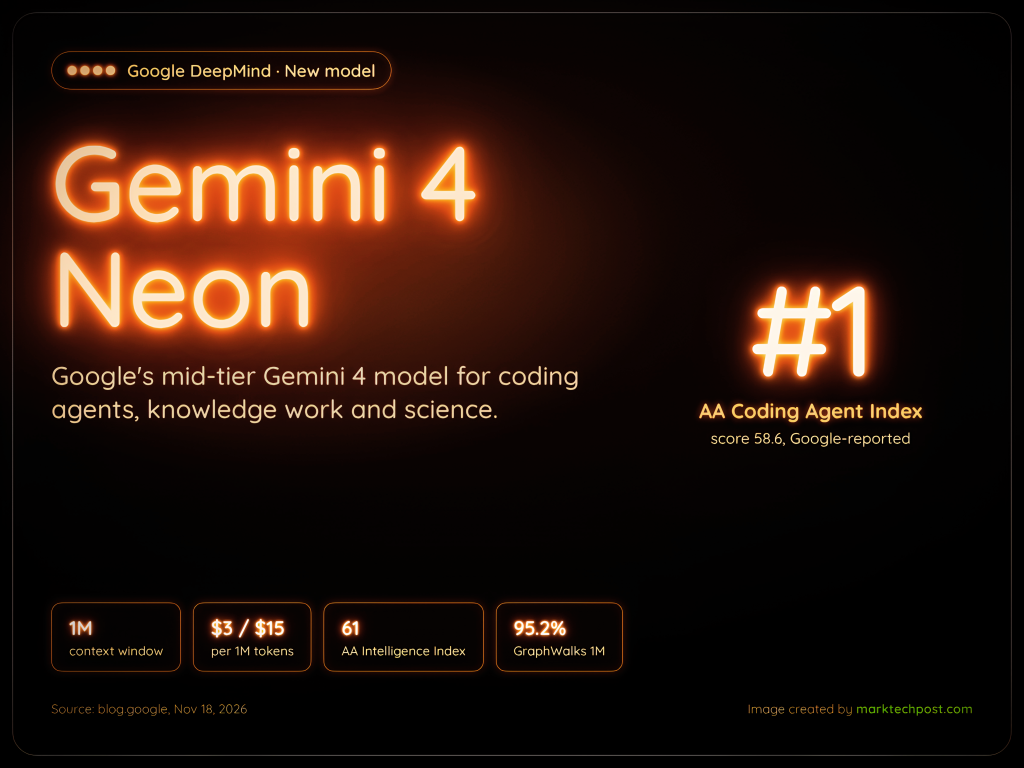
Google DeepMind Releases Gemini 4 Neon: 1M Context, #1 on AA Coding Agent Index

Google released Gemini 4 Neon, a 1M-context Gemini 4 model priced at $3/$15 per million tokens. It scores 61 on the AA Intelligence Index and ranks #1 on AA’s Coding Agent Index.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

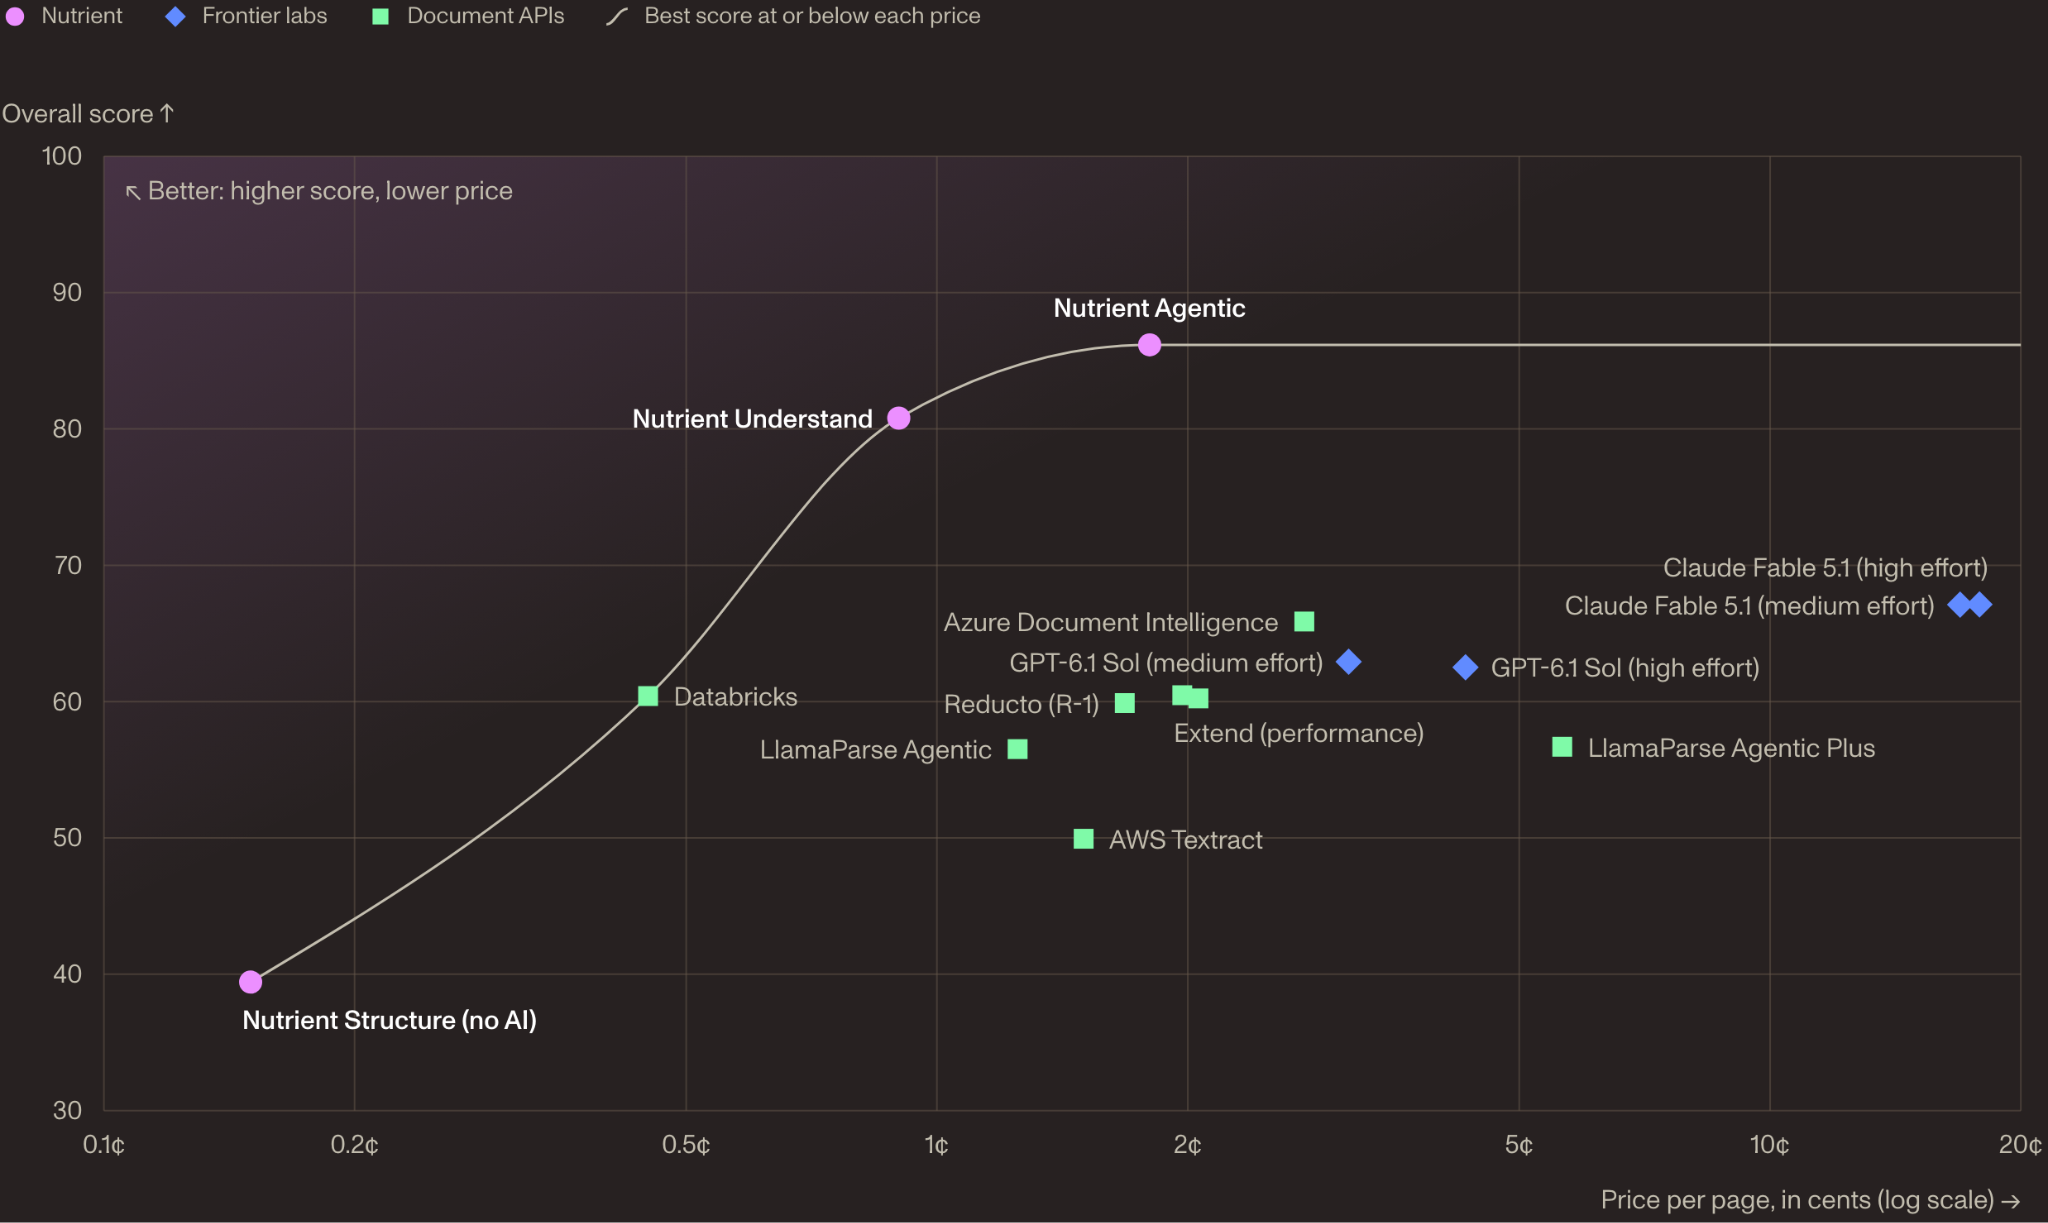
Nutrient Data Extraction API: JSON Matching Your Schema With Per-Field Citations and Confidence

Nutrient Data Extraction API parses PDFs, scans and Office files into JSON matching your schema. Fields carry page, region and match-label citations, and Studio lets teams test before writing code.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

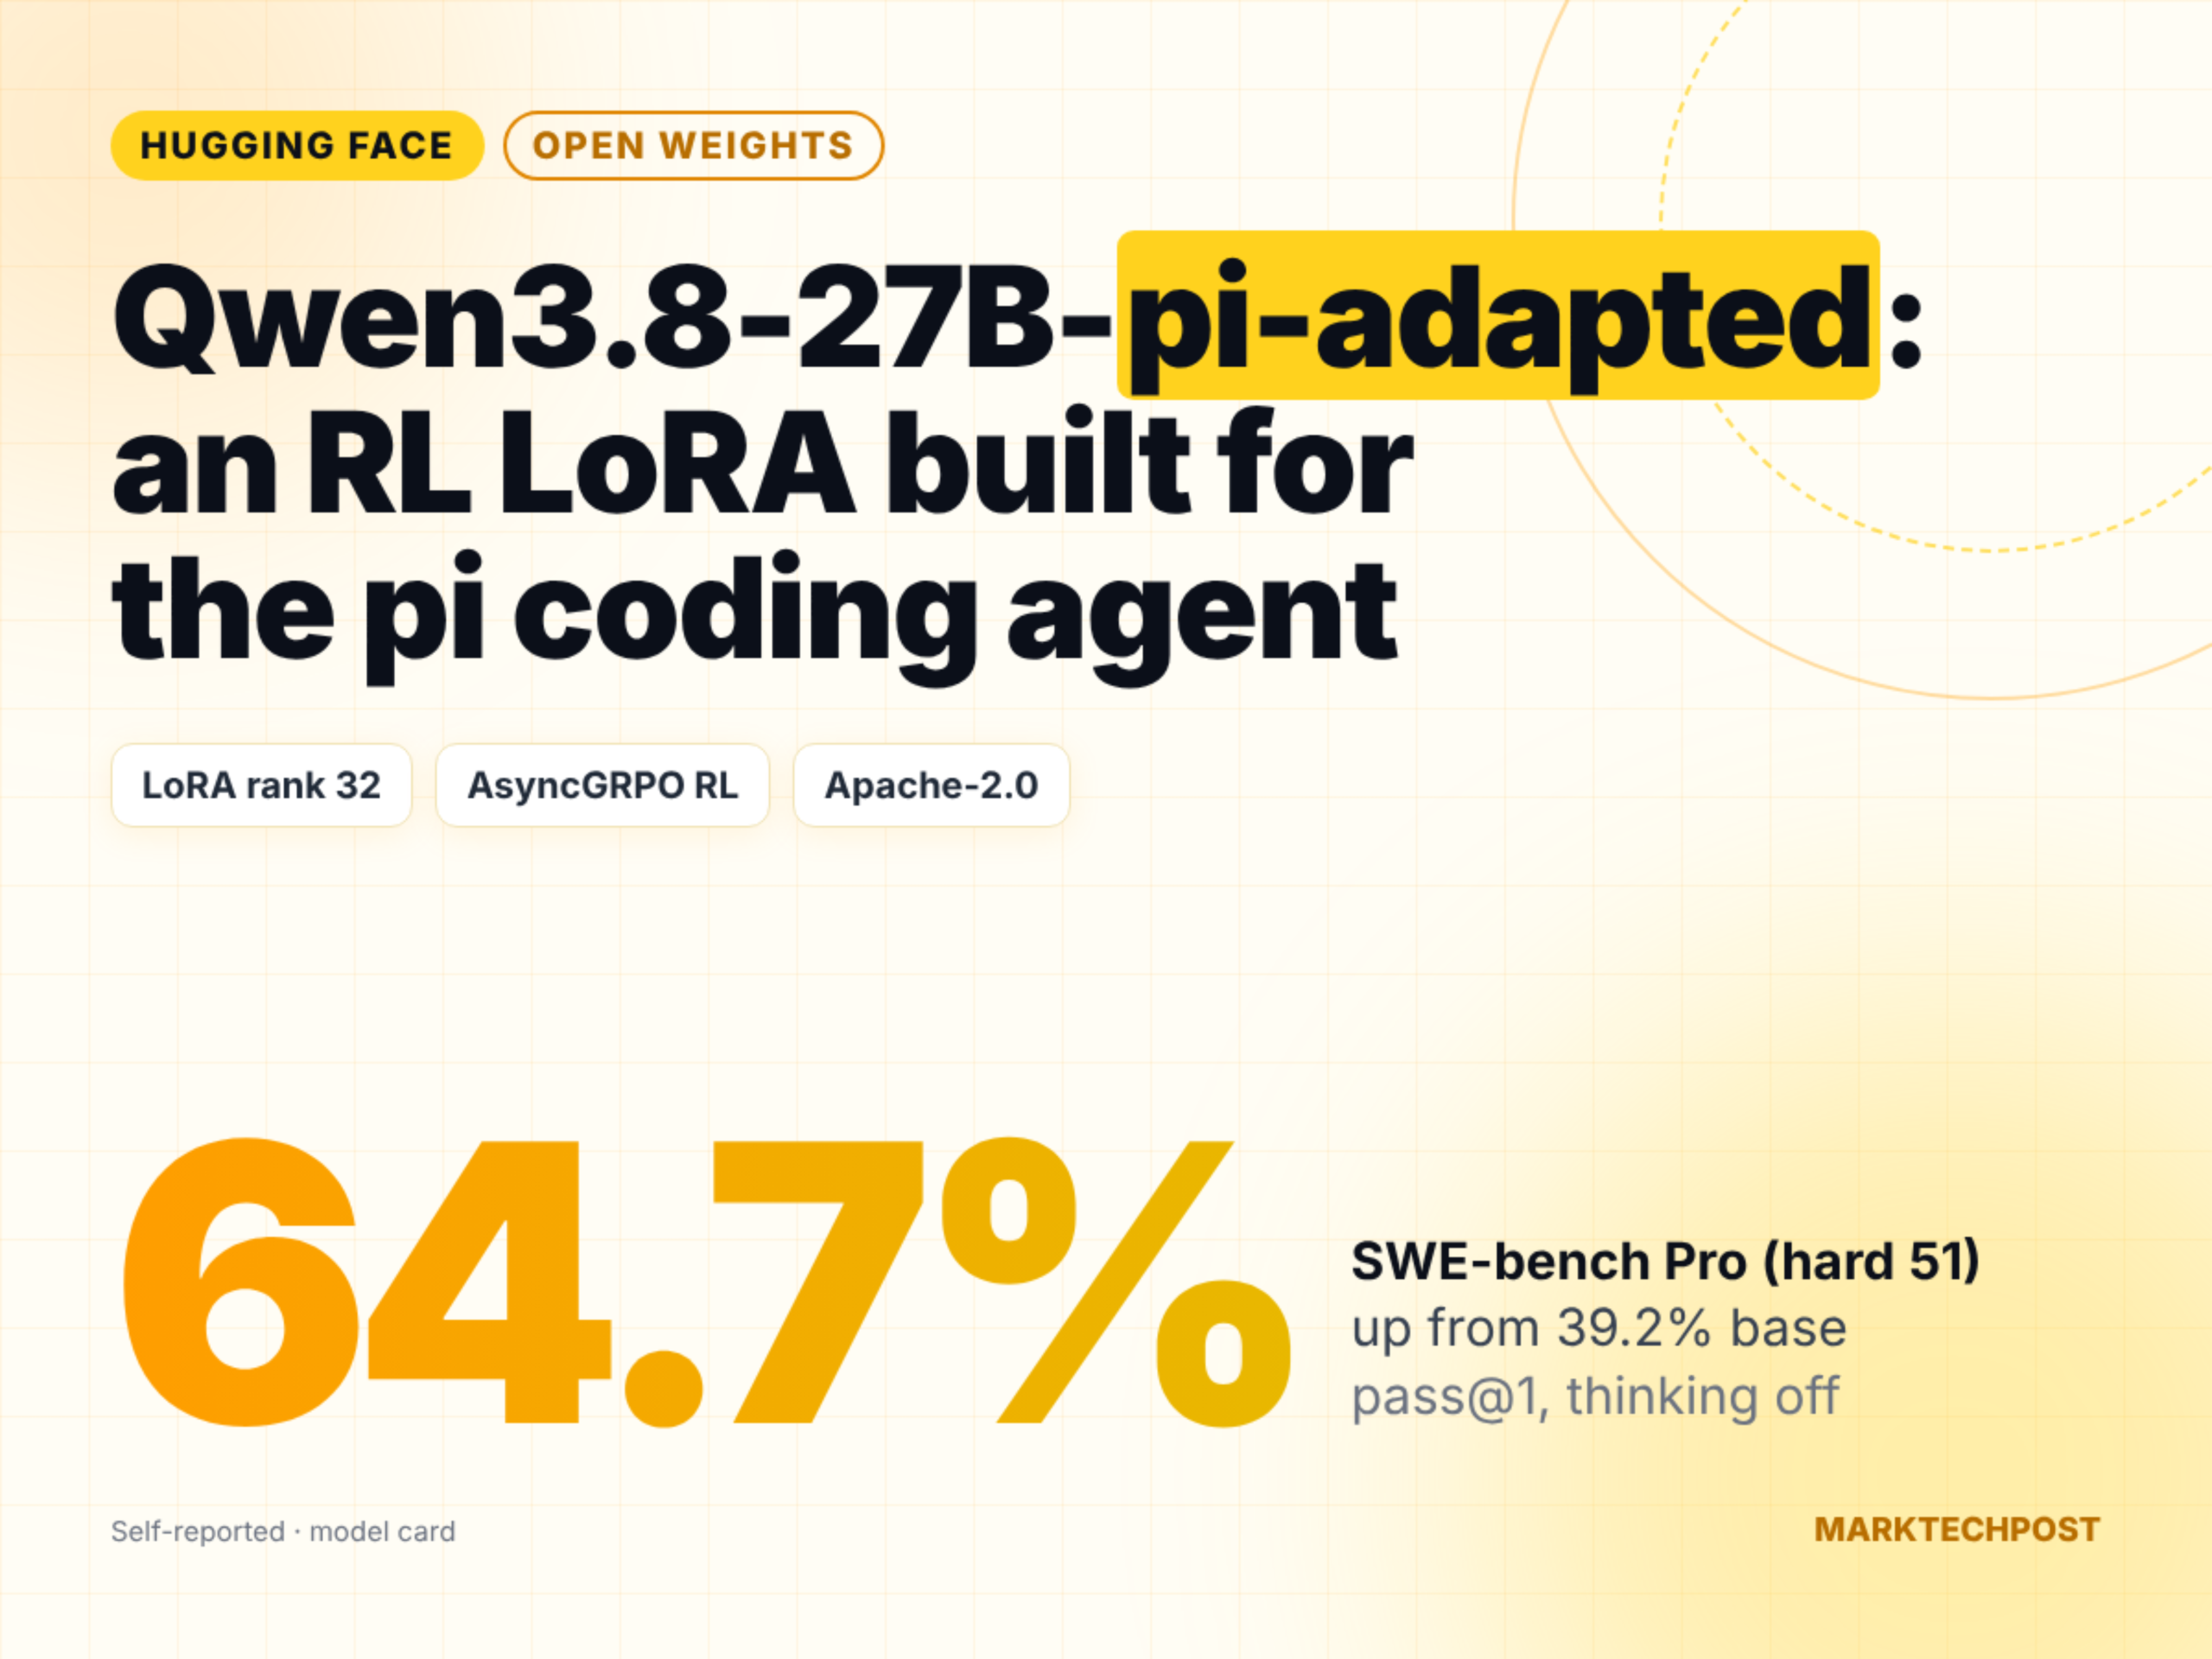
New LoRA Adapter Lifts Qwen3.8 Coding Success From 39% to 65%

Hugging Face released Qwen3.8-27B-pi-adapted, an Apache-2.0 LoRA adapter trained with reinforcement learning for the pi coding agent. It lifts SWE-bench Pro hard-51 pass@1 from 39.2% to 64.7% and Terminal-Bench 2.1 from 39.5% to 55.8%.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

SID AI Releases SID-2 Agentic Search Model With 0.720 NDCG Swarm Mode

SID AI released SID-2, an agentic search model trained with reinforcement learning. A single agent reaches 0.585 NDCG in 3.11 seconds, and a 12-agent SID-2 Swarm scores 0.720 NDCG, above GPT-6 Astra on SID’s benchmark.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

Anthropic Adds Code Mode to Claude Code: Claude Now Chains Tool Calls in JavaScript

Anthropic has added Code Mode to Claude Code v2.1.323. The experimental feature lets Claude write JavaScript that chains Bash, Read and Edit calls in 1 step, and keep talking while long commands run.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

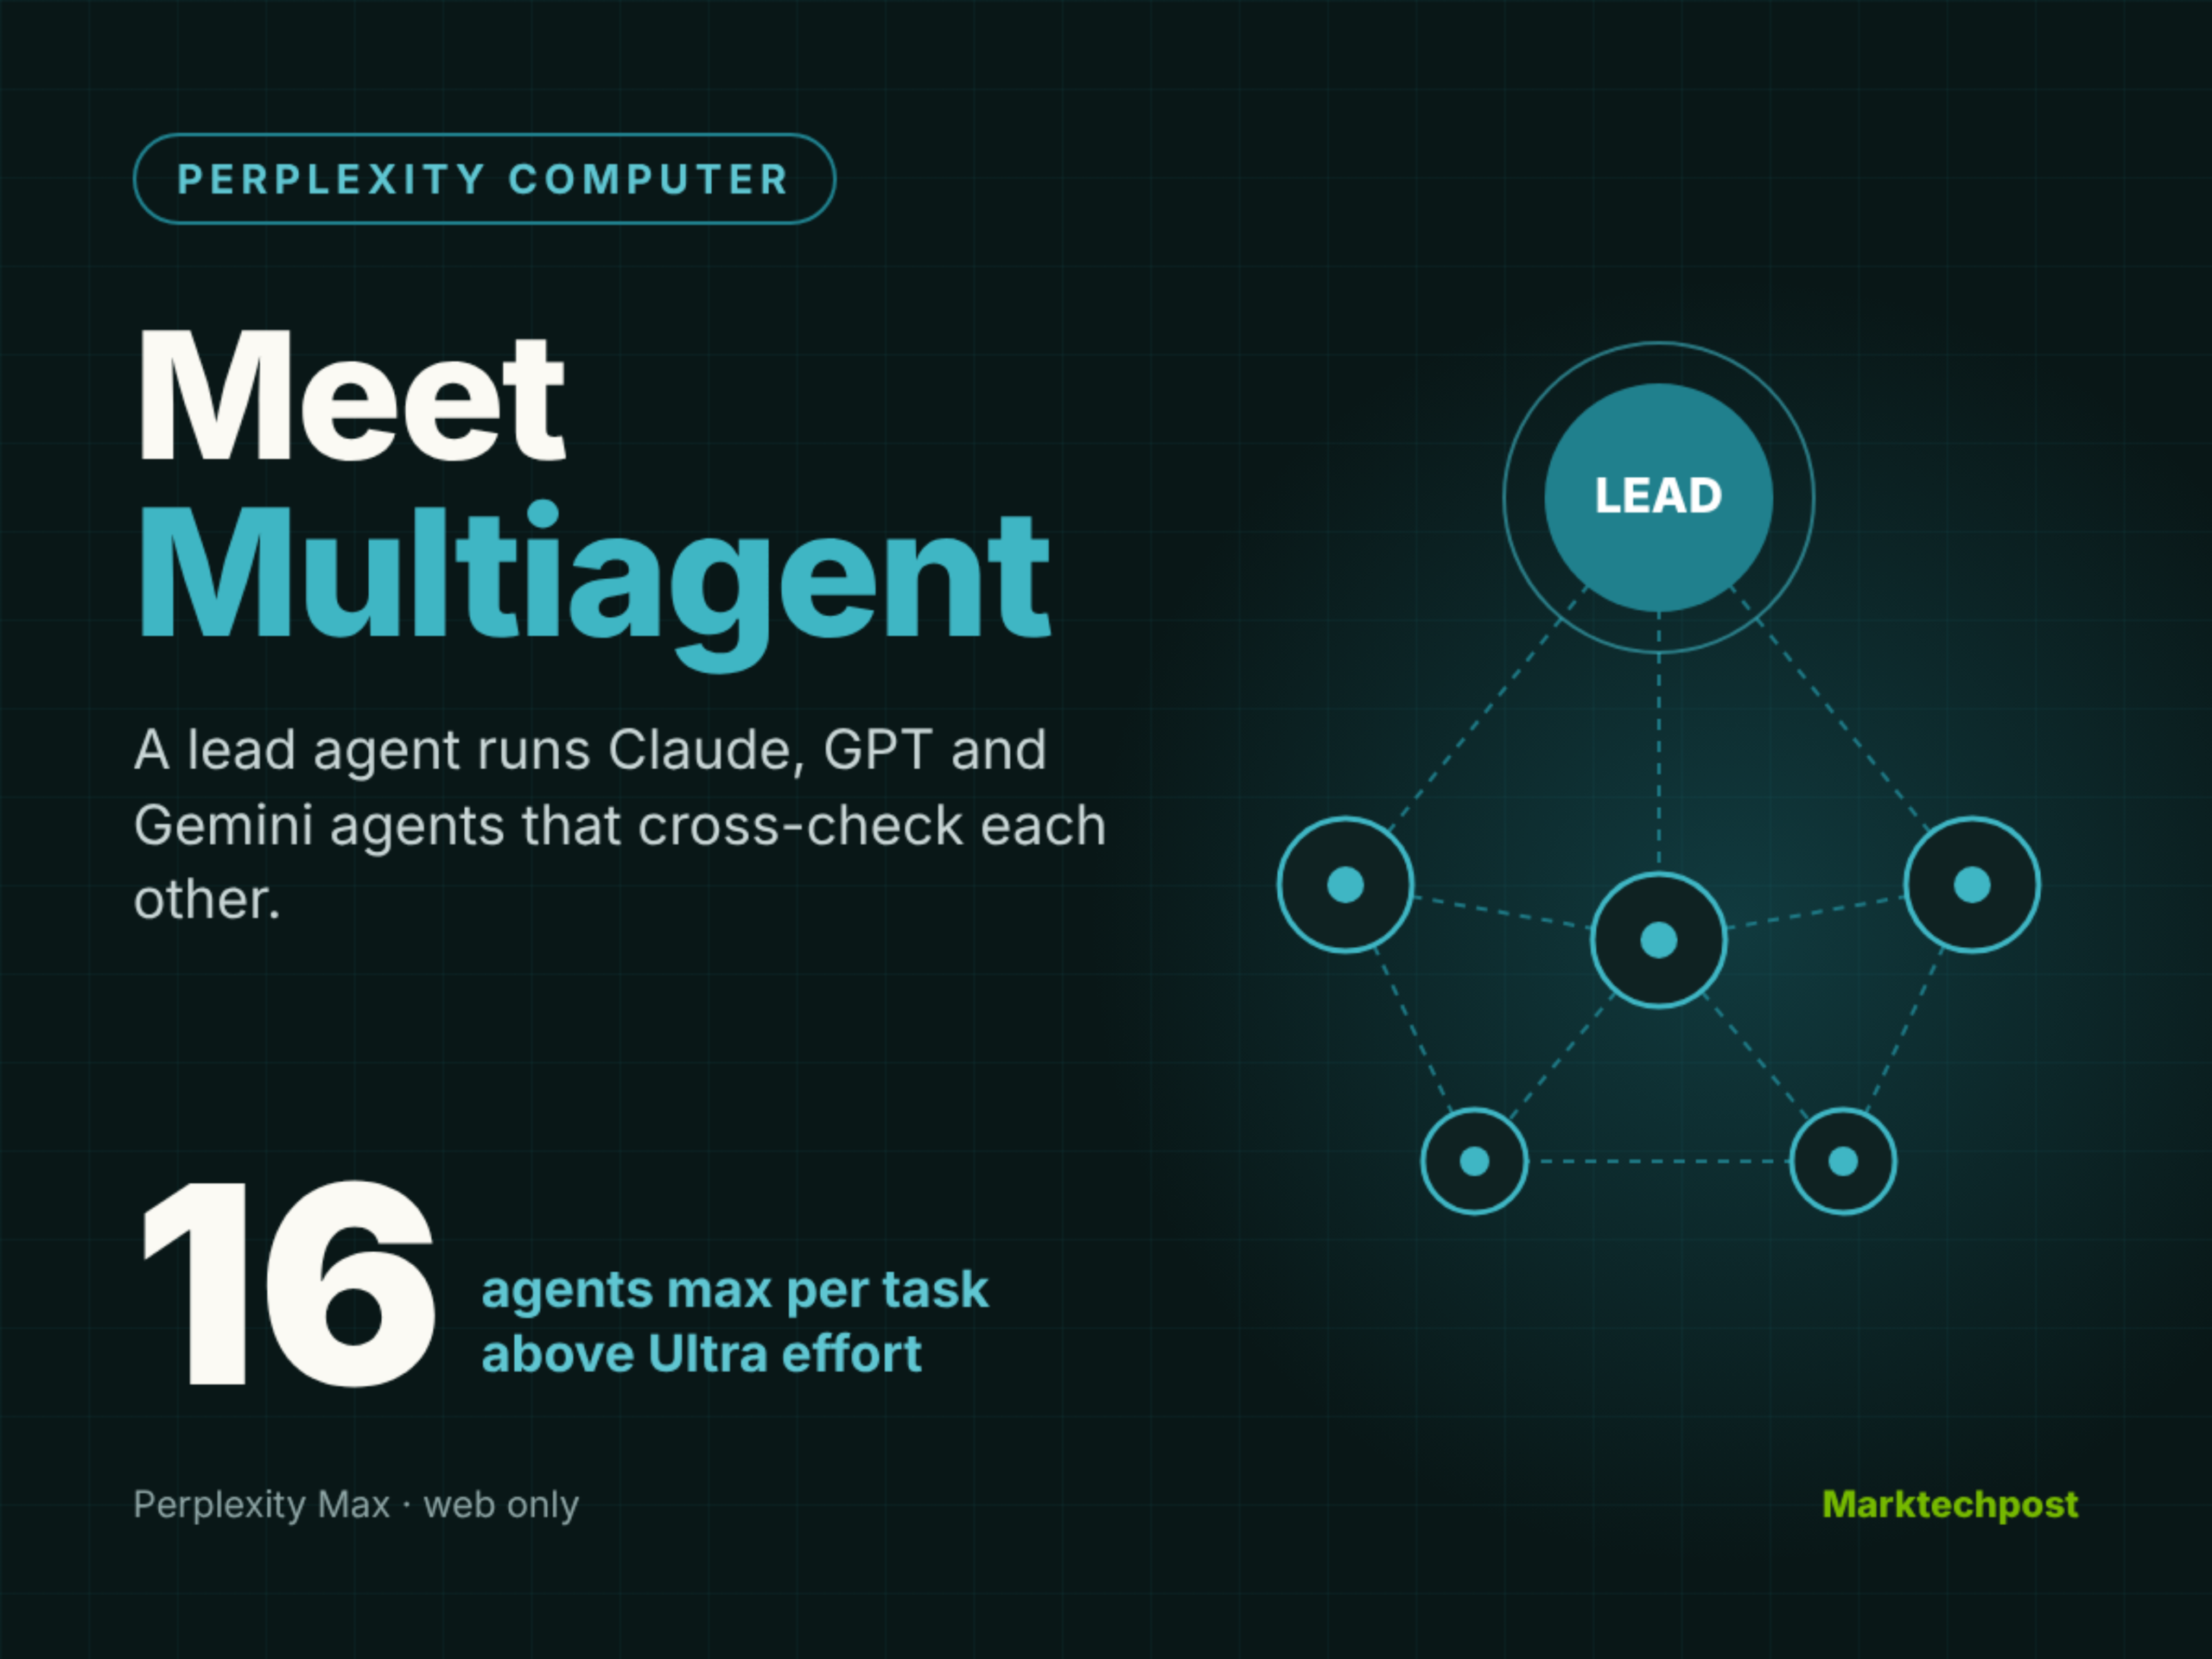
Perplexity Computer Adds Multiagent: Up to 16 AI Agents That Cross-Check Work

Perplexity added Multiagent to Computer, an effort level above Ultra where a lead agent runs up to 16 agents on Claude, GPT and Gemini models that share findings and check each other’s work.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

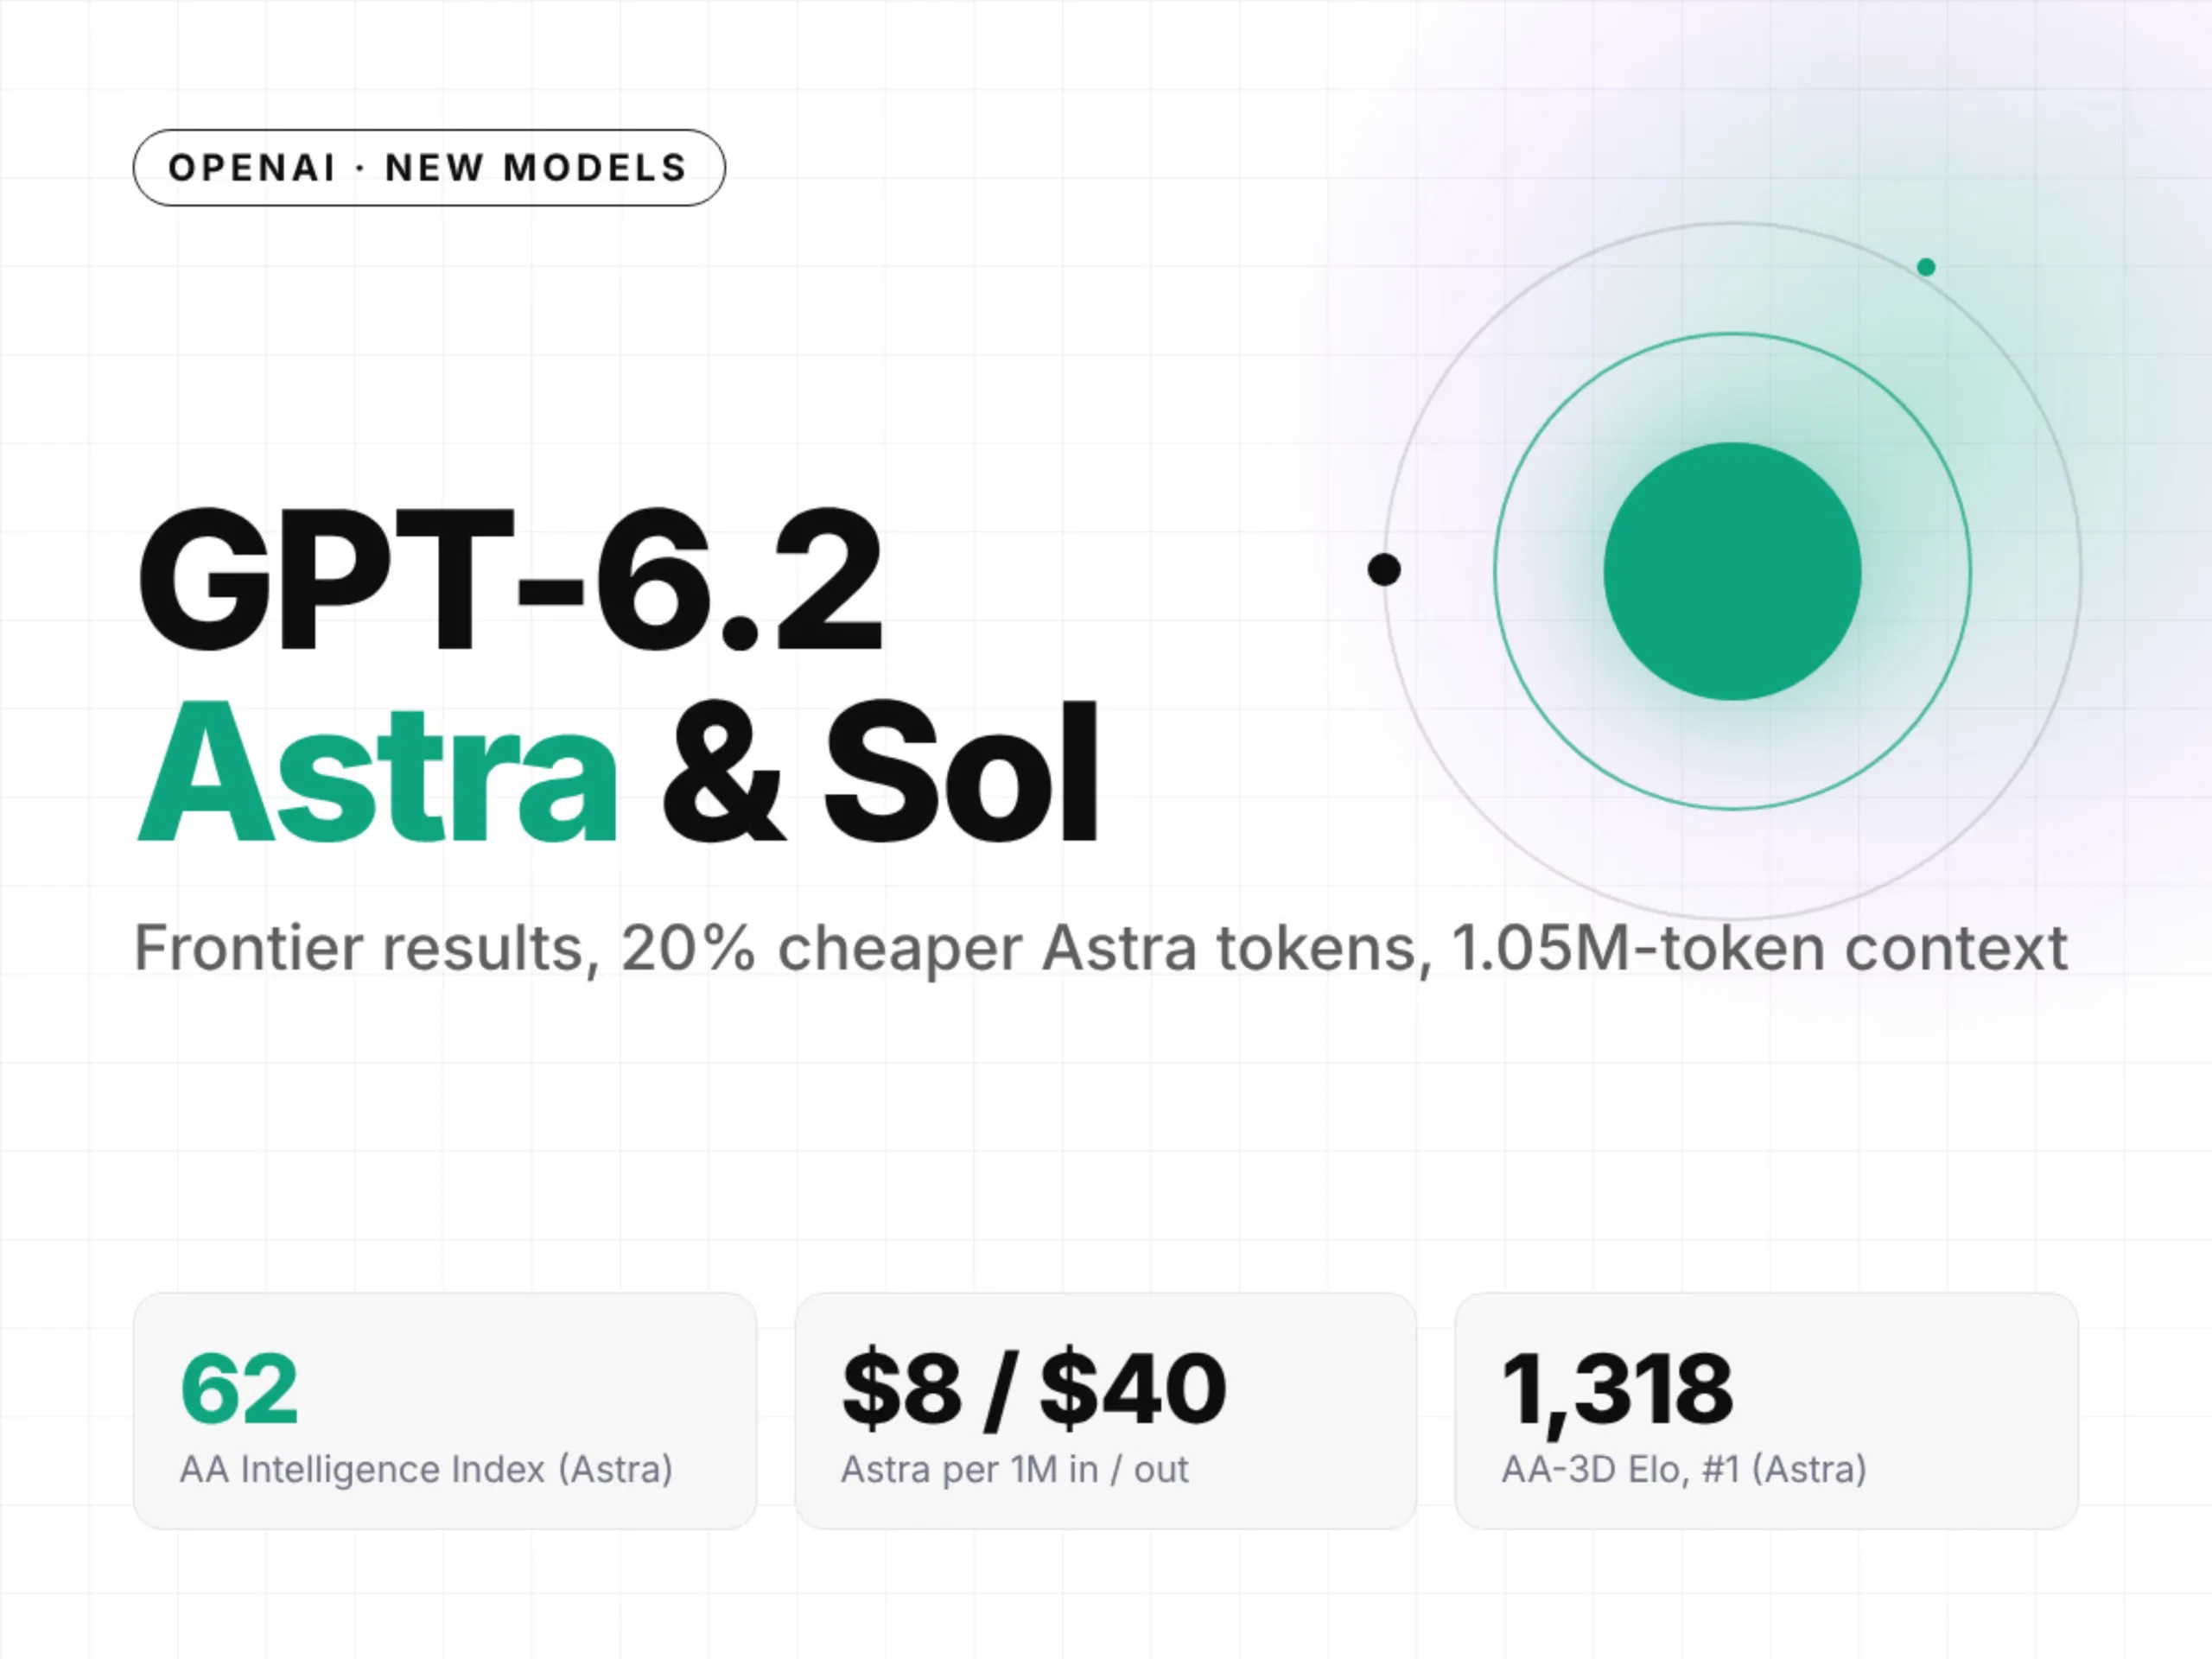
OpenAI Releases GPT-6.2 Astra and Sol With a 20% Cheaper Astra API

OpenAI released GPT-6.2 Astra and GPT-6.2 Sol on November 17, 2026. Astra's API price drops 20% to $8/$40 per million tokens, and it ranks second on the Artificial Analysis Intelligence Index.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

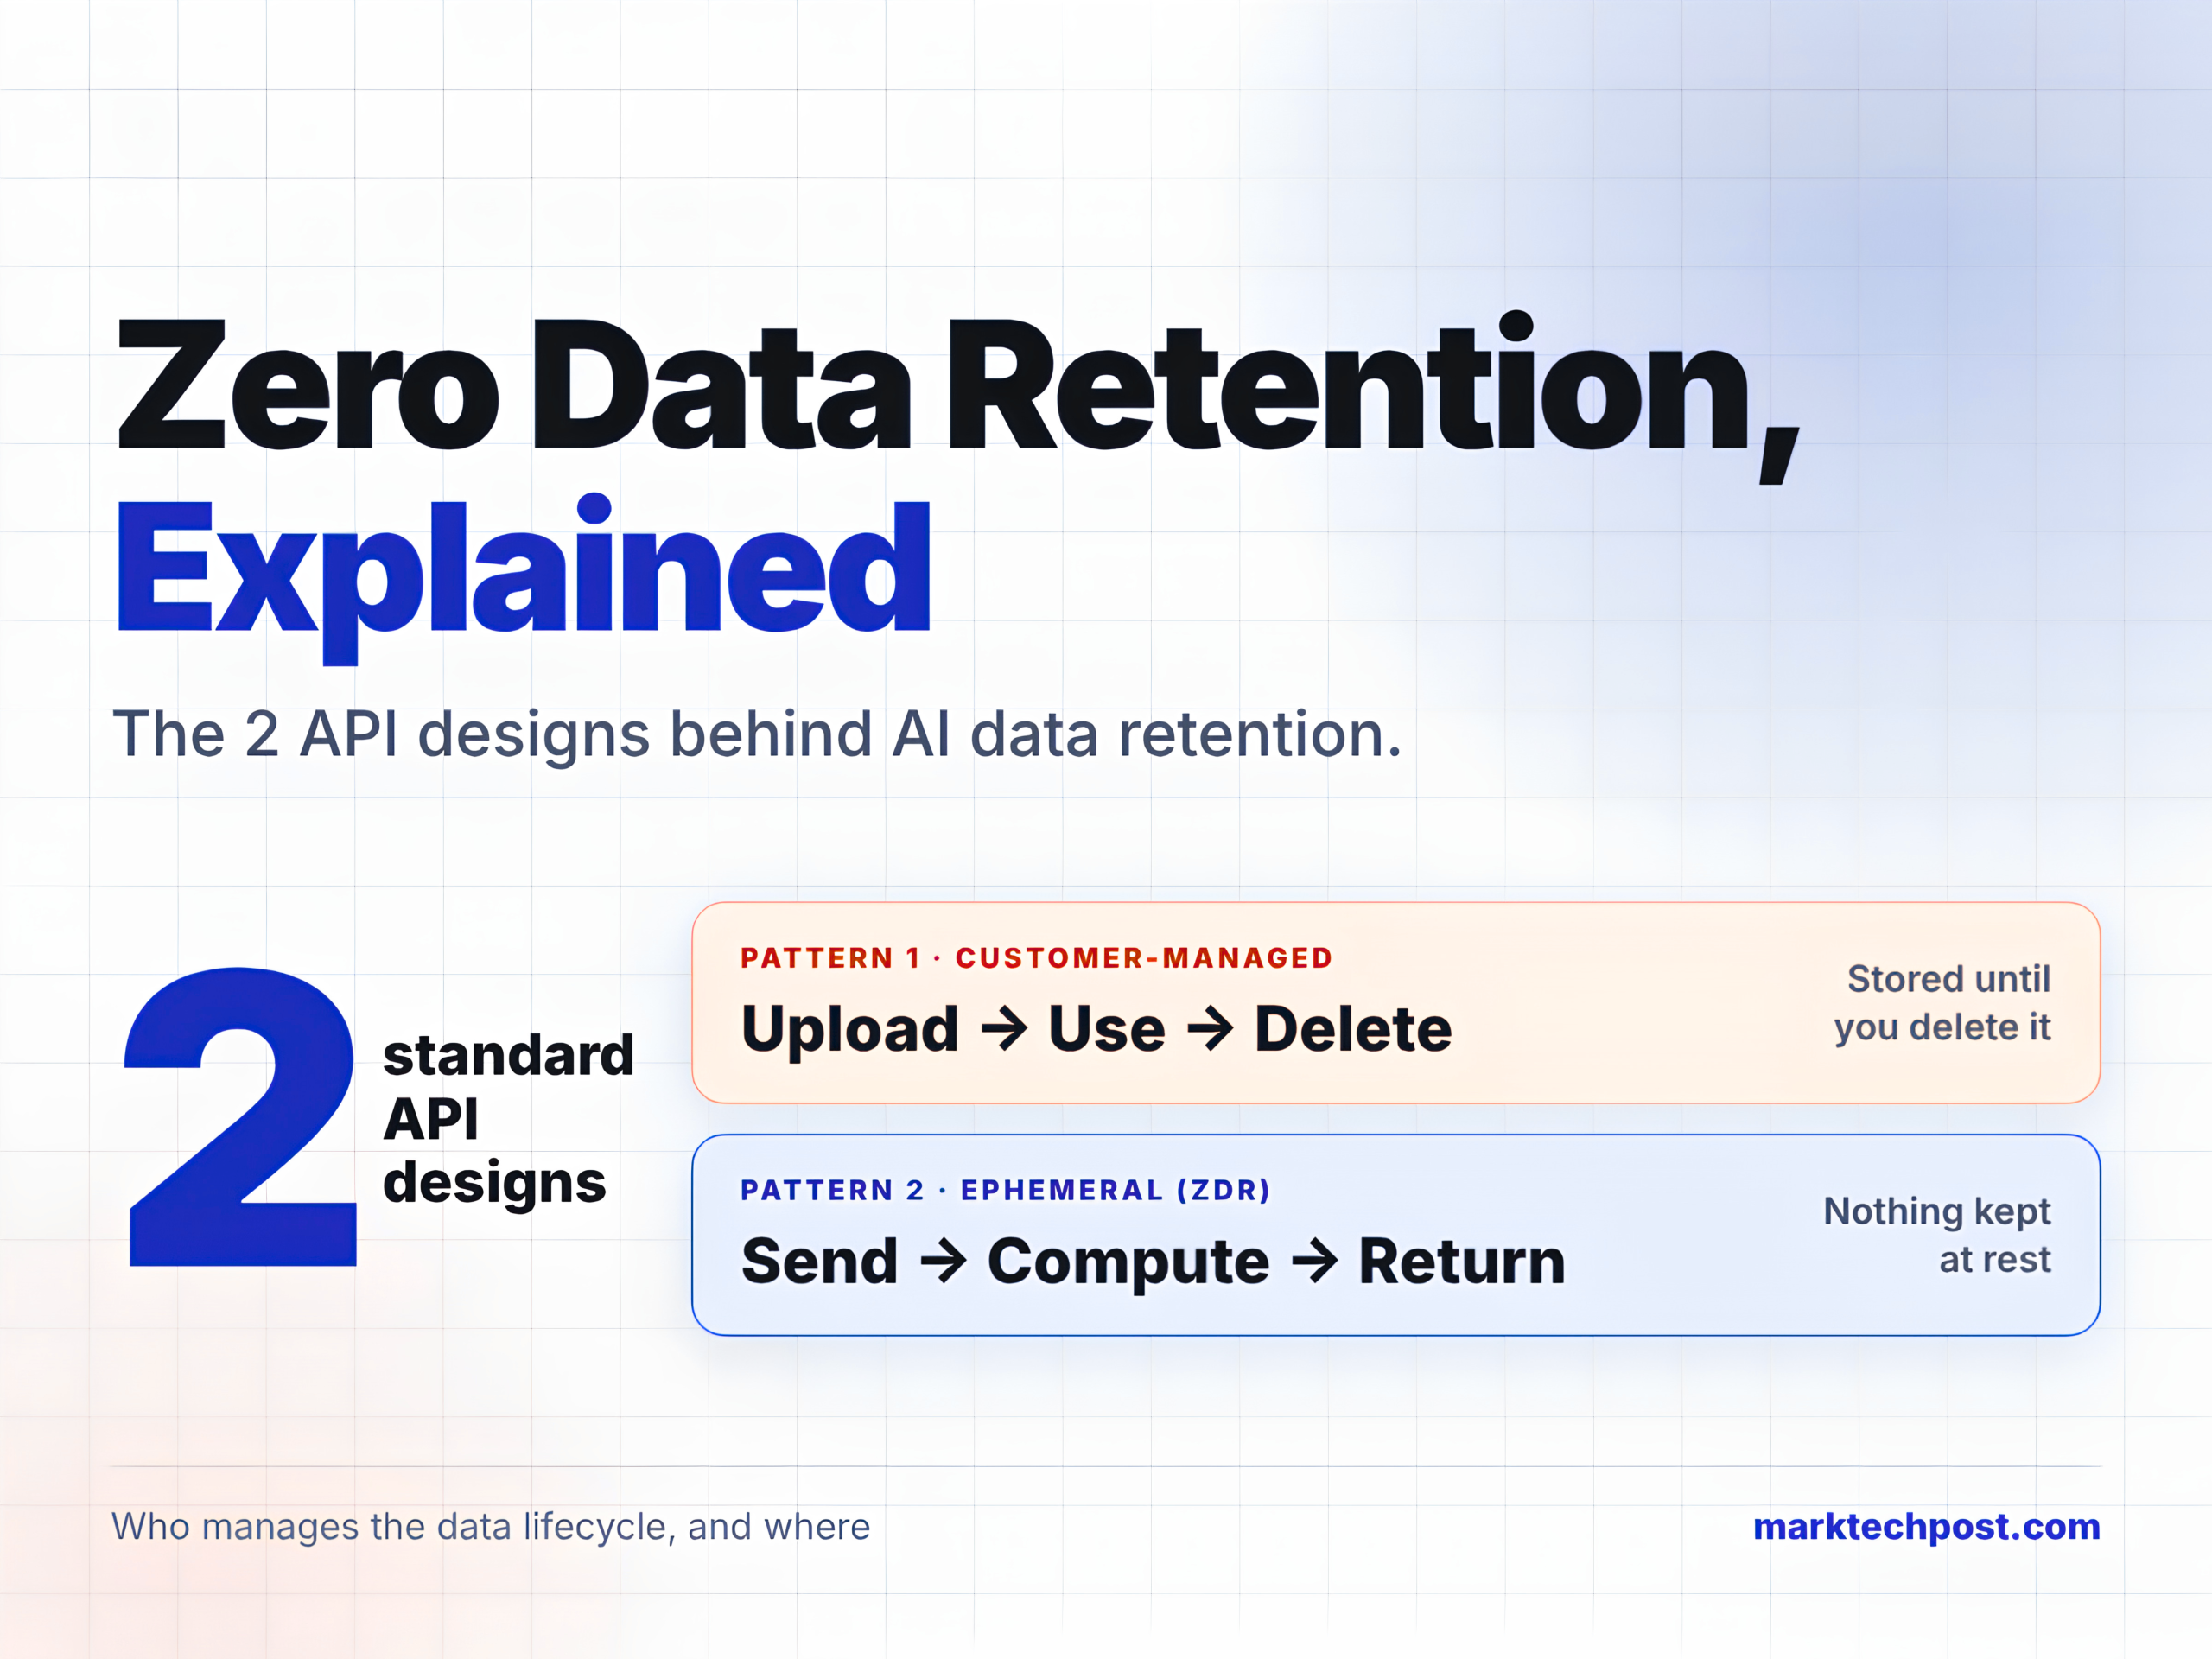
Clearing Up the Confusion on AI Data Retention: Two Standard Designs Explained

Zero data retention applies to specific AI endpoints, not whole vendors. This guide explains the 2 standard API designs for data retention, who manages deletion in each, and 6 checks for developers.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

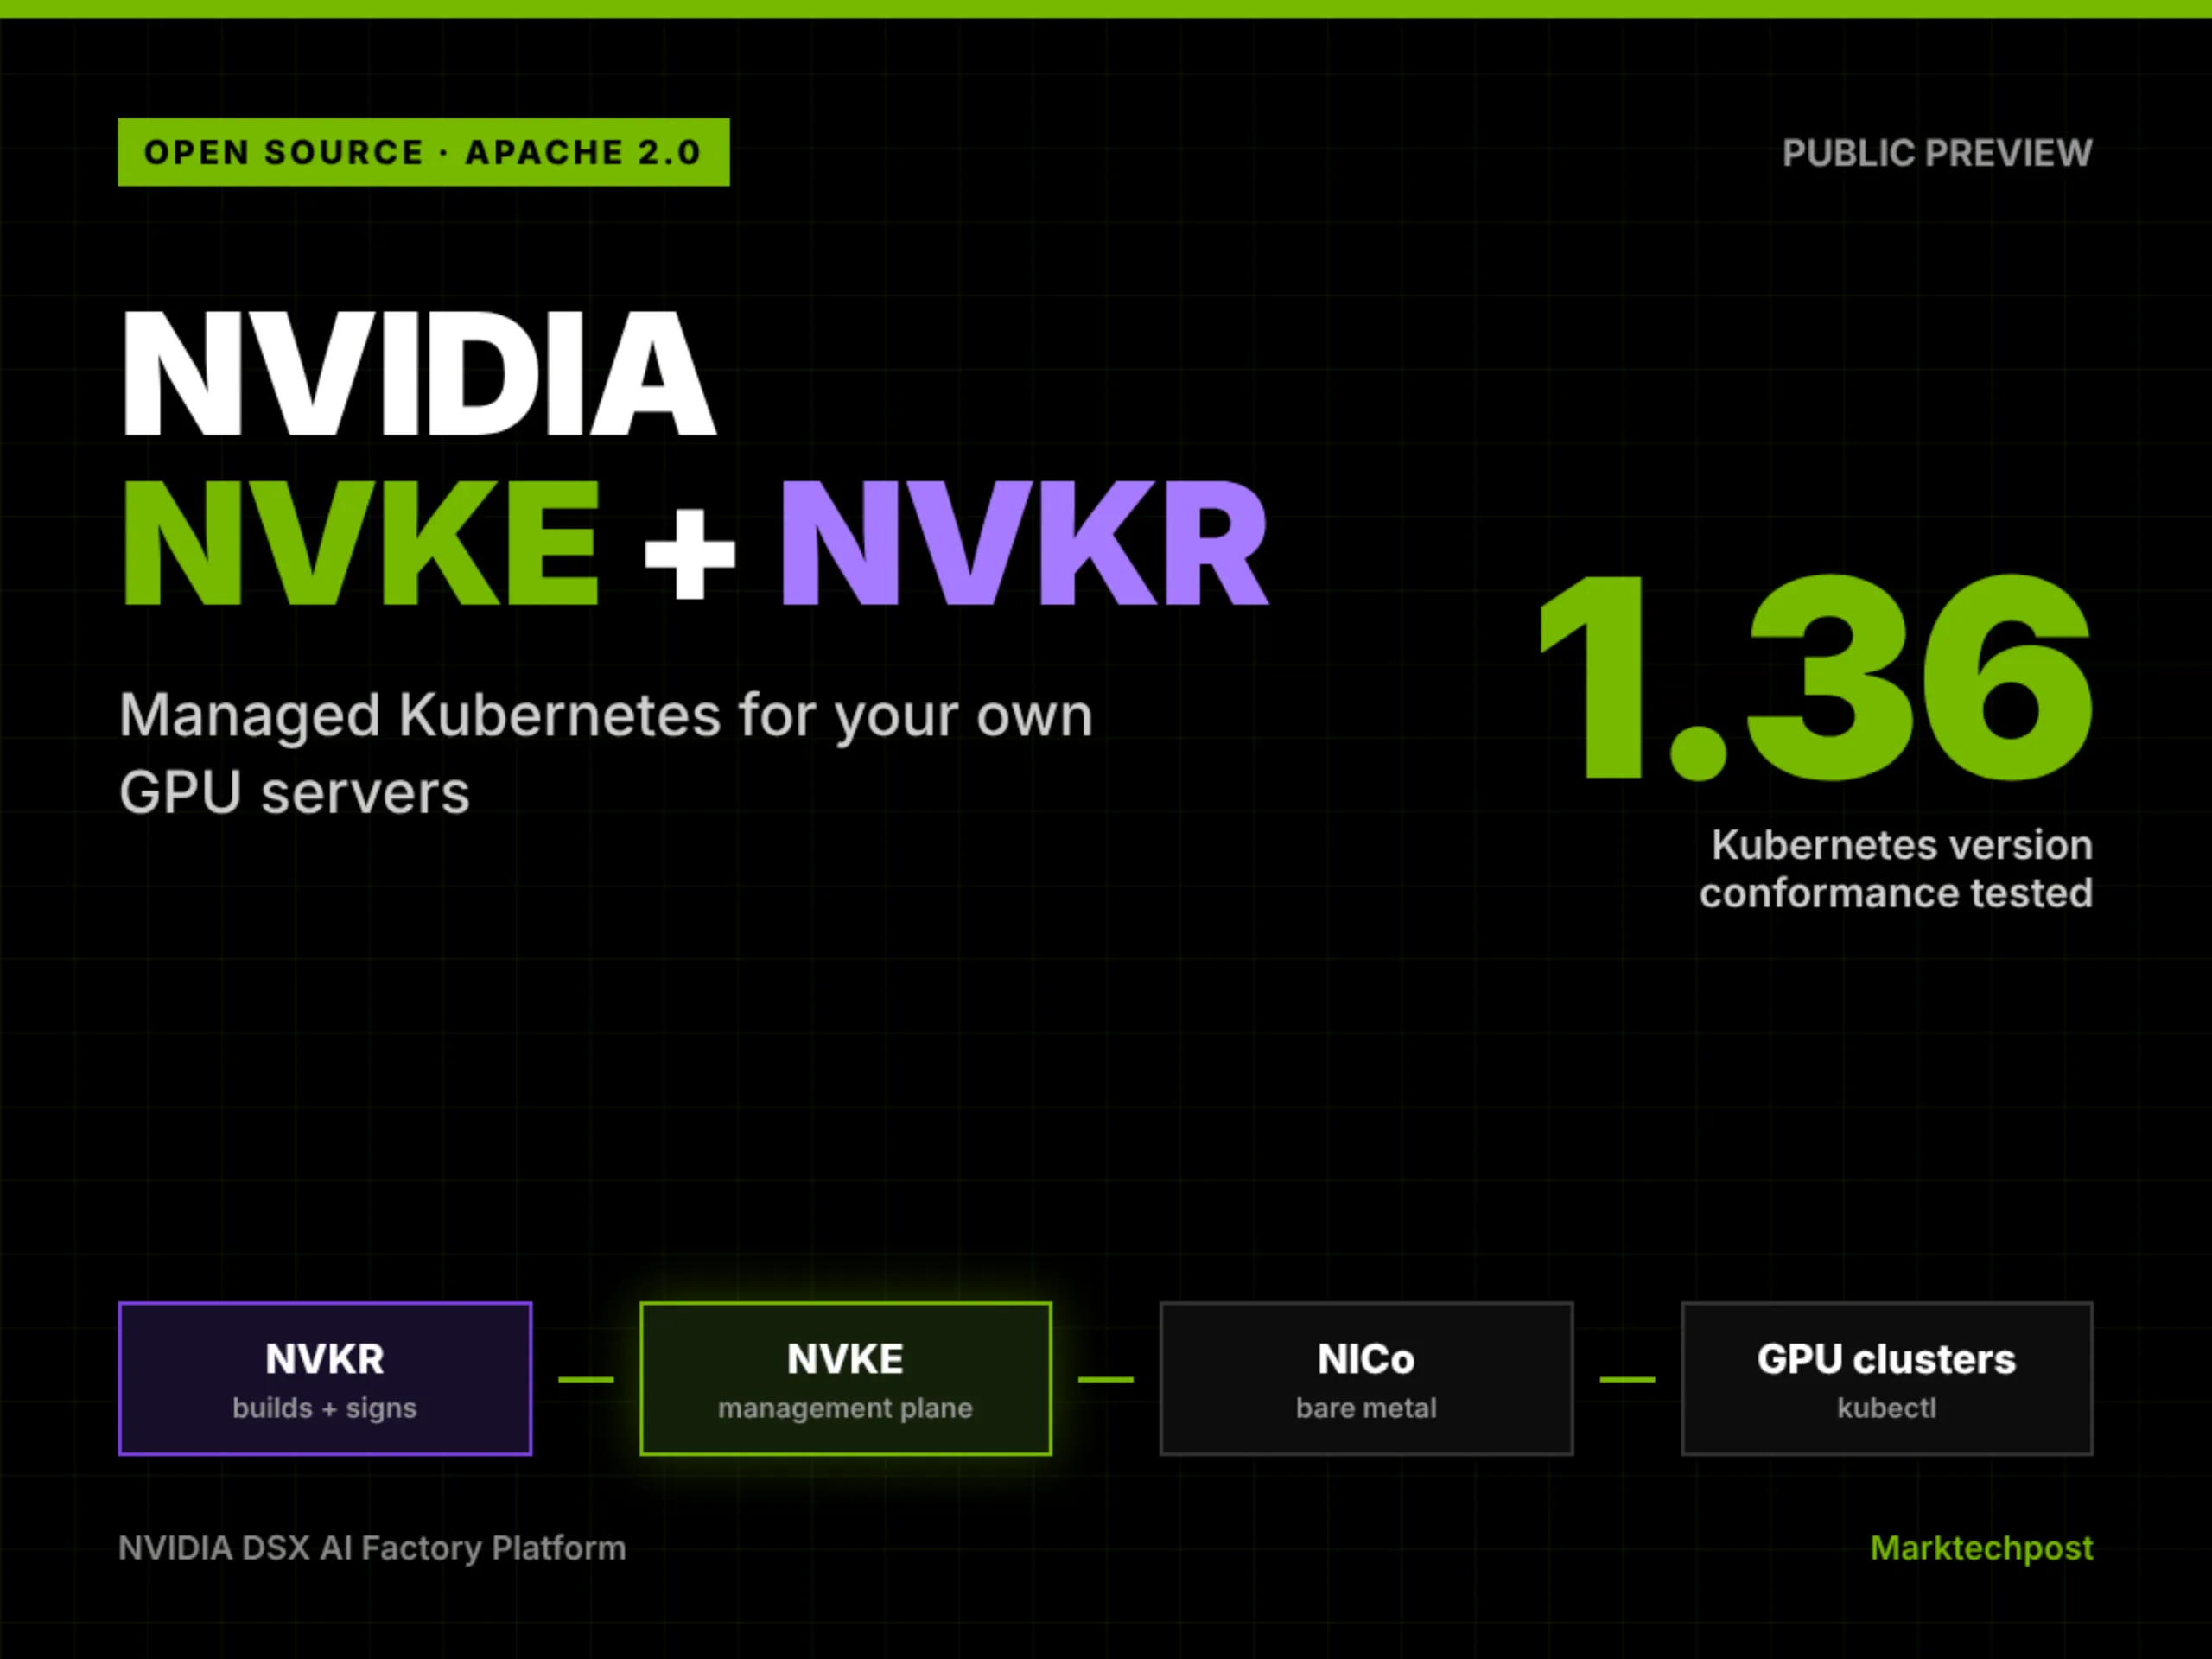
NVIDIA Open-Sources NVKE and NVKR for Managed Kubernetes on GPU Infrastructure

NVIDIA has open-sourced NVIDIA Kubernetes Engine (NVKE) and NVIDIA Kubernetes Recipes (NVKR) under Apache 2.0. Together they let AI factories run a managed Kubernetes service on their own bare-metal GPU servers. Both are in public preview.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

Sarvam Launches Sarvam Token Factory: Bringing India-Hosted Inference to 8 Open Models

Sarvam Token Factory is now open to everyone. It serves Sarvam 105B, GLM 5.3, DeepSeek V4.1 Flash, Kimi K3.1 Pro and Gemma 4 31B from GPU clusters in India through one OpenAI-compatible API.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

Liquid AI Releases d1.2 and d1.2-ultra: Omnimodal Decision Models That Top the AA Decision Index

Liquid AI released d1.2 and d1.2-ultra, decision models that read text, images and audio and return calibrated probabilities with zero output tokens. d1.2-ultra scores 75 on the Artificial Analysis Decision Index v2.1.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

Meet Meta’s JiTTests: LLM-Generated Tests Designed to Fail Before Risky Code Lands

Meta has moved Catching JiTTests into production. The LLM system writes tests designed to fail on risky diffs, and caught 74 privacy SEVs before landing in H1 2026, with a 60% engineer-reported true-positive rate.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

Alibaba Releases Qwen4-Max: 2.4T MoE, 71B Active, 1M Context

Alibaba released Qwen4-Max, a proprietary 2.4T-parameter MoE model with 71B active parameters, native vision and a 1M-token context. It costs $1.5/M input tokens and cuts Work360 cost per task by 62%.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

Hark Releases Handoff², a 2x Faster Computer-Use Agent for Hark Pro

Hark has released Handoff², the computer-use agent inside Hark Pro. It averages 2x faster than v1, completes 82% of 478 internal web tasks, and learned to batch actions through latency-penalized RL.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

Bland Launches Tofu-1, a Full-Duplex Speech-to-Speech Model for Calls

Bland has released Tofu-1, a full-duplex speech-to-speech model for noisy, high-stakes phone calls. It is in enterprise research preview, with no published benchmarks, size or pricing yet.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

Cmpnd Releases dspy-wsp: Weight-Space Programming Comes to DSPy

Cmpnd released dspy-wsp, a prototype DSPy optimizer for weight-space programming. A frontier LLM reads a small model’s weights, edits them in a sandbox, and tests each change, with no gradients and about $5 to $10 per run.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

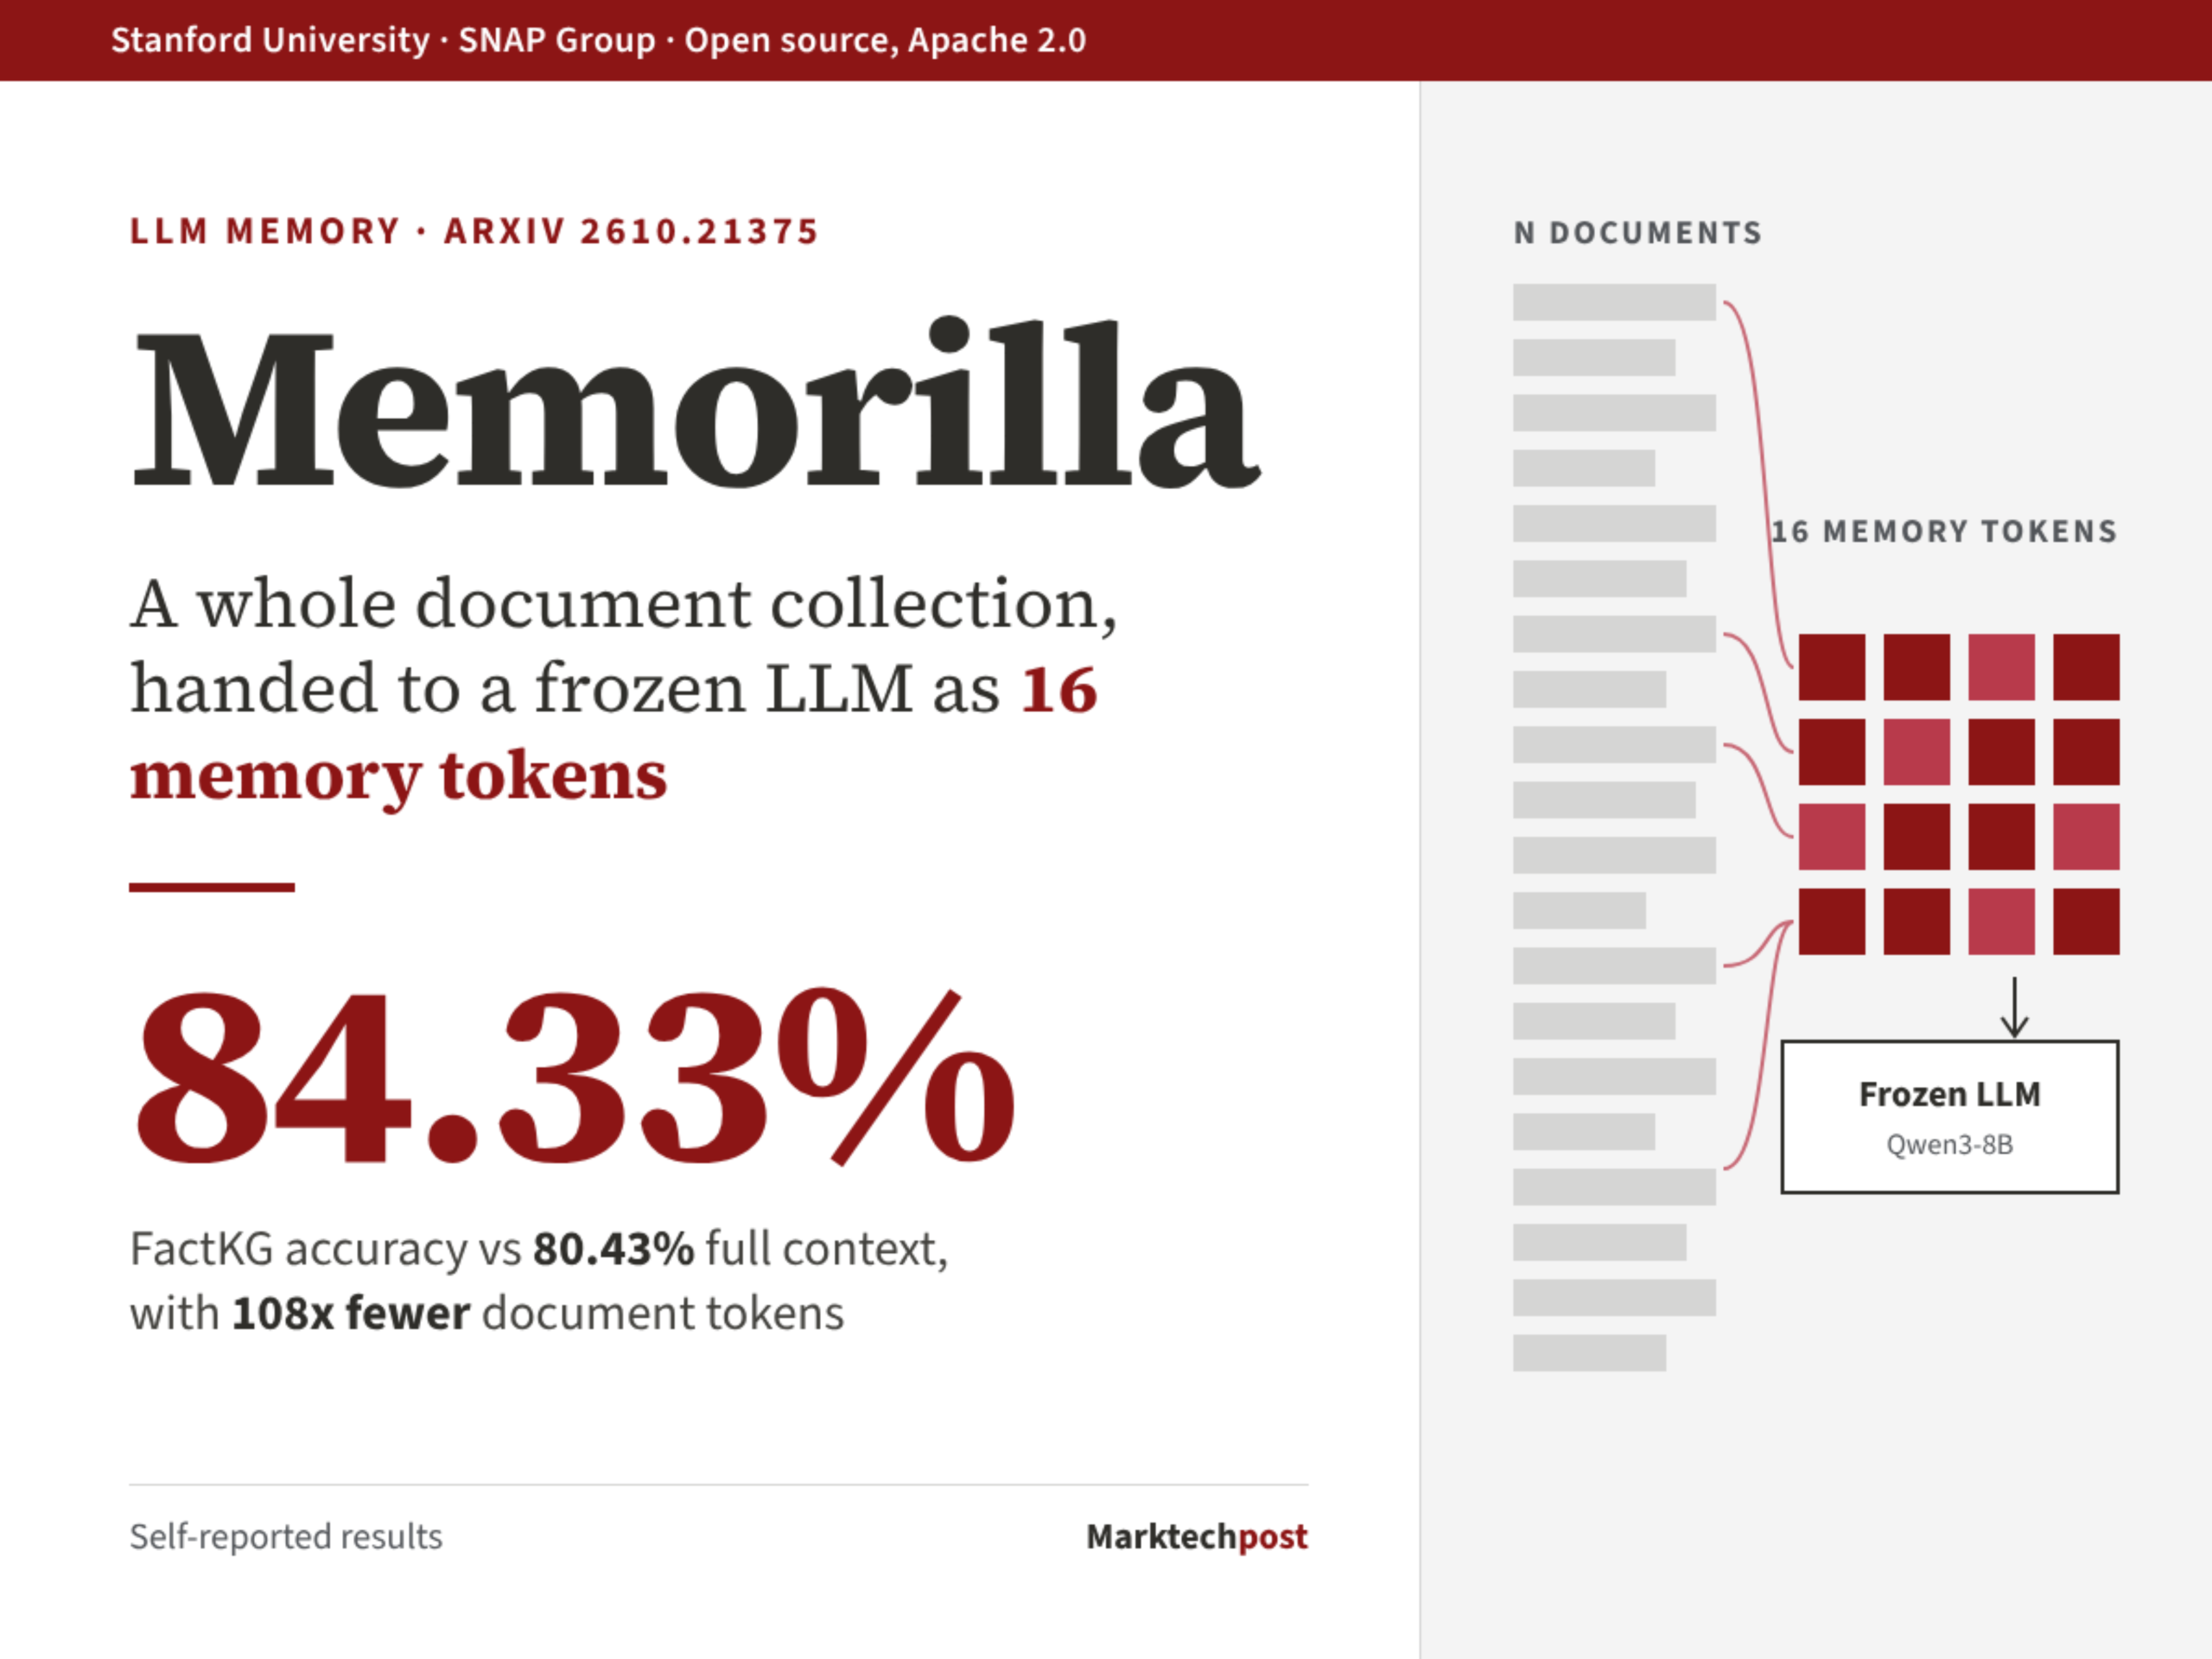
Stanford Research Open-Sources Memorilla, a Latent Memory Module for Frozen LLMs

Stanford researchers released Memorilla, an open-source memory system that compresses a document collection into 16 memory tokens for a frozen Qwen3-8B. It reaches 84.33% on FactKG using 108x fewer document tokens than full context.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

Vercel Releases UI SDK: 50+ UI Behaviors for AI Coding Agents

Vercel Labs released Vercel UI SDK, an Apache-2.0 beta library of 50+ UI behaviors. Coding agents compose them into accessible components for React, Vue, Svelte, Solid and Web Components, with a bridge for direct UI control.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

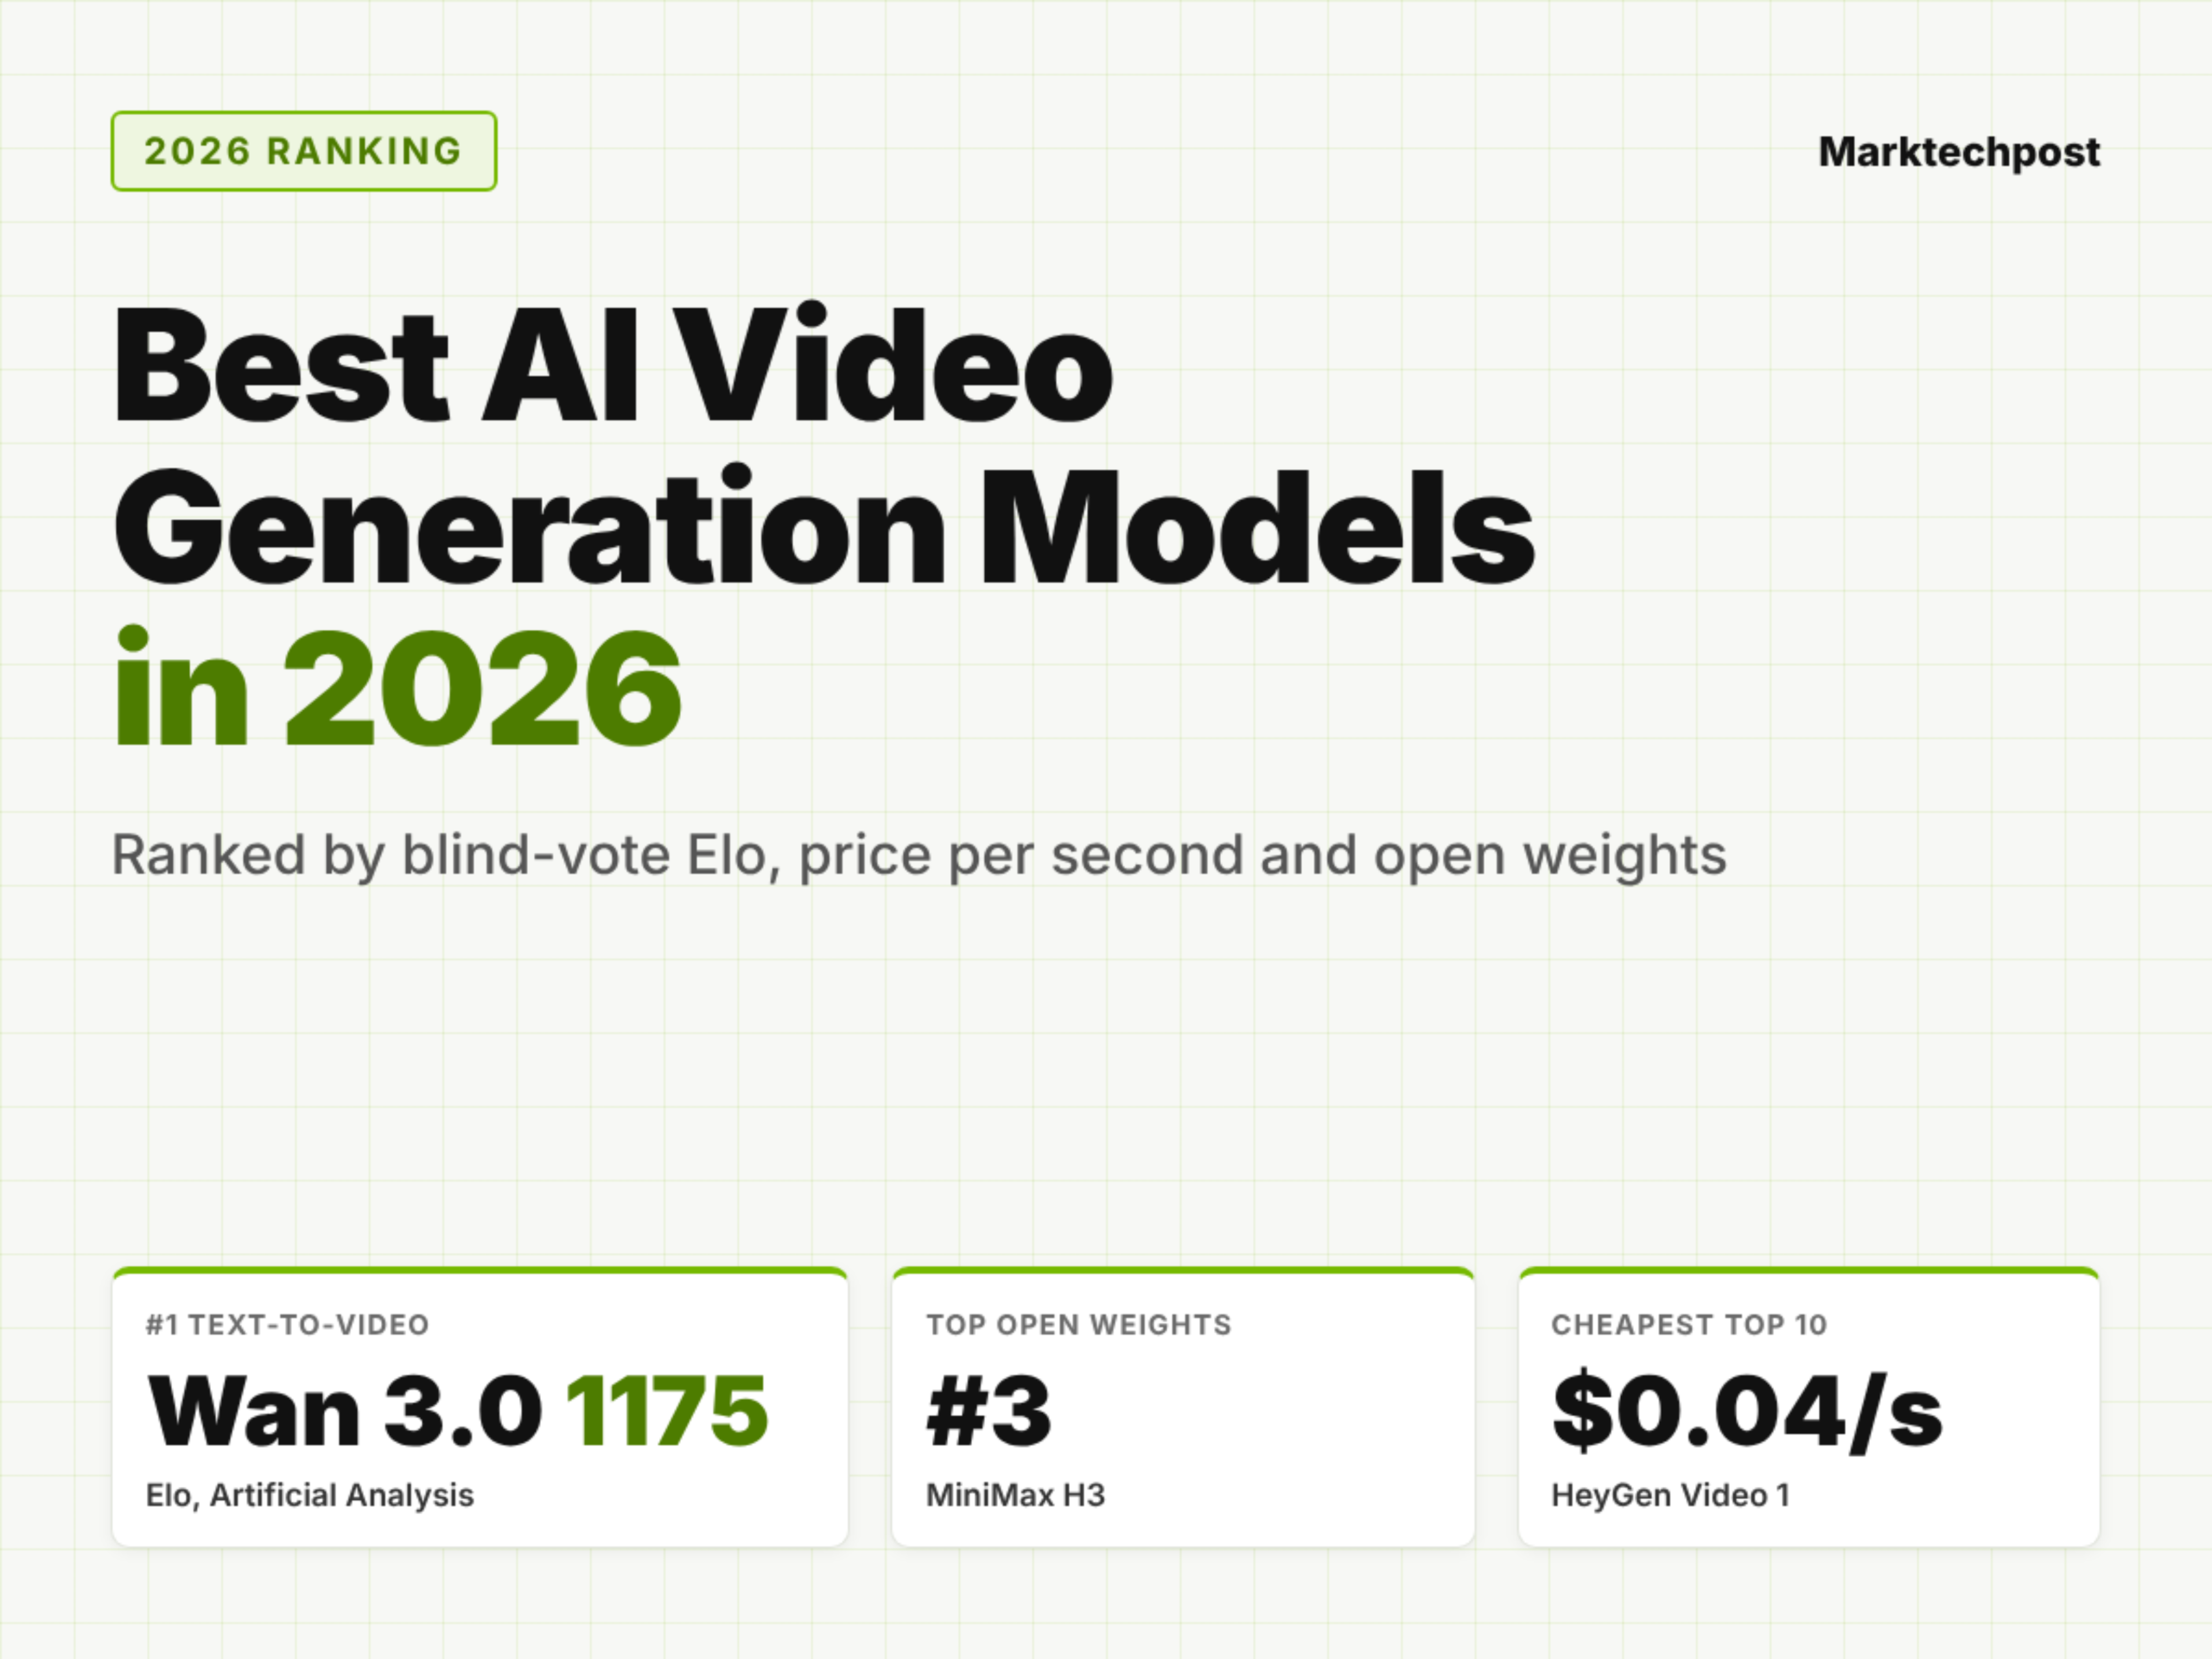
Best AI Video Generation Models in 2026: Elo, Price per Second, Open Weights

The AI video leaderboard looks very different from 12 months ago. Native audio is now table stakes. Clips run 15–30 seconds. And an open-weights model sits in the top 3. This ranking (as of Nov 13, 2026) uses one quality signal: blind human-preference Elo from the Artificial Analysis Video Arena. We pair it with API

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

Perplexity Releases Decider v1.3: Open-Weight Decision Models Add Locate

Perplexity Decider v1.3 and Flash v1.3 are open-weight decision models that return probabilities, not text. Version 1.3 adds Locate for span extraction and reports 91.6% mean accuracy on 63 query-classification tasks.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

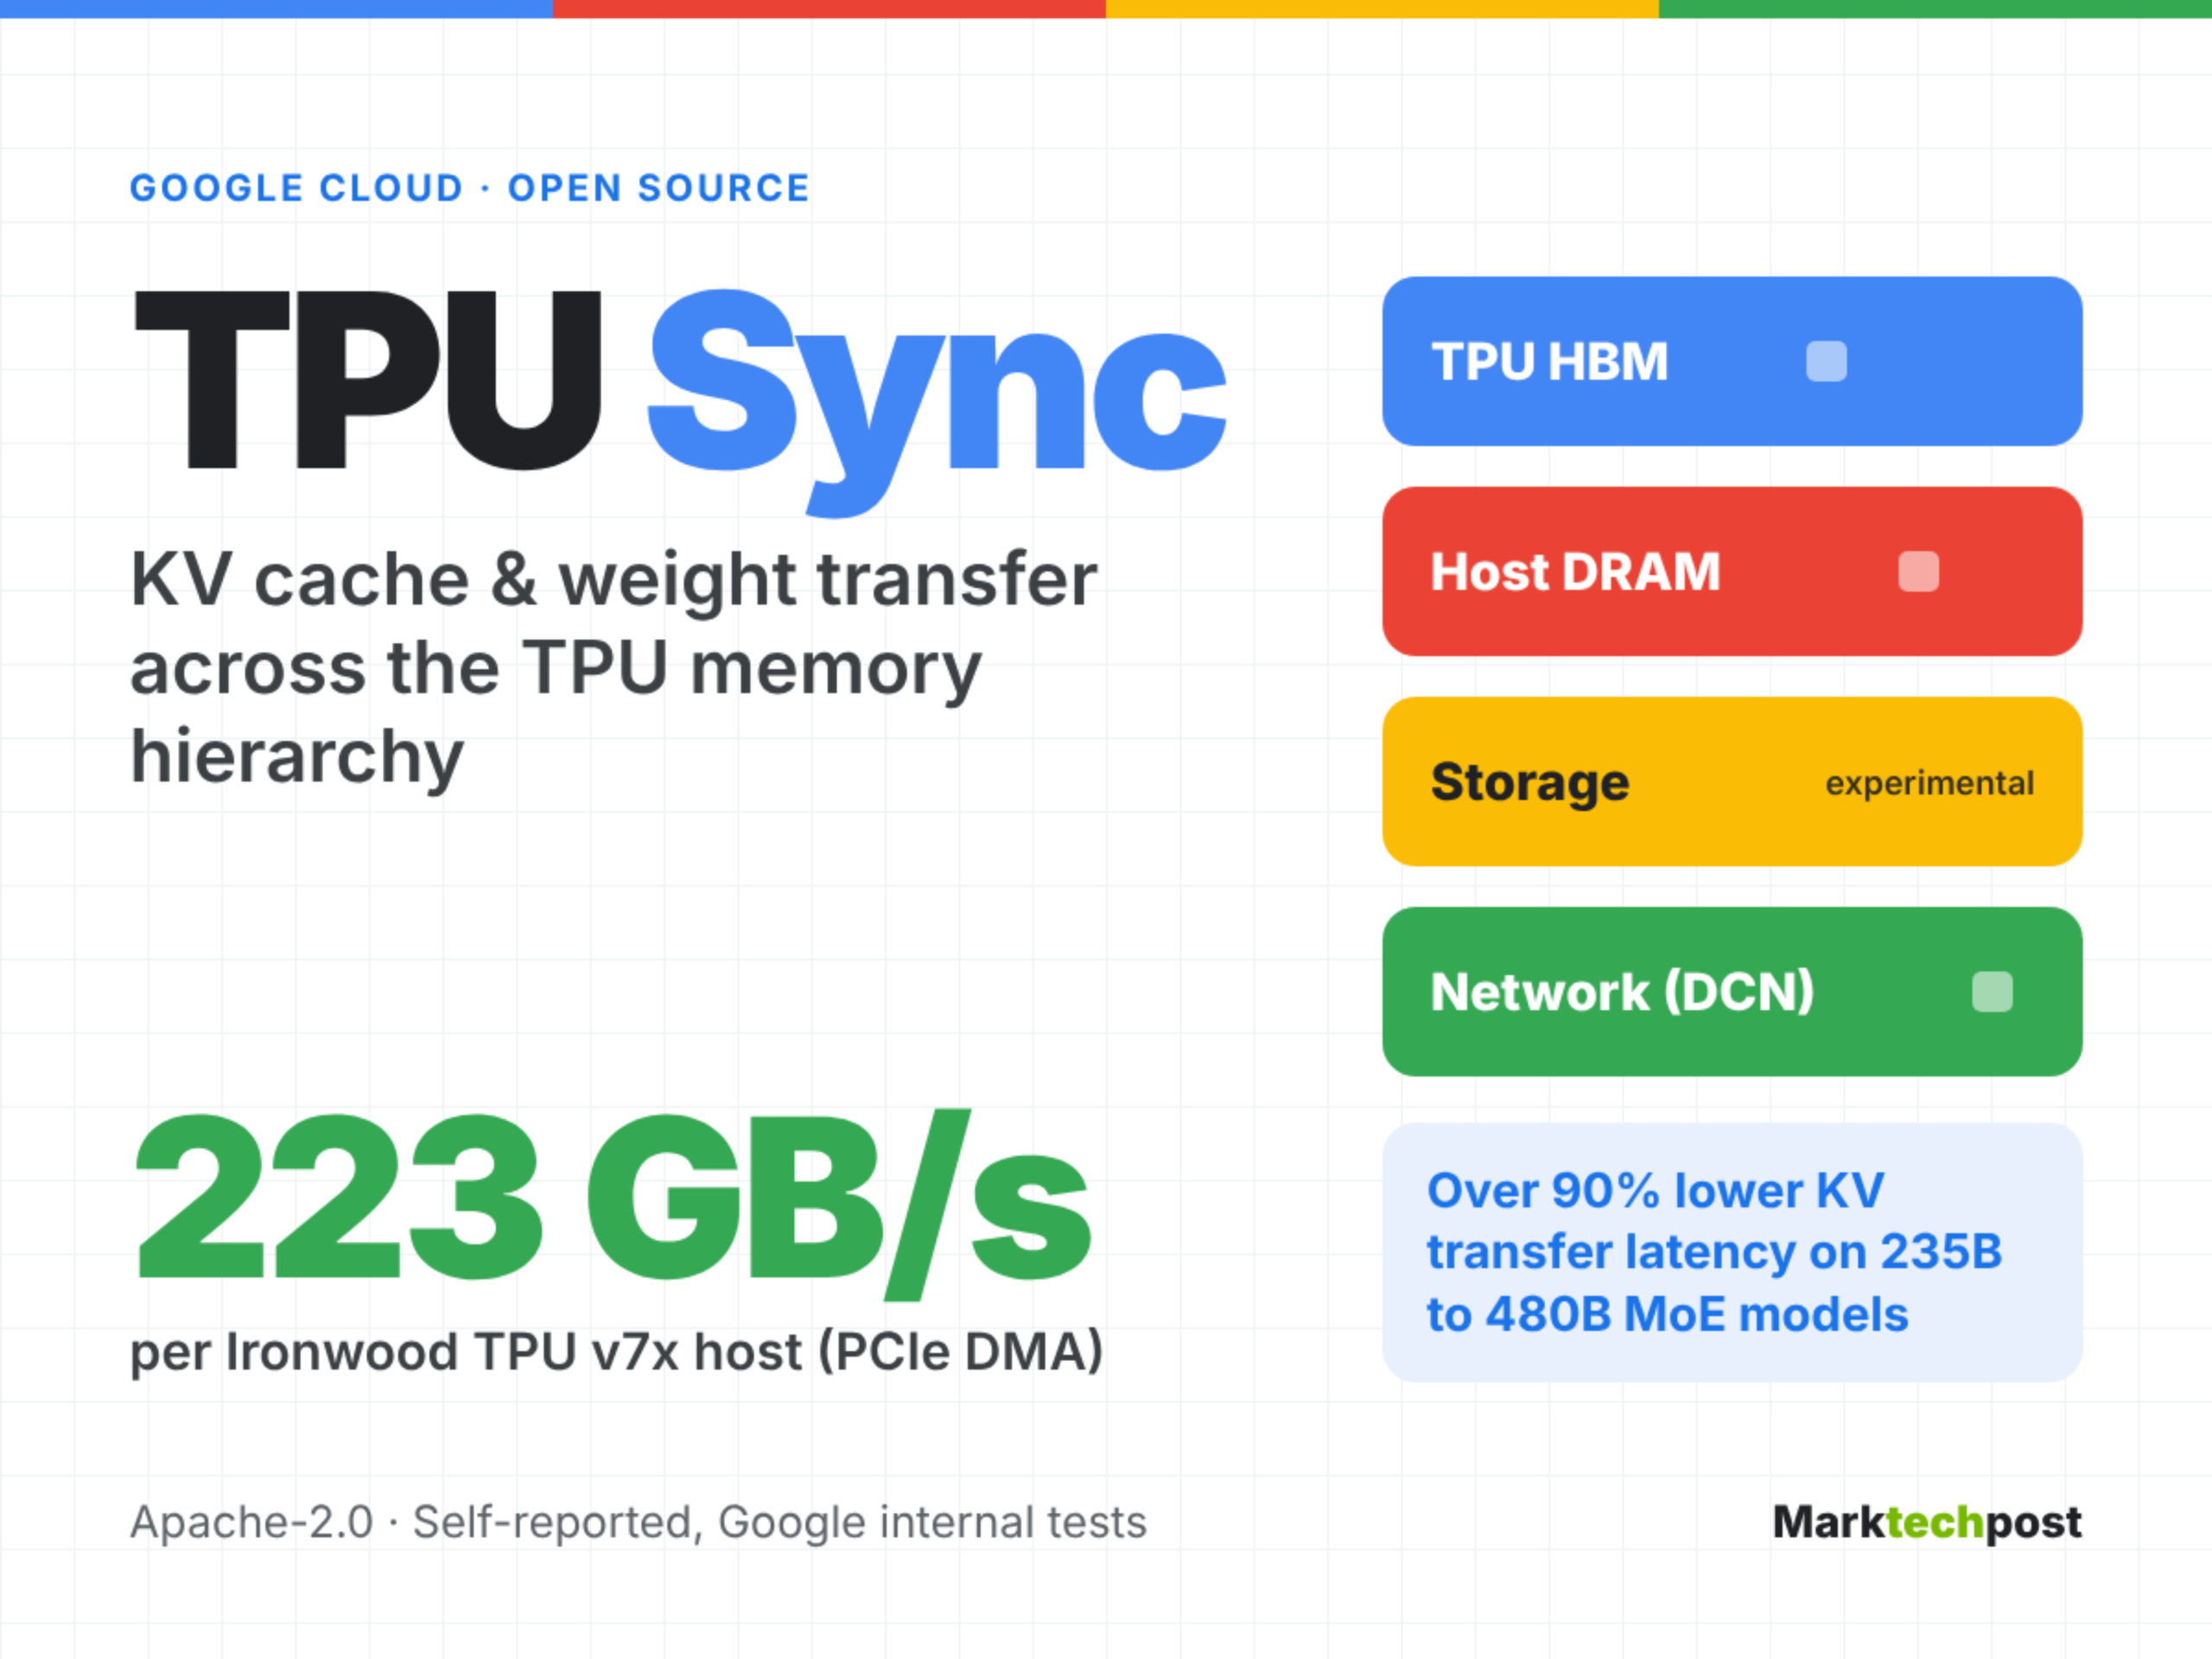
Google Releases TPU Sync: Open-Source KV Cache Transfer for TPUs

Google released TPU Sync, an open-source C++ library that moves KV caches and weights across TPU HBM, host DRAM, storage and network. Google reports over 90% lower KV transfer latency on 235B to 480B MoE models.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

Google Releases Gemini 4 Hydrogen: 2.5x Faster Than Gemini 3.8 Flash

Google released Gemini 4 Hydrogen, a fast agentic model with a 1M-token window, 4 thinking levels and $1.50/$7.50 pricing. Google reports a 51 Artificial Analysis score and 57% on Terminal-Bench 4.1.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

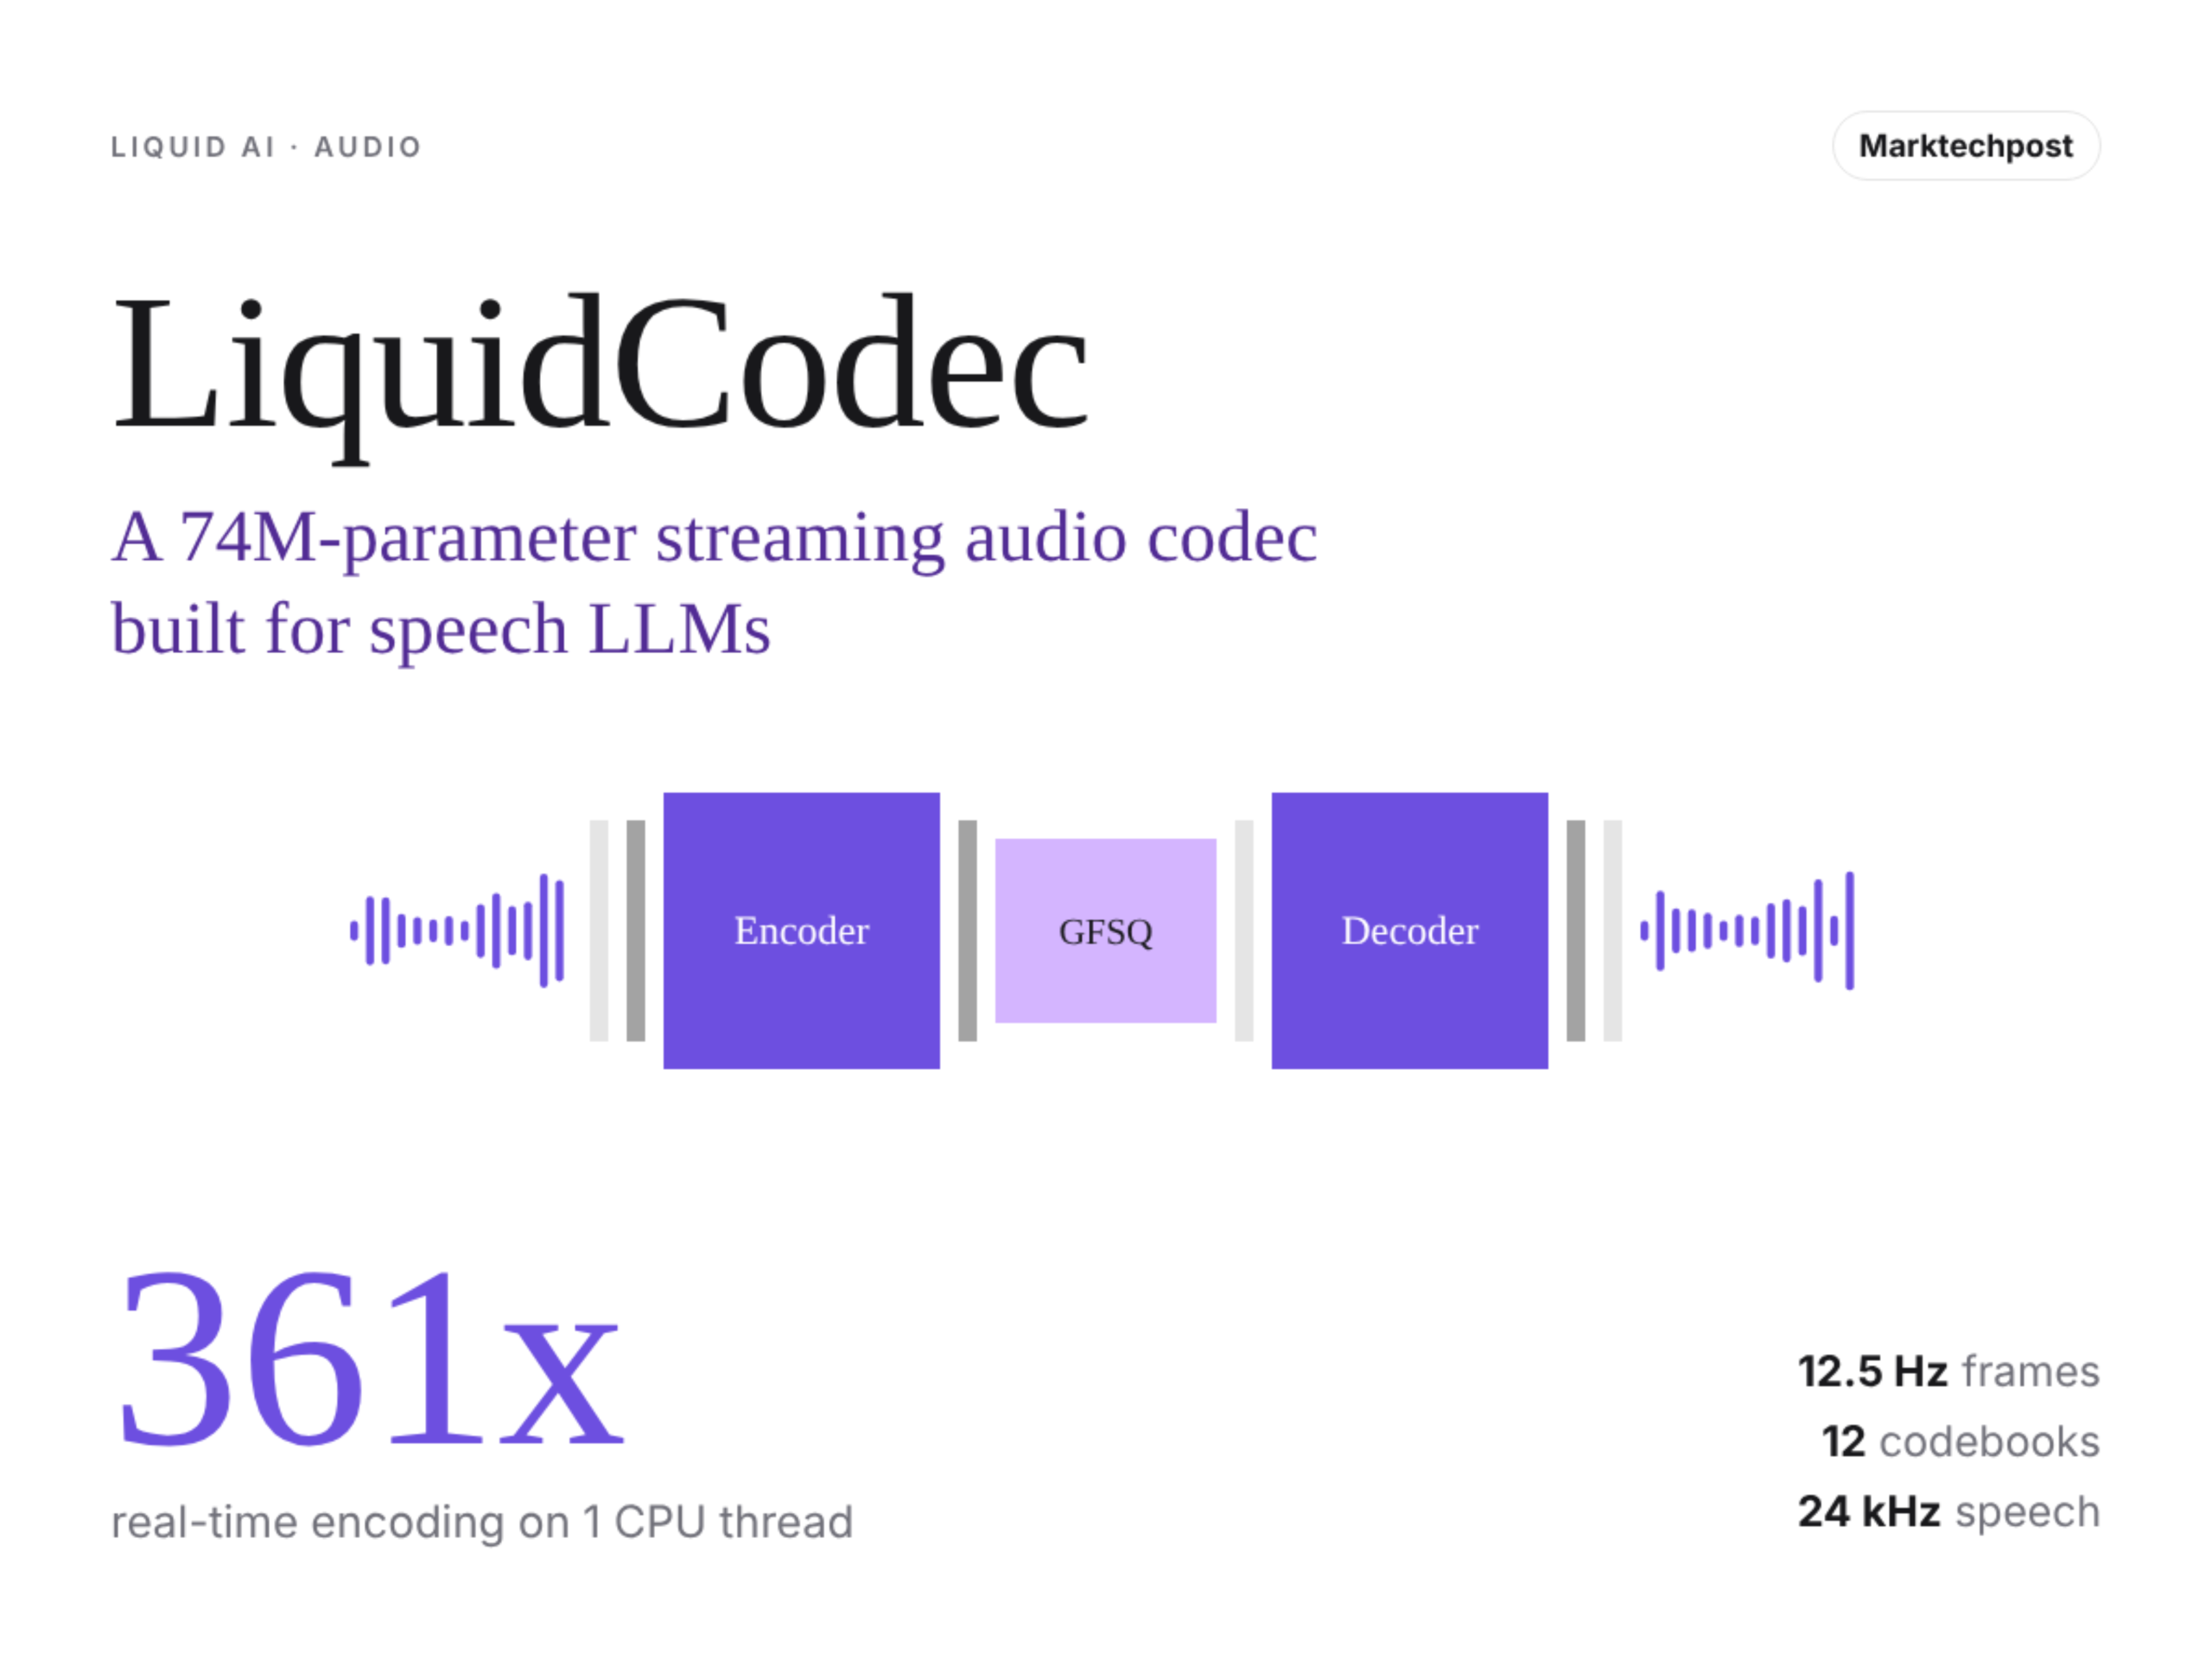
Liquid AI Releases LiquidCodec, a 74M-Parameter Streaming Audio Codec

Liquid AI released LiquidCodec, a ~74M-parameter streaming audio codec that powers LFM3-Audio-2B and LFM3-Omni-2B. It runs at 12.5 Hz with 12 codebooks and encodes about 361x faster than real time on a single CPU thread.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

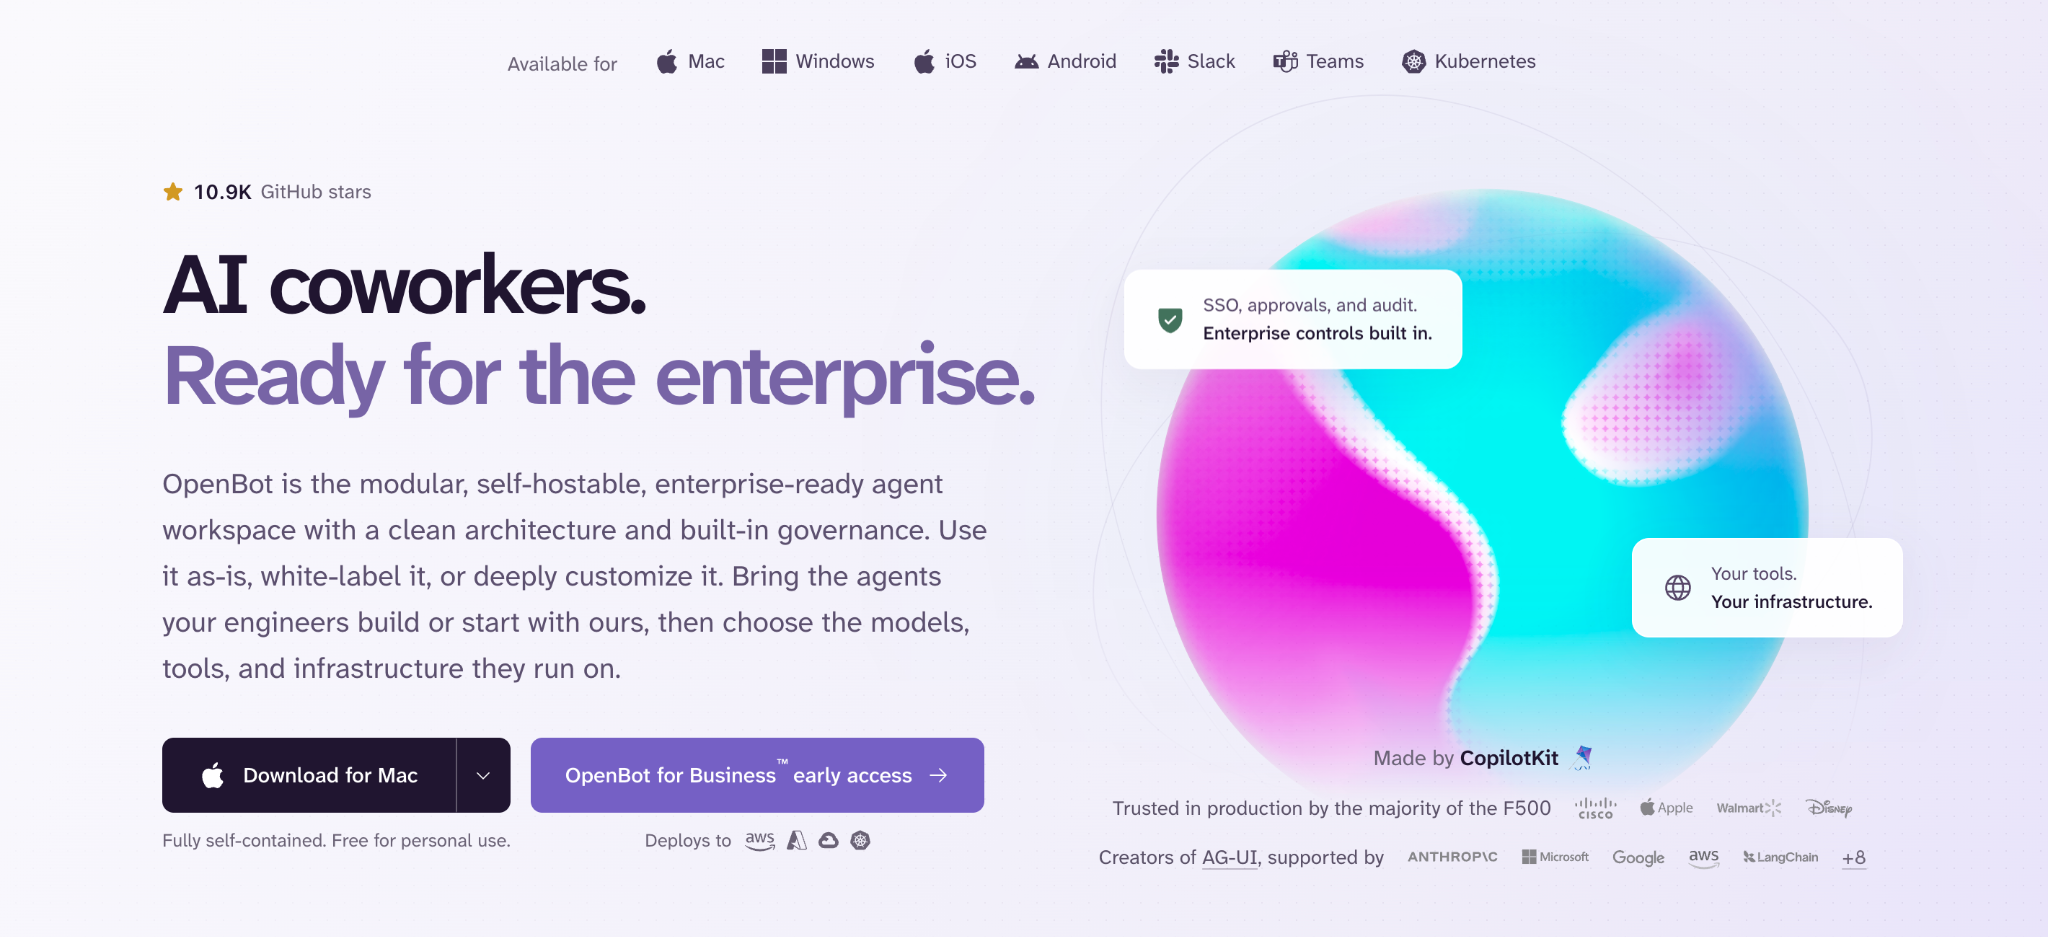
CopilotKit Releases OpenBot 1.0: An MIT-Licensed, Self-Hostable AI Coworker With Built-In Governance

CopilotKit released OpenBot 1.0, an MIT-licensed, self-hostable AI coworker workspace. Companies bring their own agents, models and infrastructure, while every Bot action passes a policy check and lands in an audit trail.

Read at MarkTechPost

MarkTechPost Asif Razzaq SI

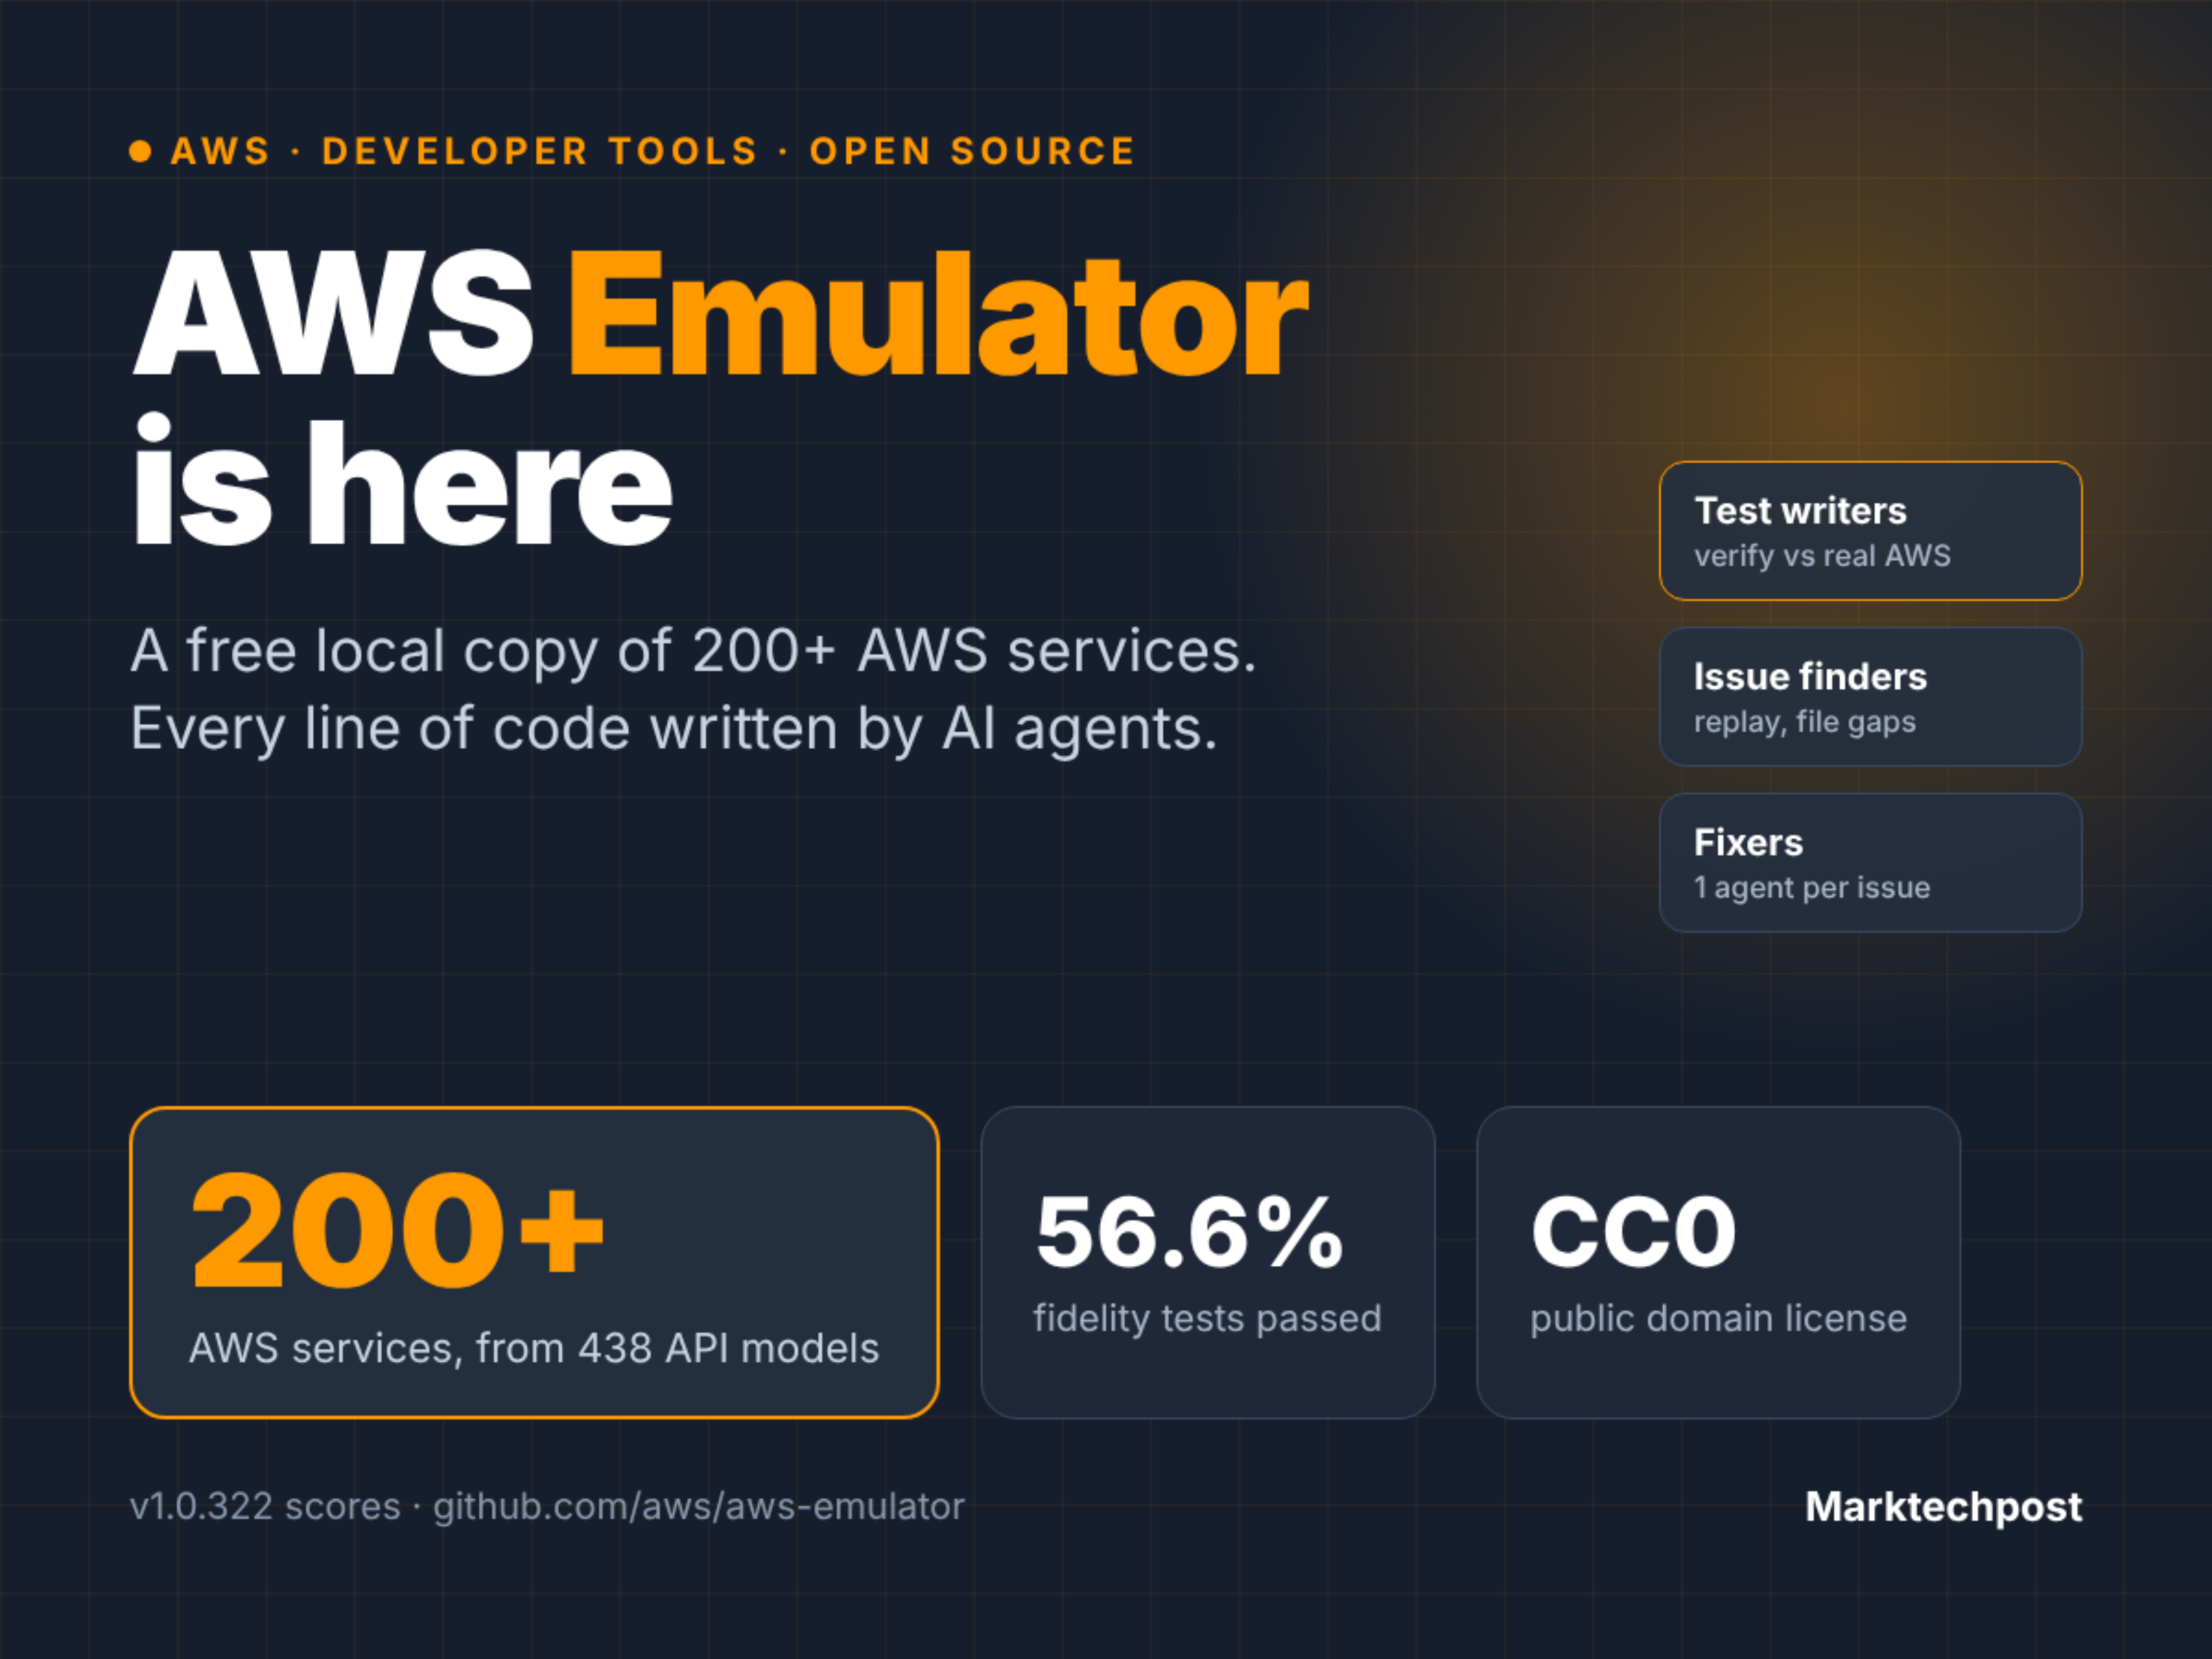
AWS Releases AWS Emulator: A Local Copy of 200+ AWS Services Built by AI Agents

AWS released AWS Emulator, a free, CC0-licensed local emulator of AWS APIs built from 438 API models. Autonomous agents wrote all of its code. It passes 56.6% of 42,857 published fidelity tests at launch.

Read at MarkTechPost

MarkTechPost Michal Sutter SI

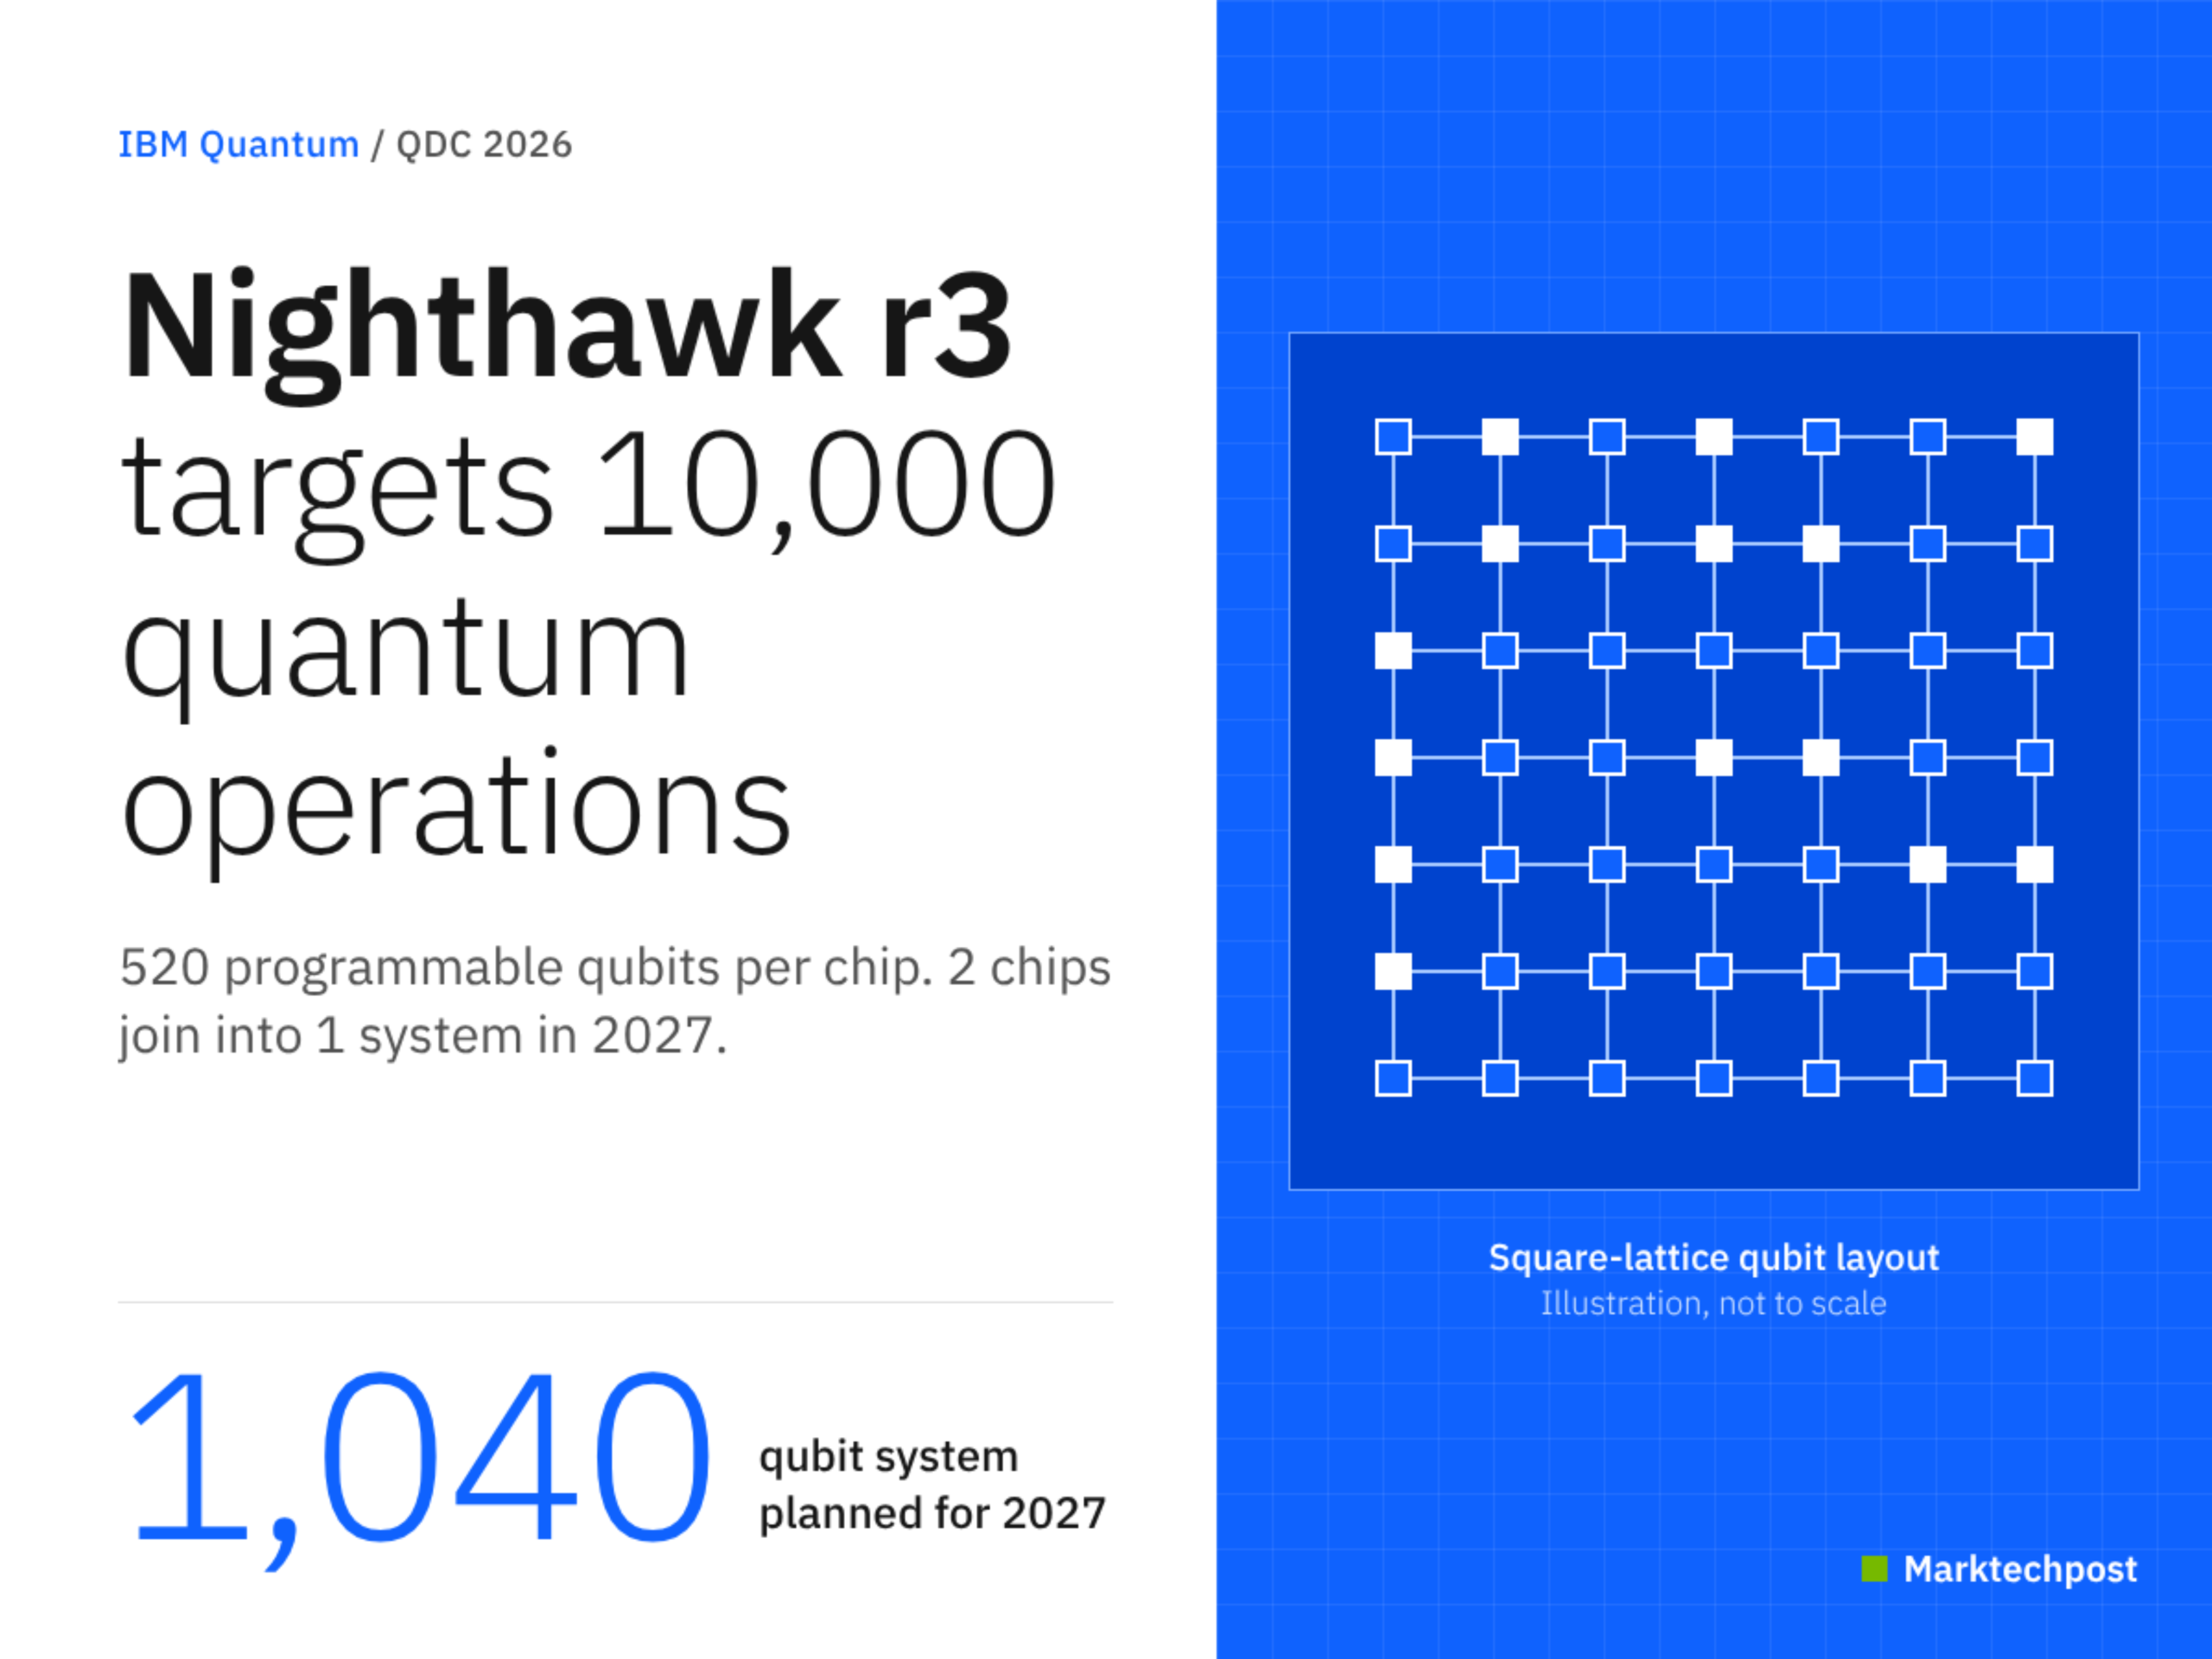
IBM Announces IBM Quantum Nighthawk r3: A New Processor to Support 10k Quantum Operations on 520 Programmable Qubits

IBM announced Quantum Nighthawk r3, a 520-qubit processor designed for 10,000 quantum operations. 2 r3 chips will link into a 1,040-qubit system in 2027, while Nighthawk r2 already posts up to 19x speedups over Heron.

Read at MarkTechPost

Older stories