Results for “model”

arXiv (research papers) Souhaila Djaffal SI

Evaluating LLM-Generated World Models for Neuro-Symbolic Reasoning

Formal world models can support planning, verification, and safety reasoning, but constructing them from open-ended natural-language situations is difficult, particularly in multi-agent settings where several formalizations may be plausible. We study whether five LLMs can generate such world models as partially observable stochastic games and whether mechanical validity is sufficient to establish that the resulting model faithfully represents the intended decision problem…

Read at arXiv (research papers)

arXiv (research papers) Mohammed Nayeem Khan SI

Precision on Demand: Escalating Weight Bits at Uncertain Decoding Steps in a Small Local Model

Local decoding usually fixes one weight precision for the whole generation. We study a different allocation: store 8-bit weights, decode with their top 4 bits, and redo a step at 8 bits only when the low-precision output distribution looks uncertain (entropy above a threshold or a small top-two margin). Quantization is simulated, the model is Qwen3-0.6B, and the benchmark is GSM8K. Cost is counted in weight bytes read per token. On 36724 replayed steps the entropy of the low…

Read at arXiv (research papers)

arXiv (research papers) Mohammed Nayeem Khan SI

Bits or permutations? Spending a fixed inference budget on weight precision or on option-order averaging in small local language models

Local language models can save memory by storing weights in fewer bits, and they can reduce sensitivity to the order of answer options by averaging a few reorderings. We ask whether the first makes the second worse, and which is the cheaper way to spend a fixed budget. On Qwen3-0.6B and Qwen3-1.7B with simulated round-to-nearest weight quantization (8, 6, 4 and 3 bits, fp16 reference), read from the logits of the letters A to D on ARC-Easy, ARC-Challenge, MMLU and HellaSwag…

Read at arXiv (research papers)

arXiv (research papers) Josh Rountree SI

Causal Concept Explanations for Deep Neural Models

Concept-based explanations in neural models are important for the development, certification, and adoption of autonomous systems. Yet, interpretability remains correlational. Without methods to guide and quantify causal relationships between explanations, a concept explanation can be provided without being necessary or sufficient for the observed output thereby appearing correct while misleading. We introduce Causal Concept Wrapper Network (CCW-Net), the first use of…

Read at arXiv (research papers)

9to5Mac Ryan Christoffel Gadgets

New Apple TV 4K remote’s best feature requires a newer iPhone model

A new Apple TV 4K releases this Friday (pre-order here), with an upgraded Siri Remote. But the new remote’s best feature might not work on your iPhone.

Read at 9to5Mac

arXiv (research papers) Amir Mann SI

Blurring the Block Boundaries: Overlapping Block Denoising for Efficient Diffusion Language Models

Diffusion Language Models (DLMs) have emerged as effective alternatives to autoregressive models for latency-critical tasks, enabling faster token generation. Recent advances employ block diffusion with self-editing capabilities, where each block refines tokens iteratively before advancing to the next one. Yet each block is only as fast as its slowest token, and the next block cannot start before it. We suggest Blurring the Block Boundaries (B3), a novel method with which…

Read at arXiv (research papers)

arXiv (research papers) Bo Dai SI

An Energy-Based Perspective on Machine Learning

Energy-based models (EBMs) define a distribution through a scalar energy, $p_θ(x)\propto\exp(-E_θ(x))$, and are usually presented as one model family among many. This tutorial has a broader goal: beyond introducing EBMs, it uses them as a single lens that connects the different aspects of machine learning. Any EBM is specified by three choices, the energy, which determines what the model represents; the inference procedure, which samples from or optimizes the energy; and the…

Read at arXiv (research papers)

arXiv (research papers) Dong Han SI

Cognitive Mapping of Learning by Thinking Mechanisms in Large Language Models

Large language models (LLMs) increasingly exhibit capabilities that resemble human Learning by Thinking (LbT), the acquisition of new insight through internal processes such as explanation and reasoning, without new external input. A systematic account of the cognitive mechanisms behind these capabilities, and of their limits, remains underdeveloped. This paper proposes a Cognitive LbT Framework that maps four mechanisms (Reflective Reasoning, Synthetic Memory Formation…

Read at arXiv (research papers)

arXiv (research papers) David Dörner

Gaussian Process-Augmented Model Predictive Contouring Control for 6-DoF Trajectory Tracking with a Holonomic AUV

Small, holonomic Autonomous Underwater Vehicles (AUVs) enable close-range inspection of underwater structures from arbitrary viewpoints, requiring accurate position and attitude tracking under state and input constraints. Model Predictive Contouring Control (MPCC) naturally handles these requirements, but relies on an accurate dynamics model, which is difficult to obtain underwater. In this paper, we present a nonlinear MPCC in all six Degrees of Freedom (DoF) for a…

Read at arXiv (research papers)

arXiv (research papers) Guoqiang Liang

From Video Frames to Robot Meta-Frames: A Unified Latent Interface for World Action Models

Pretrained video diffusion models (VDMs) offer a powerful foundation for World Action Models (WAMs), which jointly predict robot actions and future observations. Building such models requires injecting low-dimensional robot signals (e.g. proprioception, actions, and values) into a latent space shaped by natural videos, and a key design choice is the interface through which these signals enter: existing schemes treat it as a formatting detail, spending a separate latent frame…

Read at arXiv (research papers)

arXiv (research papers) Zhengxiang Huang SI

EngineAgent: Agentizing On-Device LLM Inference Engines with Inference Stack Hierarchy Awareness and Hardware Abilities

Rapidly evolving LLM architectures and heterogeneous mobile hardware make supporting new models in on-device inference engines a recurring and costly system challenge. Each model may require coordinated changes across conversion, graph construction, operators, and hardware backends. Existing coding agents often miss these cross-layer dependencies and struggle to diagnose failures across host--device execution paths. We present EngineAgent, an agentic system for automating…

Read at arXiv (research papers)

arXiv (research papers) S M Rayeed SI

CLADE: Category-Level Answering from Deficient Evidence in Retrieval-Augmented Language Models

Retrieval-augmented systems often retrieve passages that are accurate and relevant but state the answer at a coarser level of granularity than the question requires. For example, a question may ask which specific disease a drug treats (familial hyperlipidemia), while the retrieved passage mentions the broader disease family (hyperlipidemia). Prior work on context sufficiency treats such coarse passages simply as insufficient. We argue that they form a distinct case, which we…

Read at arXiv (research papers)

MacRumors Hartley Charlton Gadgets

iPad Mini 2021 vs. 2026 Buyer's Guide: Is It Worth Upgrading?

Apple's eighth-generation iPad mini went on sale earlier this month with a larger OLED display, a thinner and lighter design, the A20 Pro chip, and water and dust resistance. If you still use the sixth-generation ‌iPad mini‌ from 2021, the upgrade also brings changes that debuted on the 2024 model, including Apple Intelligence, Apple Pencil Pro support, and twice the USB-C transfer speed. The new ‌iPad mini‌ starts at $699 for 128GB with Wi-Fi or $849…

Read at MacRumors

The Decoder Maximilian Schreiner SI

Google DeepMind's Gemini Robotics 2.5 scores 96 percent sorting metal parts in a Mercedes-Benz assembly pilot

Google Deepmind introduced Gemini Robotics 2.5, a new control model for robots, and tested it with Apptronik on active Mercedes-Benz production lines in Hungary and Germany. The humanoid robot Apollo 2 sorted metal parts there with a reported success rate of 96 percent. The article Google DeepMind's Gemini Robotics 2.5 scores 96 percent sorting metal parts in a Mercedes-Benz assembly pilot appeared first on The Decoder.

Read at The Decoder

arXiv (research papers) S. Hughes

Dynamical Casimir emission from Floquet-driven Landau polaritons: Gauge invariance forbids a superradiant phase transition

Ultrastrong light--matter coupling of linear systems, such as Landau polaritons formed by a two-dimensional electron gas in a terahertz cavity, is described by the bosonic Hopfield model, and gauge invariance forbids a superradiant phase transition (SRPT). Modulating the magnetic field alone has been predicted to enhance the cycle-averaged coupling and induce a Floquet SRPT. We develop an exact theory of periodically driven Landau polaritons. Including the electric field…

Read at arXiv (research papers)

GEN (Genetic Engineering & Biotechnology News) Corinna Singleman, PhD

Hybrid Model Captures Lactate Run-Away and Back-Metabolism

A hybrid model provides hard-to-achieve insights into lactate performance during bioprocessing, creating conditions for more accurate predictions to better manage key batch parameters and variability.

Read at GEN (Genetic Engineering & Biotechnology News)

AWS Machine Learning Blog Steph Gooch SI

Amazon Bedrock tokenomics data lake

Running Amazon Bedrock across many accounts shows you the bill but not what happened inside each call. This post builds a centralized observability data lake that aggregates Bedrock invocation logs from every linked account into one queryable table, so you can see prompts, token counts, model choice, and per-invocation cost across your organization.

Read at AWS Machine Learning Blog

arXiv (research papers) Zihan Chen SI

AI Isn't Getting Dumber, We're Getting Pickier: Rising Standards in Human Evaluation of Large Language Models

Users often complain that AI assistants such as ChatGPT are getting worse. Some versions do change, but human evaluation leaves a second possibility untested: the people judging may change. We separate the two on Chatbot Arena, a public platform where people compare answers from two anonymous large language models (LLMs) and pick the better one or say both are bad. We study 1,260,967 blind votes cast from May 2023 to August 2024 on pairs of models whose versions are fixed…

Read at arXiv (research papers)

arXiv (research papers) Gioele Cerati Space

An Archival Search for Outer Solar System Objects in the NOIRLab Source Catalog DR2: 65 Candidates, Including Four L4 Neptune Trojans

I search the single-epoch detections of the NOIRLab Source Catalog DR2 (DECam, 2012-2019) for outer Solar System objects. Single-night detections are linked with a bound orbit model, vetted against artefacts, static sources and known objects, and confirmed by forced measurements on at least two new archival nights. The linker recovers 96% of known objects present on four nights in one sky tile, but end-to-end recall is about 7%, limited by cadence, tiling and catalogue…

Read at arXiv (research papers)

arXiv (research papers) Yuming Bao

A New Computational Model for the Spin-Free Sum-of-Squares Energy Bounds of Electronic Hamiltonian

Optimizing spin-free sum-of-squares (SOS) energy bounds for electronic Hamiltonians leads to semidefinite programs whose expanded size grows rapidly with the orbital dimension. We derive an exact reformulation of an established spin-free SOS model as a convex quadratic problem over a single symmetric matrix constrained between zero and the identity. Explicit recovery maps connect feasible quadratic-program iterates to certificates in the original SOS formulation, and…

Read at arXiv (research papers)

arXiv (research papers) Jinyuan Zhang SI

Multimodal Abstention That Preserves Acquired Correct Answers

Adding abstention to a task-adapted multimodal model can discard correct answers, including capabilities acquired during adaptation. We formulate abstention repair as maximizing correct abstention on unanswerable questions under a budget on newly lost correct answers. We propose ReFrain (Regression-Free Abstention), which combines a linear probe on first-token logits, threshold calibration on held-out image clusters, and a deterministic veto that replaces rejected outputs…

Read at arXiv (research papers)

Digital Trends DT Staff

iVANKY’s Black Friday Sale Targets Mac Users Who Need More Connectivity

iVANKY's Black Friday sale brings discounts on three FusionDock models, giving Mac users more options for expanding their desktop connectivity. Here's what each dock offers and how much you can save.

Read at Digital Trends

arXiv (research papers) Yuan Zhang Tech policy

Can AI be a 'Researcher Without Borders'? Auditing Bias in AI-Assisted Social Science Research about China and the US

Although large language models have demonstrated strong performance on algorithmic and mathematical tasks, their suitability as social science research assistants remains unclear, particularly because many social science questions lack agreed-upon, quantifiable benchmark answers. Evaluating this suitability is important since researchers and students increasingly rely on AI to generate research ideas. When questions concern the countries in which models were developed, bias…

Read at arXiv (research papers)

arXiv (research papers) Yu Dong SI

LM-SimBench: A Unified Framework, Dataset, and Benchmark for Large Language Model Training Simulation

Evaluating candidate parallelization strategies through distributed training runs makes strategy selection prohibitively expensive at scale. Performance simulation offers a lower cost alternative, yet controlled comparisons among existing simulators remain difficult because they differ in the training stages they model and the workloads on which they are evaluated. We introduce LM-SimBench, a unified framework, profiling dataset, and benchmark for evaluating LLM training…

Read at arXiv (research papers)

The New Stack Amanda Caswell

Google says Gemini 4 Carbon proved Signal’s encryption in weeks

Google released Gemini 4 Carbon to paying developers Tuesday, positioning its newest frontier model above Gemini 4 Argon for complex

Read at The New Stack

The Guardian China Robert Booth in Lisbon

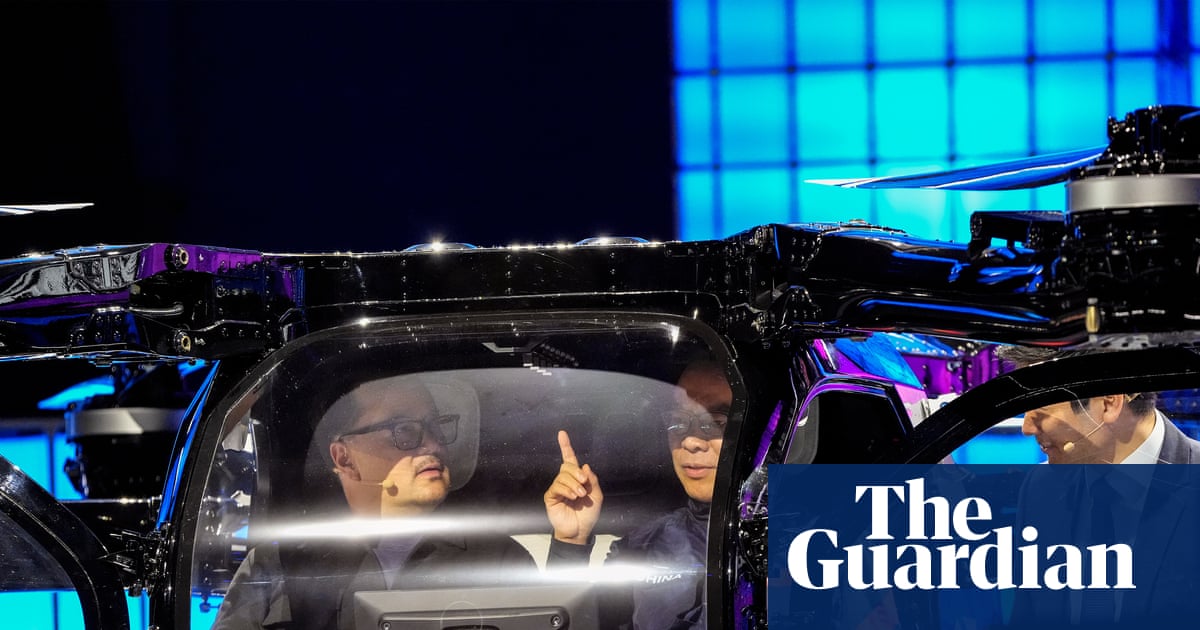
‘Flying cars’ could launch in China next summer, maker of two-seat model says

XPeng says its $300k low-altitude device will soon be ready for emergency services and recreational use in rural areas People could start taking trips in so-called flying cars in China as soon as next summer, the manufacturer of a two-seater vehicle with autopilot model has said. Deli Zhao, the chief executive of the Chinese flying car company XPeng, said the $300,000 (£225,000) low-altitude device would be ready for use by recreational users in rural locations and by…

Read at The Guardian China

arXiv (research papers) Haitian Li

Elastic-WAM: Adaptive Spatiotemporal Imagination for Efficient Robot Control

World-Action Models improve robot control by predicting future visual dynamics, but iterative video denoising incurs substantial inference overhead. Recent approaches reduce this cost through partial future denoising, yet typically rely on fixed refinement budgets. Our empirical observations reveal that preferred refinement depths vary across tasks and states, while different future regions exhibit varying relevance to action generation. Motivated by these findings, we…

Read at arXiv (research papers)

arXiv (research papers) Shuting Yang Security

Location Matters: Sparse Latent-Variance Attacks for Face Privacy against Diffusion Personalization

Text-to-image diffusion models can learn and reproduce an individual's identity from only a few reference photos, creating risks of unauthorized and misleading content generation. Proactive defenses address this risk by adding adversarial perturbations to facial images before release, thereby disrupting identity acquisition during downstream personalization. However, existing methods typically rely on dense $L_\infty$-bounded perturbations, whose accumulated distortions can…

Read at arXiv (research papers)

Google (The Keyword)

Gemini 4 Carbon is now available for developers.

Starting today, developers can build with Gemini 4 Carbon, our strongest model with frontier performance in cybersecurity and long-horizon capabilities. Built for sustai…

Read at Google (The Keyword)

9to5Google Abner Li SI

Gemini 4 Carbon rolling out to Gemini app for AI Ultra, Argon remains

Following the preview at the end of last month, Google is now bringing its latest Gemini 4 Carbon model to the Gemini app.

Read at 9to5Google

Older stories