AWS Machine Learning Blog

Recent stories from AWS Machine Learning Blog.

AWS Machine Learning Blog Aryaman Kothari SI

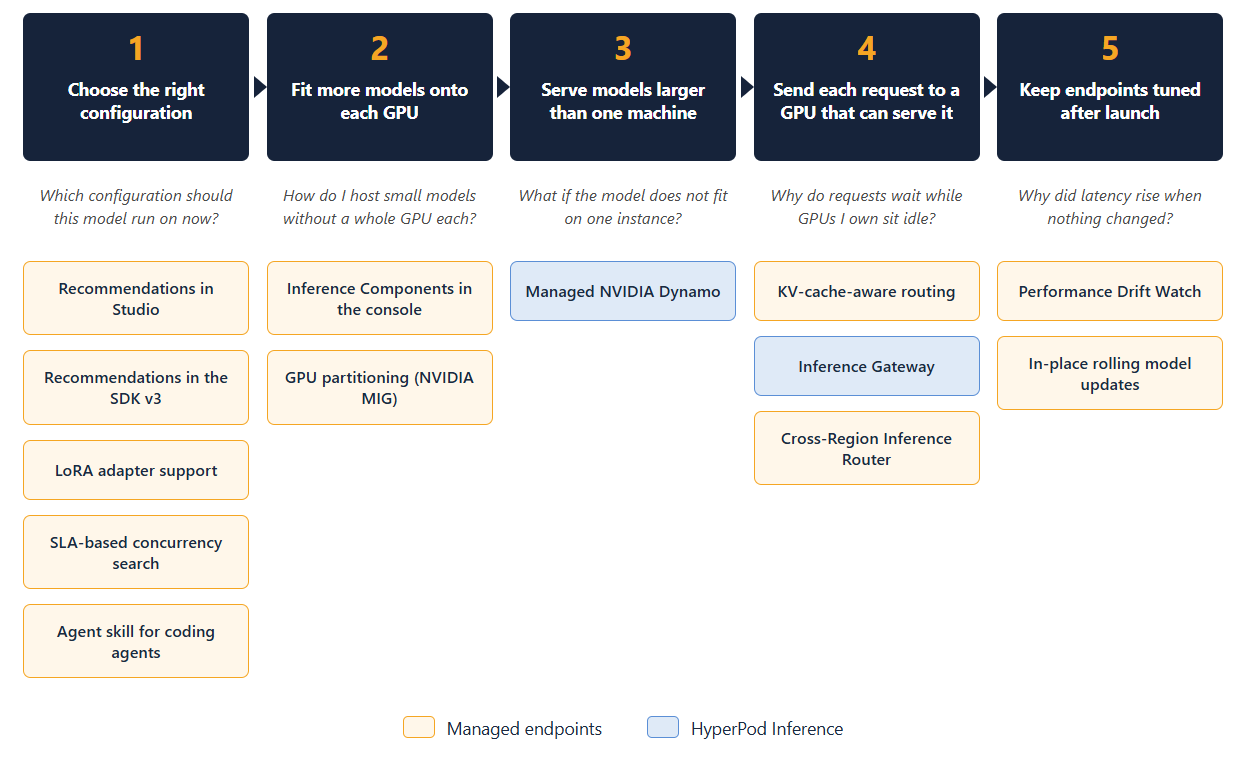
Amazon SageMaker Inference: 2026 launches in review, part 2

This second installment reviews 13 more Amazon SageMaker AI inference launches from 2026, spanning configuration recommendations, fitting more models onto each GPU, serving models too large for one instance, cross-Region routing, and post-launch tuning, bringing the year's total to 26.
Read at AWS Machine Learning Blog

AWS Machine Learning Blog Alex Thewsey SI

Use Kimi Code CLI with models on Amazon Bedrock

Kimi Code CLI v2.7.0 adds a native Amazon Bedrock provider, so you can connect the open source coding agent to models like Kimi K3.1 Pro using your standard AWS credential chain (named profiles or SSO) instead of a separate API key. This post shows how to configure the provider and send your first request.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Madhu Samhitha Vangara SI

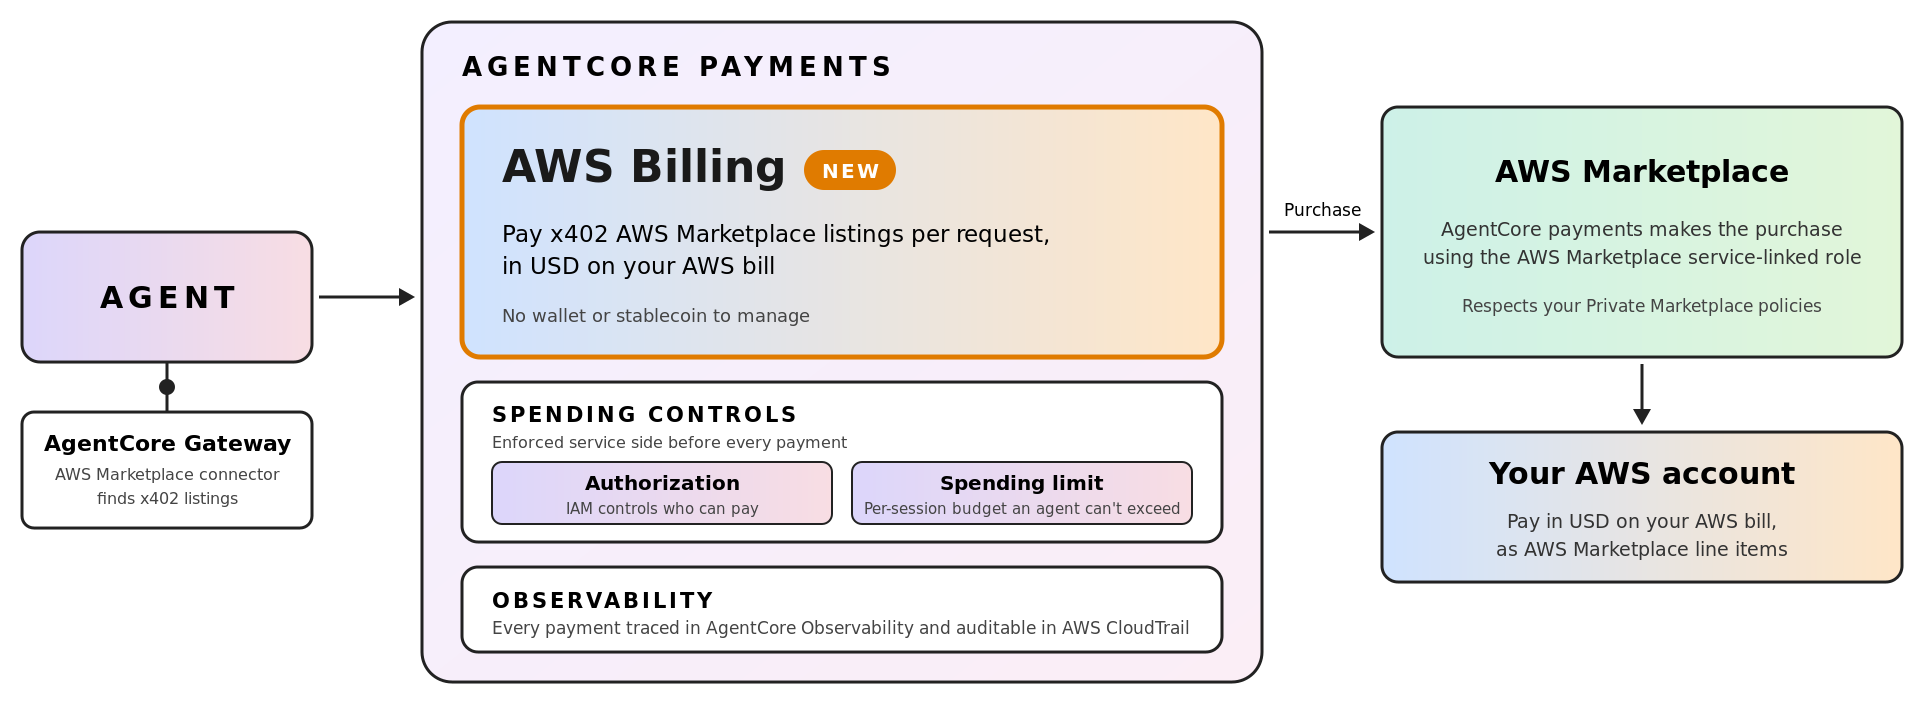
Enable AI agents to pay for AWS Marketplace x402 products with Amazon Bedrock AgentCore payments

Amazon Bedrock AgentCore payments now supports AWS Marketplace, so agents can discover and buy x402-enabled products, APIs, data, and content and pay in USD on the developer's AWS bill, with no stablecoin wallets or API keys. This post walks through a research agent that finds a tool, pays per request through AWS Billing, and answers with sources.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Dr. Jens Kohl SI

How the BMW Group governs hundreds of agents across thousands of developers

When hundreds of agents serve thousands of developers, governance cannot be an afterthought. The BMW Group shares the practices and patterns its R&D teams use to build, govern, and operate AI agents at enterprise scale without sacrificing speed, quality, or compliance.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Josh Anderson SI

Run your whole selling business in AWS Quick

Most sellers do not need another AI product to learn. They need the tools and information they already use brought together, so they can see what is happening in their business and act on it.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Hazim Qudah SI

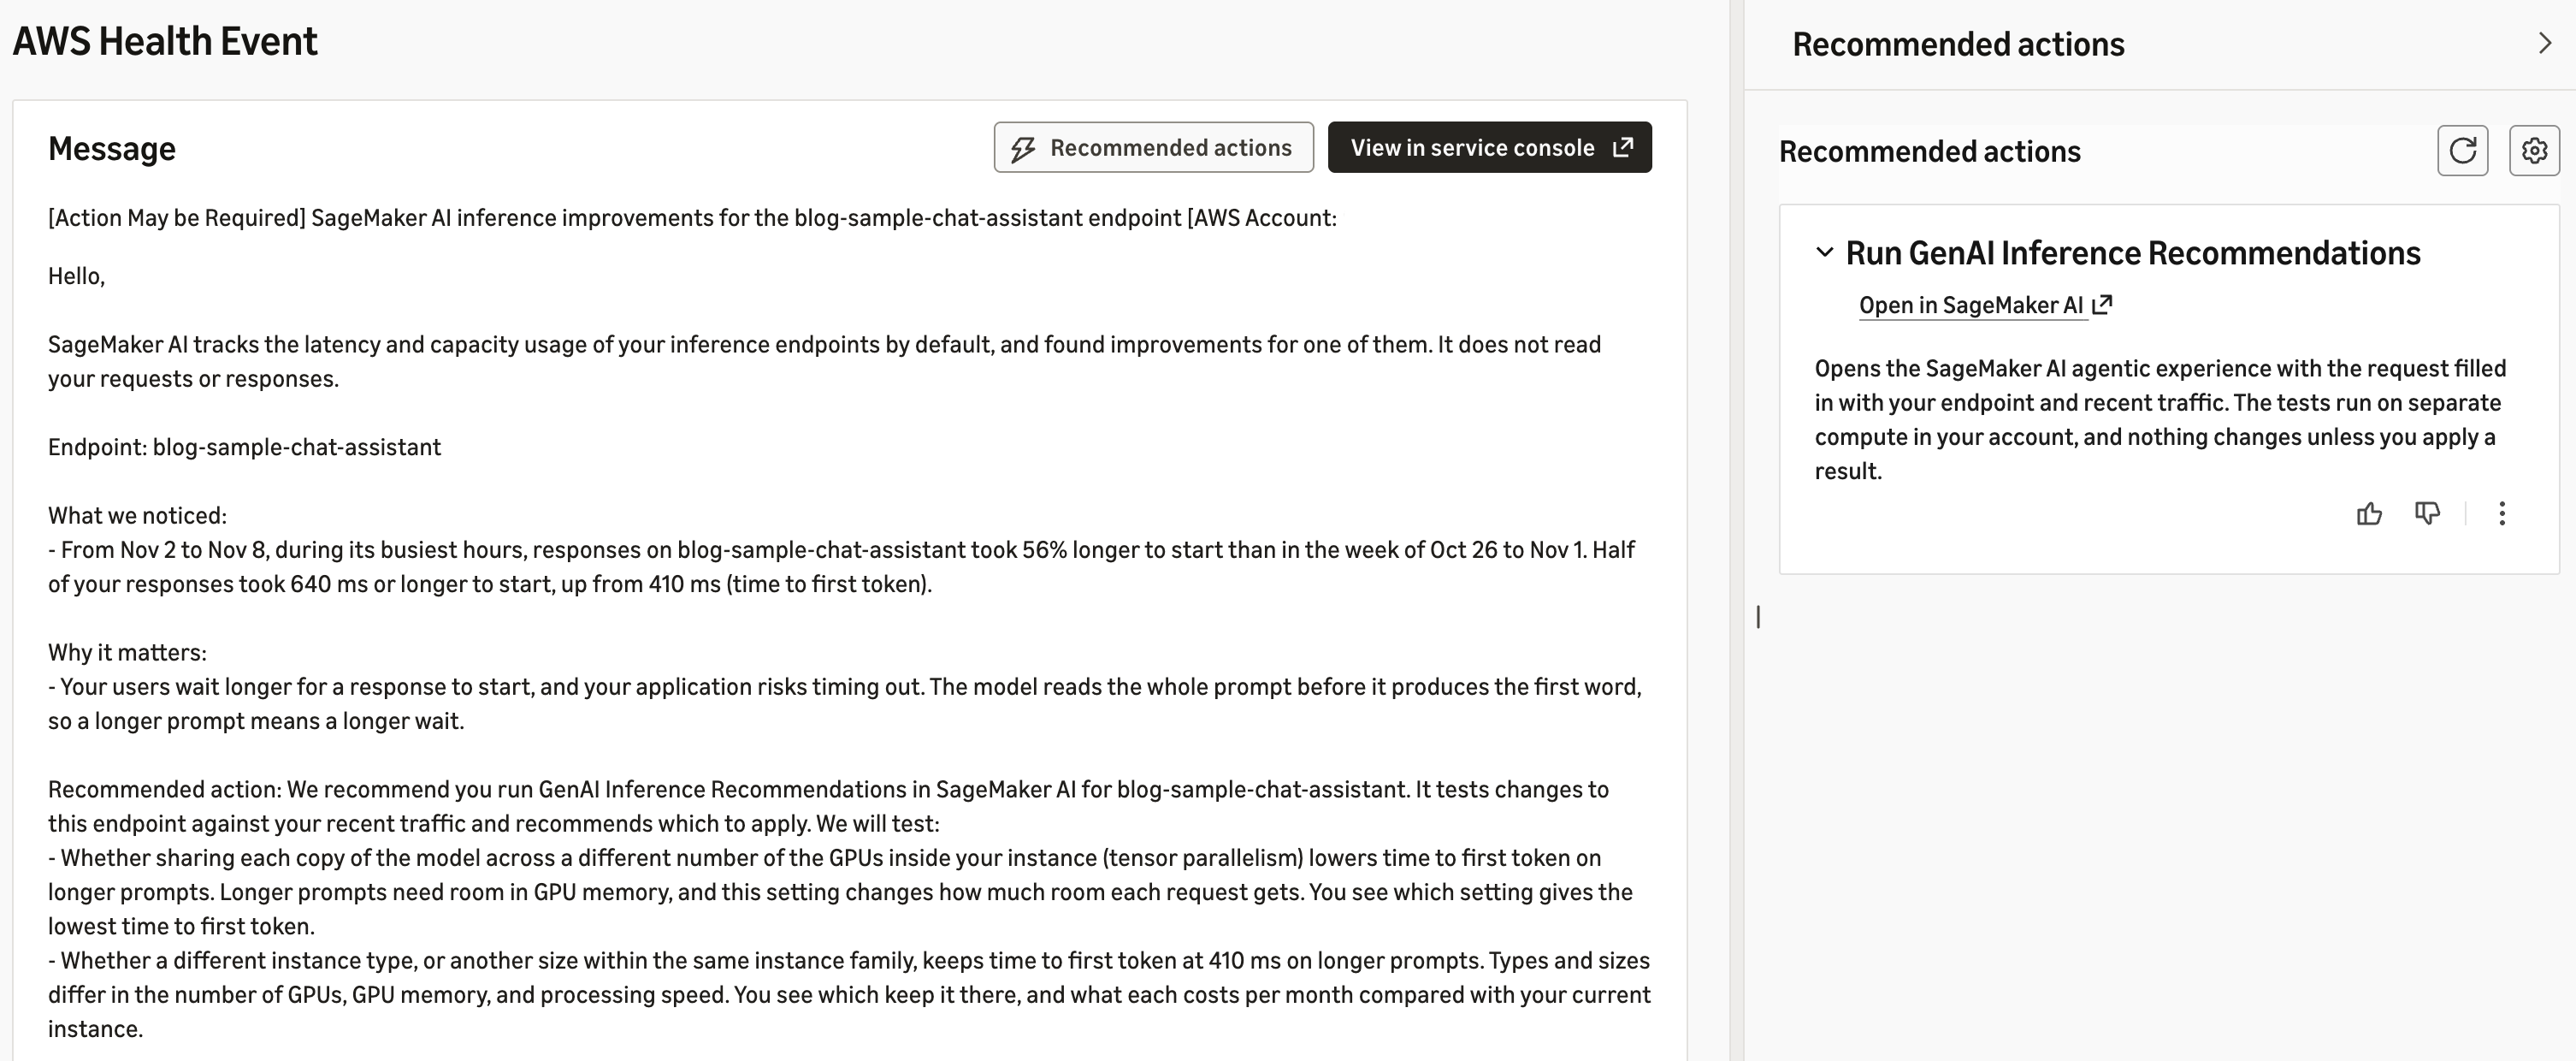
Amazon SageMaker AI now detects latency drift, idle GPUs, and missed optimizations on your inference endpoints

Amazon SageMaker AI now monitors your generative AI inference endpoints by default and tells you when a change could improve performance or lower cost. It tracks latency, GPU utilization, and serving configuration, then sends a finding through AWS Health with a one-click path to benchmark alternatives in SageMaker Studio before you apply any change.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Sunitha Srivatsa SI

Inside Amazon Connect Talent: The science of structured AI interviews

For organizations hiring hundreds or thousands of people, every interview presents the same challenge: How do you give candidates a consistent opportunity to demonstrate their skills while gathering the evidence needed to make informed hiring decisions? Structured behavioral interviews offer a research-backed approach to this challenge. They use consistent, job-related questions and clear scoring criteria

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Evandro Franco SI

Amazon Bedrock AgentCore harness adds Strands harness defaults, built-in tools, and lifecycle hooks

Amazon Bedrock AgentCore harness now runs on the open-source Strands harness, bringing a recommended model, task-oriented defaults, automatic prompt caching, proactive context management, and new built-in tools. It also adds lifecycle hooks so you can run deterministic allow or deny checks at defined points in the agent loop.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Suyin Wang SI

Amazon Polly launches voice cloning: A unique voice for your brand

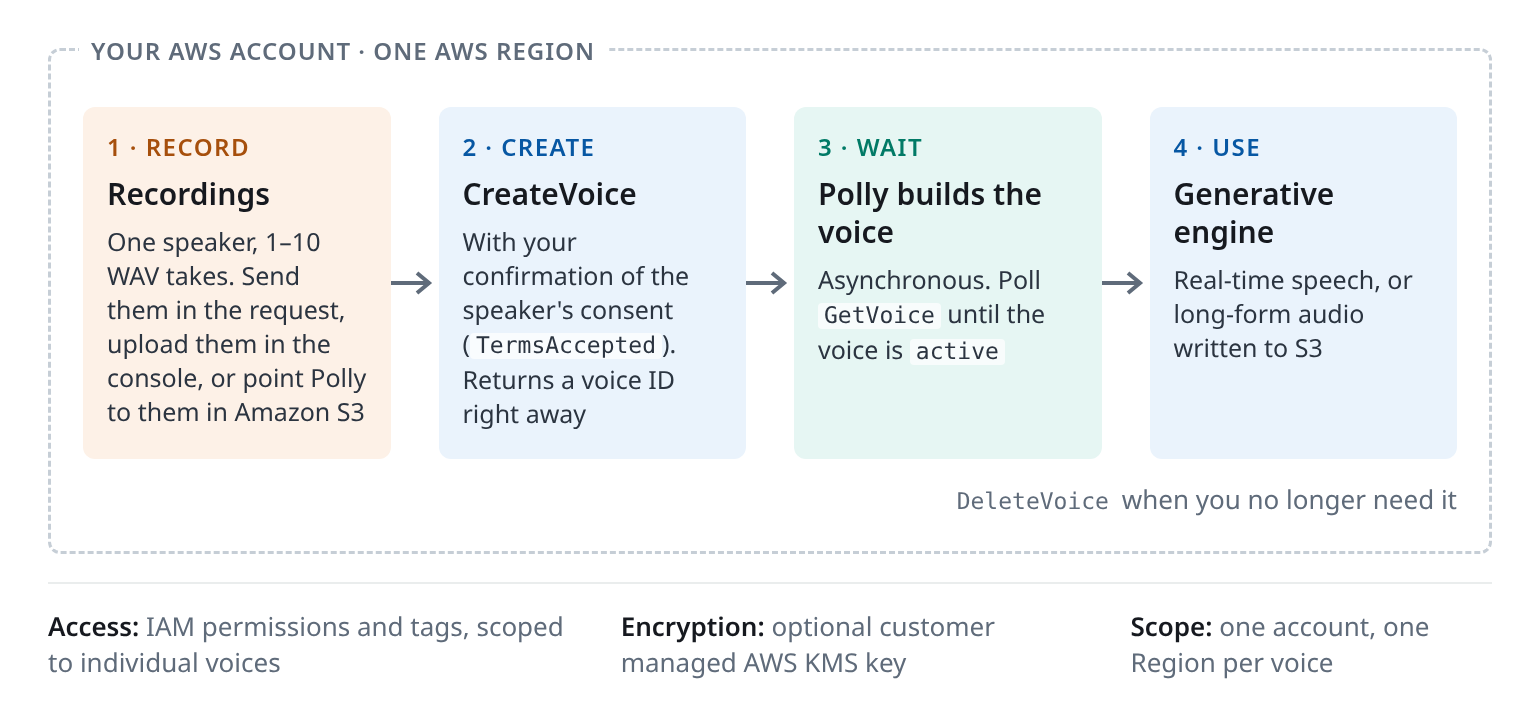
Voice cloning in Amazon Polly is now generally available. Give Amazon Polly a few minutes of recordings from a consenting speaker, and it builds a custom voice that reads new text in that speaker's voice. Cloned voices run on the Amazon Polly generative engine and support seven languages.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Ilan Geller SI

Optimize AI economics on Amazon Bedrock with Accenture’s sequenced approach

As enterprises scale AI on Amazon Bedrock, token spend can grow even as per-token prices fall. This post walks through six composable optimization levers, shows how Accenture applied them across four client engagements, and recommends a sequence for cutting AI token spend on your own workloads.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Rakesh Vangari SI

From learning to leaderboard: How Cisco upskilled 1,200 engineers in agentic AI with AWS AI League

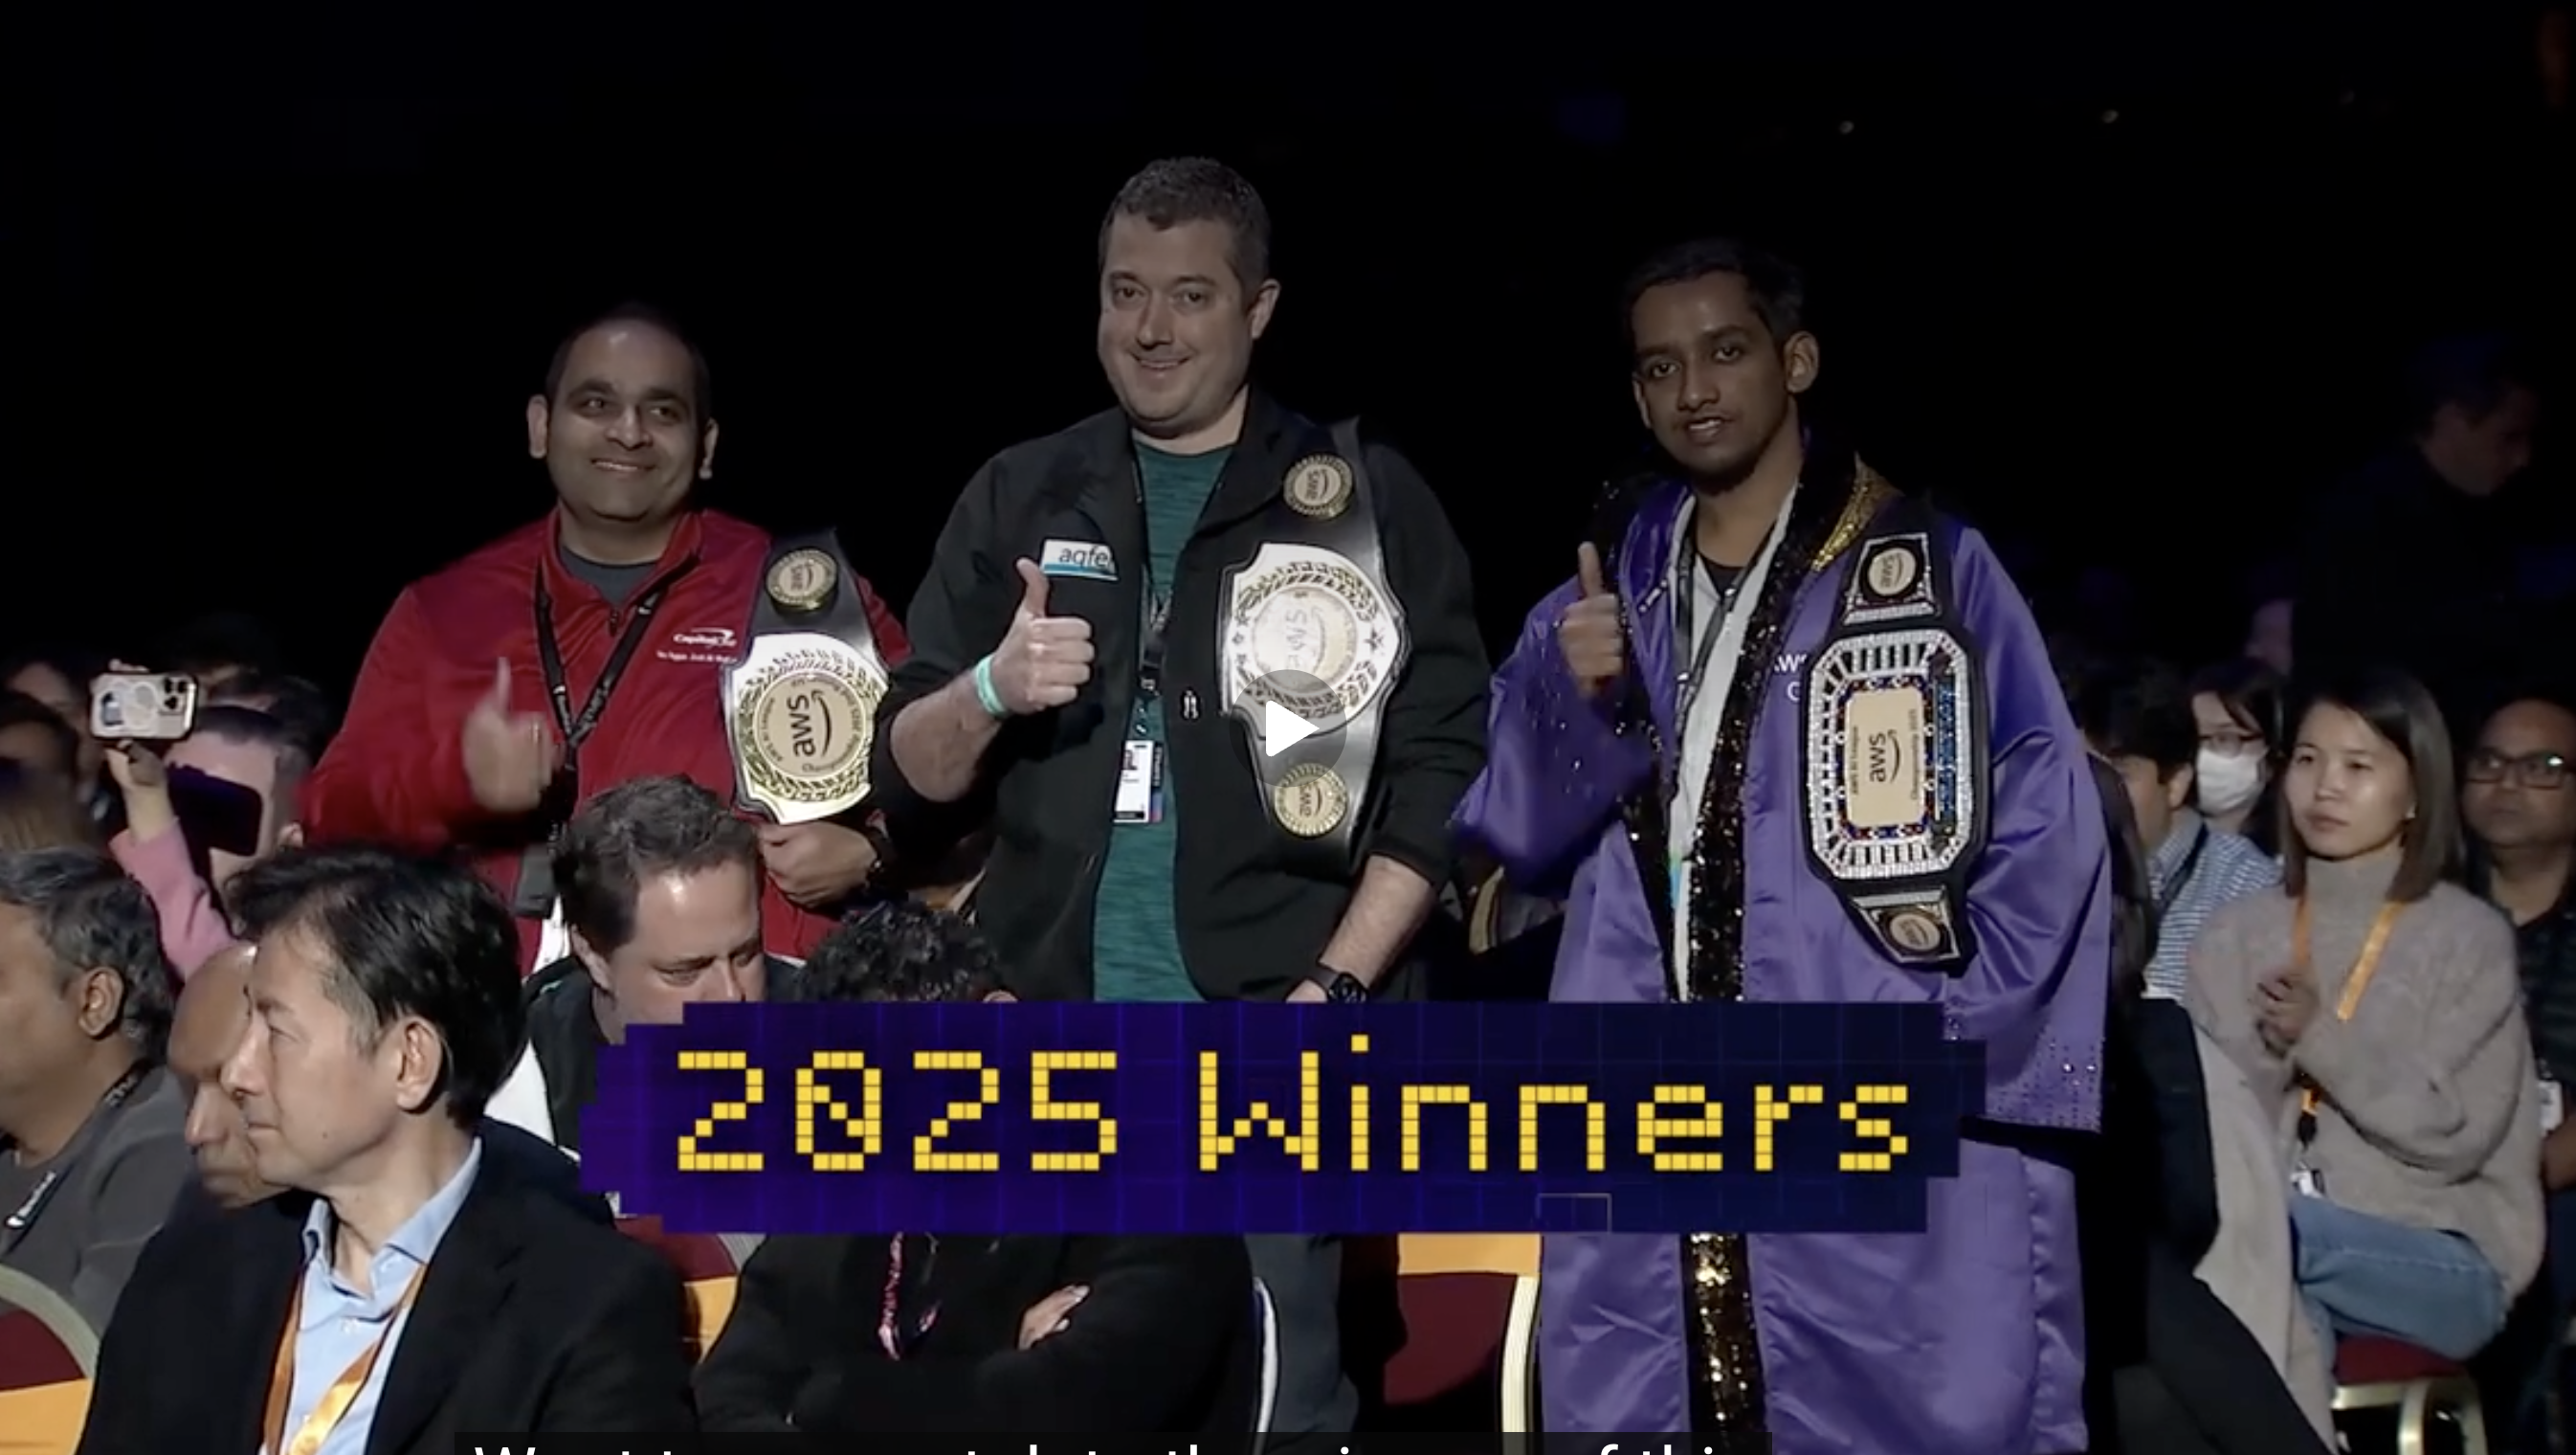
Cisco and AWS used Cisco Transformation Fest and AWS AI League to turn hands-on AI learning into a culture of building. A Cisco engineer won the 2025 AWS AI League global title and 1,200 engineers competed in 2026. This post shares Cisco's journey, lessons from the 2026 winning agent built on Amazon Bedrock AgentCore, and how to host your own league.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Dmitry Soldatkin SI

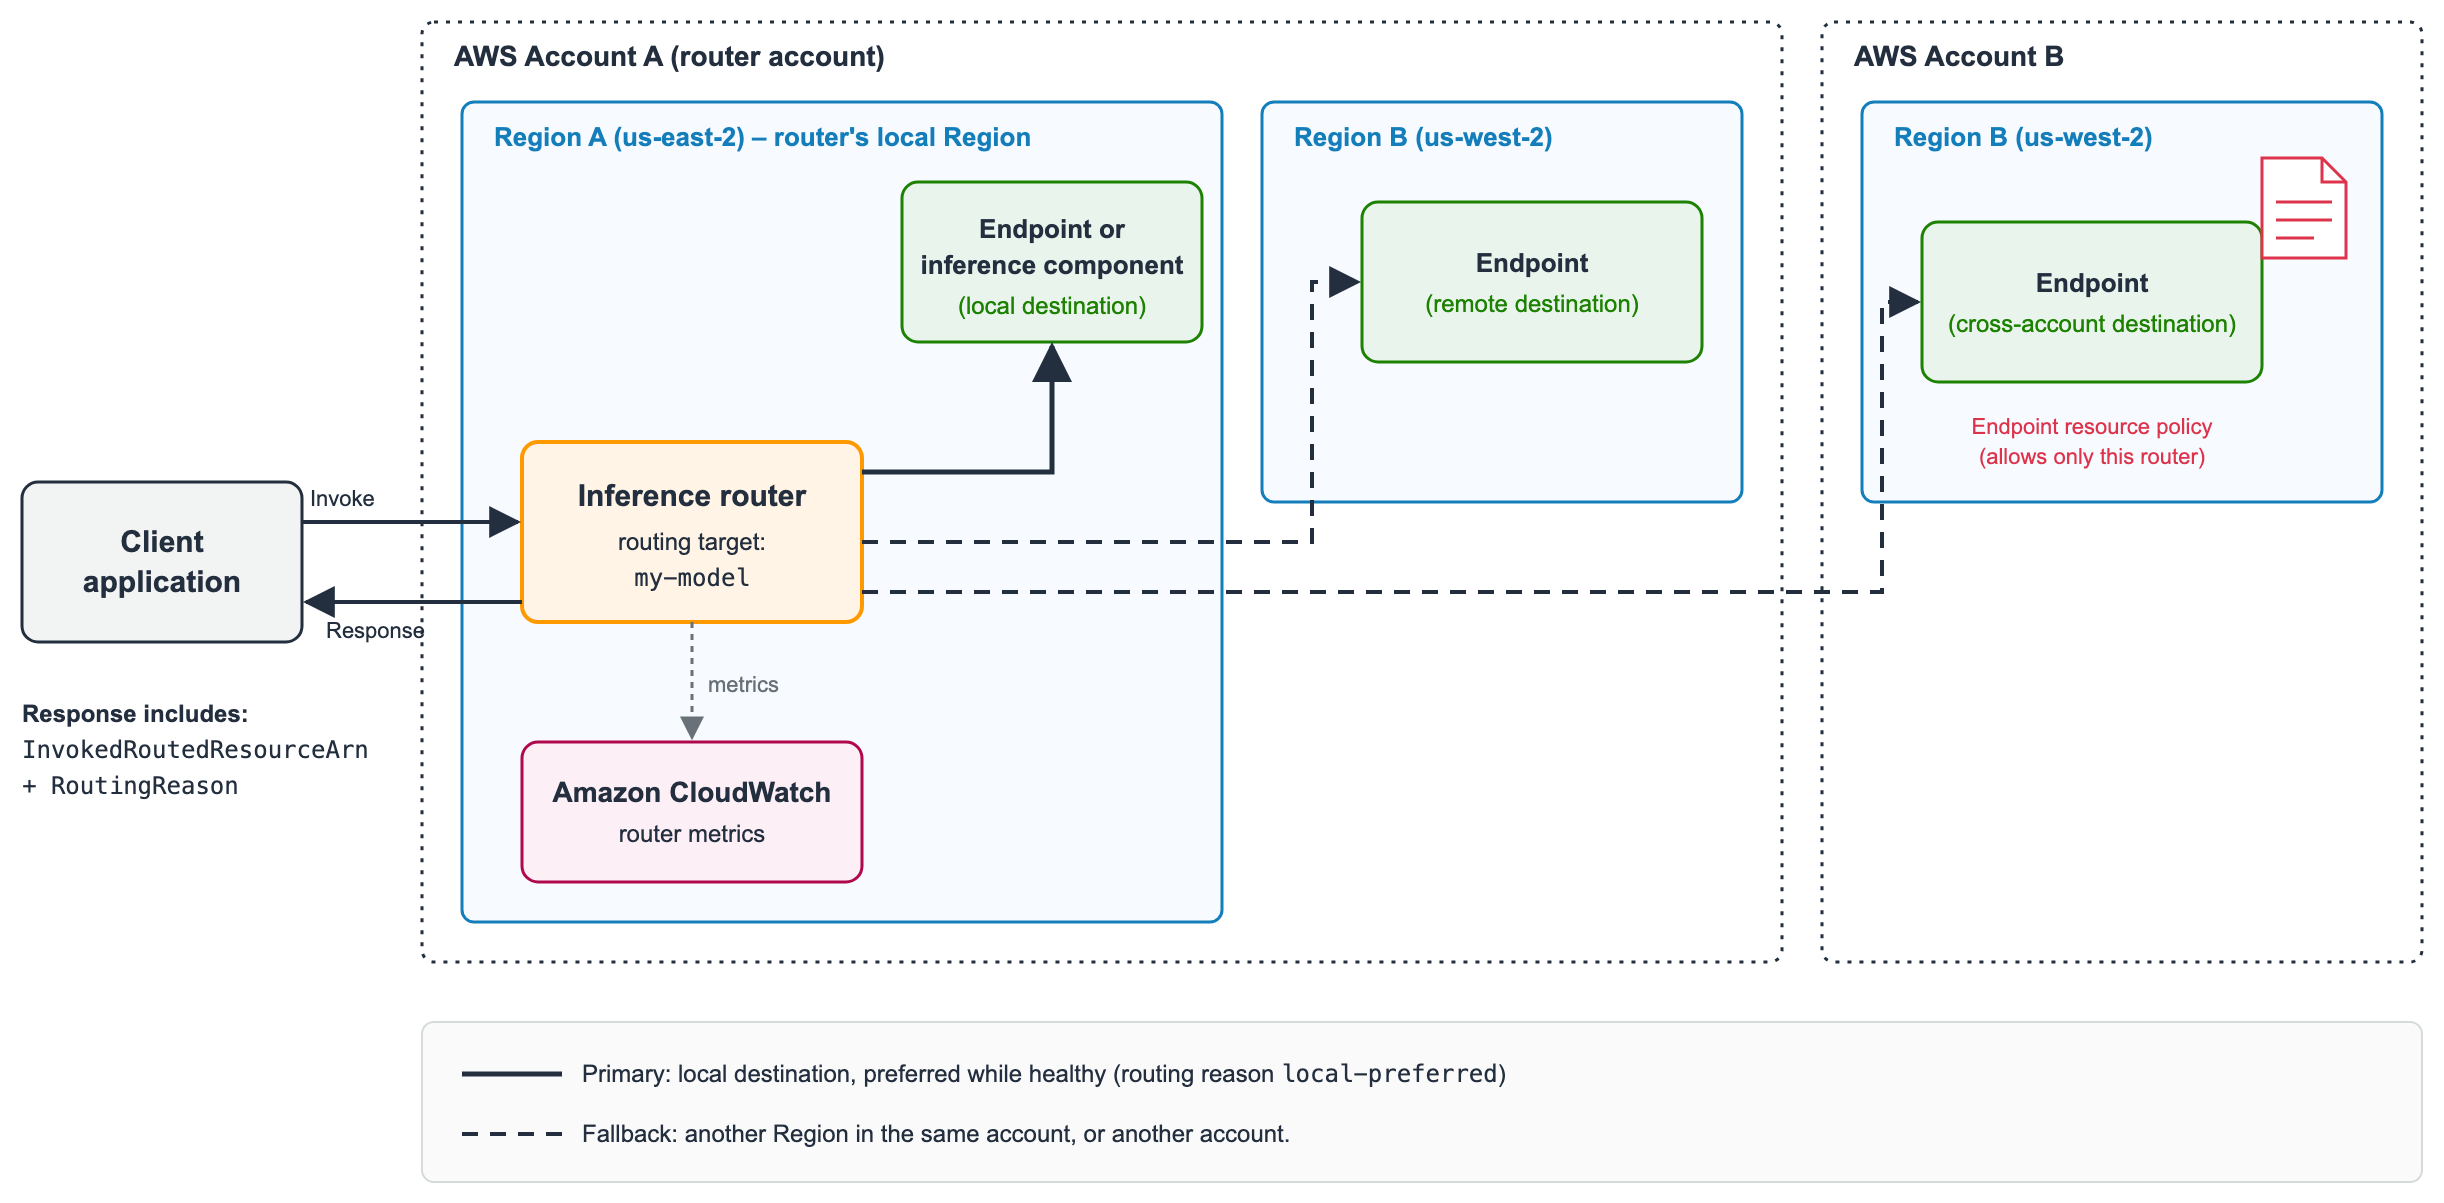
Keep inference running through regional capacity shortfalls with cross-Region inference routing in Amazon SageMaker AI

Cross-Region inference routing in Amazon SageMaker AI gives your application one invocation path across the endpoints and inference components you already run, in one or more AWS Regions and AWS accounts. The router prefers its own Region and shifts new requests to another destination only when the local one can't serve reliably.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Joe McCarron SI

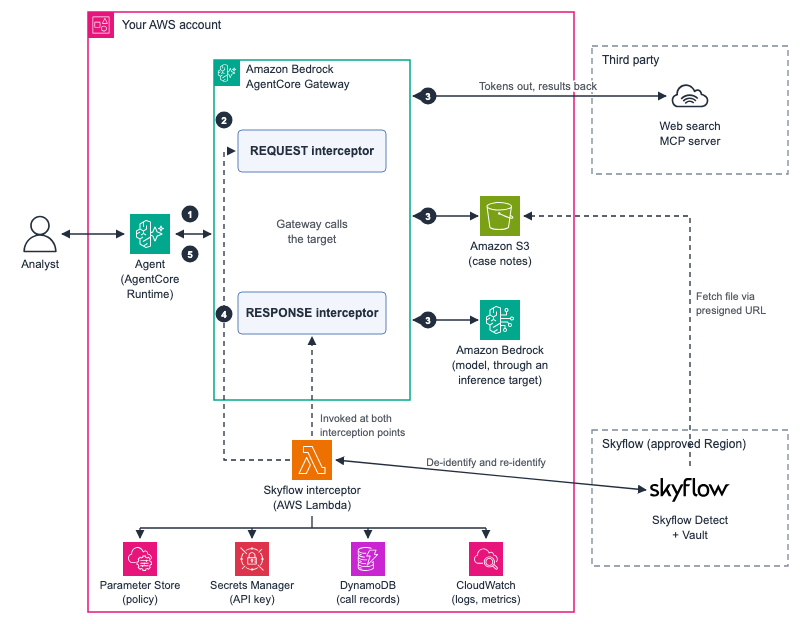
Protect agent tool calls with Skyflow and Amazon Bedrock AgentCore Gateway

Learn how Skyflow and Amazon Bedrock AgentCore Gateway keep sensitive data out of the tools your AI agents call. Added as a gateway interceptor, Skyflow de-identifies data before any tool, model, or log sees it, and restores it for authorized callers, with no change to your agent code.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Helen Greul SI

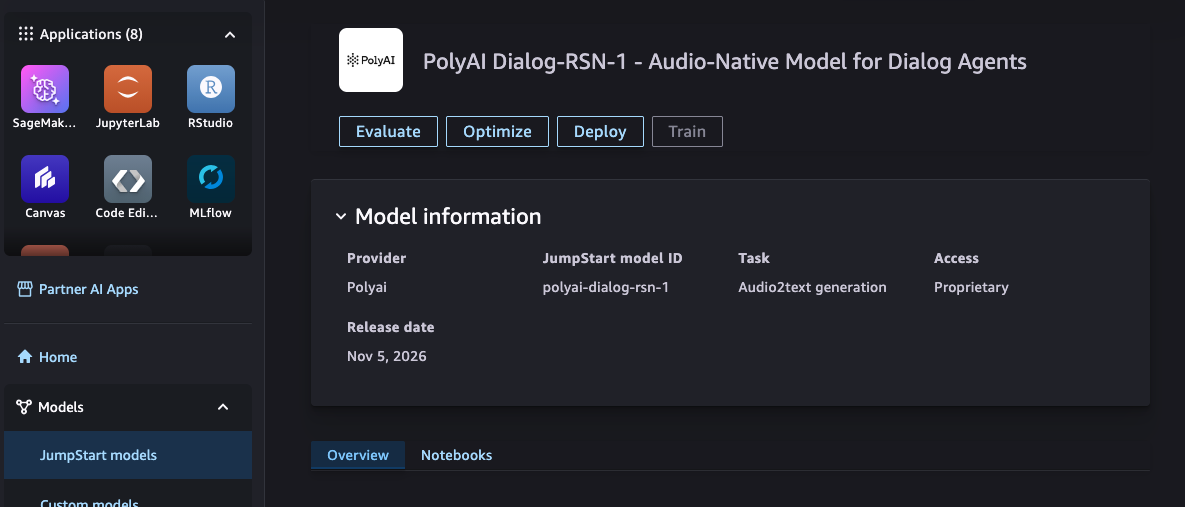
PolyAI Dialog-RSN-1 is now on Amazon SageMaker JumpStart

PolyAI Dialog-RSN-1, a reasoning model built for real-time complex dialog, is available today on AWS Marketplace and Amazon SageMaker JumpStart. Discover it, evaluate it on your own data, and deploy it to a secure SageMaker endpoint in your own AWS account.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Mijanur Palash SI

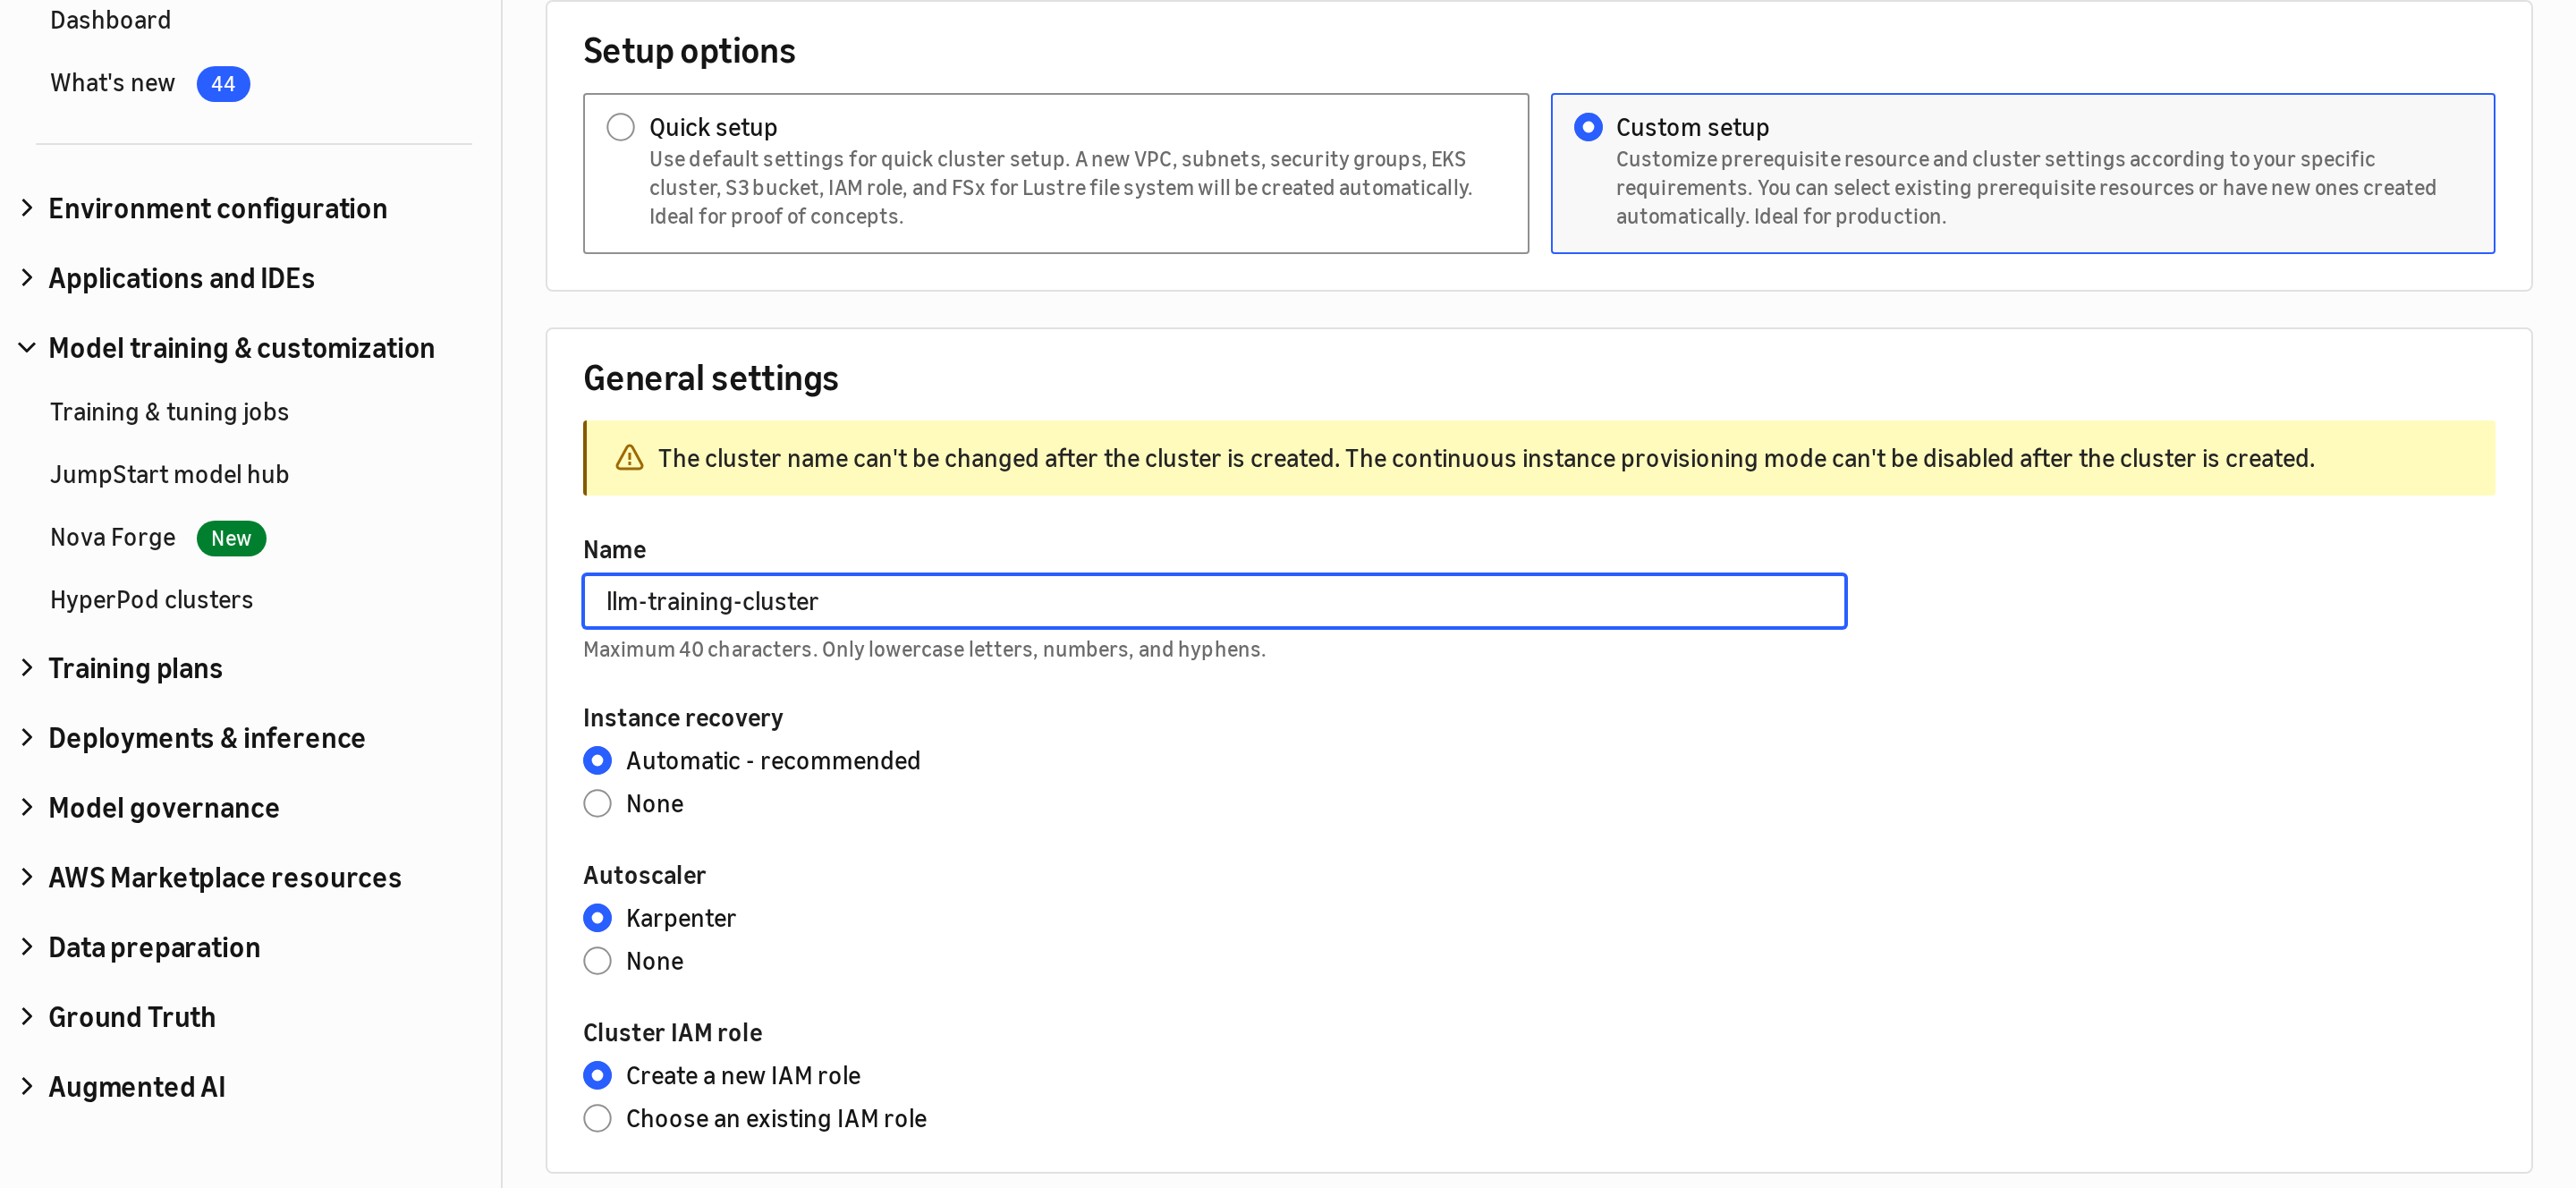
Introducing enhanced infrastructure observability in Amazon SageMaker HyperPod

Amazon SageMaker HyperPod now offers enhanced observability to help you diagnose GPU training issues faster. It brings together diagnostic and profiling capabilities for training workloads on both Amazon EKS and Slurm orchestrators, pinpointing issues across GPU, network, and host layers.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Muru Bhaskaran SI

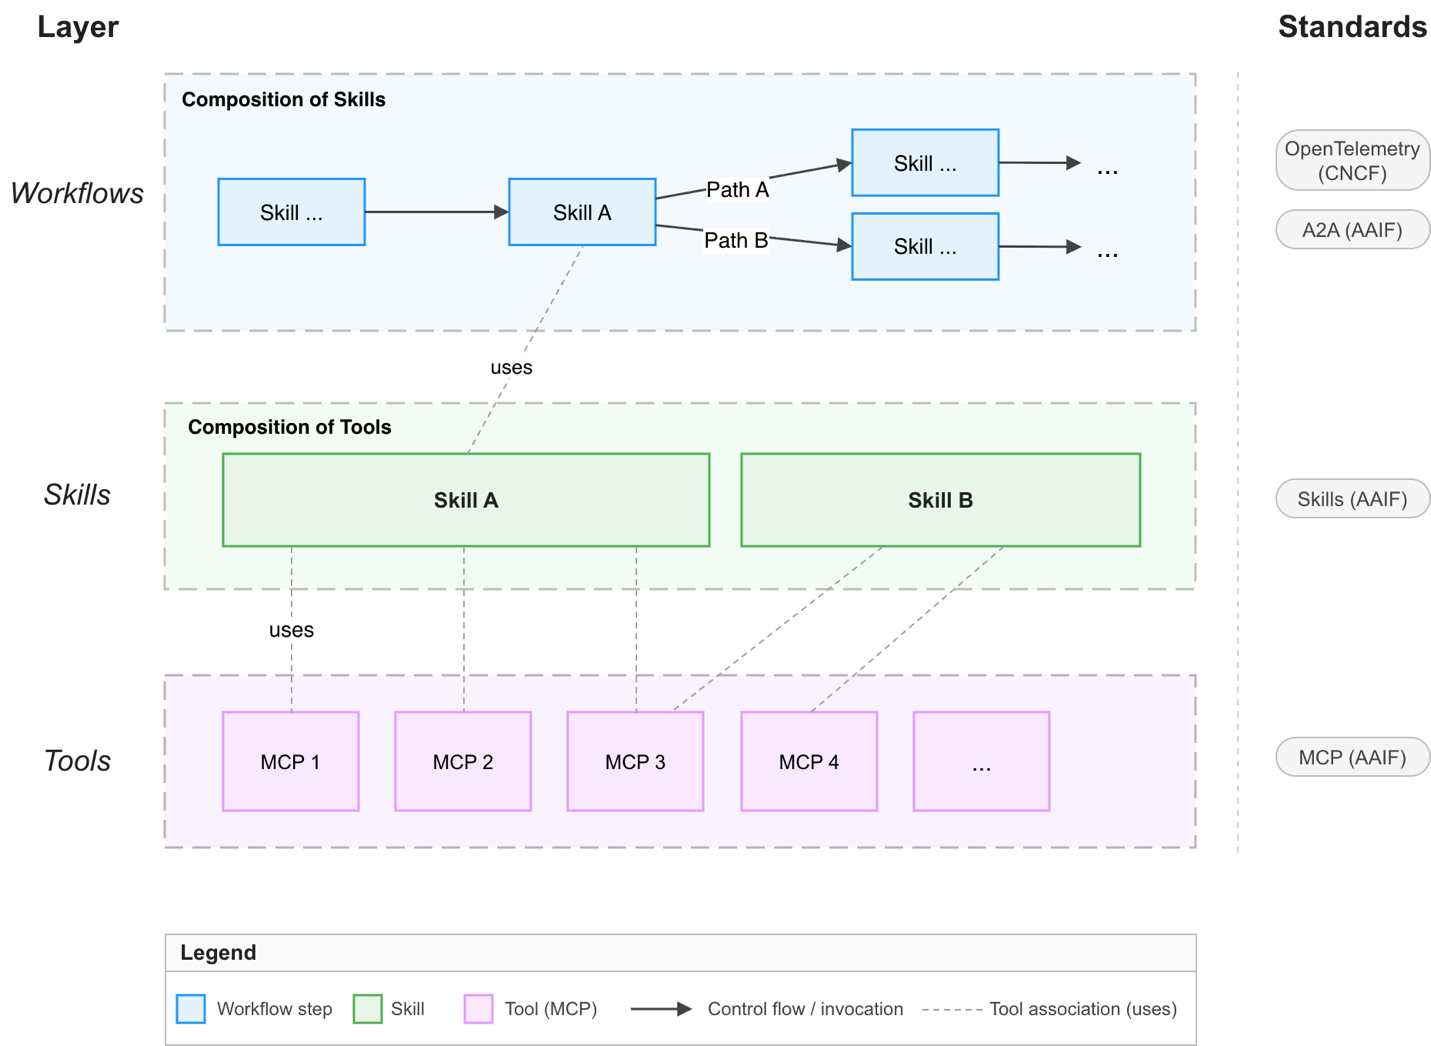
Using NVIDIA Run:ai GPU Fractioning on Amazon EKS

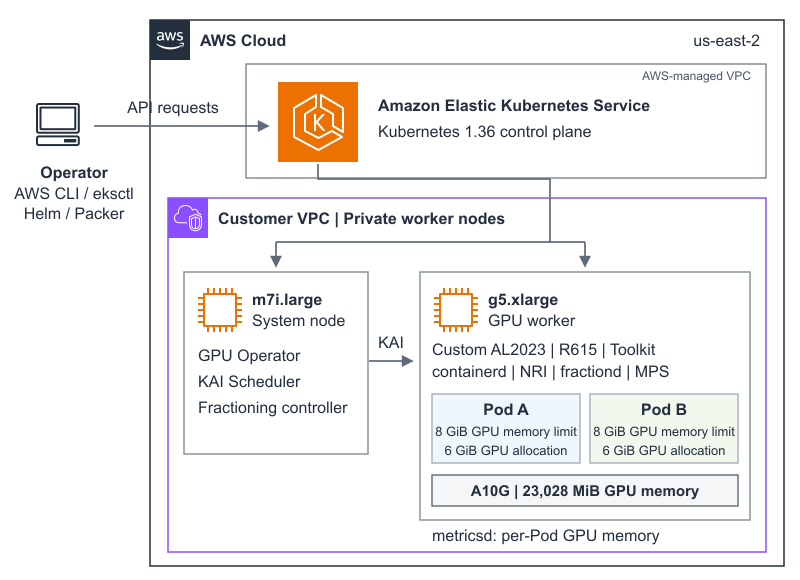
Learn how to run two memory-bounded Kubernetes Pods on a single NVIDIA A10G GPU using open-source NVIDIA Run:ai GPU Fractioning on Amazon EKS. This walkthrough builds a custom Amazon Linux 2023 image, installs KAI Scheduler and the GPU Fractioning Operator, and validates per-Pod GPU-memory contracts with enforcement and metrics.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Sandeep Raveesh-Babu SI

Full Fine-Tuning (FFT) on SageMaker AI Serverless Model Customization

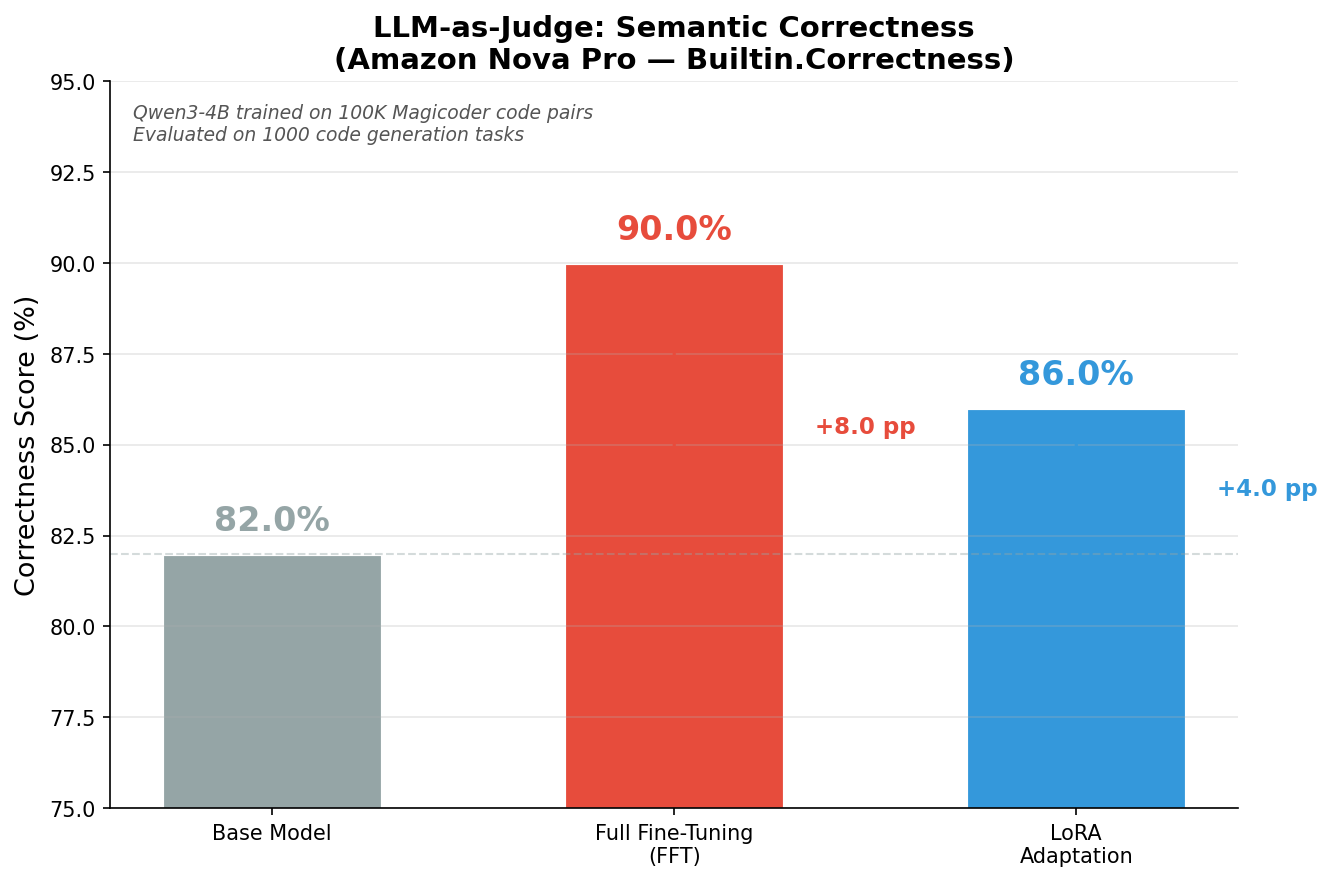
Amazon SageMaker AI Serverless Model Customization now supports Full Fine-Tuning (FFT). This post explores when FFT outperforms LoRA across key benchmarks, examines the spectral properties of model weight matrices behind the quality gap, shares practical hyperparameter tuning guidelines, and shows how to get started.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Summer Devlin SI

Exa boosts embedding throughput by 50% to index billions of documents on AWS AI chips

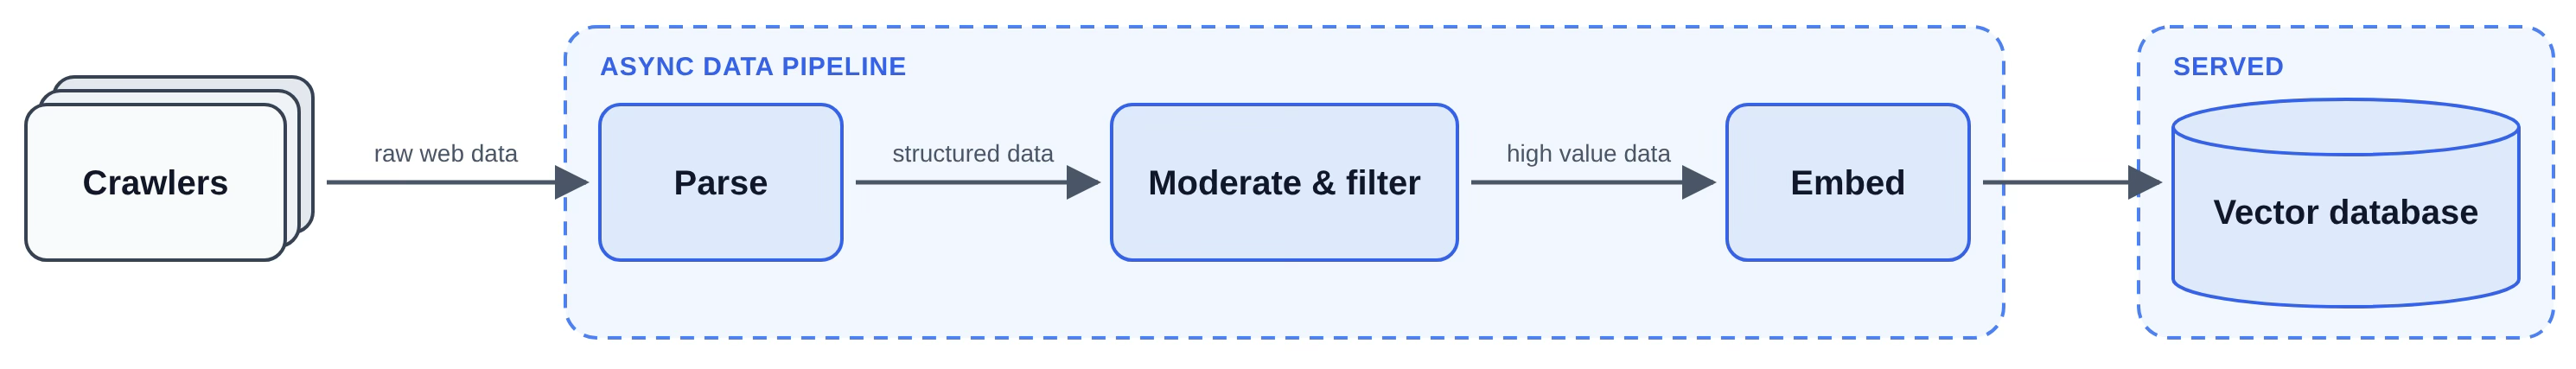
Exa's neural search engine is backed by an in-house vector database, so the unit economics of embedding tens of billions of web documents drive the business. This post shares how Exa optimized embedding inference on AWS Neuron hardware (Inferentia2 and Trainium2) with custom NKI kernels, reaching a 47% gain in performance and cost per million documents.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Roy Allela SI

Introducing workload recovery and expanded infrastructure checks on Amazon SageMaker HyperPod

Large training jobs can stall or compute wrong results even when every node looks healthy. Amazon SageMaker HyperPod now adds workload recovery and expanded infrastructure checks that catch these failures sooner and raise the goodput of your training workloads.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Dan Ferguson SI

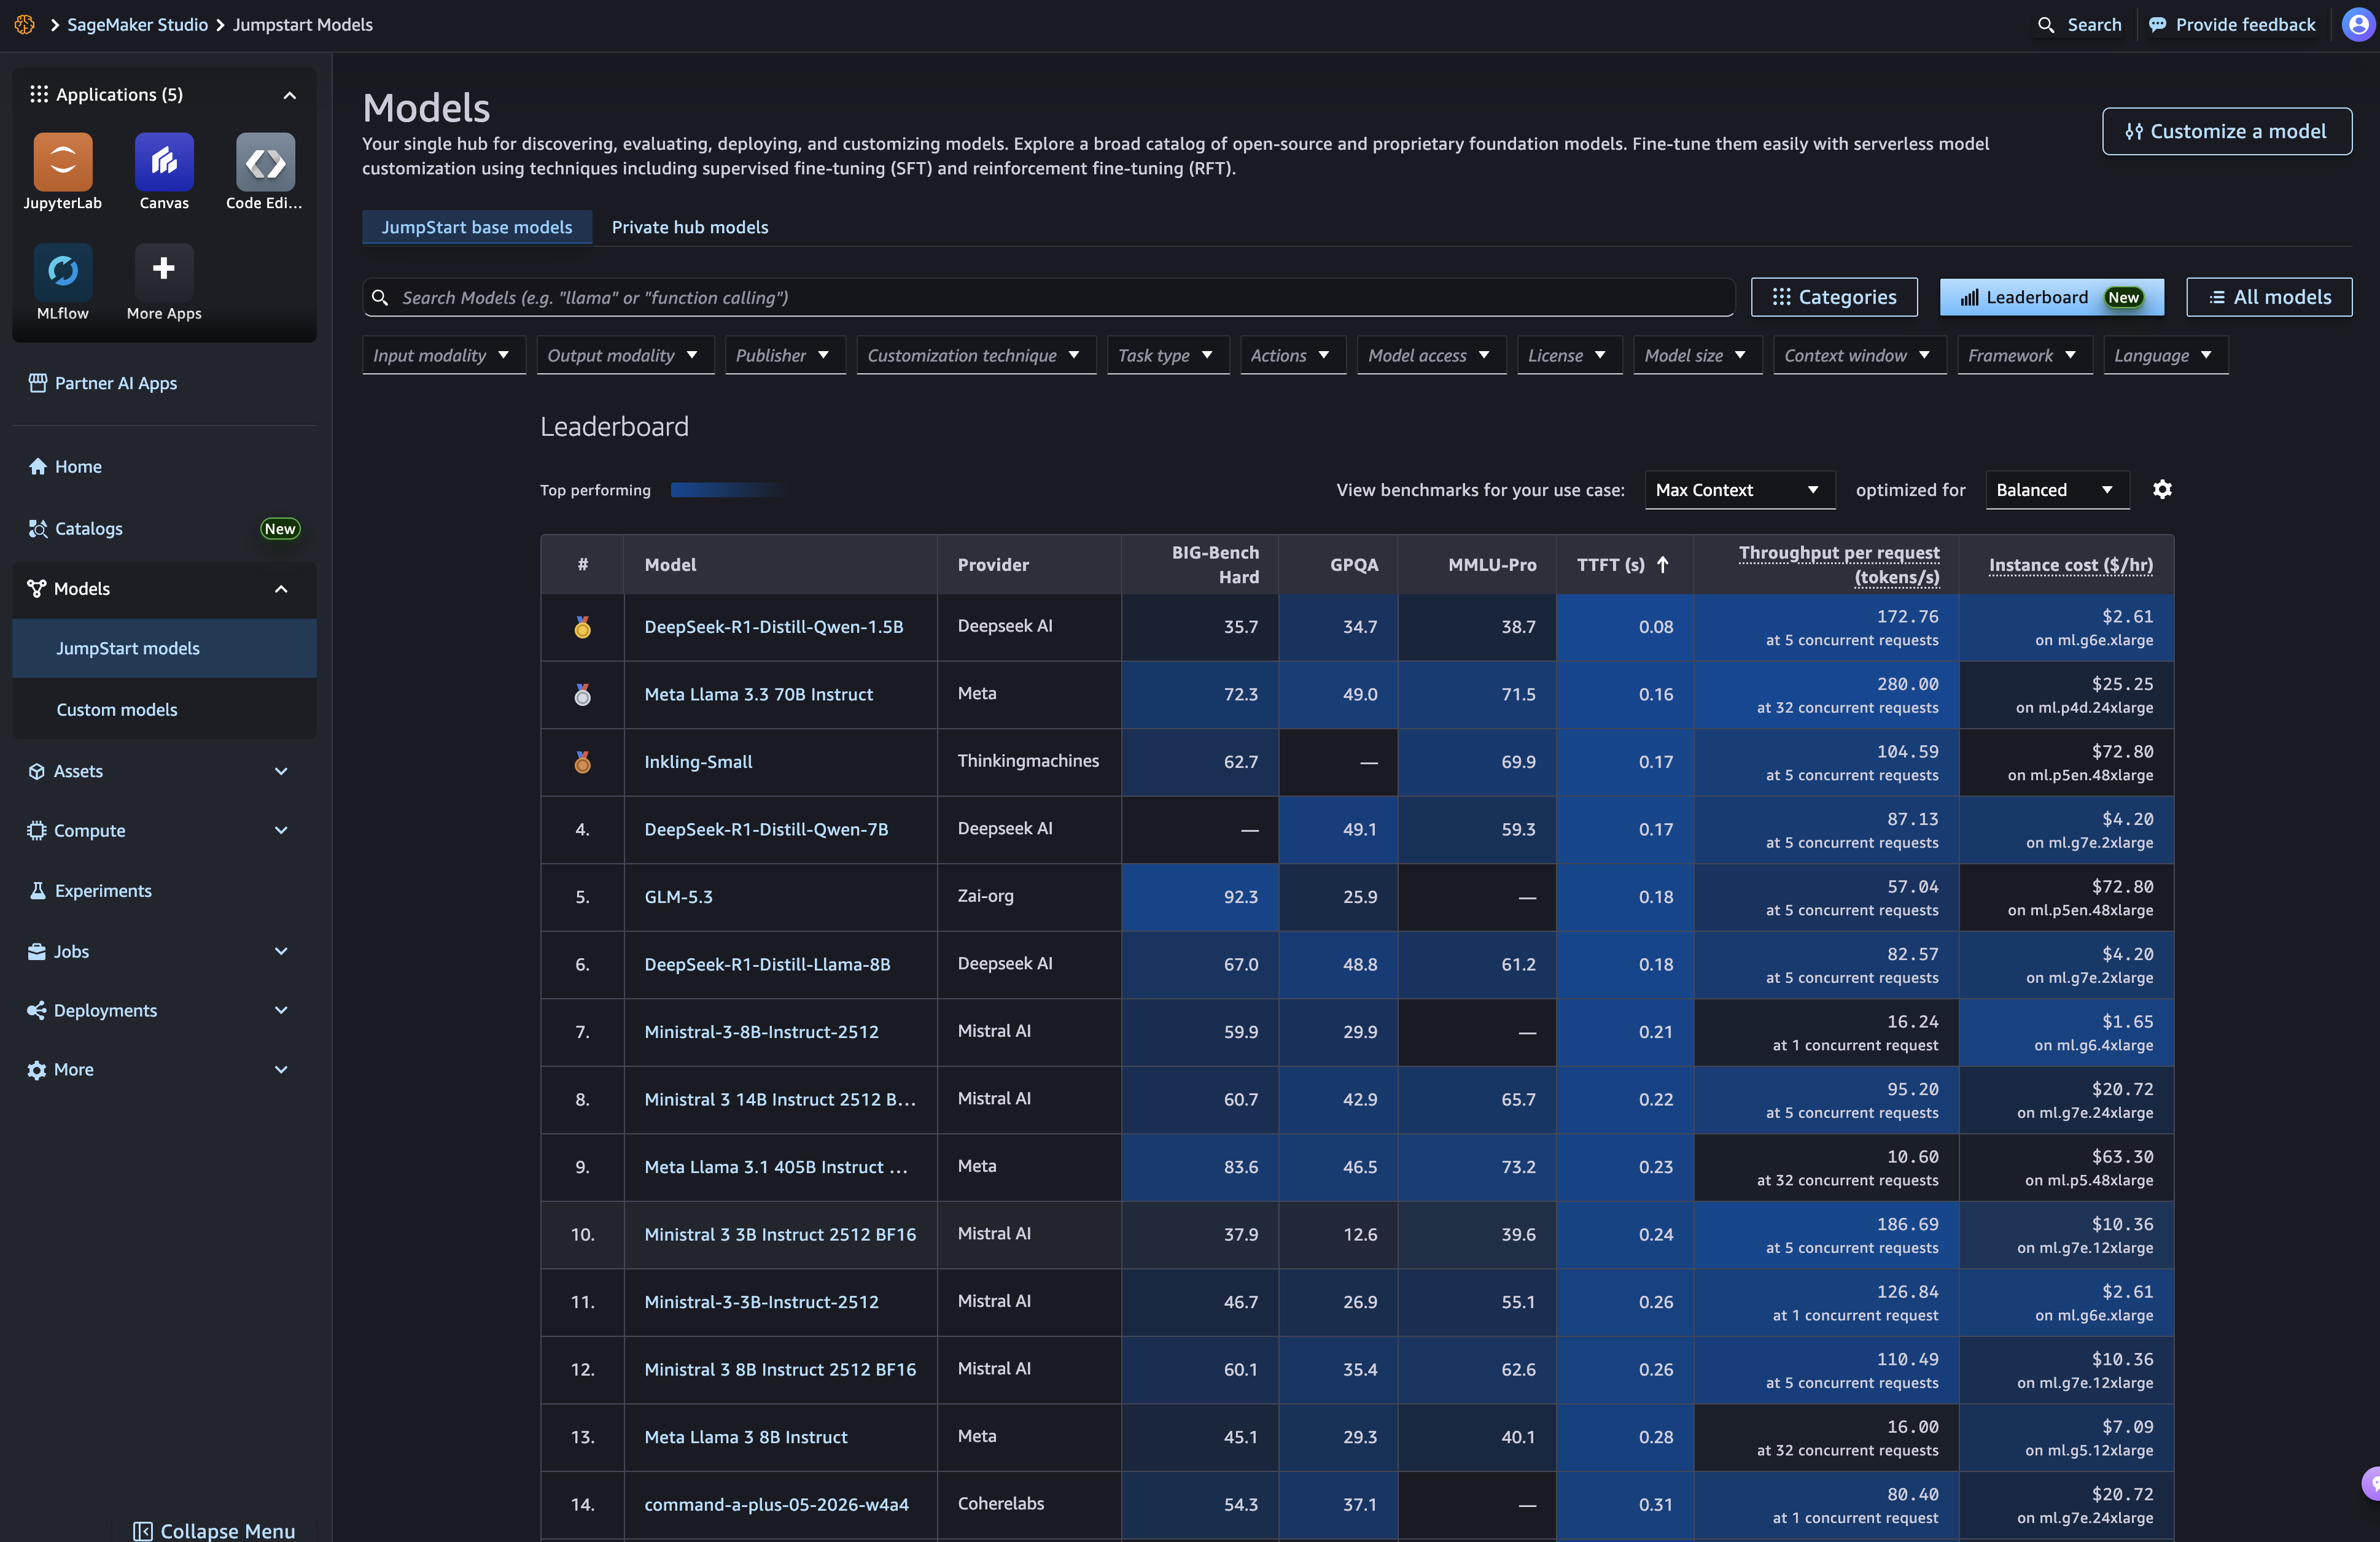
Introducing the Amazon SageMaker JumpStart Model Leaderboard

The Amazon SageMaker JumpStart Model Leaderboard compares 70+ foundation models side by side on quality, speed, and cost, directly in SageMaker Studio. Learn what the leaderboard shows, how AWS benchmarks models, and how to go from a shortlist to a deployed model.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Alan Yao SI

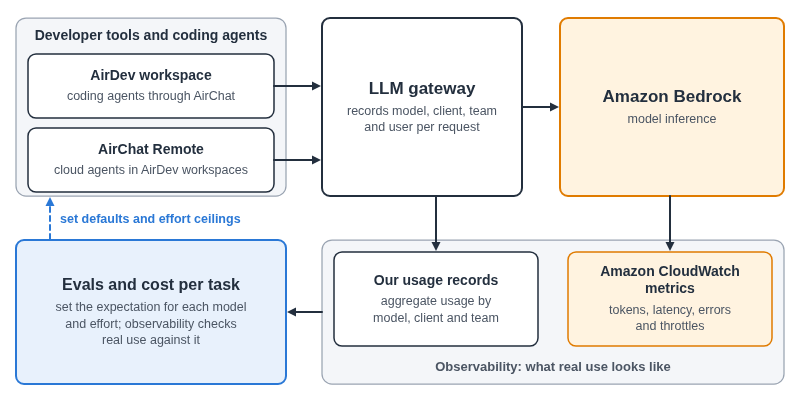
How Airbnb uses cost per task to operate coding agents on Amazon Bedrock

Airbnb runs evals on real engineering tasks and uses Amazon Bedrock observability to choose models for its coding agents and control production costs. This post shows how cost per task guides model selection, why production spending can differ from eval results, and how to monitor latency, manage quotas, and attribute spend.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog InduTeja Aligeti SI

Design responsible AI controls for Amazon Aurora PostgreSQL

Learn how to make RAG chatbot answers traceable with Amazon Aurora PostgreSQL, pgvector, and Amazon Bedrock Guardrails, logging sources, scores, and guardrail traces in SQL.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Aastha Paul SI

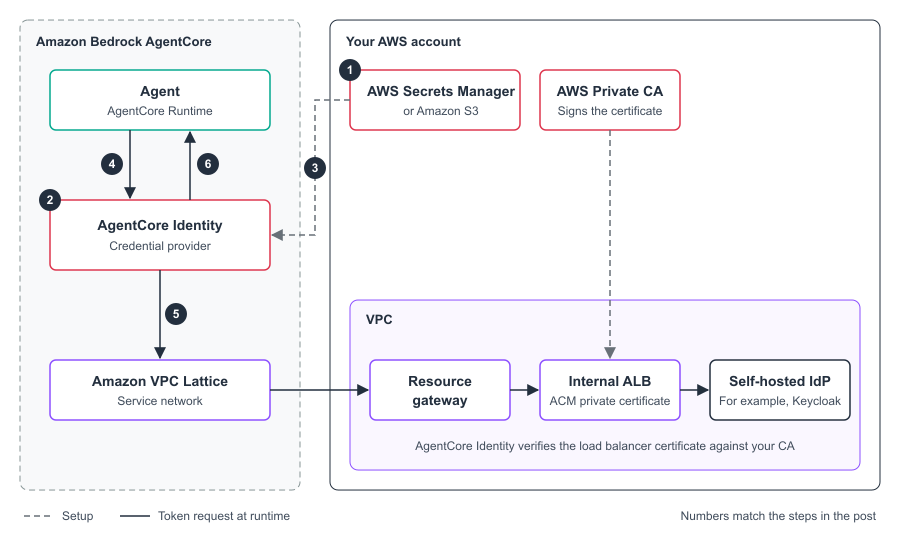
Private certificate authority support in Amazon Bedrock AgentCore Identity

Amazon Bedrock AgentCore Identity now supports private certificate authorities (CAs), so your agents can connect to self-hosted identity providers that use a private CA. This post shows how to issue an IdP certificate with AWS Private CA, configure a credential provider to trust it, rotate the CA, and protect the certificate.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Apoorva Chandra SI

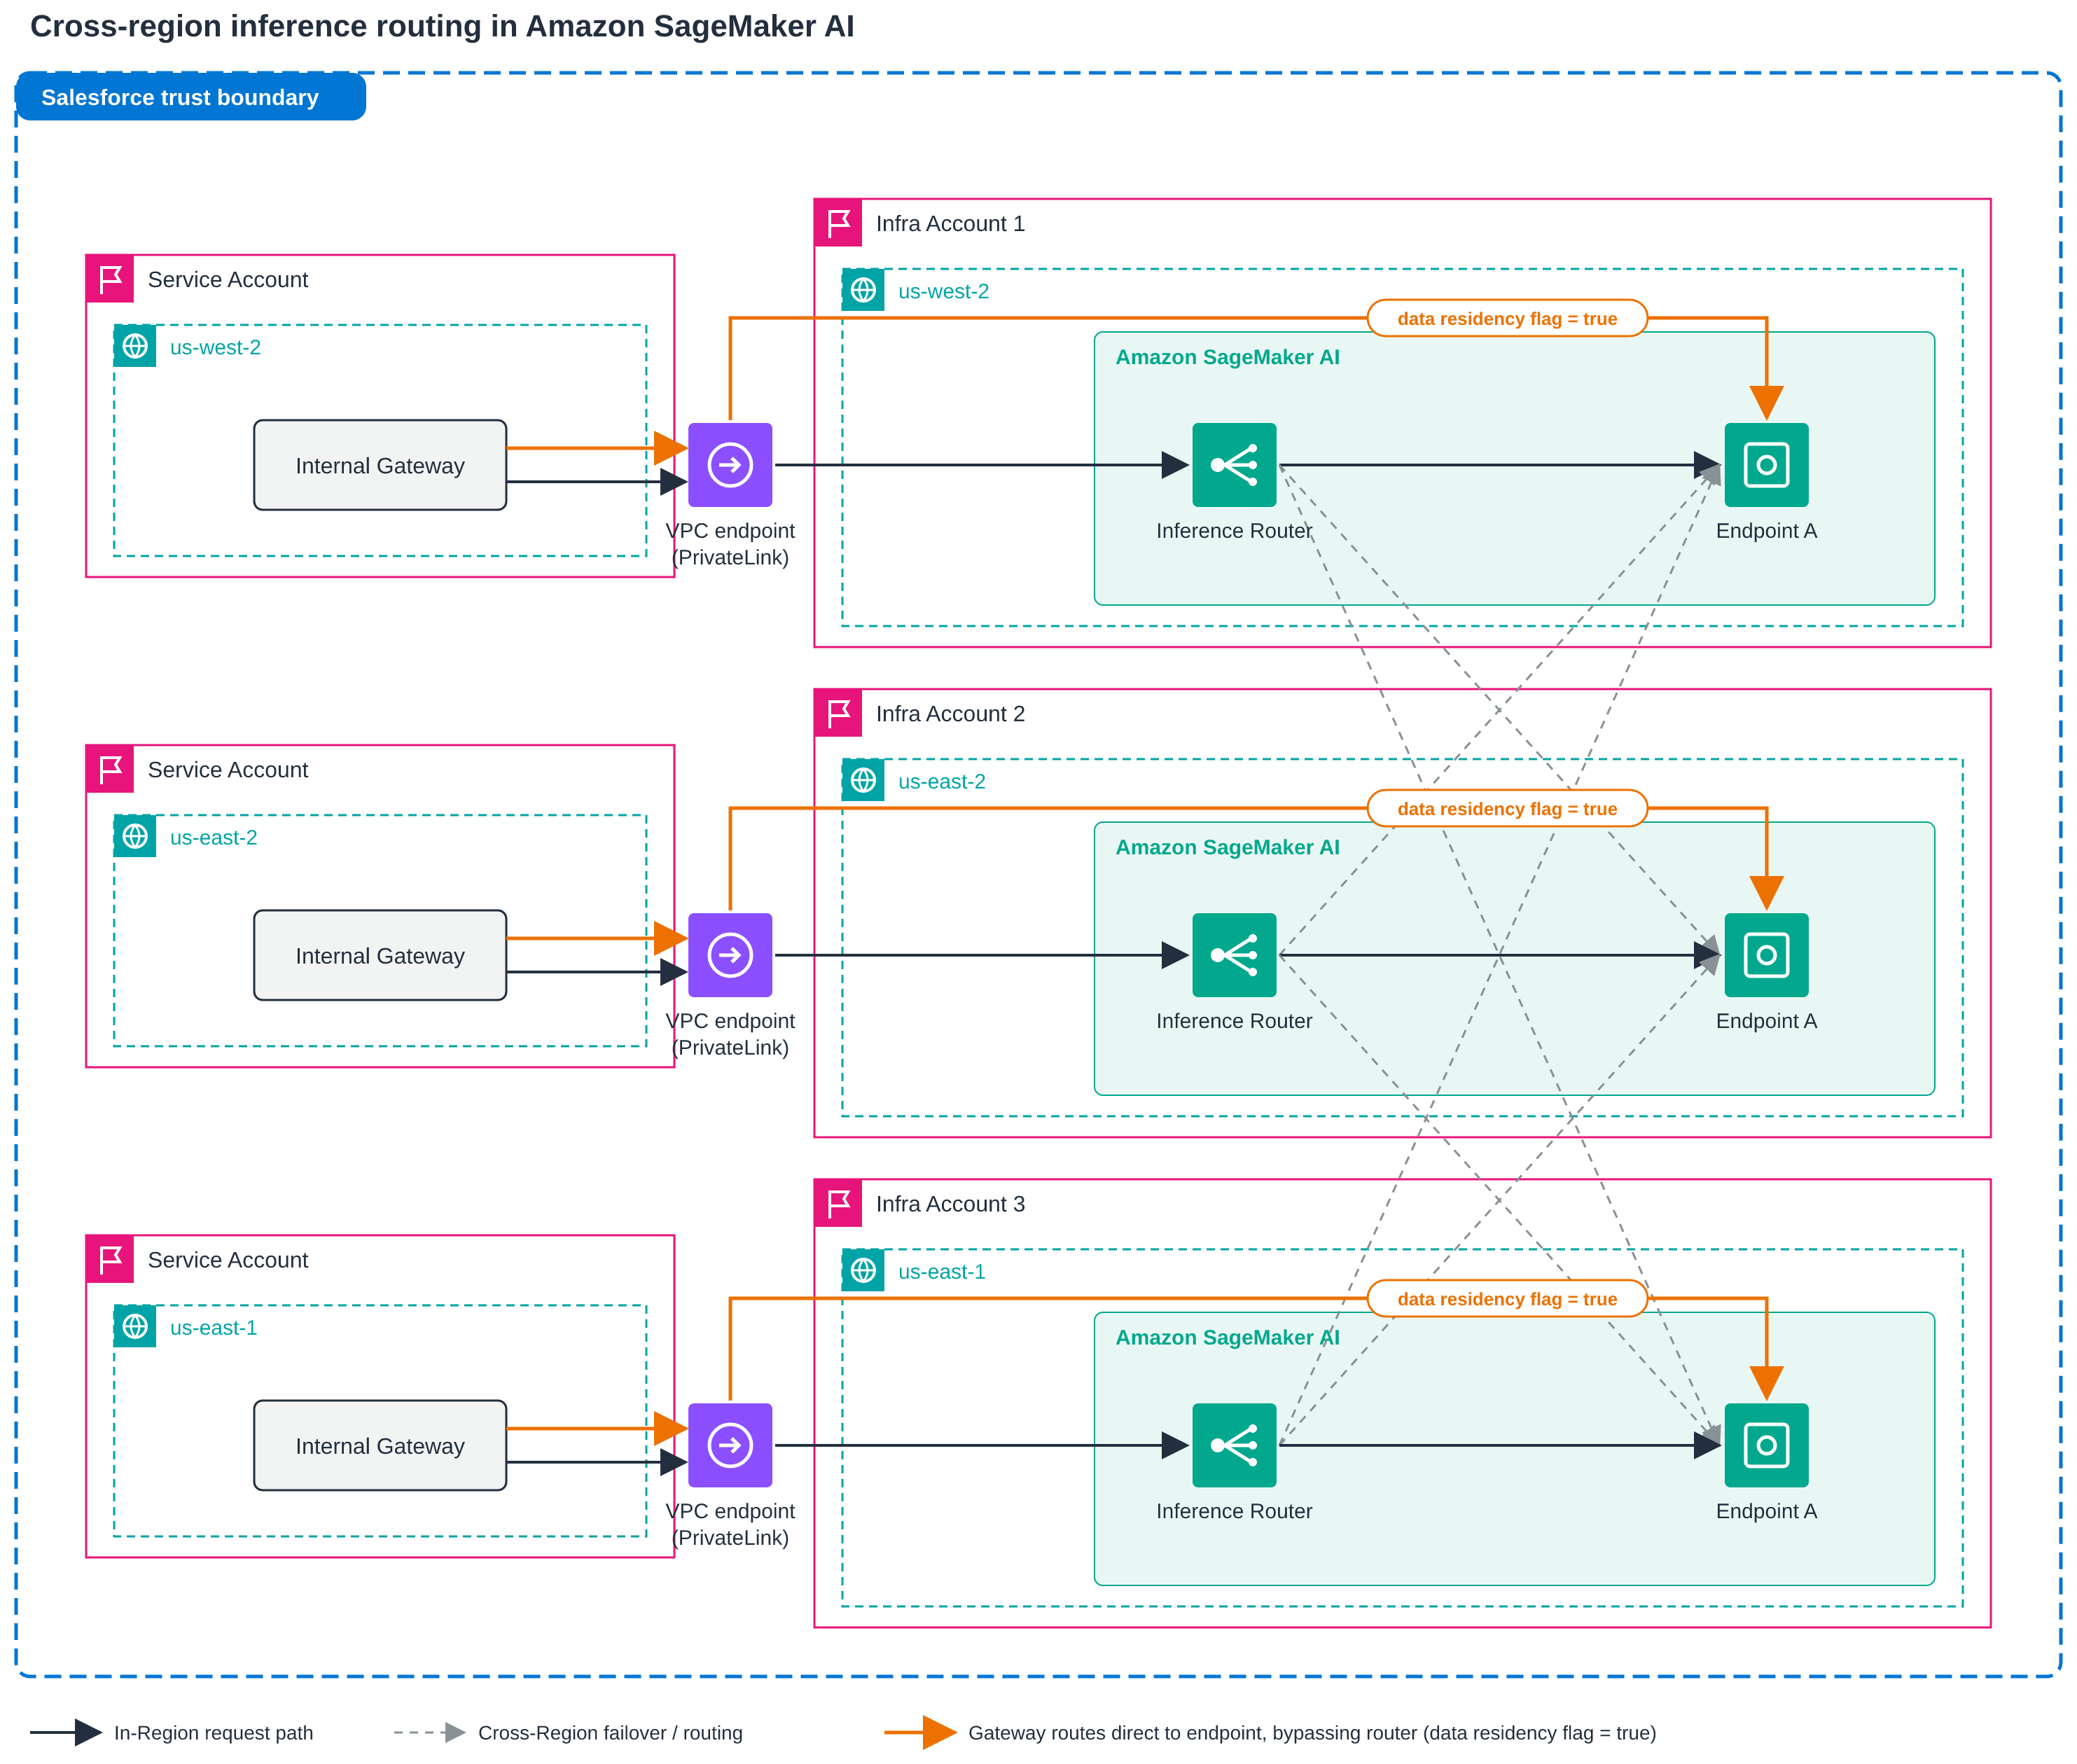
How Salesforce is advancing global-scale model serving with cross-Region inference routing in Amazon SageMaker AI

Learn how Salesforce uses the cross-Region inference router in Amazon SageMaker AI to turn fragmented Regional capacity into reliable model serving. Salesforce adds capacity securely across Regions and accounts while keeping its data residency commitments, and sees per request where each call was served and why.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Mariah Miller SI

How Social Department built culture-aware video discovery

Social Department, an AI operating system for entertainment marketing, worked with TrackIt and AWS to build QuickSearch: single-action queries that surface shareable scenes, quotable lines, memeable frames, and trend-aligned moments across large video libraries, using TwelveLabs models on Amazon Bedrock and Amazon OpenSearch Serverless.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Puneeth Komaragiri SI

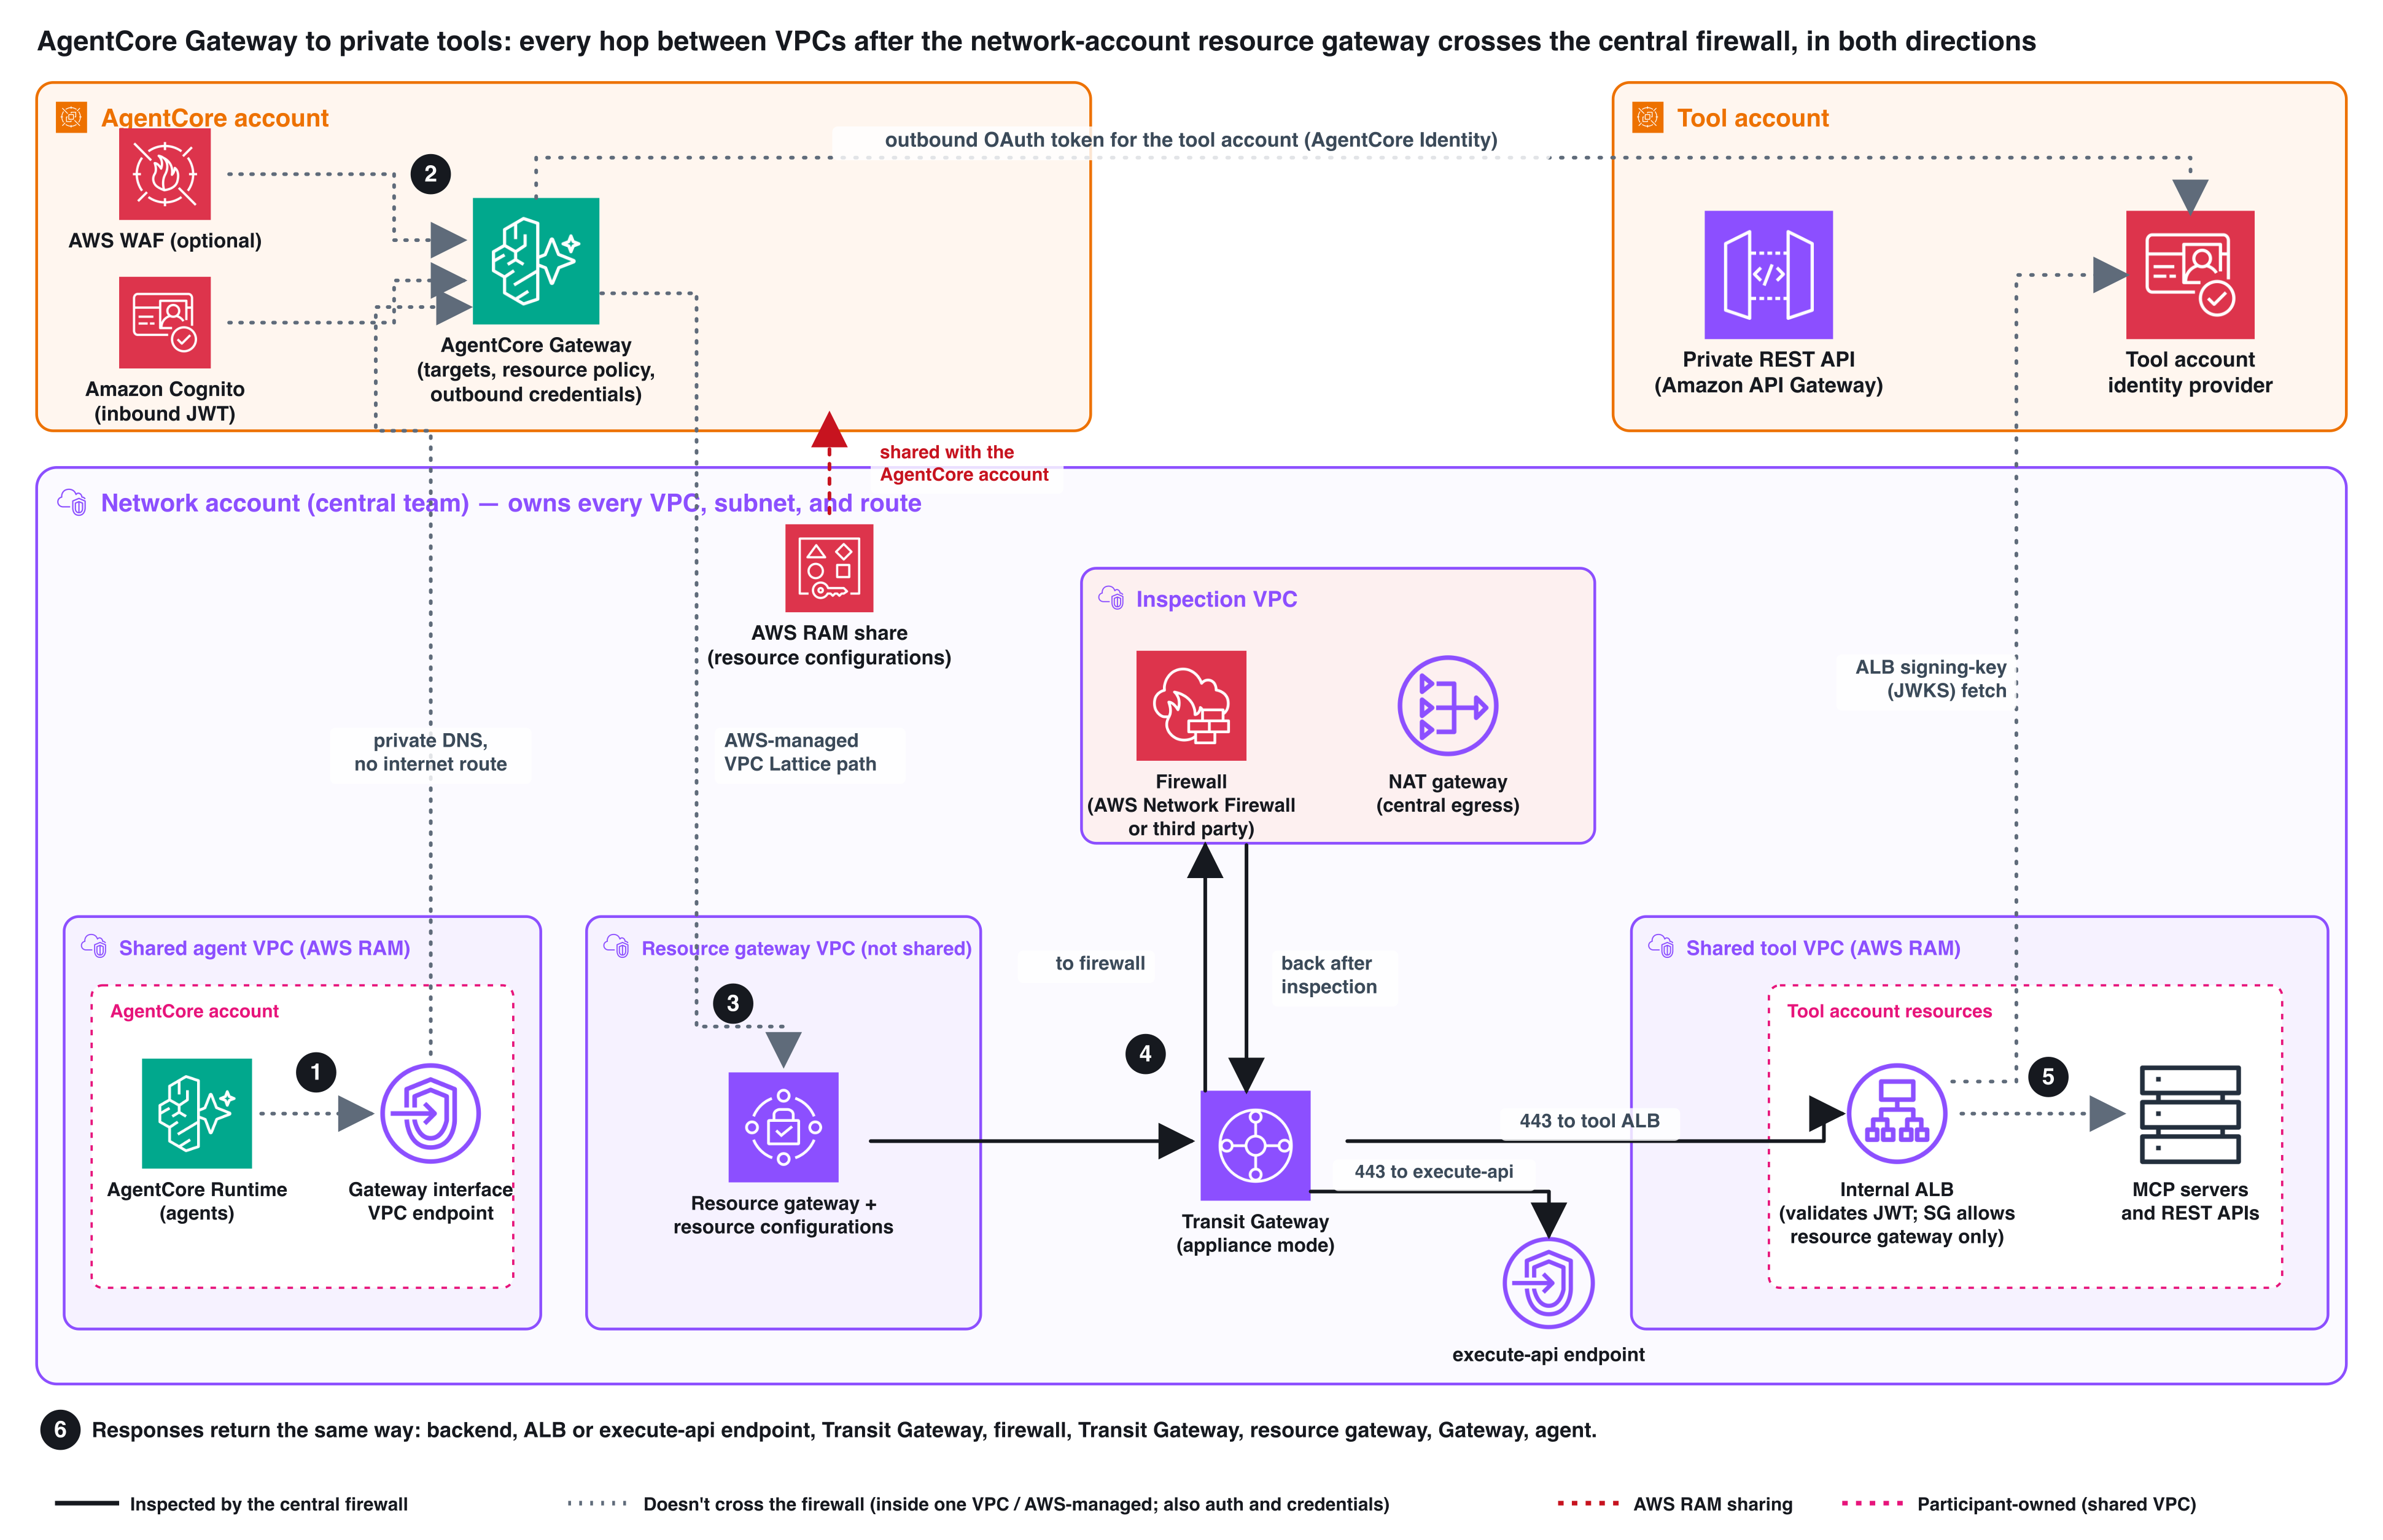
Connect Amazon Bedrock AgentCore Gateway to private APIs in a hub-and-spoke network with centralized inspection

Many enterprises run a centralized network model: one account owns every VPC and a central firewall inspects all traffic. This post shows a tested pattern for connecting Amazon Bedrock AgentCore Gateway to private APIs and MCP servers in that model, with the VPC Lattice resource gateway in the network account so every hop crosses the firewall.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Mariah Miller SI

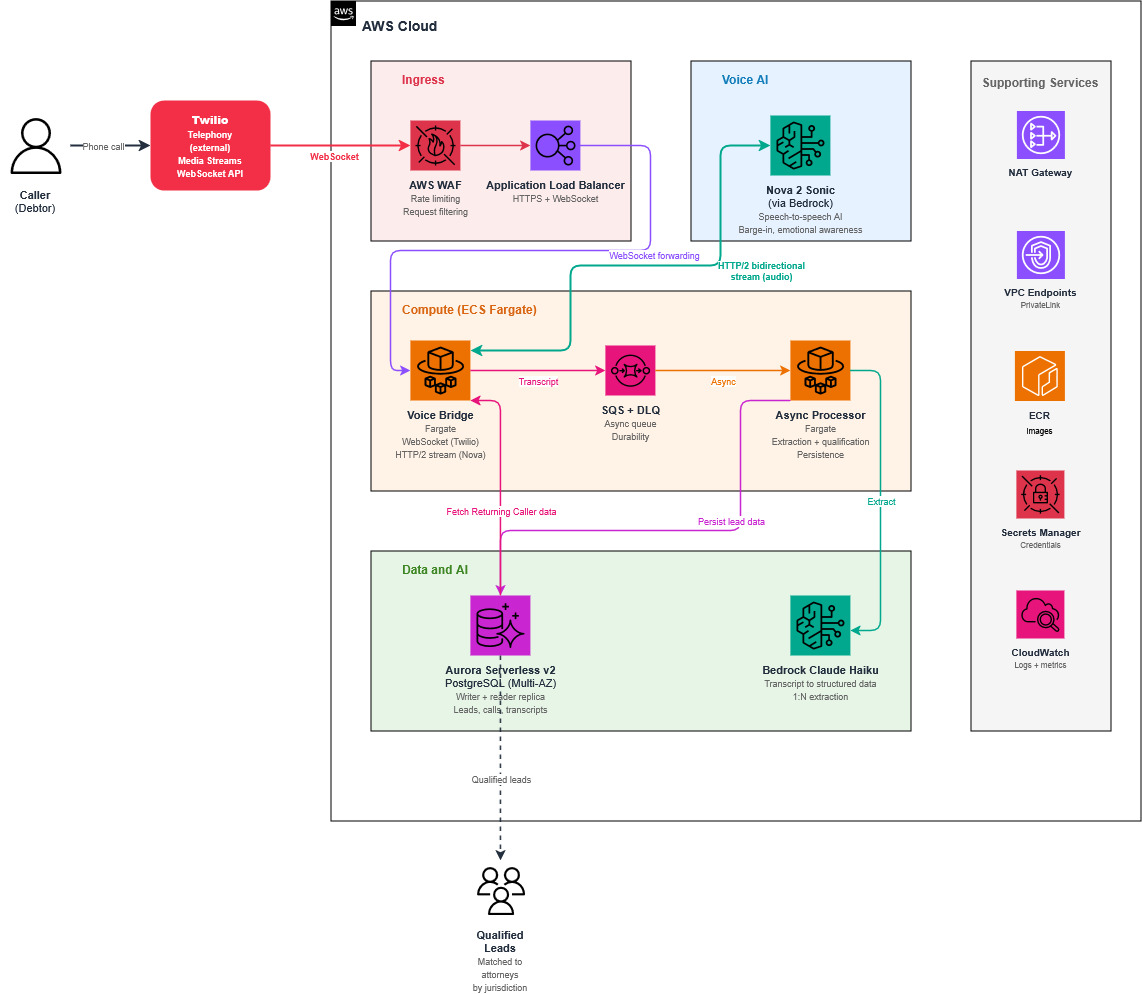
How Stretto built an AI voice agent with Amazon Nova 2 Sonic

Stretto replaced its web-form lead capture with Tara, an AI voice agent built on Amazon Nova 2 Sonic that conducts bankruptcy intake interviews by phone and qualifies leads. See how Stretto, the AWS Generative AI Innovation Center, and CI&T designed the voice architecture, validated it for sensitive conversations, and moved it to production.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Jane Ridge SI

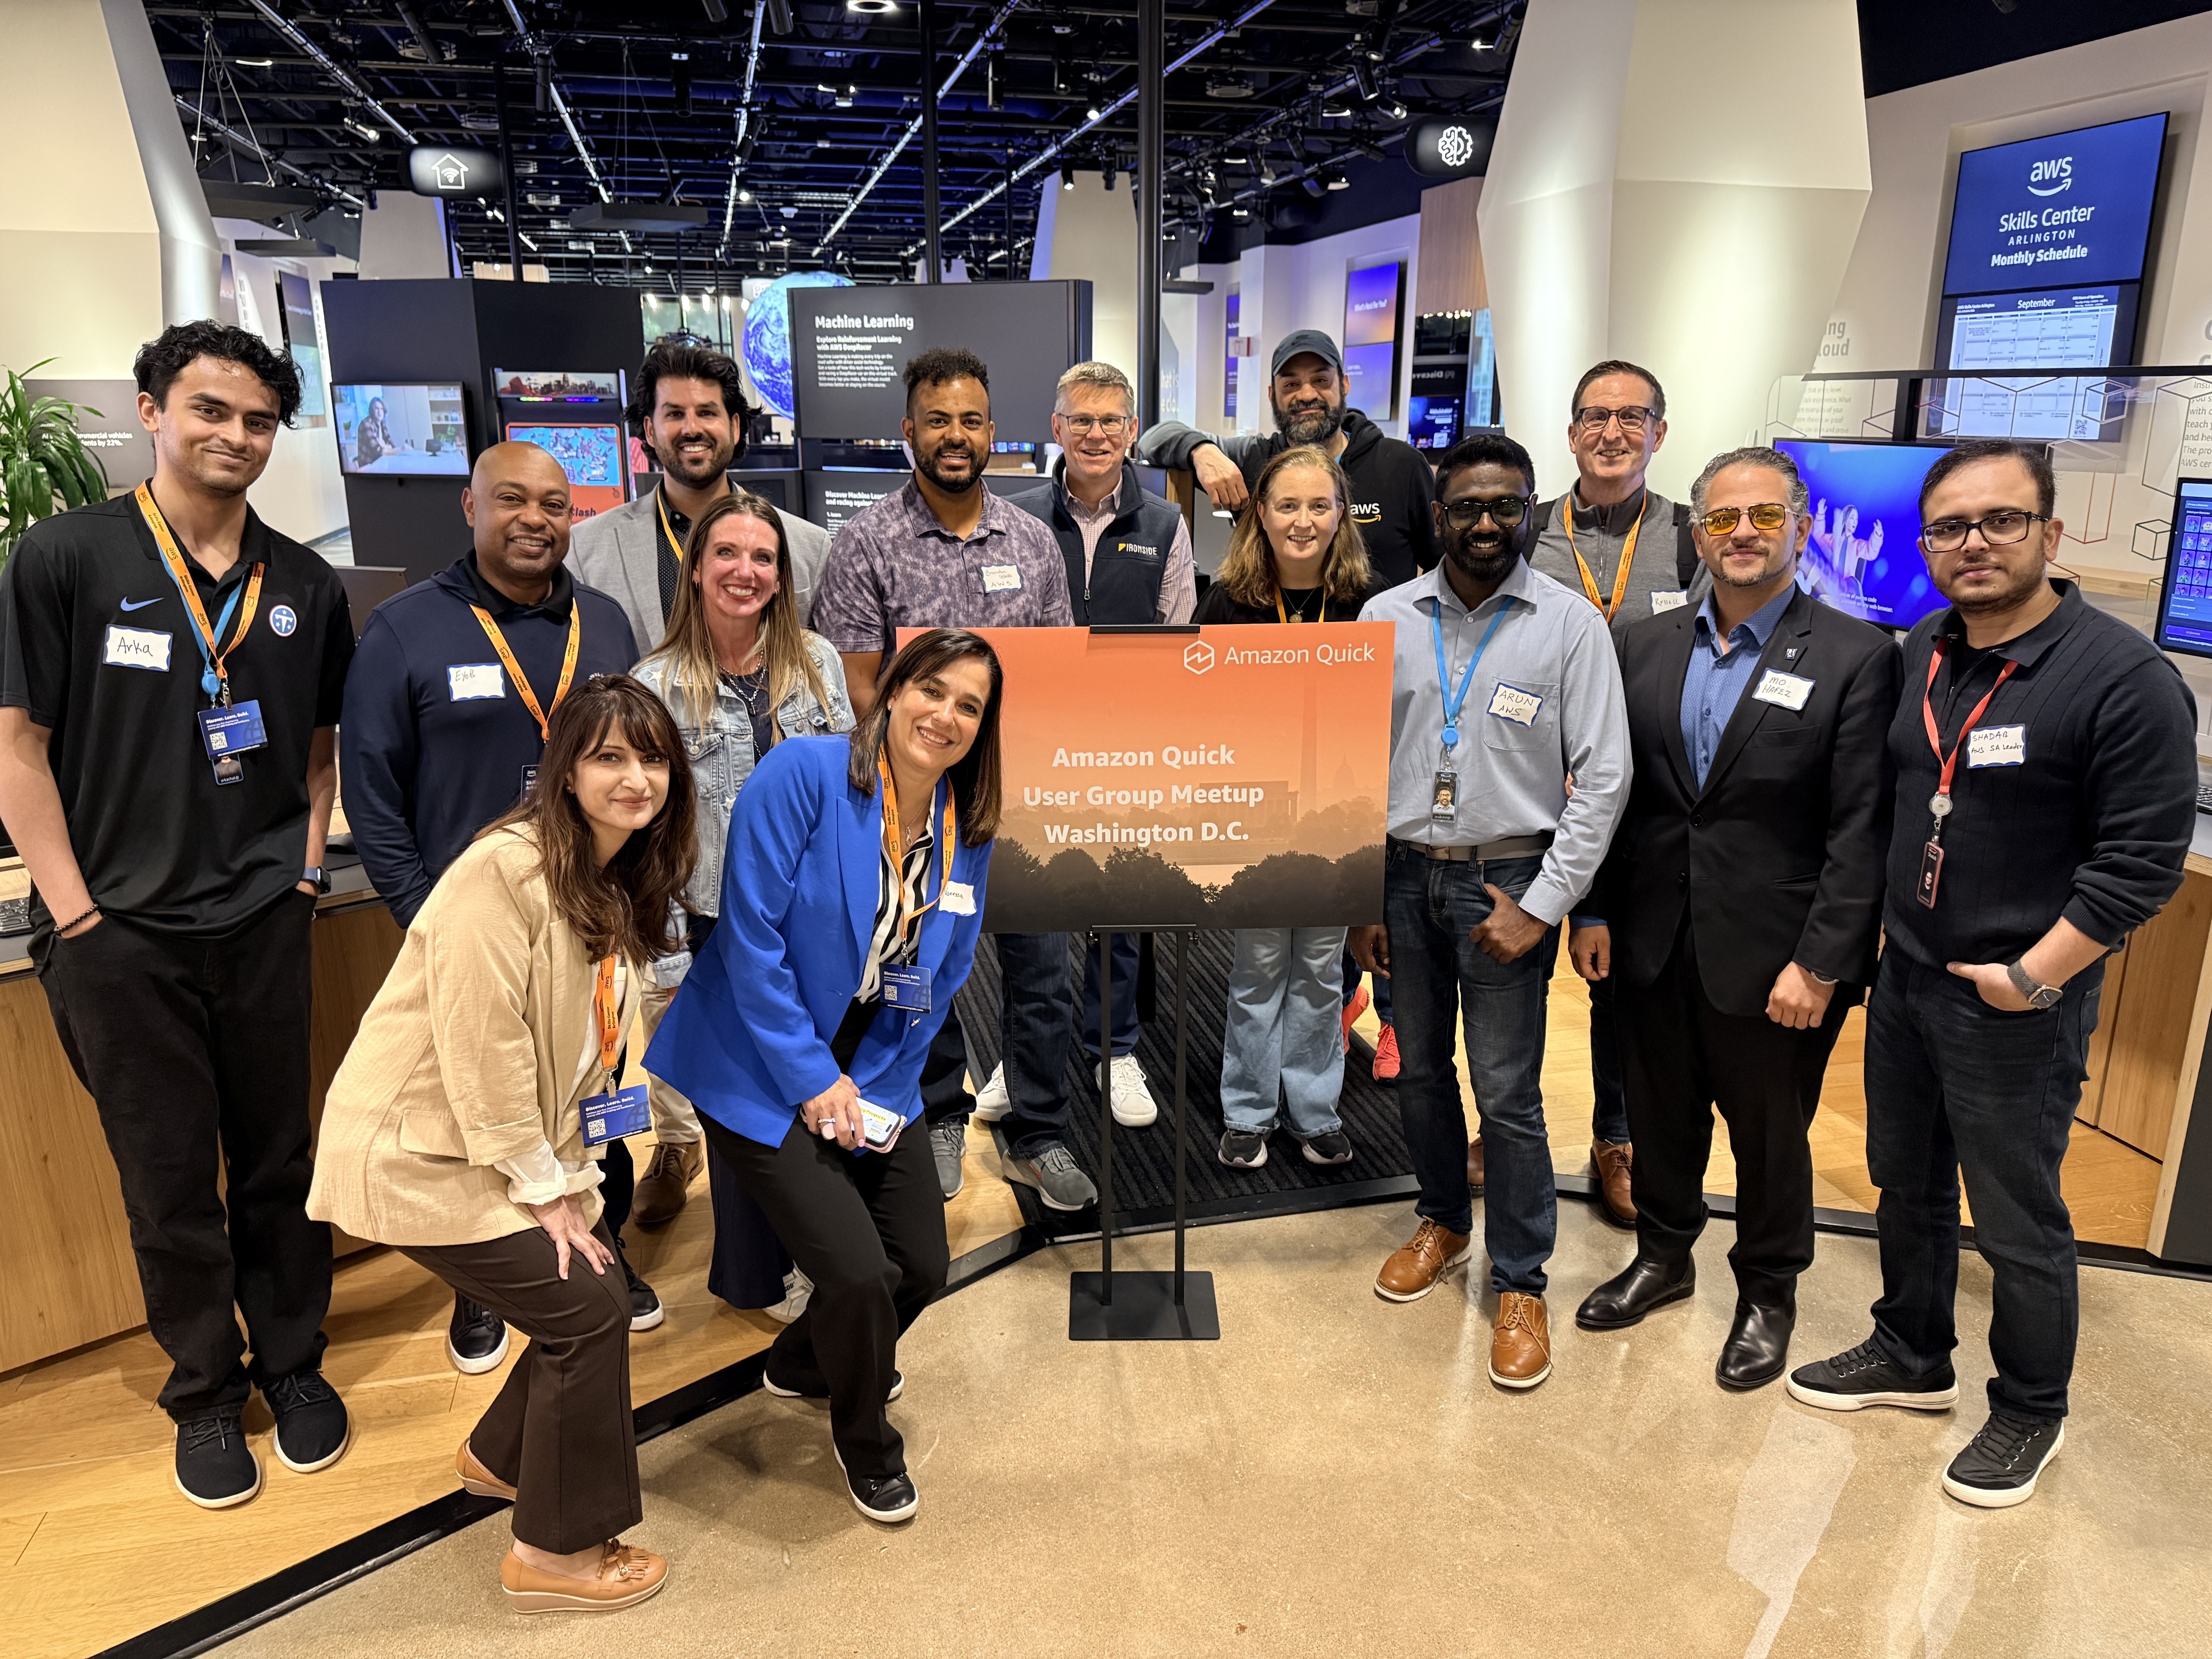
From reporting to reasoning: Getting enterprise data ready for AI agents

A recap of the inaugural AWS Quick User Group DC meetup, where data leaders explored getting enterprise data ready for AI agents. It covers what's new in AWS Quick, Financial Independence Group's AI analytics journey, and hands-on app and no-code flow building.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Vinay Arora SI

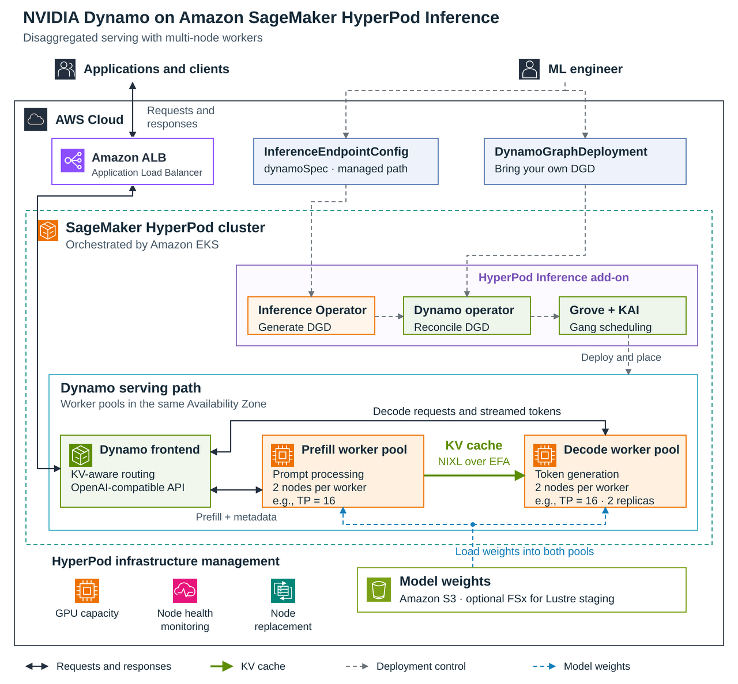
Managed NVIDIA Dynamo on Amazon SageMaker HyperPod Inference

Amazon SageMaker HyperPod Inference now supports NVIDIA Dynamo for distributed inference, with multi-node and disaggregated serving, KV-aware routing, and automatic fault recovery. Serve large models across many nodes without building the orchestration layer yourself.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Pallav Gupta SI

Reducing token costs and latency in Amazon Bedrock AgentCore JSON workloads

As production agents on Amazon Bedrock AgentCore process multi-megabyte JSON payloads, token costs and latency climb. This post shares three composable strategies: offloading heavy artifacts to Amazon S3, on-demand result paging, and dictionary compaction. Together they cut per-turn token use by up to 71% and latency by up to 80%.

Read at AWS Machine Learning Blog

Older stories