Results for “model”

arXiv (research papers) K. Shahzad

Genuine multipartite entanglement in ring-shaped Hubbard models

Spin states can be extracted from many-electron systems by detecting electrons at a set of lattice sites, which act as particle labels. Here we quantify the genuine multipartite entanglement (GME) of such spin states, which are generally mixed, in standard and extended Hubbard rings, together with the corresponding detection probability. We show that the on-site repulsion, by suppressing charge fluctuations, enhances the GME, and that in the strongly interacting regime at…

Read at arXiv (research papers)

Digital Trends Vikhyaat Vivek

Scientists taught AI to read lips in total silence, and the results are pretty impressive

Researchers at KAIST have developed a new AI system that reads lip movements without audio, using a diffusion language model to decipher ambiguous words and potentially improve communication in noisy environments.

Read at Digital Trends

Inc42 Shrishti Bisht Startups

Smartphone Price Hike: Samsung, Xiaomi Models Get Costlier By Up To ₹4,000 In India

Samsung and Xiaomi have increased smartphone prices by up to ₹4,000 across 48 variants in India amid rising memory chip…

Read at Inc42

arXiv (research papers) Kangwen Zhao SI

GainCtrl: Predicting Remaining Gains for Efficient LLM Agent Execution

Large language models (LLMs) are widely used to power agents that interact with tools and environments to solve complex tasks. Repeated attempts improve the quality of tool-using agents, but continued execution incurs additional costs even when it is unlikely to improve the best result ultimately returned. This raises the question of when to stop an attempt to reduce execution cost while preserving task-level Best-of-N quality. To address this question, we introduce…

Read at arXiv (research papers)

arXiv (research papers) Peng Liu SI

MemEmo: Evaluating Emotion in Memory Systems

Memory systems address the challenge of context loss in Large Language Models during prolonged interactions. However, as an essential tool for warm companionship and personalized services, the effectiveness of memory systems in processing affective information remains underexamined. To bridge this gap, we propose an emotion-enhanced memory evaluation benchmark to assess the performance of mainstream and state-of-the-art memory systems in integrating and harnessing emotional…

Read at arXiv (research papers)

arXiv (research papers) Ahmed Tariq Independent researcher SI

Routing Beyond Task Categories: A Cost-Aware LAB-Bench Study

We tested whether features of biology questions or of a model's first answer can improve accuracy within an inference budget. In a LAB-Bench pilot, we compared a category router with one that adds six structural features. Neither reached the primary 80% accuracy target on development. At the 50% and 60% secondary targets, both chose Haiku for all 120 held-out questions and scored 71/120. We then froze a new comparison before collecting responses on 144 additional questions…

Read at arXiv (research papers)

arXiv (research papers) Pier Mattia Basciano Security

A First Look at System One Decision Models for Malware Detection

Malware detection needs scores calibrated at a fixed false positive rate (FPR) and decisions an analyst can read: feature-based detectors give the first, large language models (LLMs) on decompiled code the second, through generated text of uncalibrated confidence. System One decision models answer a typed question about a text with a probability over its declared answers in one forward pass. We present the first evaluation of these models for Windows Portable Executable…

Read at arXiv (research papers)

arXiv (research papers) Haiteng Wang SI

IndustrialKnowEval: A Benchmark for Evaluating Multi-Level Industrial Knowledge in LLMs

Large language models (LLMs) are increasingly explored for industrial tasks, yet few benchmarks evaluate their mastery of industrial knowledge across different types of cognitive demand. We introduce IndustrialKnowEval (IndKnow), a benchmark for industrial knowledge and engineering question answering. It contains 43,282 samples covering 21 task types across seven industrial sectors, including aerospace, electric power, and metallurgy, organized into four levels of cognitive…

Read at arXiv (research papers)

Semiconductor Engineering Ed Sperling SI

Are AI Agents The New Semiconductor IP?

Agents are emerging as reusable design tools, but trust and use models remain challenging.

Read at Semiconductor Engineering

OpenAI News SI

Our first phase of embedded assessments

OpenAI begins embedded assessments with Apollo Research, METR, and Transluce, and Goodfire to independently evaluate model alignment, safeguards, and monitoring systems.

Read at OpenAI News

arXiv (research papers) Kai Tang SI

SpeCal: Spectral Calibration for Unsupervised RLVR

Reinforcement learning with verifiable rewards (RLVR) has substantially improved the reasoning abilities of large language models, but its dependence on ground-truth answers or external verifiers limits its ability to exploit abundant unlabeled reasoning data. Unsupervised RLVR alleviates this bottleneck by deriving scalar rewards from the model's own rollouts. However, the reliability of such self-generated supervision varies substantially across rollout groups and…

Read at arXiv (research papers)

The Hacker News Security

Amazon Uncovers AI Agent Campaign Targeting LiteLLM, Dify, and Other Apps for API Keys

Attackers' AI agents have been hunting for weak spots in internet-exposed AI apps such as LiteLLM, One API, and Dify to steal the AI provider keys stored inside, according to the agents' own records. The records, which Amazon's threat intelligence team captured with decoy servers, describe stolen keys being used to run the AI models that powered the search for more keys. The team said this

Read at The Hacker News

arXiv (research papers) Yongkang Xiao Security

MASTA: A Feedback-Scheduled Multi-Agent System for End-to-End Tamarin Modeling and Analysis

Tamarin-based formal verification of security protocols requires expert-authored multiset rewriting rules and temporal-logic lemmas. Translating a natural-language protocol description into a complete formal model with an LLM is hard because syntactic, reachability, and property-level errors compound across the multi-step modeling process, and a single agent that both authors and self-evaluates cannot reliably localize them. We present MASTA, a multi-agent system that…

Read at arXiv (research papers)

South China Morning Post Chong Ming Lee Geopolitics

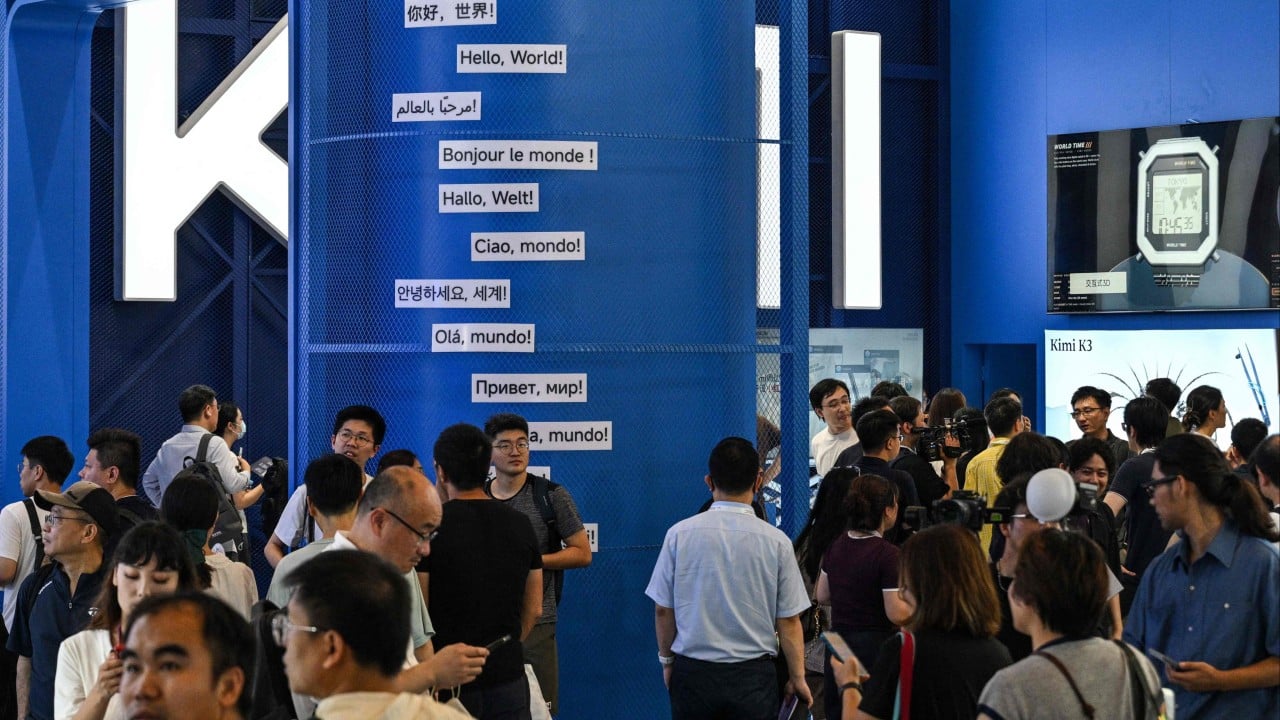
China’s Moonshot AI puts Kimi models into race for science discoveries

Chinese artificial intelligence start-up Moonshot AI, the developer of the Kimi models, is setting its sights on scientific discovery, joining US rivals in the race to turn AI into a research engine. The Beijing-based company is increasingly exploring applications that demand more advanced AI reasoning capabilities, pushing into the realms of biology, chemistry and pharmaceutical research. “The real excitement is … science,” said Giacomo Ficari, Moonshot’s director of…

Read at South China Morning Post

South China Morning Post Kyodo Geopolitics

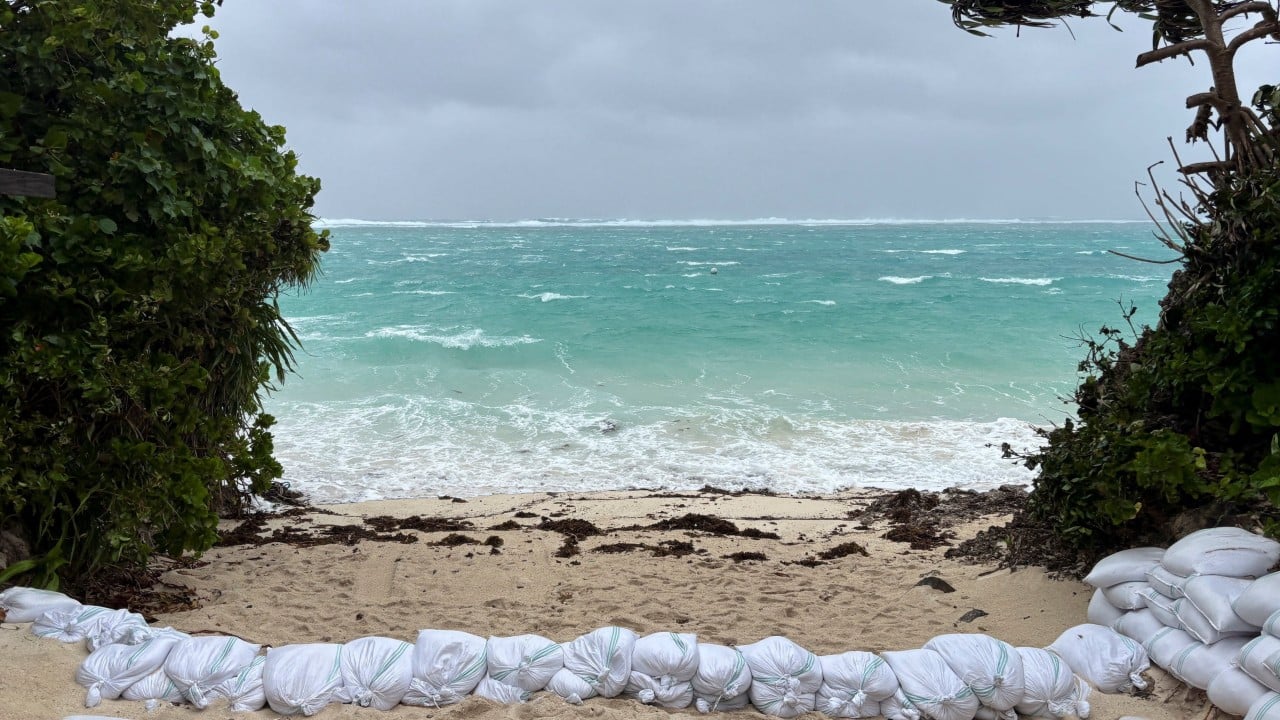
Japanese forecasters find AI beats traditional models at tracking typhoons

Artificial intelligence-based typhoon track forecasts in Japan are outperforming conventional physics-based models, with AI accurately projecting early on the path that last month’s Typhoon Champi would ultimately take. Private weather service Weathernews Inc has been using AI forecasts, while Japan’s weather agency is pursuing research and development towards their use. But experts say challenges remain, including forecasting typhoon intensity. Conventional physics-based…

Read at South China Morning Post

arXiv (research papers) Dong Lai Space

Magnetic Power in Binaries: From Coalescing Binary Neutron Stars to Close-in Exoplanetary Systems

A binary system containing two magnetic components ("stars") can be modeled as a circuit powered by the orbital motion, with the magnetic field lines linking the two stars serving as wires. When the total resistance in the binary components is small -- as found in many astrophysical systems such as binary neutron stars and extra-solar hot-Jupiter or super-Earth systems -- the connected field lines are twisted and open up in a quasi-cyclic manner, leading to quasi-periodic…

Read at arXiv (research papers)

arXiv (research papers) Michael Kingston SI

Instrumenting Failure: Scoring Language Model Agents at Every Decision Node in Imperfect-Information Games

Agent evaluations report task success and rarely say what an agent did at each decision. We score every decision node of three 12B to 14B instruct-tuned language models (LMs) playing five zero-sum imperfect-information games against four opponents on eight properties from decision and game theory, five of them against a CFR+ equilibrium reference. At each node, the LM also states a belief about the opponent's hidden state in a separate call. Without memory and at temperature…

Read at arXiv (research papers)

arXiv (research papers) Ruoxuan Shi SI

Safety-Preserving Medical LLM Fine-Tuning via Bilevel Data Selection

As general large language models (LLMs) are increasingly adapted for patient-facing medical applications, improving medical capability while controlling patient-facing risks remains a critical challenge. Large-scale medical instruction data are essential for acquiring domain knowledge through supervised fine-tuning (SFT), but unsafe responses can undermine existing safety alignment. To address this problem, we propose Scalable Bilevel Data Selection (S-BDS) for…

Read at arXiv (research papers)

arXiv (research papers) Angel Martinez-Sanchez SI

Instructions Before Actions: Prospective and Retrospective Language Supervision for Driving Vision-Language-Action Data

Driving vision-language-action (VLA) models can accept navigation instructions, yet predicting a driver's trajectory does not establish that a model follows the instruction. We study how driving-language supervision is collected and evaluated, distinguishing prospective instructions issued before an action from retrospective labels written after observing it. We develop ADVLAT-Engine to synchronize spoken instructions, road-scene video, and vehicle trajectories, and compare…

Read at arXiv (research papers)

arXiv (research papers) Linliang Chen SI

GEAR$^2$: Pruned Experts Live On through Gated Reuse of Activated Experts and a Missing-Mass Residual

Mixture-of-Experts (MoE) Large Language Models (LLMs) activate only a few experts per token while generally keeping all the experts in GPU memory for high efficiency. Expert pruning reduces this GPU memory footprint cost, yet discards the contribution of pruned experts. Existing remedies either rely on static substitutes, merge experts at the cost of altering their functions, or require costly recovery training. In this paper, we find that the functionalities of pruned…

Read at arXiv (research papers)

arXiv (research papers) Yuchen Fan SI

Newton-PINet: A fast physics-informed neural network with Newton linearization for meta-learning nonlinear PDEs

Scientific machine learning has opened new avenues for solving parameterized partial differential equations (PDEs), enabling models to learn a family of PDEs and generalize to unseen instances. In this context, data-driven operator learning methods typically require large training datasets, while physics-informed neural networks (PINNs) suffer from difficult optimization and limited generalization, especially for nonlinear PDEs. We propose Newton-PINet, a physics-informed…

Read at arXiv (research papers)

arXiv (research papers) Jizhou Guo Tech policy

Same Papers, Different Verdicts: Tracing Version Drift in LLM Peer Review

Venues and benchmarks read LLM review scores as measurements of a paper, while providers replace their models within months. We audit twenty frontier models from OpenAI, Google and Anthropic on ICLR 2027 submissions while they were under review, with tests registered before the decisions. Between an earlier and a later version of Claude Opus and of Gemini, the share of papers placed on the accept side falls by 52 and 53 percentage points on 183 and 60 randomly drawn…

Read at arXiv (research papers)

arXiv (research papers) Aspen Wang Tech policy

Necessary for What? Auditing Demographic Disclosure to LLM Synthetic Respondents

Large language models (LLMs) increasingly answer surveys on behalf of real panelists, and each panelist's recorded demographic attributes (e.g., age, education, ethnicity) are often placed in the prompt on the premise that richer profiles make more faithful synthetic respondents. While data minimization limits personal data to what a purpose requires, a synthetic survey serves several purposes at once, from predicting individual answers to estimating how opinions are…

Read at arXiv (research papers)

YourStory Startups

Ola Electric hands the keys to dealers. What led to this shift in gears?

For long, Ola Electric ran its own showrooms and sold directly to customers. Now it is shifting to a dealer-led model with plans to have 700 dealer stores by March 2027. What prompted this reset and what should the company get right for it to work?

Read at YourStory

arXiv (research papers) Senquan Wang SI

BiGSyn: A Bi-Level Heterogeneous Graph Contrastive Learning Framework for Interpretable Drug Synergy Prediction

Drug combination therapy has become a mainstream of modern medicine, with the potential to enhance efficacy, reduce toxicity, and overcome drug resistance. However, identifying synergistic drug combinations remains challenging, as it requires modeling complex interactions across multiple biological scales---from atom-level molecular structures to entity-level relations in biological networks. Existing approaches typically model these levels in isolation, overlooking…

Read at arXiv (research papers)

Inc42 Ankush Das Startups

AI Startups To Watch: 5 Startups That Caught Our Eye In November

AI in India has moved past the phase of picking a single large language model. For two years, the loudest…

Read at Inc42

arXiv (research papers) Jun Wu SI

Language Models Meet Vibration Testing for LEO Constellation Satellites with Calibrated Response Prediction from Few-show Sweeps

Large language models (LLMs) increasingly drive engineering analysis end to end, turning textual records into the inputs of numerical programs, but a plausible and wrong value can pass silently into a decision. We propose deterministic validation gates for LLM-driven engineering analysis, a general paradigm in which a typed configuration produced by LLMs is consumed only after it passes deterministic checks on units, physical consistency, verbatim quotes, agreement between…

Read at arXiv (research papers)

arXiv (research papers) Ke Shen SI

ToolGraph as a Q-Function for Test-Time Scaling of Tool-Use Agents

Tool-use agents must chain interdependent calls, yet which outputs satisfy which later inputs in a deployed catalog is not something a general-purpose language model reliably infers from tool descriptions alone. We compile that structure once into a reusable external representation. ToolGraph is a directed, weighted dependency graph over a tool catalog: parameter matching and interventional probes, which execute a candidate chain with and without its proposed predecessor…

Read at arXiv (research papers)

arXiv (research papers) Makoto Sato SI

Weight-Space Programming Changes How an LLM Uses Python for Computational Biology

Weight-space programming allows a language model to edit another model's weights without gradient-based training. We used Claude Opus 5.5 to edit Qwen3.5-0.8B and investigated how the edits changed its use of Python on computational biology problems. We compared four initial edited checkpoints with the original model on 50 test problems across three test seeds, yielding 600 paired evaluations. Strictly correct answers increased from 44 to 77, and technically correct answers…

Read at arXiv (research papers)

arXiv (research papers) Saksham Gupta SI

Memory-Efficient Speculative Decoding with Quantized Draft KV Cache

Speculative decoding reduces generation cost, but it stores two KV caches: one for the target model and one for the draft model. We reduce this extra memory by quantizing the draft cache. The target cache and verifier remain in BF16, so that compression cannot change the target model's final correction rule. We first study how to divide precision between keys and values. A naive per-token quantizer makes keys appear much more sensitive: splitting a 12-bit budget, K8V4 beats…

Read at arXiv (research papers)

Older stories