Results for “models”
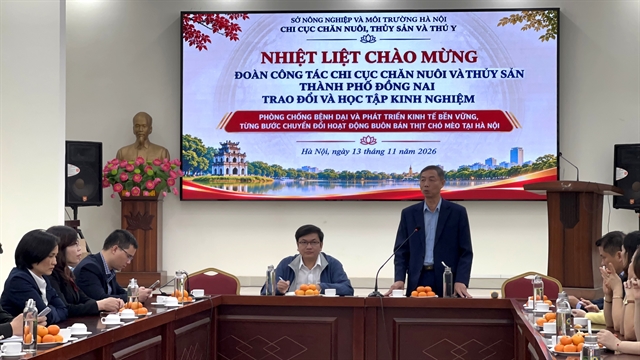
Đồng Nai studies rabies prevention and livelihood transition models in Hà Nội
Hà Nội's approach follows the One Health direction, including addressing the risk of rabies transmission at its source while ensuring livelihoods for local people, contributing to the national goal of no human deaths from rabies by 2030.
Learning Optimal Transport Plans Via Autoregressive Token Regression
Optimal Transport (OT) provides a principled framework for finding the minimum cost coupling between probability distributions. Classical solvers remain the gold standard for this task. At the same time, OT is an ideal testbed for studying whether learning-based amortized models can internalize the structure of OT type problems. Here, ground-truth solutions are available and marginal constraints are explicitly defined. Also, exact discrete solutions have well-characterized…
Communicate the Change: Efficient Expert Parallelism via Activation Compression
Scaling has driven the success of large language models (LLM), with sparse mixture-of-experts (MoE) architectures enabling greater parameter capacity without a proportional increase in computation. At large scales, MoE models rely on expert parallelism to distribute experts across devices. Each MoE layer requires two synchronous collective communication steps during inference: dispatching hidden states to the activated experts and combining the resulting expert outputs. As…
EGS: A Complementary Safety Framework for Educational LLMs
Large Language Models (LLMs) offer strong potential for personalized education, but adolescent-facing deployment raises risks of toxic, biased, misleading, or developmentally inappropriate content. We argue that educational safety should move beyond binary refusal: student queries are often ambiguous or curiosity-driven, requiring contextual guidance rather than simple blocking. We introduce the Educational Guardrail System (EGS), a lightweight, model-agnostic runtime…
Is 4-Bit Quantization More Than Noise to a Chat Model's Safety Behaviour? Attributing Behavioural Shifts with Matched Perturbations
Chat models on phones and laptops are usually 4-bit copies of the model that was evaluated, and audits of such copies disagree about what quantization does to refusal. A 4-bit build is one of many weight perturbations of the same size, so a change in its behaviour could come from its specific rounding error or from any perturbation that large. In a pre-registered study of three 3-4B chat models, with paired tests, blind human labels and an 8-bit null, we find two 4-bit…
CueClash: Frontier Vision-Language Models Judge 3-D Relations Close to the Picture Plane
A vision-language model (VLM) can judge 3-D relations from the picture or from the ground layout. In photographs the two usually agree. We separate them with CueClash, rendered scenes in which the 2-D cue for each of five relations is right on exactly half the statements. The shortcut gap is accuracy when the cue is right minus accuracy when it is wrong. For Claude Opus 5.5, GPT-5.5 and Gemini 3.6 Flash at low reasoning effort it is +18 to +37 percentage points. It is +7 to…
CorrectCast: Selective Multimodal Context for Scale-Aware Residual Correction in Precipitation Nowcasting
Precipitation nowcasting models suffer from errors in intensity, location, and spatial structure. Addressing these errors by retraining nowcaster backbones can be computationally expensive and requires architecture-specific modifications. To overcome these limitations, we propose CorrectCast, a decoupled residual correction framework that refines completed nowcasts while keeping the base nowcaster frozen. By operating on predicted precipitation fields, CorrectCast requires…
Baidu AI cloud infrastructure revenue jumps 94% in Q3
At Baidu World 2026, the company launched Ciyuansuo, a marketplace for large models.
He Left Accenture to Build an Embedded SLM—Now It Ranks Among the World’s Best
Anuj Gupta founded KiteFishAI to develop compact language and embedding models for enterprise applications, AI governance, and multimodal technologies.
Reconfiguring Procedural Knowledge for Compositional Robot Skill Adaptation
General-purpose behavior models increasingly internalize broad procedural knowledge during training, making their adaptation to new goals and skill interfaces less a problem of learning entirely new behaviors than of reconfiguring existing competence. We study this capability as reconfigurability, the ability to realize new behaviors by cost-efficiently restructuring existing components and relations under sparse governing information, where task specifications provide…
Menlo Ventures leads $110m round for AI startup Noeri
The idea grew from helping a Stanford microbiology team use OpenAI models more cheaply.
Long-Context Generation Is a Sampling Problem (When You Turn Up the Heat)
Open-weight language models are widely observed to get worse the longer they generate. Often, attempts to fix this involve more training. At high temperature, The sampler, i.e. the rule that picks the next token out of the model's probabilities, decides whether long and agentic generation survives and/or thrives. We test 29 open-weight models from 1B to 122B parameters on ten established benchmarks plus needle retrieval out to one million tokens, covering SWE-bench Verified…
LoCaR: Localized Canvas Retrieval With Frozen Vision-Language Model
Whole image embeddings can under represent small objects and local attributes that distinguish relevant images for localized queries. We present LoCaR, a training free framework for localized text to image retrieval with frozen vision language models. LoCaR constructs and utilizes independent proposals (SAM2) focusing on the object so as to get a more localized representation that independently encodes each region using the frozen visual encoder. We further study…
TeleChat to Xing4: Advancing Frontier Agentic Models on Domestic Chips and Frameworks
We present Xing 4, a series of large language models that extends the TeleChat lineage through coordinated advances in model architecture and training infrastructure on Ascend. This report describes the design principles and systems engineering behind the series, spanning architecture selection, large-scale pretraining, and reasoning and agentic post-training. We study how sparse activation, attention design, model depth and width, and speculative decoding balance model…
From Sorry to QED: Refining LLM Math Proofs via Angelic Execution
Large language models (LLMs) can now generate Lean proof scripts that capture the high-level structure of many mathematical arguments. However, these scripts frequently fail on complex theorems: a single missing side condition or misapplied lemma can cause the prover to abort early and discard an otherwise viable proof outline. This paper presents MathEye, a framework that converts imperfect LLM-generated proof scripts into fully verified Lean proofs by combining symbolic…
When AUC Meets Generative Reconstruction: A Unified Principle for Balanced Visual Representation Learning
Multimodal large language models (MLLMs) require visual encoders that extract fine-grained visual features while constructing semantically disentangled and discriminative representations. Conventional methodologies encounter a fundamental trade-off: contrastive learning enhances inter-class discrimination by suppressing intra-class variability, whereas generative reconstruction emphasizes perceptual fidelity but lacks explicit comparative supervision. The naive aggregation…
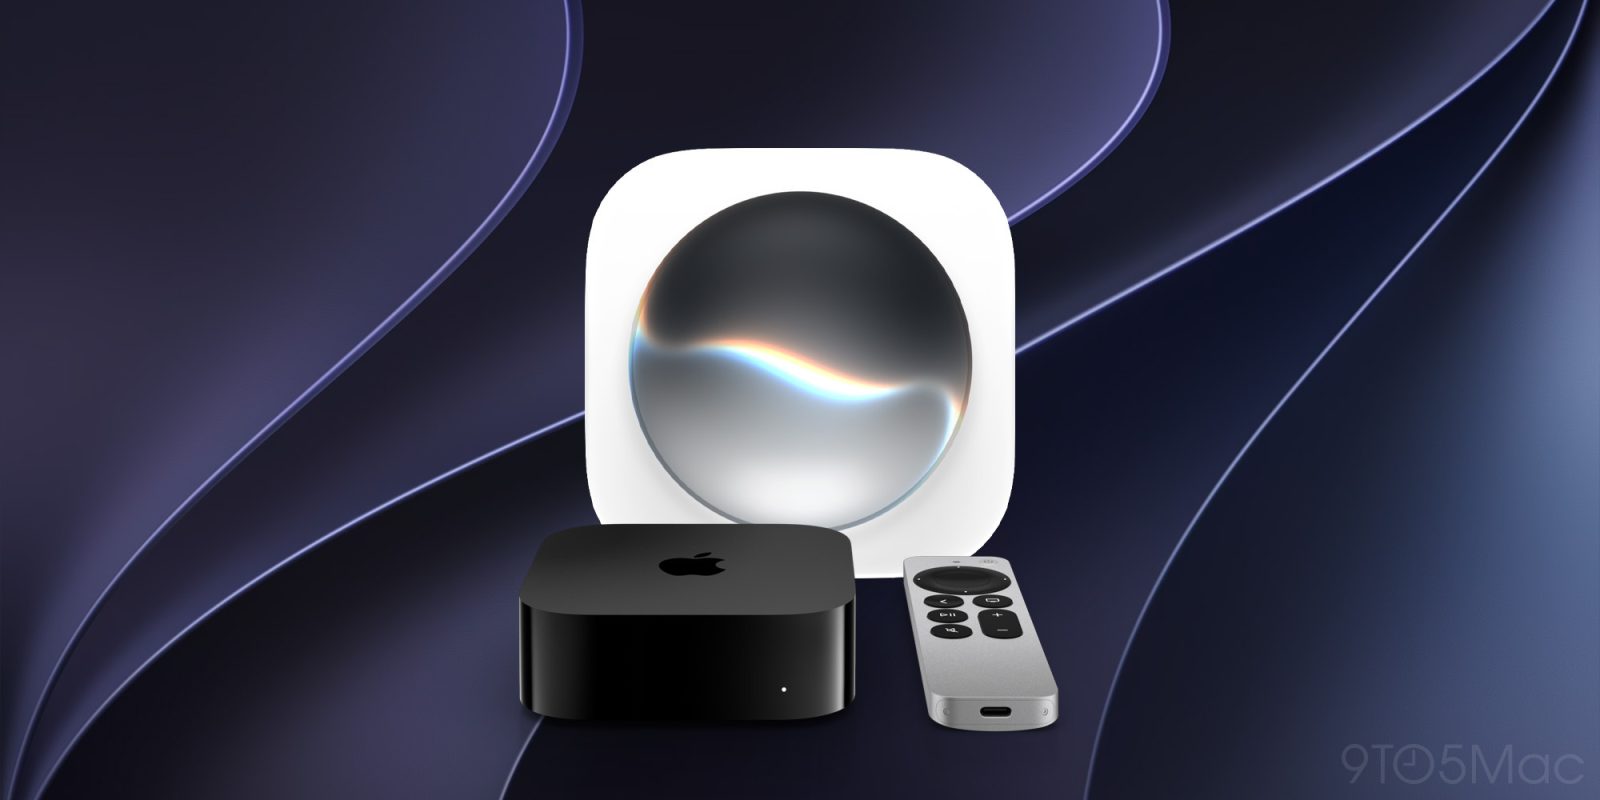
tvOS 27.3 beta 2 brings Siri AI to Apple TV beta testers
Following the rollout of Siri AI to select Apple TV models with tvOS 27.2.1, Apple today expanded availability to users running the tvOS 27.3 developer beta. Here are the details.
QCap: a physics-corrected graph neural network for the capacitance matrix of any planar superconducting device layout
Electromagnetic simulations of device layouts to extract capacitance are computationally intensive, a major obstacle to accurate design of circuit devices. Machine learning models can bypass these simulations, but previous approaches have been restricted to layouts using only particular components, and require thousands of simulations of those same components as training data. We present QCap, a model that accurately predicts the Maxwell capacitance matrix of an arbitrary…
Thinking Harder Doesn't Lead to Better Choices: Reasoning Effort Increases the Confidence but Not the Correctness of LLM Shopping Agents
Large language models (LLMs) are increasingly deployed as autonomous shopping agents that process multimodal product listings (consisting of visual and text data) and recommend purchases on behalf of consumers. Naturally, one might assume that models with more thinking power would make higher-quality purchasing decisions. To test this belief, we ask two questions about such agents: does asking a model to think harder make it choose better products, and does the confidence it…
Reducing High-Bandwidth Flash Latency In GPU Systems (Georgia Tech, Nvidia, Stanford)
Researchers at Georgia Tech, NVIDIA Research, and Stanford University published “SlipStream: Enabling HBF for GPU Systems by Mitigating the Latency and SRAM Overheads.” Abstract Excerpt “Large language model (LLM) inference demands ever more memory capacity for larger models and batch sizes. High-Bandwidth Flash (HBF) replaces the DRAM dies of HBM with NAND flash and provides... »
Spatial effects and mechanisms of the digital economy’s impact on agricultural carbon emissions
To explore the spatial effects and mechanisms of the digital economy in promoting low-carbon agricultural transformation, this paper measures digital economy development and agricultural carbon emissions based on panel data for 31 provinces in China from 2011 to 2023, and analyzes their spatial distribution characteristics. Spatial Durbin and mediating models are employed to investigate the effects and mechanisms of the digital economy on agricultural carbon emissions. The…
Hierarchical Personalized Federated Learning for Fine-Grained Intrusion Detection: A Multi-Class Analysis in Heterogeneous Attack Environments
Intrusion Detection Systems (IDS) play a vital role in protecting modern network infrastructures. Although Federated Learning (FL) enables collaborative training without sharing raw network traffic, global models struggle with non-IID attack distributions. Moreover, practical security operations require fine-grained attack classification for targeted threat responses. To address these challenges, this paper investigates the convergence dynamics and performance of…
Eight in Ten LLMs Leak System-Prompt Secrets: Nevan, an Agentic Capture-the-Flag Study
We audit instruction-hierarchy enforcement across 363 text-in/text-out models from the OpenRouter catalog. The research question we answer with this experiment is which models disclose a protected secret embedded in the system prompt, and through which techniques. Each model guards a secret 16-character flag set in its system prompt, while an artificial intelligence (AI) agent (OpenCode, powered by DeepSeek V4.1 Flash), steered by a human researcher, tries to persuade it to…
PersonaHate: A Scalable Persona-Based Data Synthesis Pipeline for Hate Speech Analysis
Hate speech remains a persistent and evolving threat on online platforms. The widespread use of large language models (LLMs) further intensifies this problem by making hateful content easier and cheaper to generate at scale. Although stronger hate speech detectors continue to be proposed, their performance remains uneven across target identity groups and different forms of hateful expression, partly because existing training data provides only limited coverage of these…

California attorney general sues OpenAI over alleged safety failures
California Attorney General Rob Bonta (D) on Monday sued OpenAI for allegedly placing public safety at risk with its advanced AI models, claiming it had no guardrails to prevent the breach of technology startup Hugging Face. Two autonomous AI agents from the tech company were being evaluated in an internal testing sandbox before they went...
Simplifying models of noisy stabilizer QEC on leakage qubits by Pauli twirling
The growing capabilities of quantum error-correction (QEC) experiments make it increasingly important to develop methods that predict or assess logical performance over many QEC cycles. Prior work has shown that a stabilizer QEC cycle subject to Pauli-stochastic noise can be modeled by a classical Markov process over syndrome states, with a logical Pauli channel attached to each syndrome transition. Here, we extend this framework to systems in which physical qubits are…
Wrong Input, Wrong Threshold: Re-evaluating Adversarial Facial Privacy
Published face-privacy methods report protection above 90% against black-box recognition models. That number comes from an evaluation protocol with two independent defects, reported in a measure that cannot size either one. The input is wrong: methods published since 2022 feed the network the whole photograph, or a detector's box, where deployed systems detect, align to a landmark template and crop. Re-scoring the same files through a realistic front end costs a standard…

Cuba’s Communist Allies in Asia
China, Vietnam, and North Korea offer more than diplomatic support against U.S. pressure – they offer different models for keeping one-party rule intact.
Knowing Which, Not How Much: Language Models Order Party Positions They Cannot Place
Language models are increasingly asked where real actors stand: what a party's platform prioritises, what an institution has committed to. Such judgments are gradable, carrying both an order and a magnitude. Nearly every benchmark that tests them asks about one entity at a time, then reads that score as the model's knowledge of the domain. Order and magnitude, however, need not be acquired together. Text about social entities carries far more comparison than measurement, so…