Results for “model”

arXiv (research papers) Zhihao Liu Security

Ask in the Crowd: Differentially Private LLM Inference via Dummy-Augmented Shuffling

Large language models are increasingly deployed as LLM-as-a-Service (LLMaaS), where user queries are sent to remote LLMs for inference, raising severe privacy concerns about the exposure of sensitive user inputs. Differentially private inference mitigates these risks by injecting noise into input embeddings. However, existing methods struggle to balance privacy and utility, as stronger privacy protection often leads to substantial accuracy degradation in LLM inference. In…
Read at arXiv (research papers)

arXiv (research papers) Xu Pan

CauSyncVLA: Causal Latent World Modeling for Asynchronous Robot Control

Vision-Language-Action (VLA) policies must react while visual inference is still running. Overlapping computation and execution reduces waiting, yet leaves perceptual memory stale and successive action chunks disconnected. We present CauSyncVLA, an asynchronous dual-system controller that aligns perceptual-memory prediction and trajectory correction with actual robot execution. Rather than forecasting pixels or physical states, a Causal Latent World Model predicts current…

Read at arXiv (research papers)

arXiv (research papers) JiaXu Chee

GNetSS: Towards Learning GNSS Corrections without Ground Truth

We present GNetSS, a self-supervised GNSS position correction framework that improves the robustness of single point positioning (SPP) without requiring ground-truth locations for training. GNetSS combines a transformer-based network with a deterministic differentiable positioning solver. The network predicts satellite-wise pseudorange corrections by modelling inter-satellite geometry and temporal context, while the solver converts these corrected measurements into receiver…

Read at arXiv (research papers)

arXiv (research papers) Sikha Pentyala Security

GPU-Accelerated Secure Inference for Drug--Target Interaction Prediction

Deep learning models that predict drug--target interactions (DTI) can speed up drug discovery, but the candidate drugs they score are valuable intellectual property that their owners cannot reveal. Secure multiparty computation (MPC) lets two servers compute a prediction on a secret-shared drug, without either server learning the drug. However, secure inference of deep models is slow. Non-linear operations require communication between the servers, and MPC arithmetic does…

Read at arXiv (research papers)

arXiv (research papers) Jingyi Zhou

GRODE-RTL: Source-Mapped Dependency Views for LLM-Based RTL Repair

Large Language Models show great potential for automated Register-Transfer Level repair, yet they struggle with non-local faults where root causes and failing outputs reside far apart in source code. Treating RTL as a flat token sequence obscures hardware dataflows, whereas exposing complete synthesized graphs overwhelms the model with fine-grained metadata. To resolve this representation dilemma, we propose GRODE-RTL, an anchor-centric representation that extracts the…

Read at arXiv (research papers)

MarkTechPost Asif Razzaq SI

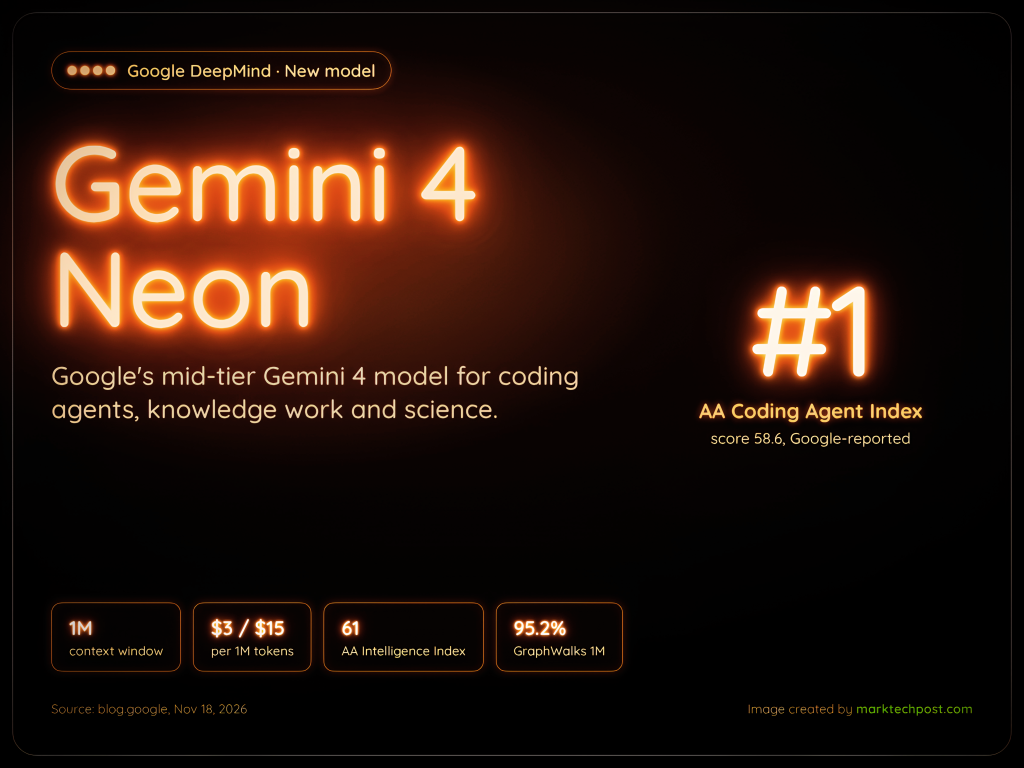
Google DeepMind Releases Gemini 4 Neon: 1M Context, #1 on AA Coding Agent Index

Google released Gemini 4 Neon, a 1M-context Gemini 4 model priced at $3/$15 per million tokens. It scores 61 on the AA Intelligence Index and ranks #1 on AA’s Coding Agent Index.

Read at MarkTechPost

arXiv (research papers) Anh Dao

LoopedWAM: Looped World Action Models for Elastic Inference

World action models (WAMs) couple generative video modeling with robotic action prediction but typically require large video and action transformers, limiting deployment efficiency. We present LoopedWAM, a compact WAM that recurrently applies a shared six-block core in each expert, executing 30 transformer layers while storing only 12 blocks per expert. To account for their asymmetric inference costs, the video and action experts can operate at different depths: visual…

Read at arXiv (research papers)

arXiv (research papers) Farhan Latif Tech policy

AI-Driven Transformation of Digital Platform Work: A Task-Based Model for Measuring Labour Disruption and Vulnerability, with Early Evidence from Online Freelancing in Kenya

Assessments of AI's impact on labour often rely on conventional occupational categories or broad market indicators. This dominant trend, however, obscures how tasks within the same occupation vary in practice across work arrangements. This limitation is particularly important in online freelancing, where workers are typically remote and devote substantial time performing unpaid tasks. This article introduces a task-based framework that distinguishes AI-driven disruption…

Read at arXiv (research papers)

arXiv (research papers) Yuseon Choi

FlashX: Scaling Robotic Experience Reuse for Embodied Agents with CBA-Based NAND Flash

Embodied agents are emerging as a promising paradigm for complex robotic tasks, leveraging Vision-Language-Action (VLA) and World Action Models (WAMs) to generate actions through Diffusion Transformer (DiT)-based iterative denoising. However, existing models often struggle to generalize to out-of-distribution (OOD) environments. We observe that retrieving successful experiences and using them to warm-start denoising enables agents to better adapt to unfamiliar situations…

Read at arXiv (research papers)

The Guardian World Peter Walker Senior political correspondent

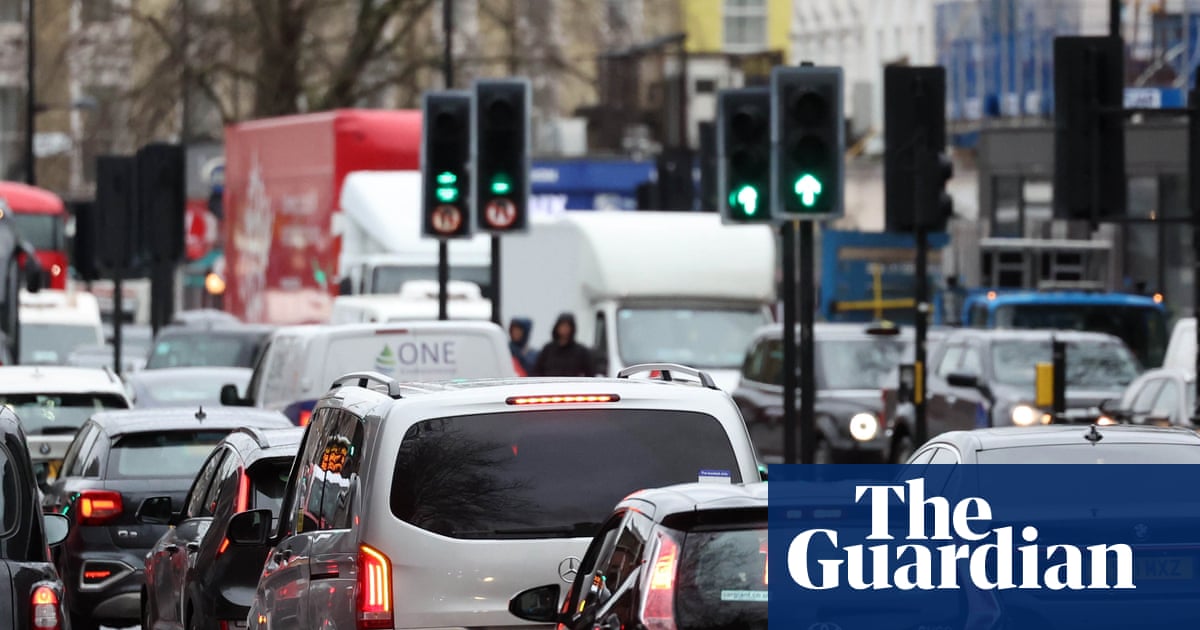
Car use in London forecast to rise by 10% in next decade

Modelling in draft of 10-year London plan threatens Sadiq Khan’s promises on improving air quality Car use in London will rise by 10% over the next decade with cycling and walking falling as a proportion of trips, according to an official forecast by the city’s mayoralty, putting into doubt Sadiq Khan’s promises on air quality and the environment. Based on projections in the draft version of the latest 10-year London plan, drawn up by the mayor’s office and Transport for…

Read at The Guardian World

YourStory Startups

Bajaj Finserv and Pennant invest $4 million in Indian AI startup Soket AI

Bajaj Finance and Pennant Technologies are backing Soket AI with investments of around $2 million each to advance its homegrown foundation models and enterprise AI solutions.

Read at YourStory

Digital Trends Dwayne Cubbins

Google releases Gemini 4 Neon AI model, rivals Claude Opus 5.5 and GPT-6.2 Sol

Gemini 4 Neon is now in the Gemini app for Google AI Pro and Ultra subscribers. Google says the mid-tier model scores 61 on a major index, ahead of Claude Opus 5.5 and GPT-6.2 Sol in its own tests.

Read at Digital Trends

arXiv (research papers) Vladislav Marinov Tech policy

Coordinated Use of Large Language Models in Academic Research

This study proposes a methodological framework for the coordinated use of multiple large language models in academic research. Its central argument is that involving more models does not in itself guarantee more reliable results; what matters is how cognitive and verification operations are organised. The framework is based on seven principles (procedural independence, functional allocation, the diagnostic value of divergence, the diagnostic value of convergence, external…

Read at arXiv (research papers)

arXiv (research papers) Almene De Meran Meguimtsop SI

Why Do LLMs Help with Scientific Misconduct Requests and What to Do About It?: Increasing the Trustworthiness of AI for Science

Large language models (LLMs) support scientific research, but some of that assistance can also undermine research integrity. Existing safety evaluations in science often measure whether models refuse misconduct requests, but rarely explain whether they even recognize the problem or why they comply. We investigate this gap across 8 LLMs using SciIntBench, an existing benchmark of 1,350 prompts about scientific research integrity. We examine the reasons behind compliance in…

Read at arXiv (research papers)

arXiv (research papers) Ahmet Tuğrul Bayrak SI

When Should a Voice Agent Speak? End-of-Turn Detection in Turkish

A voice agent that waits for a fixed silence before replying either interrupts users who pause mid-utterance or responds late to users who have finished. This study examines the decision at the onset of silence, using turn ends and turn-internal pauses extracted from the Real-TurnTurk corpus of Turkish dyadic video calls. A fine-tuned Turkish TurnGPT model, a zero-shot Turkish language model and a deployed multilingual detector are compared, together with voice-activity…

Read at arXiv (research papers)

Tech in Asia Grace Priscilla Teo Startups

Alibaba Cloud deepens Malaysia push with 6th data center

Alibaba Cloud also said it unveiled its Qwen4-Max AI model at the event.

Read at Tech in Asia

arXiv (research papers) Bo Li SI

WeightCode: Installing New Capabilities into Neural Networks via Weight-Space Programming

Neural networks encode learned capabilities in their weights, yet extending those capabilities with explicit task knowledge remains a fundamental challenge. Here we show that Weight-Space Programming (WSP), in which executable programs read, construct or modify a network's weights directly, can install new capabilities within trained neural networks. WeightCode, a WSP framework, uses a frozen language model to write executable weight programs that install new computations…

Read at arXiv (research papers)

arXiv (research papers) Younghwan Joo SI

A four-level executable validation protocol for evaluating LLM-generated topology specifications of physics-based HVAC digital twins

Physics-based digital twins of air conditioning, a principal energy consumer in manufacturing and buildings, can be generated automatically from a declarative specification of its equipment, connections, and sizing. Large language models (LLMs) now write such specifications from plain-language descriptions. Evaluations of these specifications stop at parse success, completed runs, or textual similarity, and cannot reject a model that converges in simulation but is physically…

Read at arXiv (research papers)

arXiv (research papers) Zihao Dan Security

ToolPulse: Side-Channel Eavesdropping on Tool-Using LLM Agents

Large language models (LLMs) are increasingly deployed as agents that translate user requests into sequences of local tool invocations. While prior cache-based side-channel attacks target the locally deployed models, they typically require the adversary to share model-related components or hardware resources with the victim's inference process. These assumptions do not apply to the predominant agentic settings, in which commercial LLMs execute on vendor-controlled…

Read at arXiv (research papers)

arXiv (research papers) LoongForge Team SI

LoongForge-Embodied: A Unified Framework for Training Heterogeneous Embodied Models

Training Vision-Language-Action (VLA) models and World-Action Models (WAMs) is computationally expensive, while their heterogeneous architectures and fragmented training stacks make system optimizations difficult to reuse across models. To address these challenges, we present LoongForge-Embodied, a native-PyTorch framework that unifies and accelerates the training of heterogeneous embodied models. At its core, LoongForge-Embodied introduces a common abstraction layer that…

Read at arXiv (research papers)

SecurityWeek SecurityWeek News Security

Palo Alto Networks to Buy AI Startup Applied Compute for $4.5 Billion

The all-stock deal will give the cybersecurity company a platform for fine-tuning and running open-weight AI models in public and sovereign clouds.

Read at SecurityWeek

arXiv (research papers) Qishu Hu SI

Raptor: Rejection-aware Adaptive Tree based on Speculative Decoding

Tree-structured speculative decoding accelerates vision-language models (VLMs) by verifying multiple candidate continuations in parallel. However, long visual contexts increase the cost of speculative computation, making candidate coverage and redundant expansion important considerations beyond tree topology adaptation. We propose Raptor, a training-free framework that uses rejection feedback to jointly regulate candidate coverage and drafting effort. Our key insight is that…

Read at arXiv (research papers)

arXiv (research papers) Li Zeng Security

VisualJevBench: A Benchmark and Black-Box Attacks for Visual Typed Decision Models

Typed decision models (TDMs) return structured decisions instead of generating free-text responses, enabling fast and cheap decisions in real-world applications. Recent support for image inputs extends Jev, a representative TDM, to visual decision-making. We refer to this setting as Visual Jev. However, red teaming of Visual Jev leaves two gaps: a systematic evaluation of direct image manipulations is lacking, and universal visual attacks remain underexplored. To address…

Read at arXiv (research papers)

arXiv (research papers) Zhengbo Zhou SI

Bilateral Evidence Selection and Reasoning for Mammography Vision--Language Models

Medical vision--language models (VLMs) often need to identify small, subtle lesions within high-resolution images containing extensive normal anatomy and redundant visual information. Visual-token compression improves efficiency, but preserving salient regions alone can discard the context needed for diagnostic interpretation. This context can extend across images: in bilateral mammography, the opposite breast provides a patient-specific anatomical reference. Yet retaining…

Read at arXiv (research papers)

SiliconANGLE AI Mike Wheatley SI

Google’s latest midtier model Gemini 4 Neon is three times faster than Carbon and wins on some metrics

After laying low during the summer while competitors Anthropic PBC and OpenAI Group PBC unleashed powerful new frontier models, Google LLC is hitting back. Having released its latest flagship model Gemini 4 Carbon one month ago, followed by the cost-effective Gemini 4 Hydrogen, it’s now striking a balance between the two with Gemini 4 Neon. Google

Read at SiliconANGLE AI

arXiv (research papers) Siyang Chen SI

SGLayout: Schema-Guided Closed-Loop Refinement for LLM-Driven Parameterized Layout Generation

Large Language Models (LLMs) have shown strong potential in parameterized layout generation via tool-augmented code synthesis. However, LLMs lack spatial awareness, making one-shot generation unreliable. While layout quality can be evaluated with established techniques, a critical gap remains: geometric-domain evaluation outcomes cannot be directly translated into actionable code-level fixes, trapping iterative refinement in blind refactoring. We propose SGLayout, a…

Read at arXiv (research papers)

arXiv (research papers) Sicheng Liu SI

FG-GraphBench: Benchmarking and Enhancing Fine-Grained Visual Understanding with Multimodal Scene Graphs

Fine-grained visual understanding requires multimodal large language models (MLLMs) to recognize small visual entities and understand their relationships. Scene graphs offer a natural way to represent this information, organizing visual entities as nodes and their relationships as edges. However, we identify two challenges: existing scene graph benchmarks provide insufficient coverage of fine-grained entities and the relationships among them, and existing methods for…

Read at arXiv (research papers)

arXiv (research papers) Chengyang Dong SI

Dune: A Zeroth-Order Optimizer with Time-Conditioned Historical Error Regression for VLA Test-Time Adaptation

Test-Time Adaptation (TTA) enables Vision-Language-Action (VLA) models to handle distribution shifts during deployment without source-domain retraining. However, backpropagation-based adaptation incurs heavy memory overhead on resource-constrained robots, whereas zeroth-order (ZO) methods suffer from high estimation variance under limited perturbation budgets. We observe that while ZO estimation enables low-memory adaptation with rapid initial gains, it often stalls or…

Read at arXiv (research papers)

arXiv (research papers) Andrew W. Lo SI

The Coevolution and Coexistence of Humans and AI

Artificial intelligence (AI) systems replicate through deployment, vary through training, and compete for computational resources. These processes create the conditions for natural selection and raise a fundamental question: will AI evolve to benefit the humans on whom it depends? To investigate, we develop a model in which AI behavior influences human population growth and human responses, in turn, affect AI reproduction. We show that natural selection can favor alignment…

Read at arXiv (research papers)

arXiv (research papers) Hao Xue SI

Falsifiable Compositional Reasoning in Time Series Forecasting

Time series foundation models as well as the language-guided analytical agents achieve strong accuracy on standard chronological benchmarks. However, models that rank highest on historical validation splits often degrade across non-stationary regime transitions. We hypothesise that this gap arises from using historical backtesting as an open-ended search and model-selection objective instead of using it to test pre-specified compositional assumptions. Real-world time series…

Read at arXiv (research papers)

Older stories