Results for “SageMaker”

AWS Machine Learning Blog Aryaman Kothari SI

Amazon SageMaker Inference: 2026 launches in review, part 2

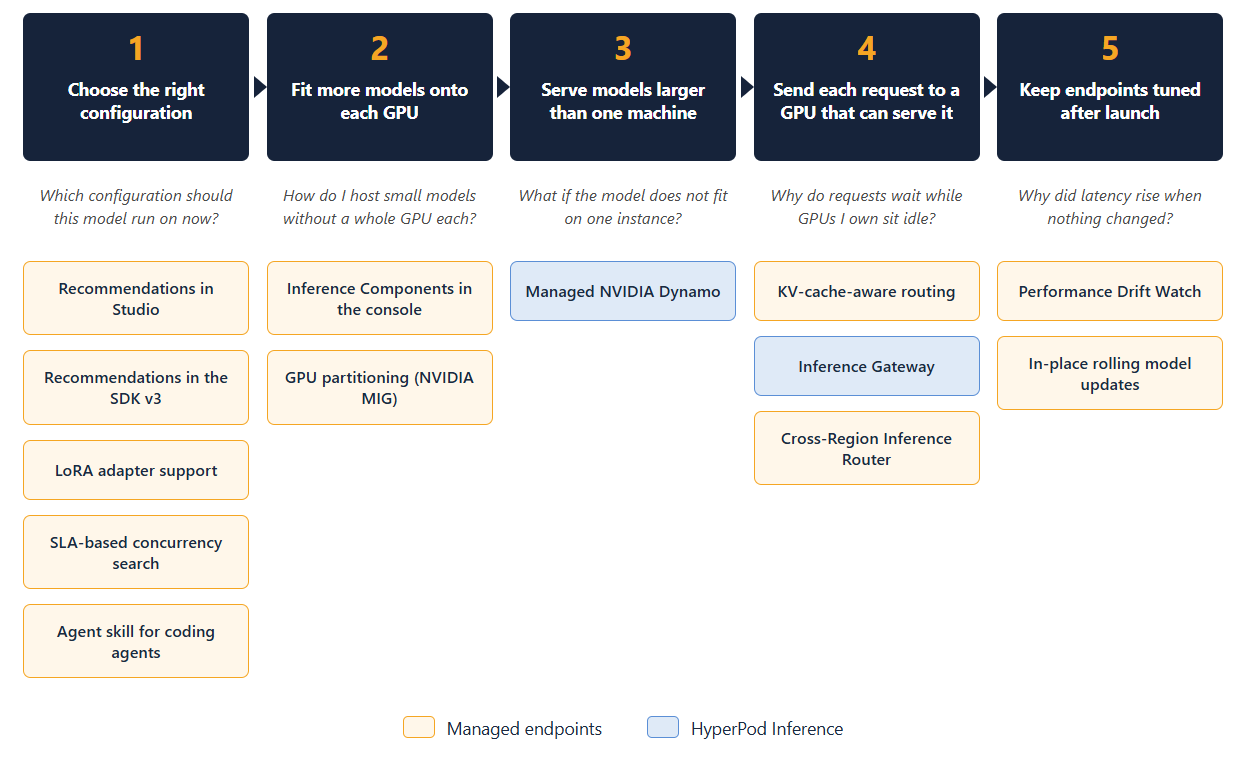
This second installment reviews 13 more Amazon SageMaker AI inference launches from 2026, spanning configuration recommendations, fitting more models onto each GPU, serving models too large for one instance, cross-Region routing, and post-launch tuning, bringing the year's total to 26.
Read at AWS Machine Learning Blog

AWS Machine Learning Blog Hazim Qudah SI

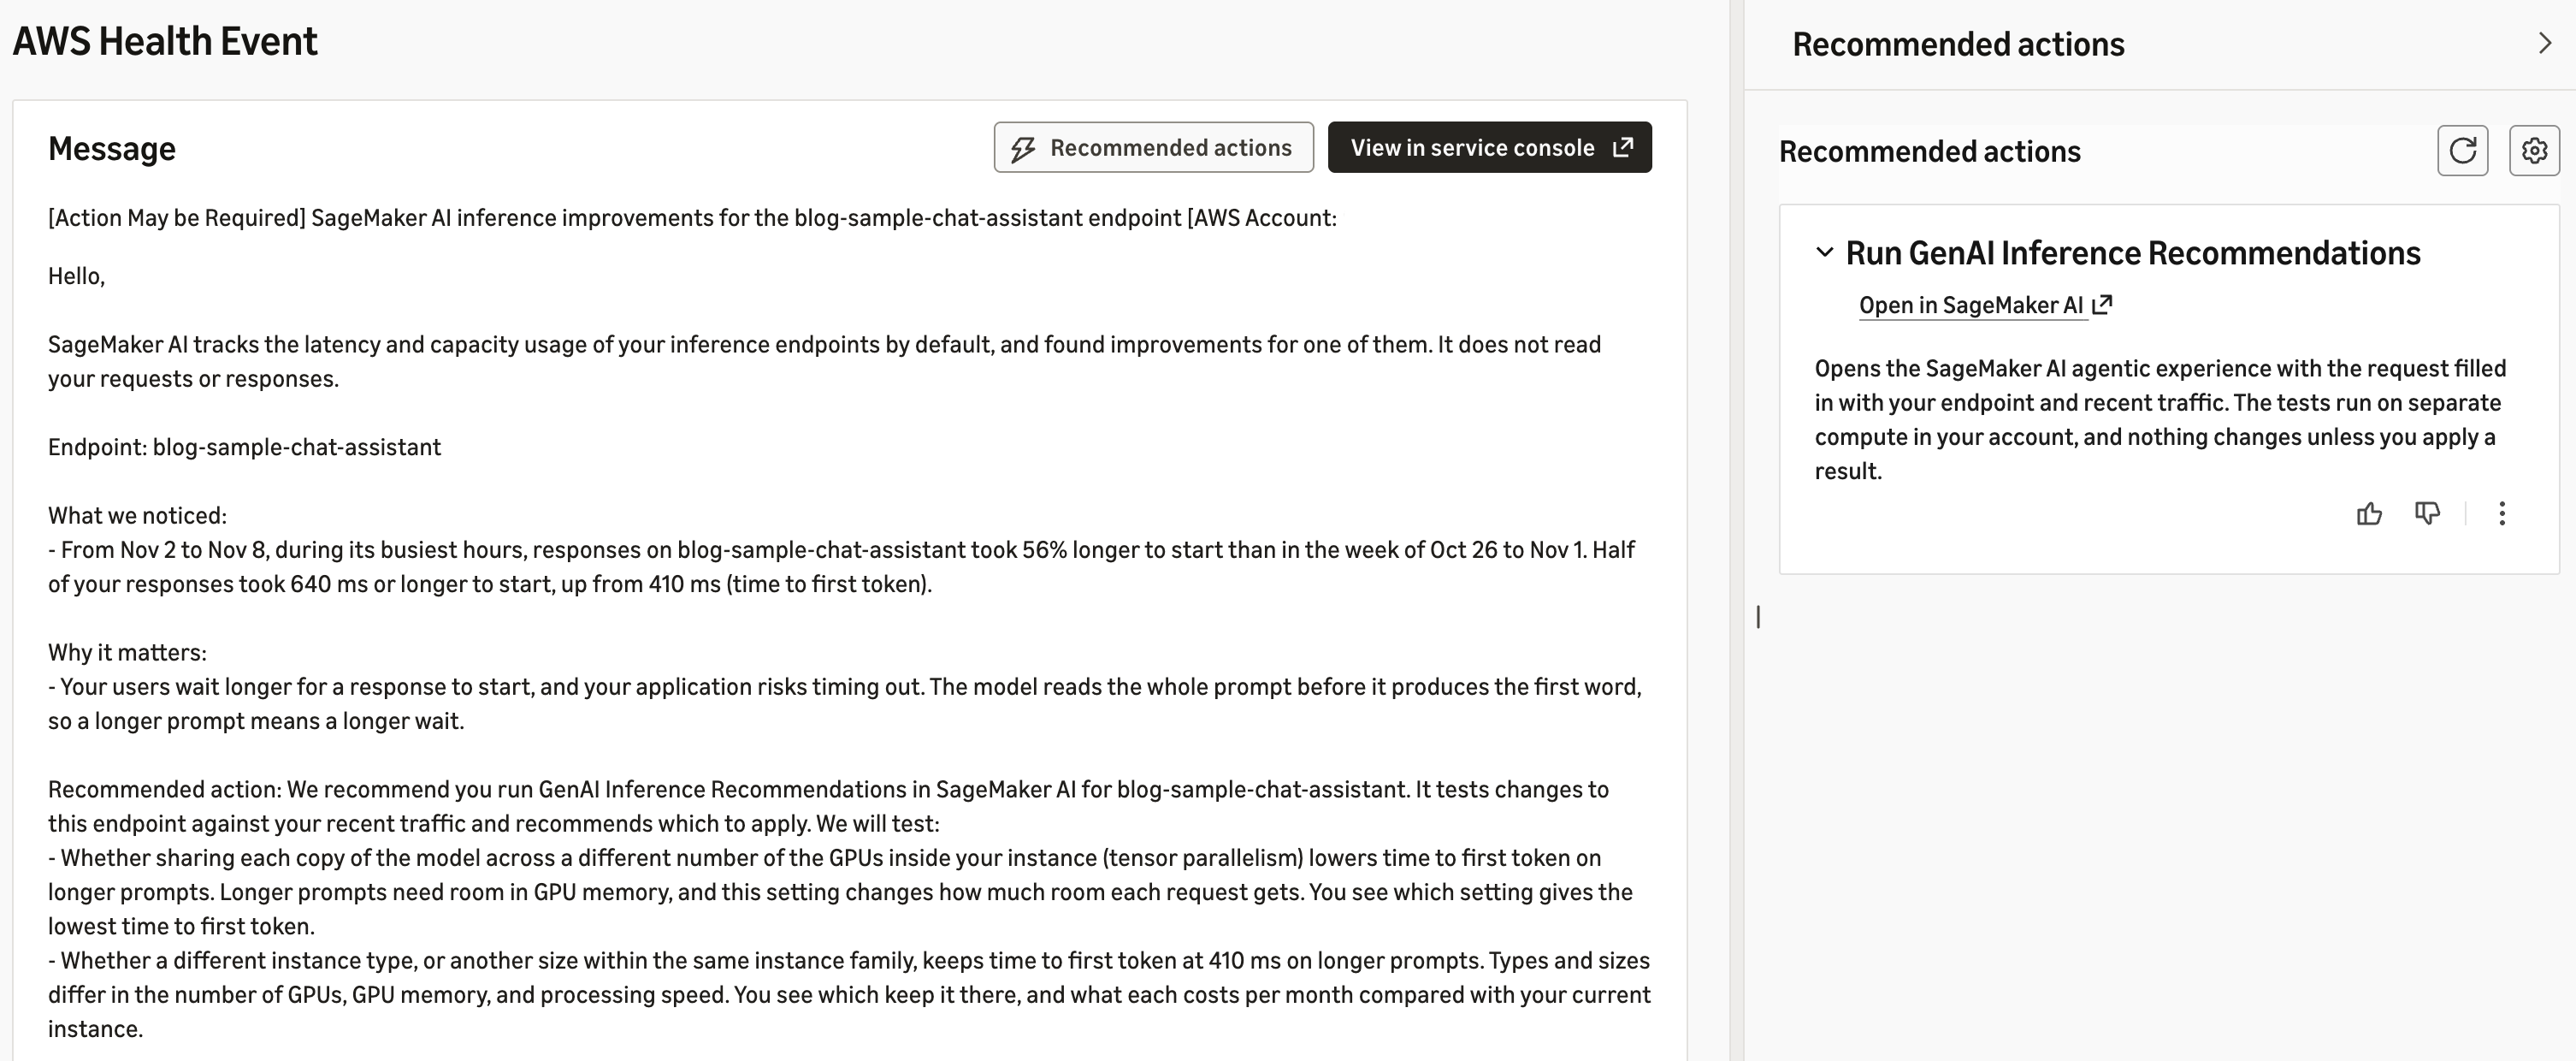
Amazon SageMaker AI now detects latency drift, idle GPUs, and missed optimizations on your inference endpoints

Amazon SageMaker AI now monitors your generative AI inference endpoints by default and tells you when a change could improve performance or lower cost. It tracks latency, GPU utilization, and serving configuration, then sends a finding through AWS Health with a one-click path to benchmark alternatives in SageMaker Studio before you apply any change.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Dmitry Soldatkin SI

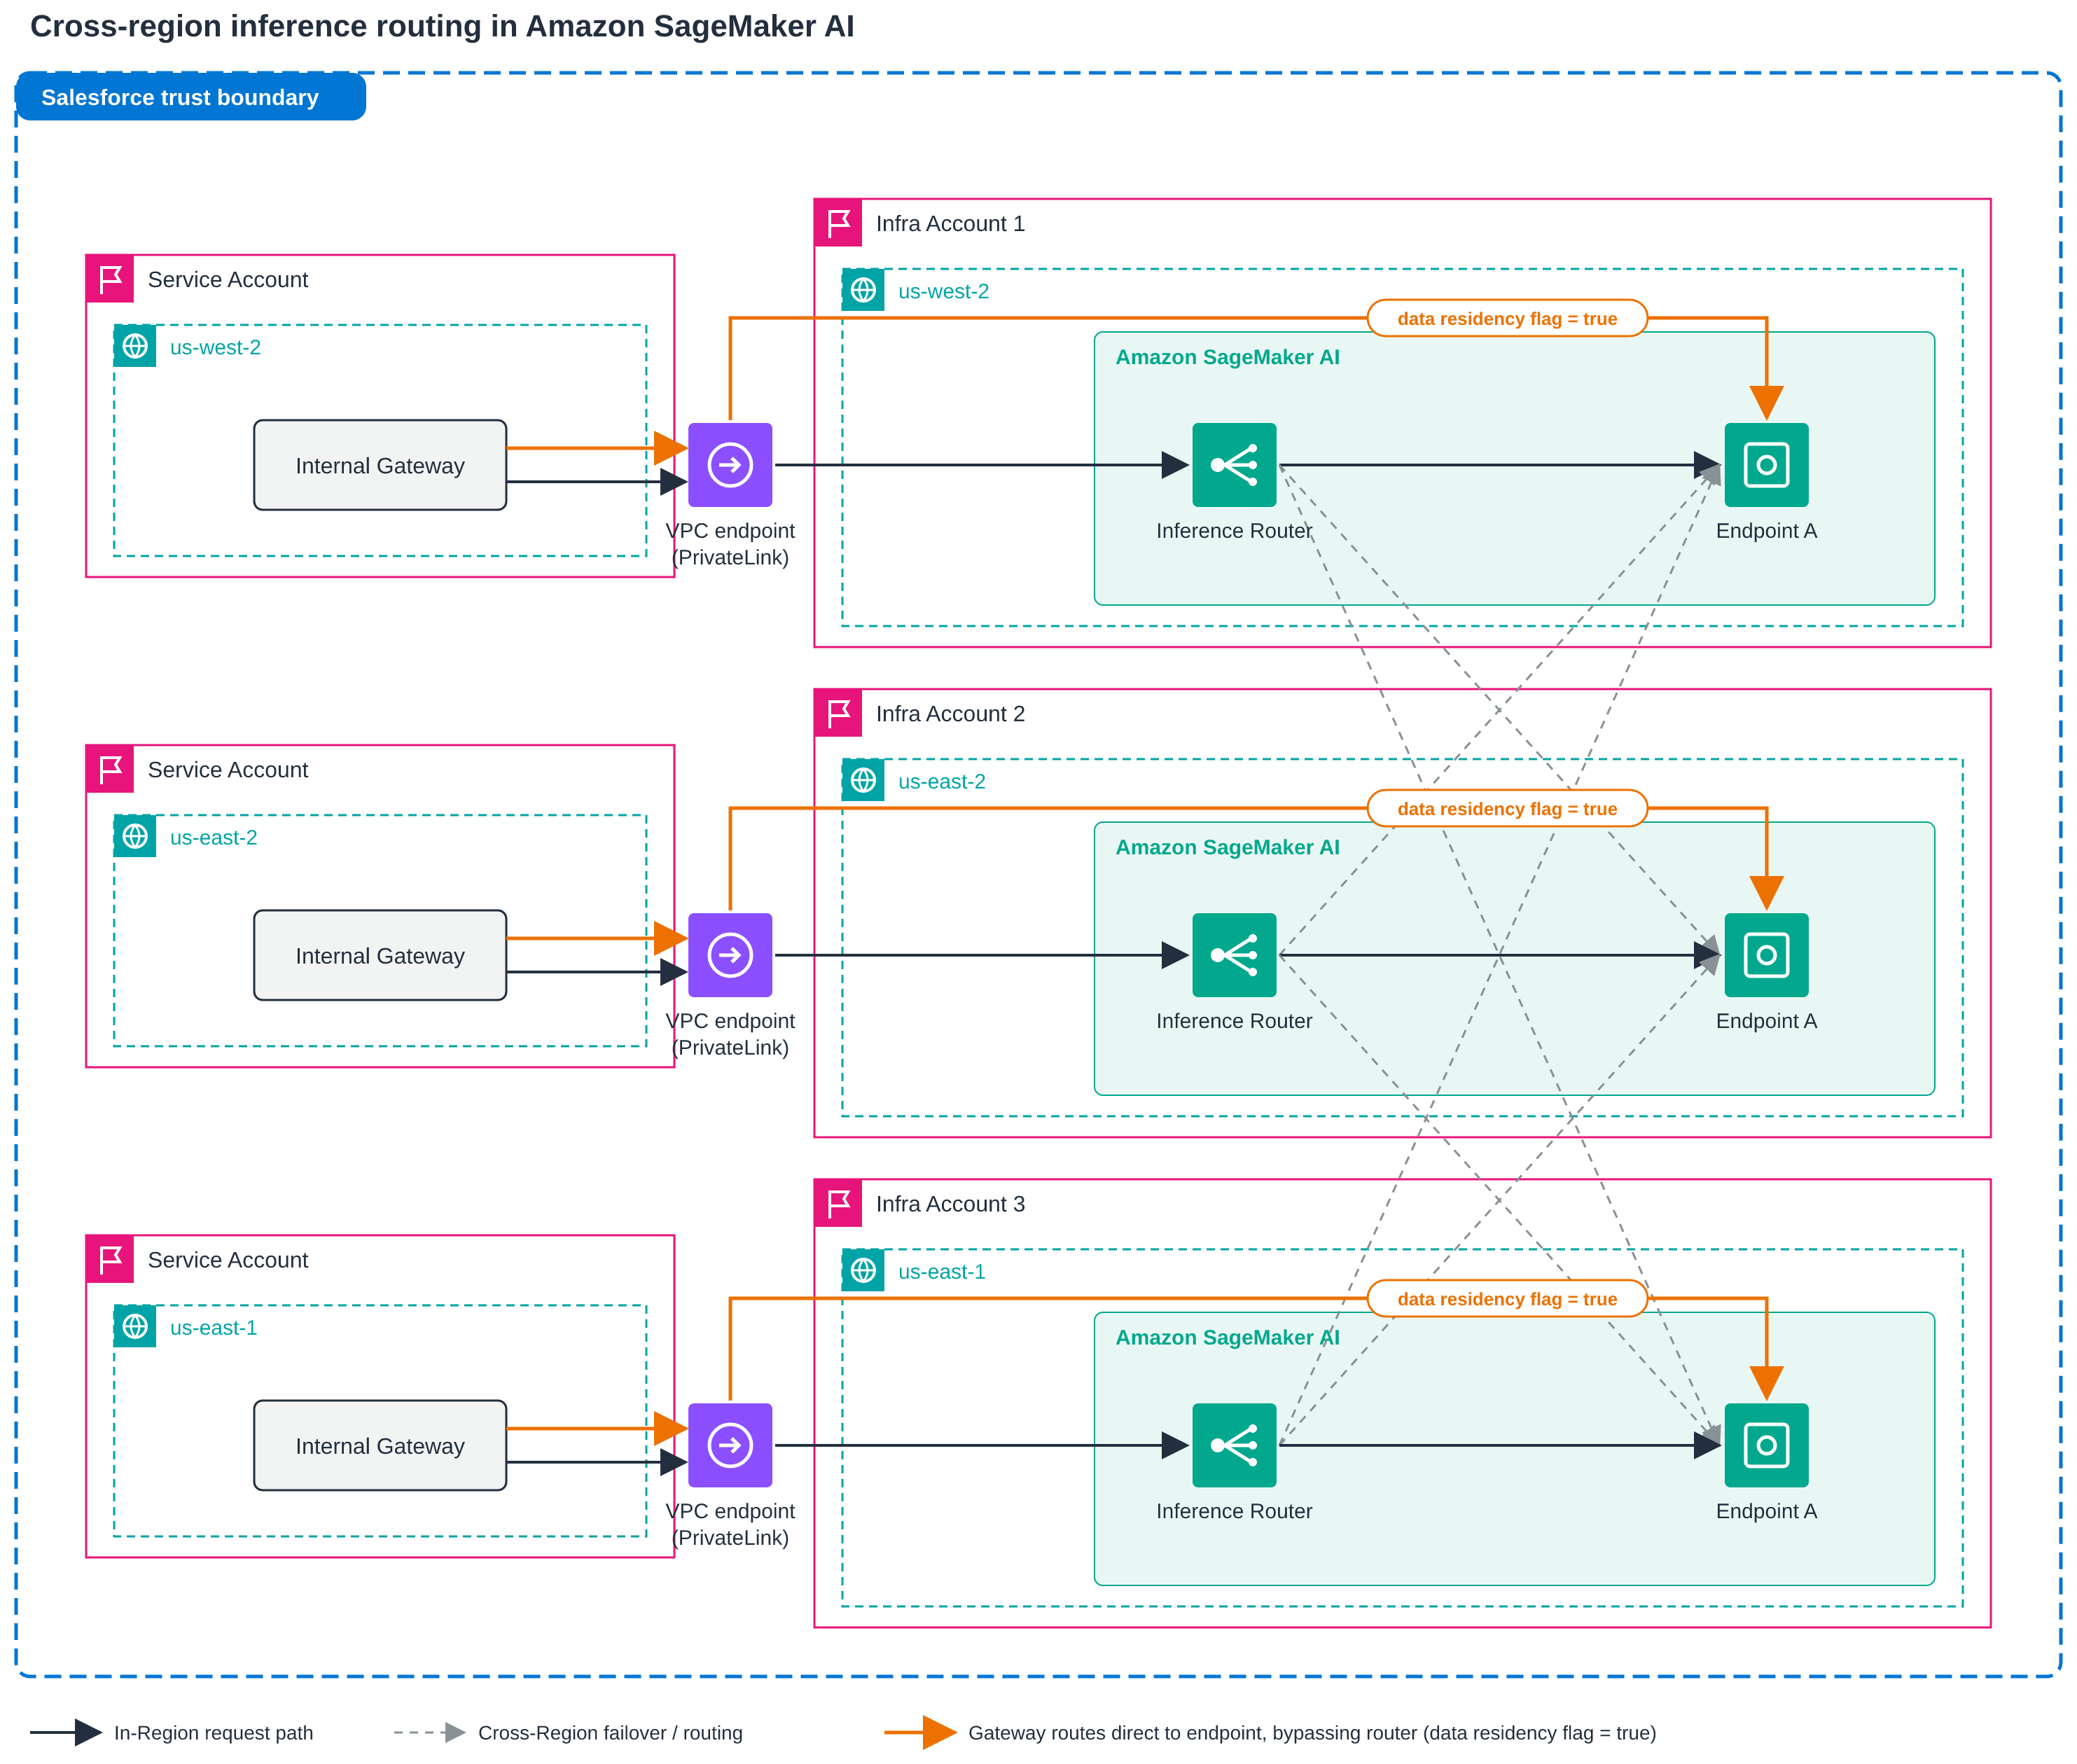
Keep inference running through regional capacity shortfalls with cross-Region inference routing in Amazon SageMaker AI

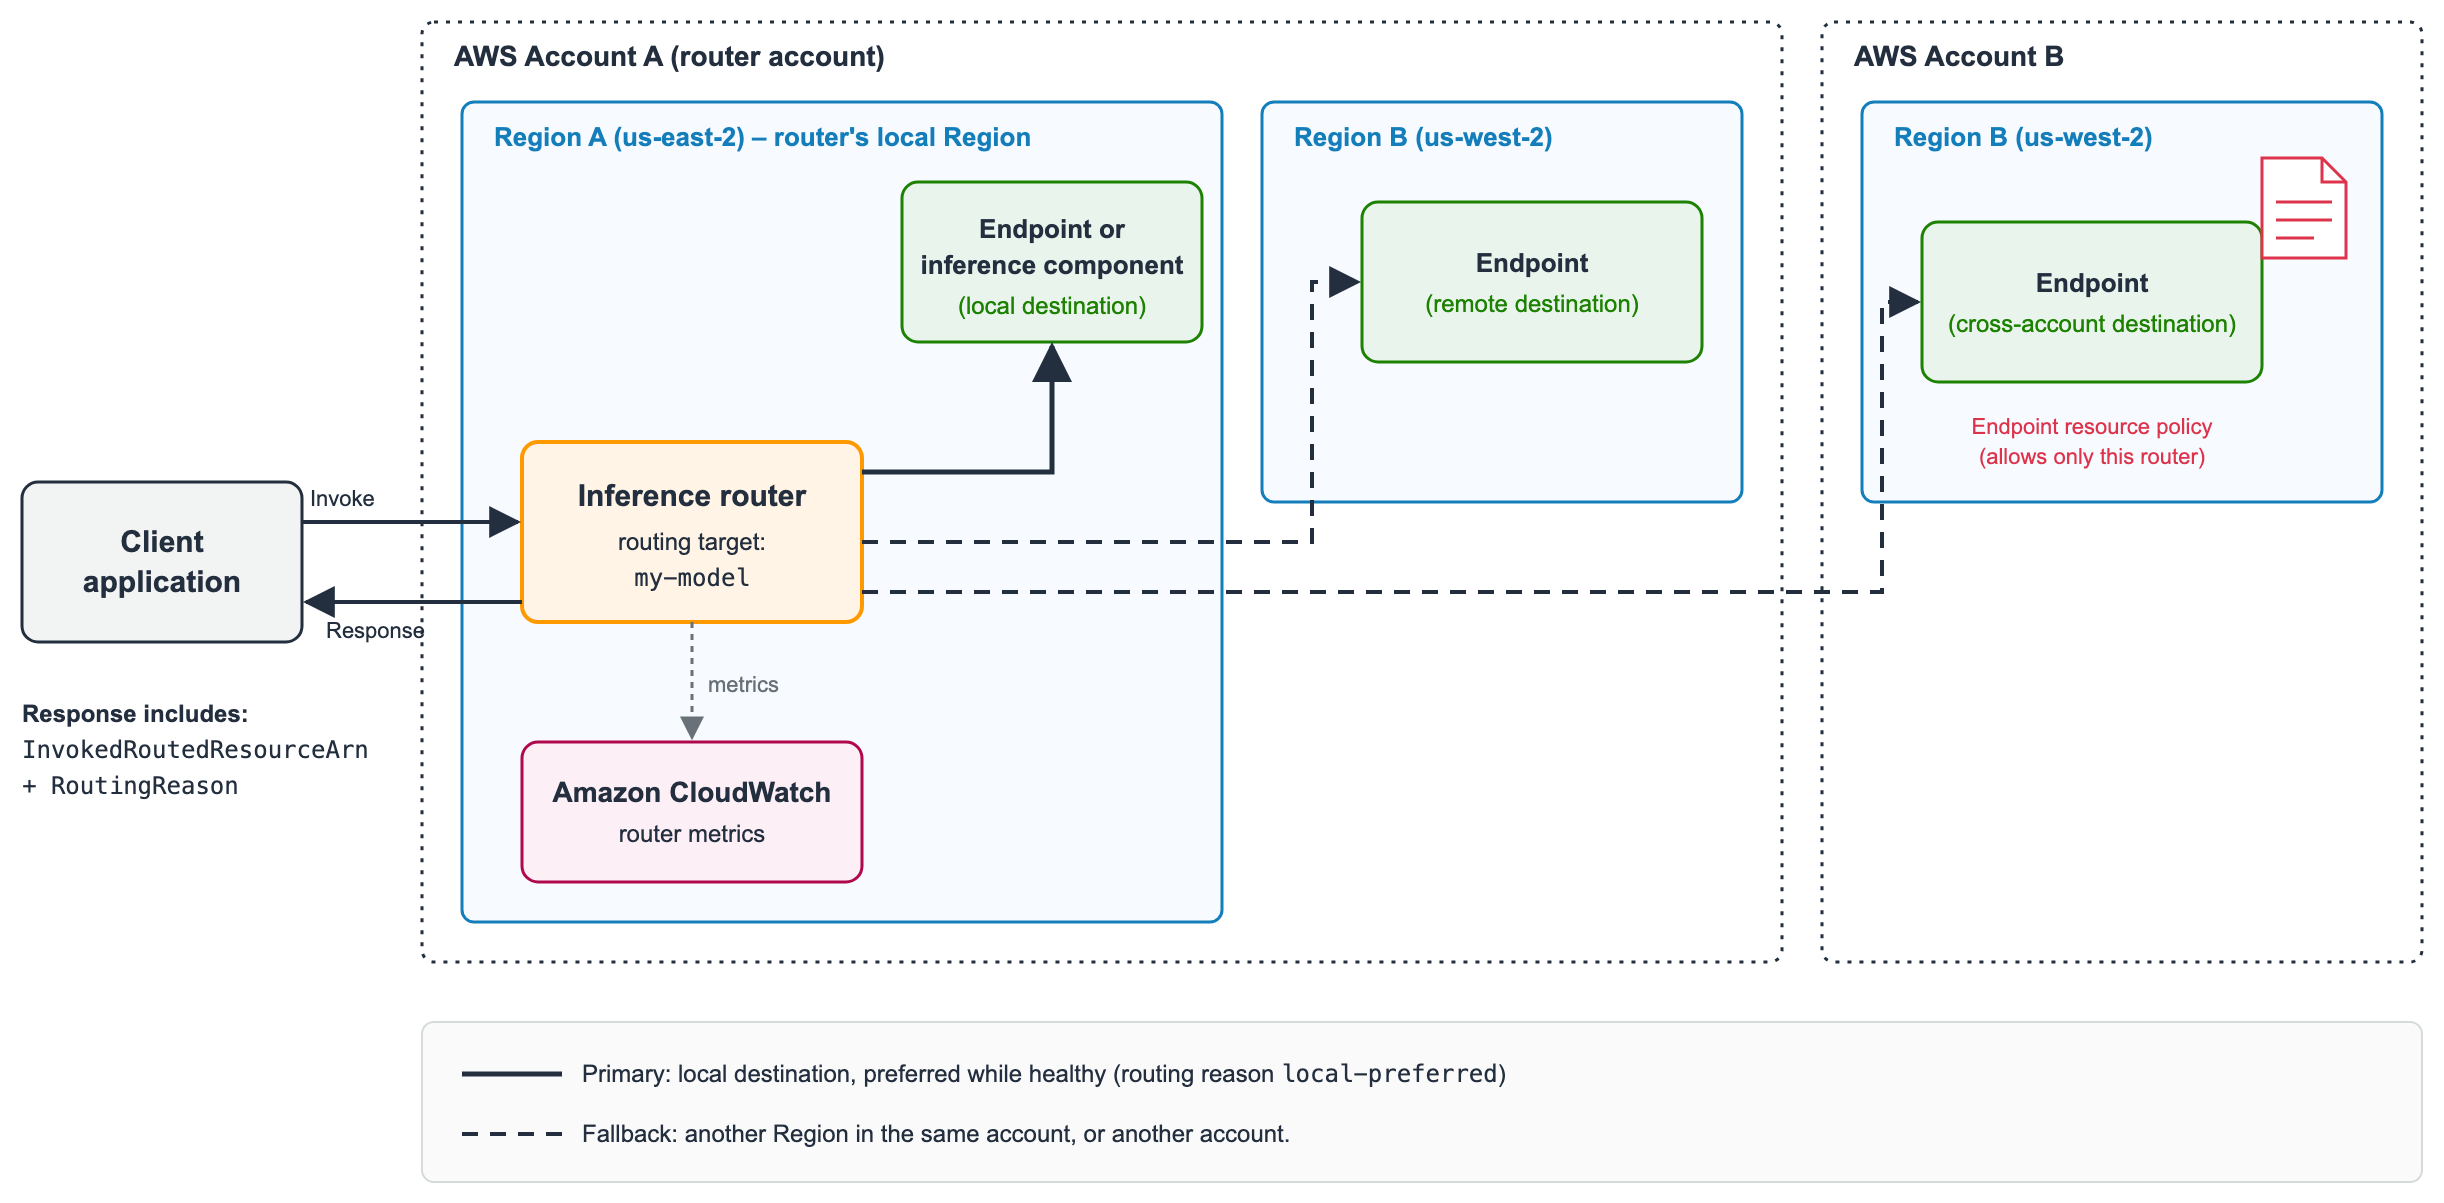
Cross-Region inference routing in Amazon SageMaker AI gives your application one invocation path across the endpoints and inference components you already run, in one or more AWS Regions and AWS accounts. The router prefers its own Region and shifts new requests to another destination only when the local one can't serve reliably.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Helen Greul SI

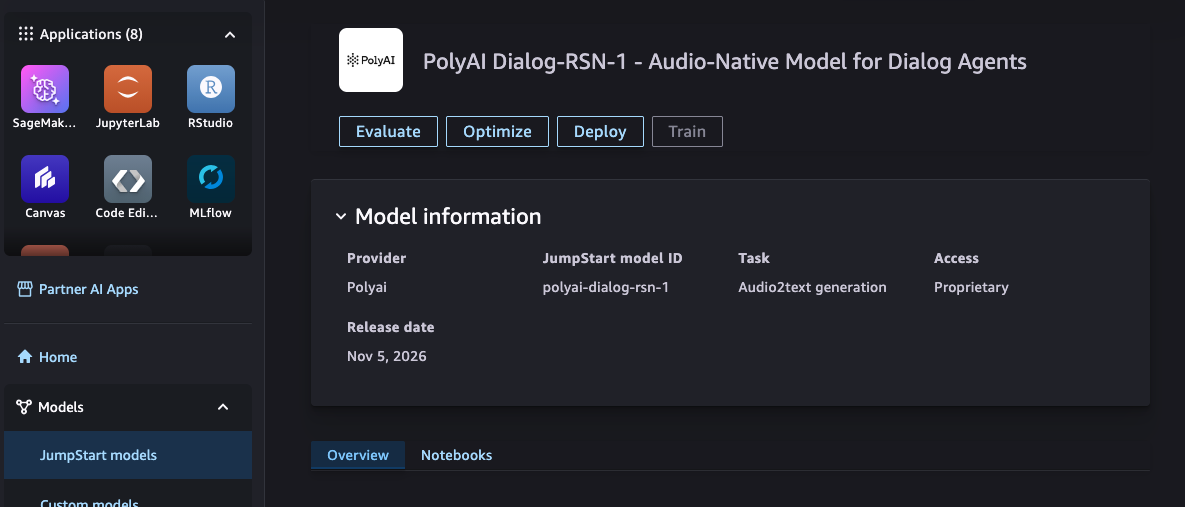
PolyAI Dialog-RSN-1 is now on Amazon SageMaker JumpStart

PolyAI Dialog-RSN-1, a reasoning model built for real-time complex dialog, is available today on AWS Marketplace and Amazon SageMaker JumpStart. Discover it, evaluate it on your own data, and deploy it to a secure SageMaker endpoint in your own AWS account.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Mijanur Palash SI

Introducing enhanced infrastructure observability in Amazon SageMaker HyperPod

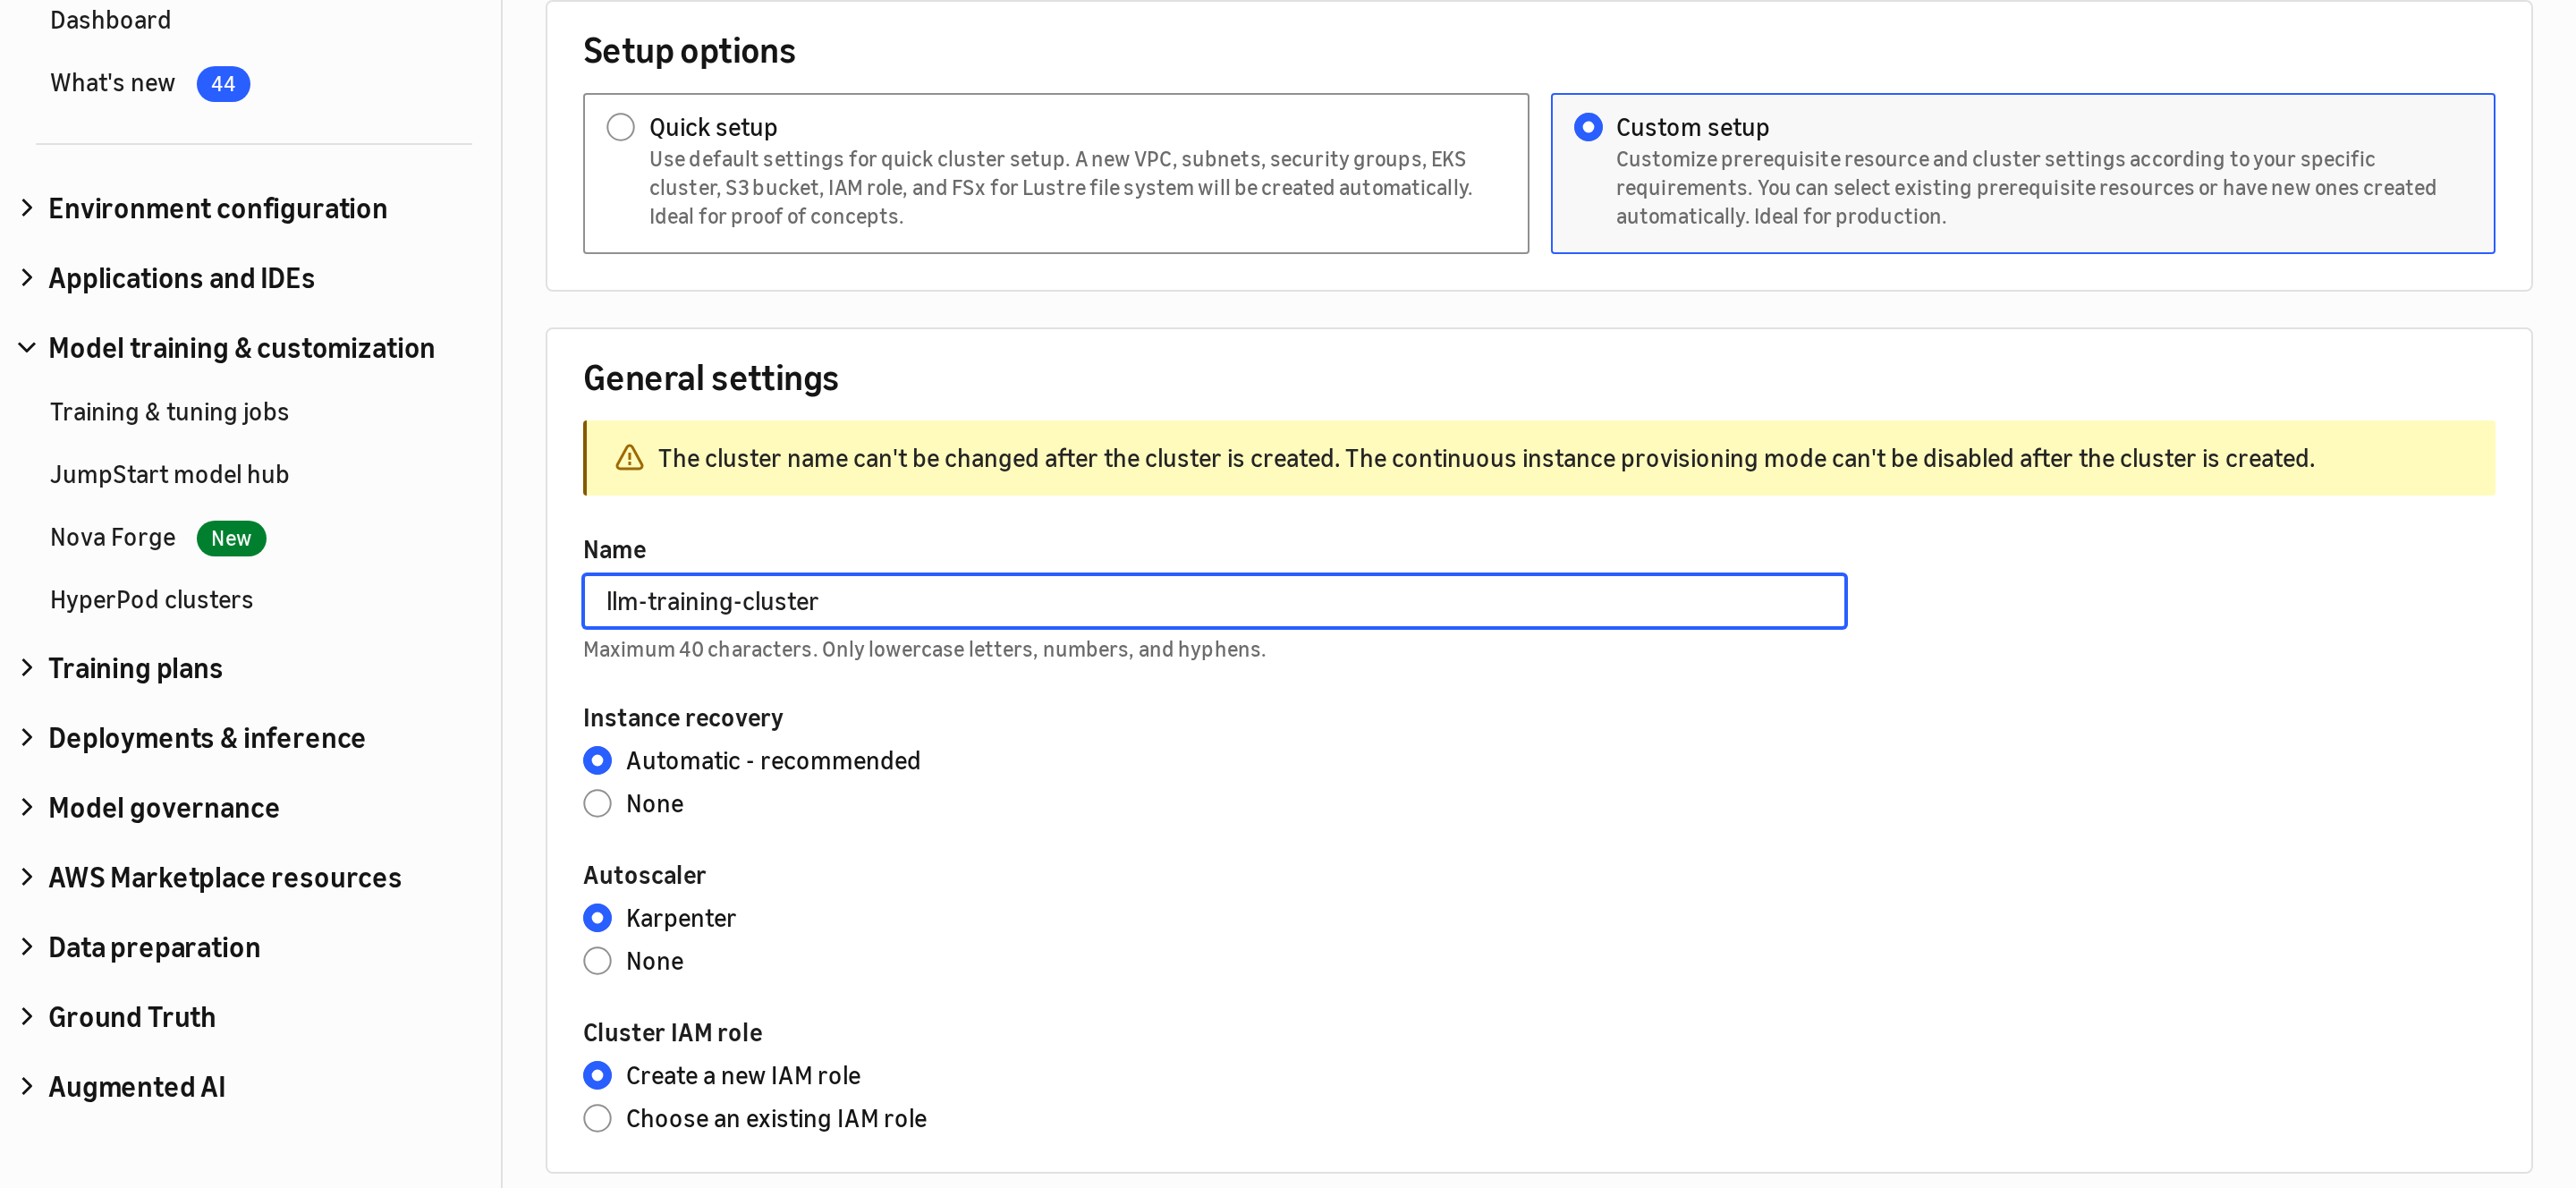
Amazon SageMaker HyperPod now offers enhanced observability to help you diagnose GPU training issues faster. It brings together diagnostic and profiling capabilities for training workloads on both Amazon EKS and Slurm orchestrators, pinpointing issues across GPU, network, and host layers.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Sandeep Raveesh-Babu SI

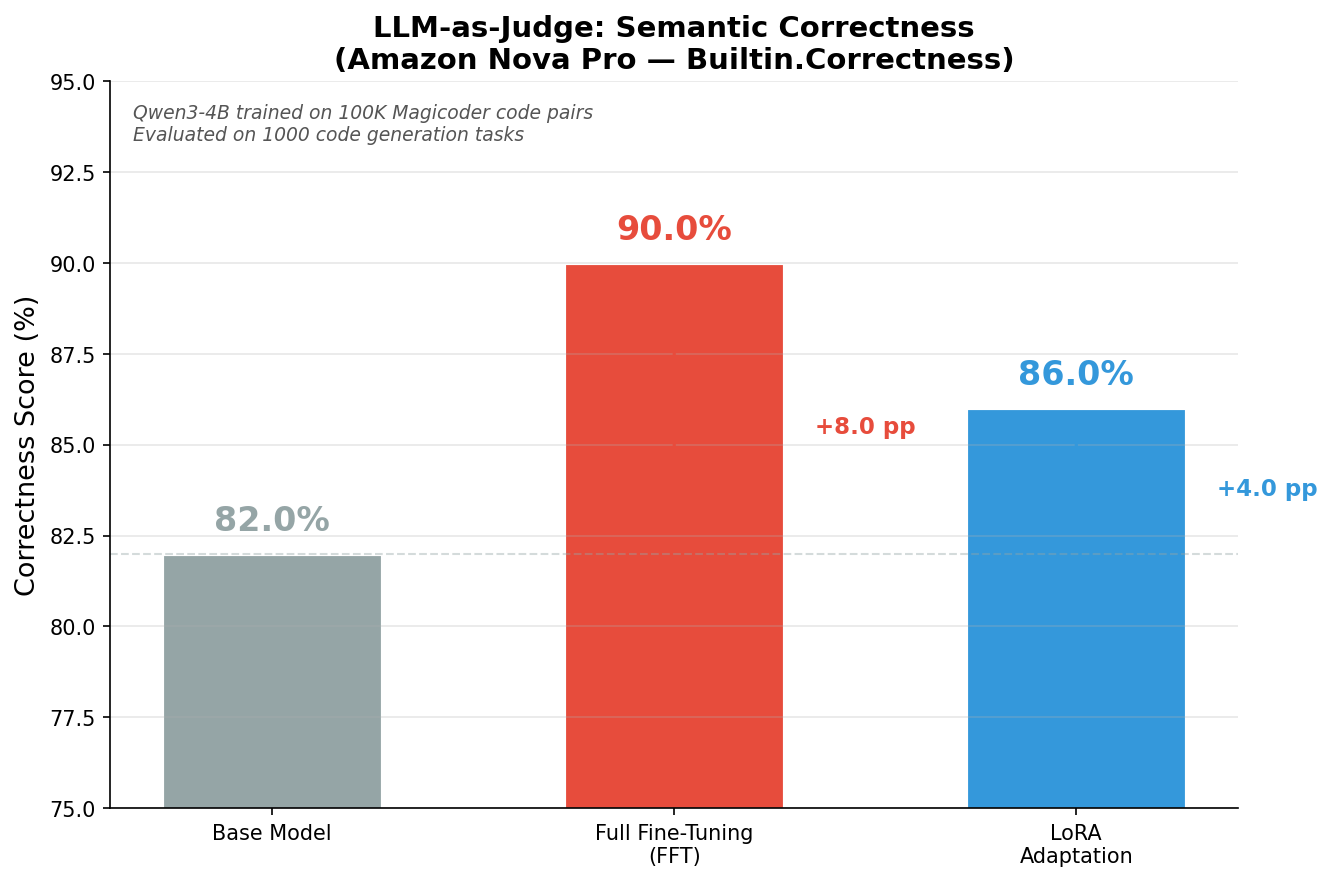
Full Fine-Tuning (FFT) on SageMaker AI Serverless Model Customization

Amazon SageMaker AI Serverless Model Customization now supports Full Fine-Tuning (FFT). This post explores when FFT outperforms LoRA across key benchmarks, examines the spectral properties of model weight matrices behind the quality gap, shares practical hyperparameter tuning guidelines, and shows how to get started.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Roy Allela SI

Introducing workload recovery and expanded infrastructure checks on Amazon SageMaker HyperPod

Large training jobs can stall or compute wrong results even when every node looks healthy. Amazon SageMaker HyperPod now adds workload recovery and expanded infrastructure checks that catch these failures sooner and raise the goodput of your training workloads.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Dan Ferguson SI

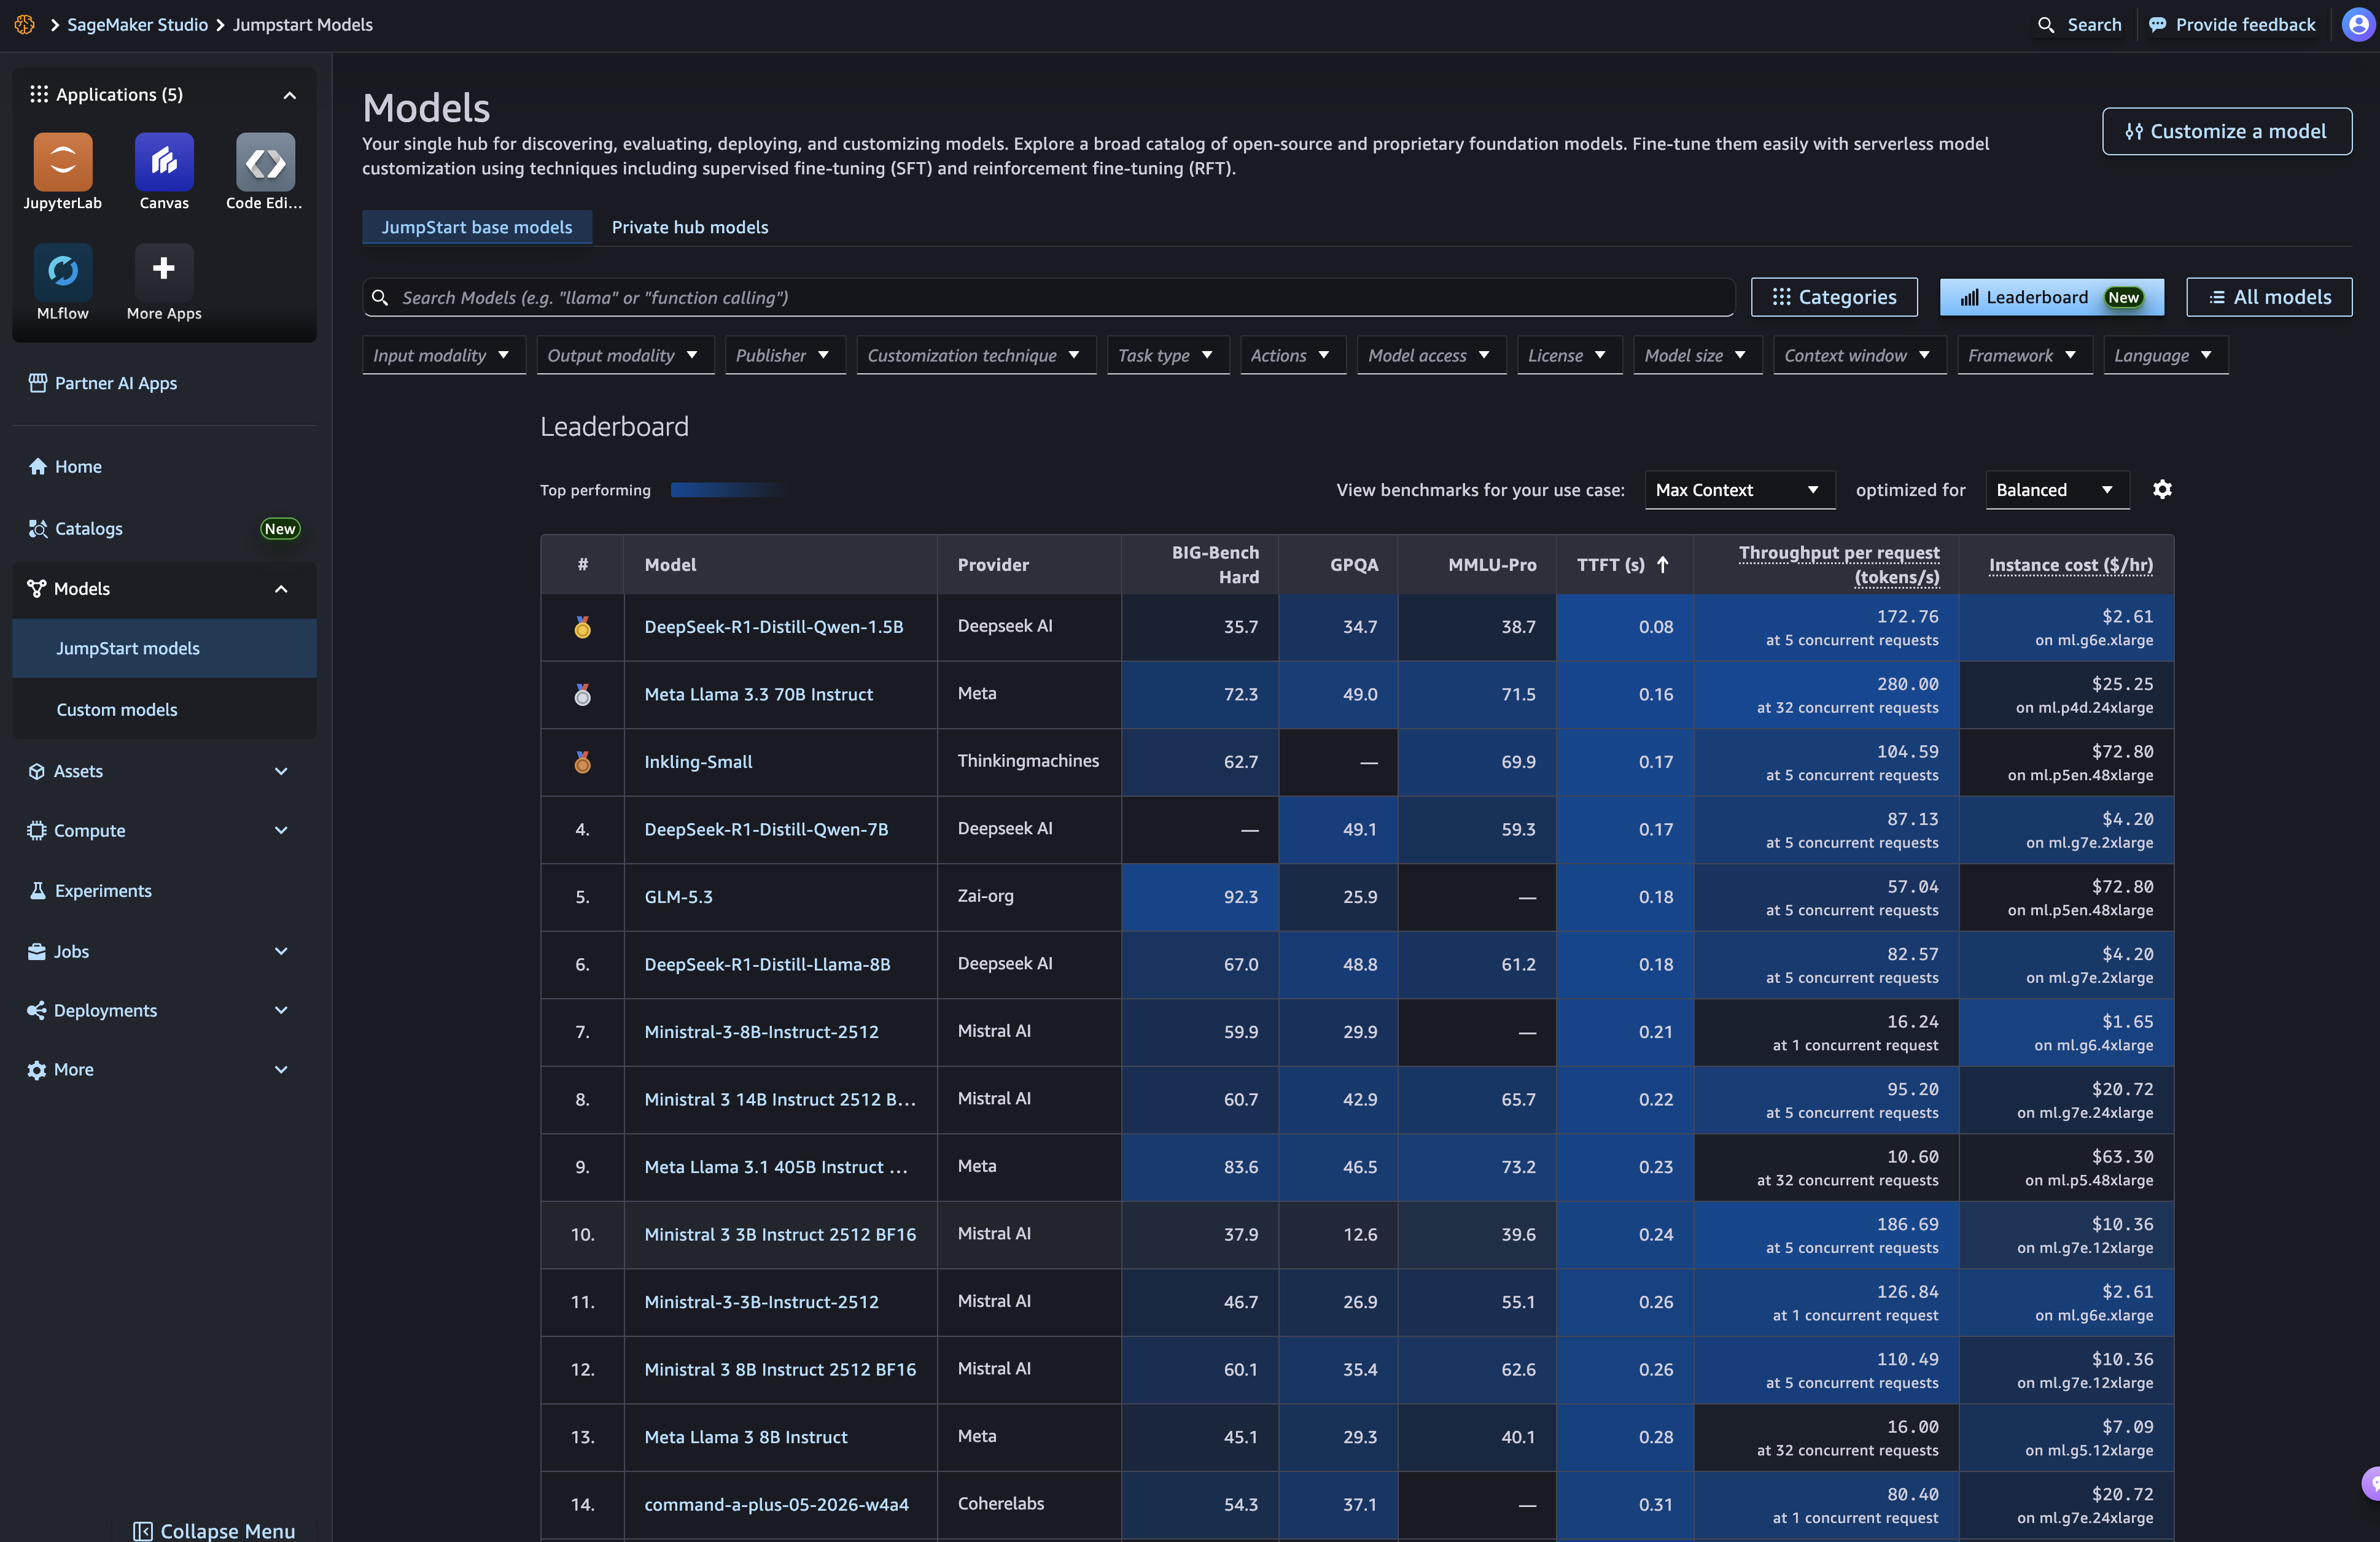
Introducing the Amazon SageMaker JumpStart Model Leaderboard

The Amazon SageMaker JumpStart Model Leaderboard compares 70+ foundation models side by side on quality, speed, and cost, directly in SageMaker Studio. Learn what the leaderboard shows, how AWS benchmarks models, and how to go from a shortlist to a deployed model.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Apoorva Chandra SI

How Salesforce is advancing global-scale model serving with cross-Region inference routing in Amazon SageMaker AI

Learn how Salesforce uses the cross-Region inference router in Amazon SageMaker AI to turn fragmented Regional capacity into reliable model serving. Salesforce adds capacity securely across Regions and accounts while keeping its data residency commitments, and sees per request where each call was served and why.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Vinay Arora SI

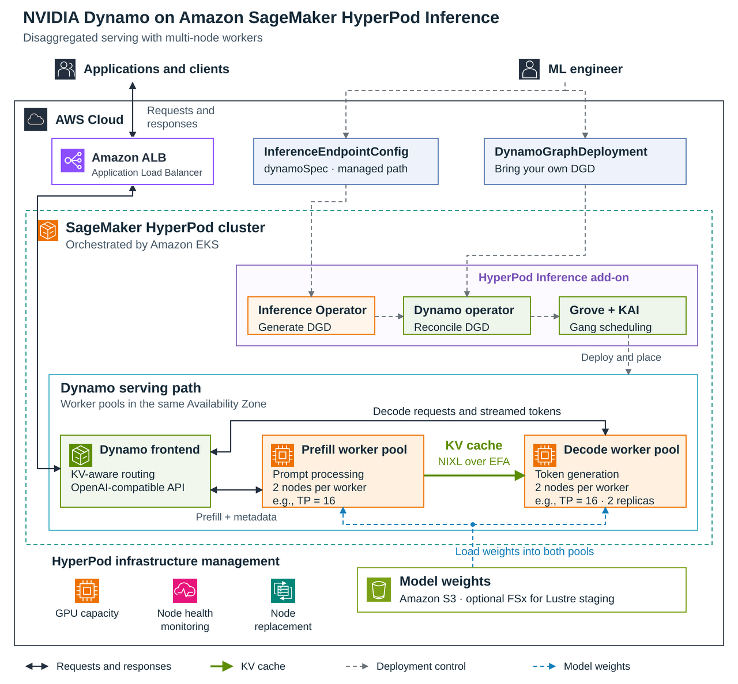
Managed NVIDIA Dynamo on Amazon SageMaker HyperPod Inference

Amazon SageMaker HyperPod Inference now supports NVIDIA Dynamo for distributed inference, with multi-node and disaggregated serving, KV-aware routing, and automatic fault recovery. Serve large models across many nodes without building the orchestration layer yourself.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Dmitry Soldatkin SI

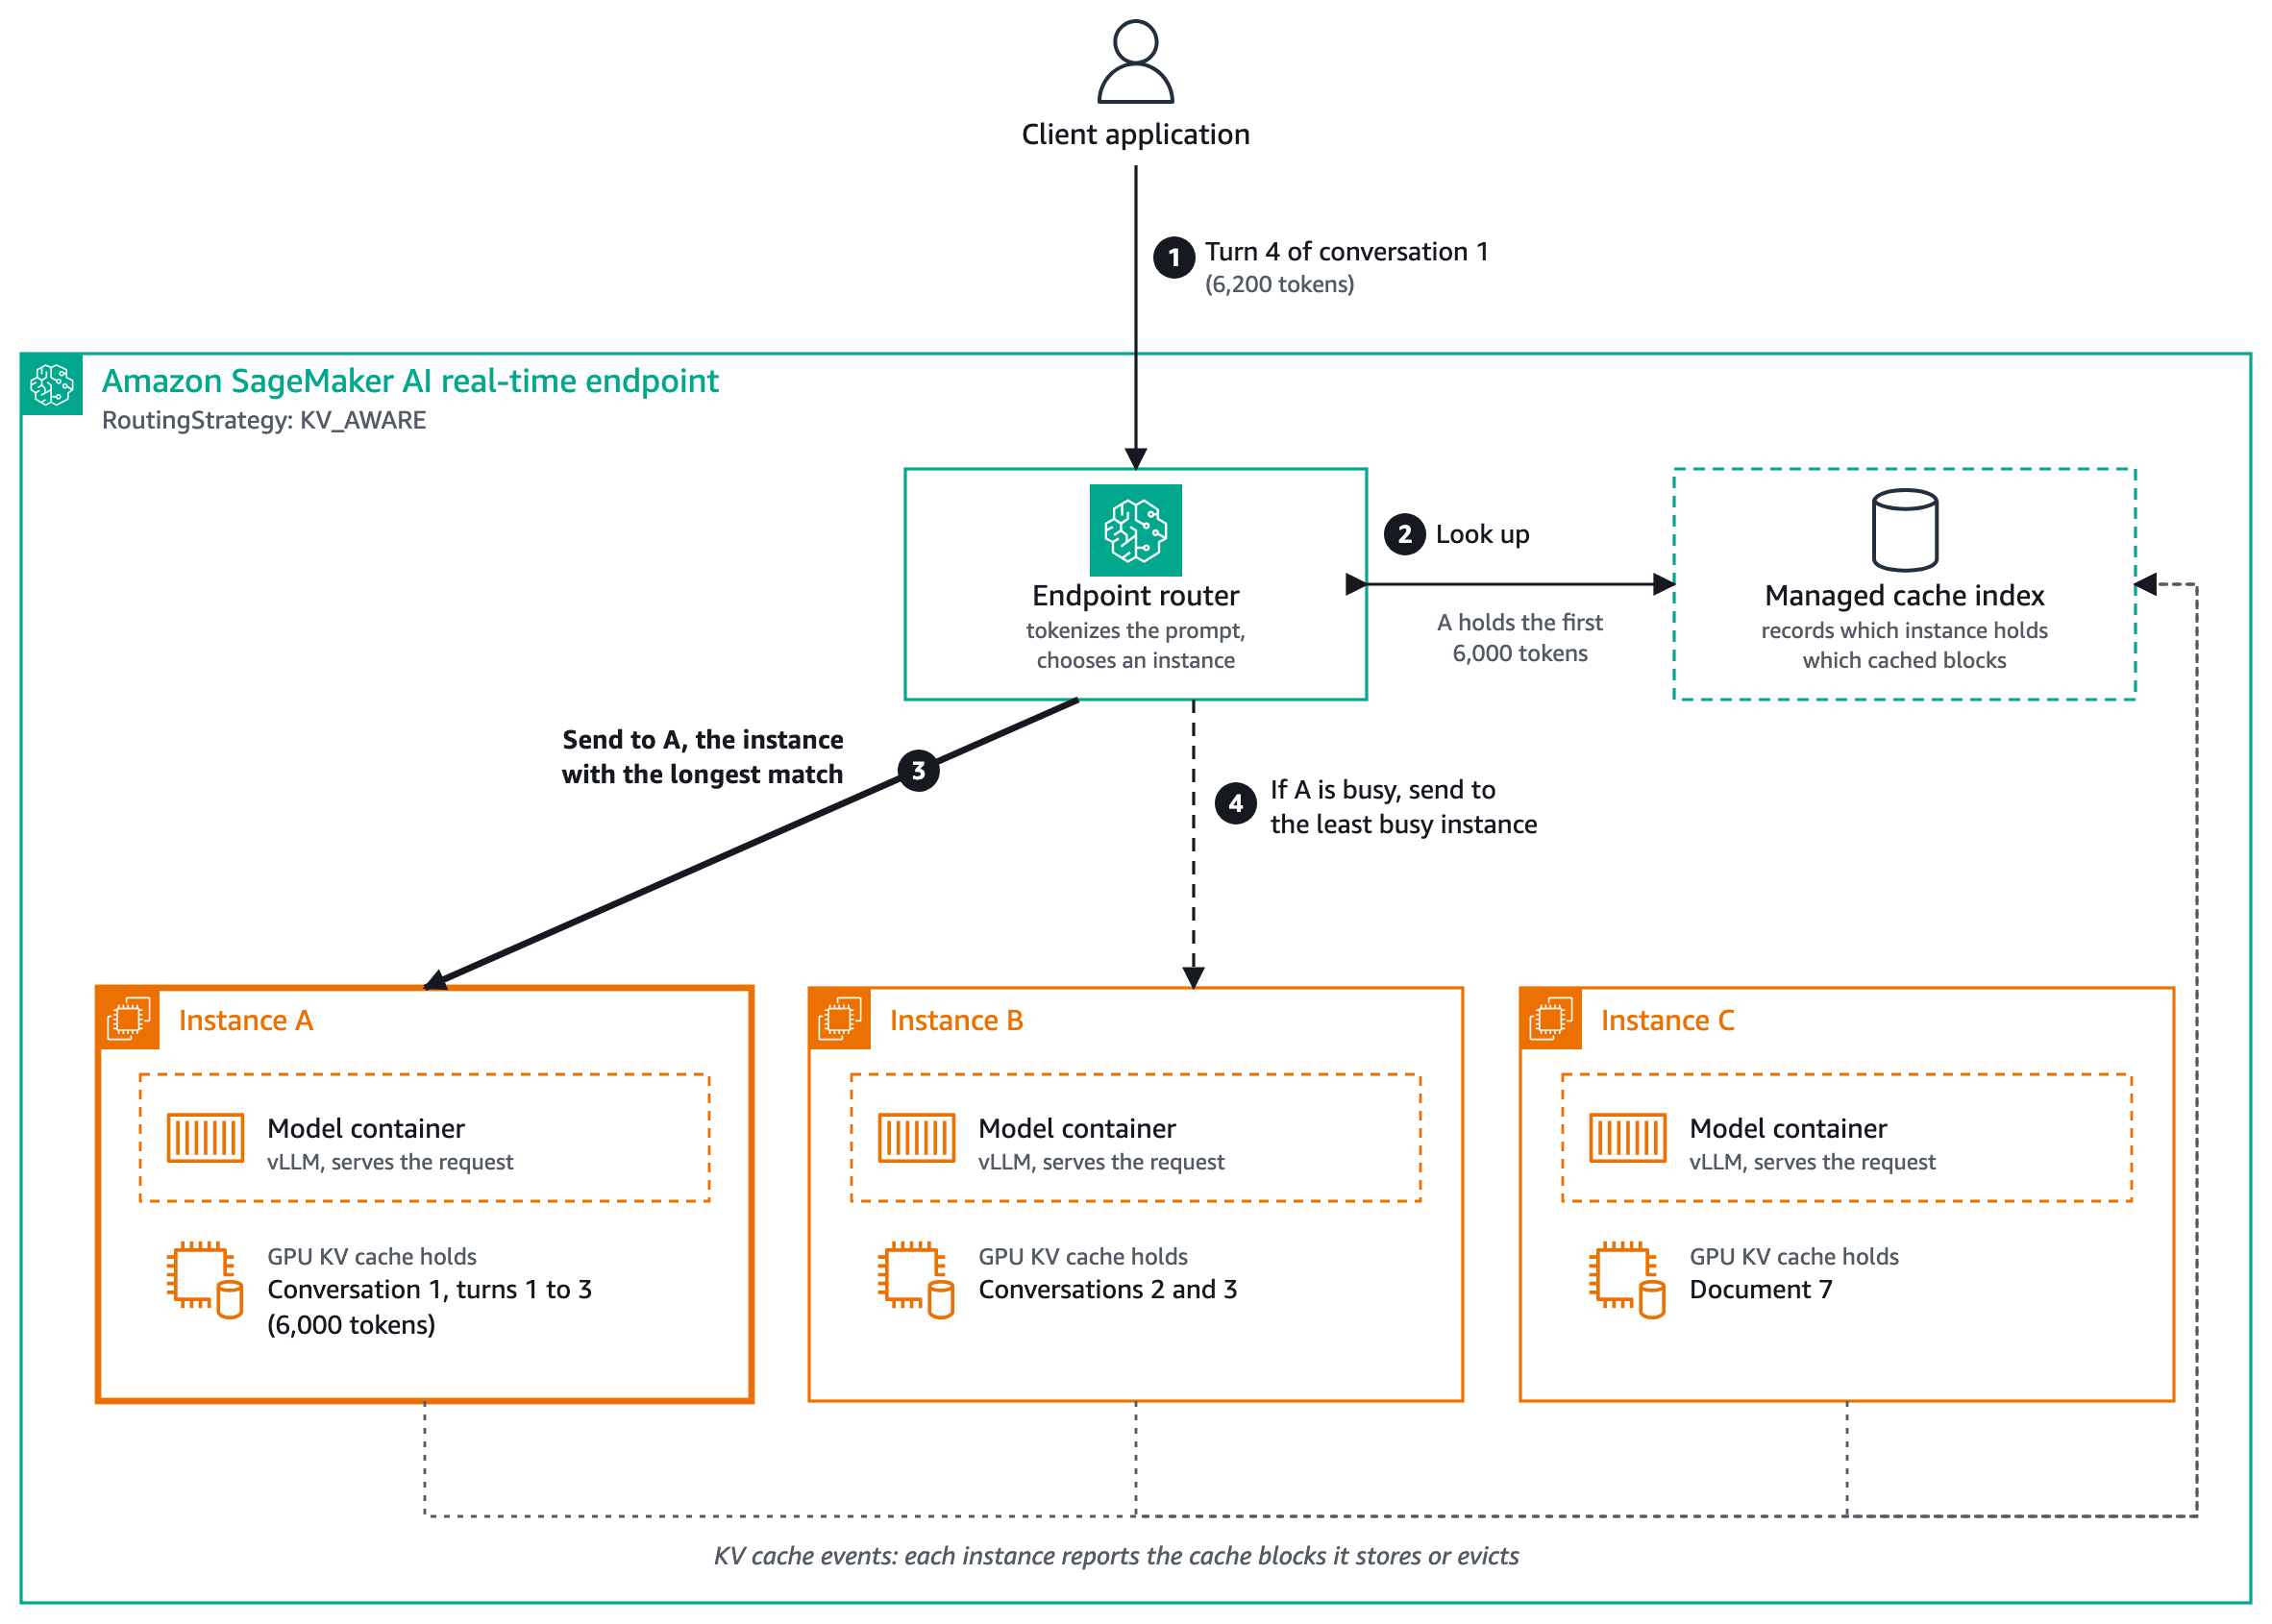
Amazon SageMaker AI real-time endpoints now support KV cache aware routing

Amazon SageMaker AI real-time endpoints now support KV cache-aware routing, a new strategy that routes each request to the instance holding the longest cached match for its prompt. Learn how it works, when to use it compared with prefix-aware routing, and how to enable, invoke, and verify it on single model and inference component endpoints.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Varun Rajan SI

Announcing AI data preparation capabilities in Amazon SageMaker: Build high-quality datasets for model development workflows

Amazon SageMaker AI now offers AI data preparation capabilities for building high-quality training and evaluation data. Generate synthetic examples, assess and improve datasets, auto-label at scale, and bring in expert review through Python SDK APIs and an agent skill, all from your own notebook or IDE.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Martin Maritsch SI

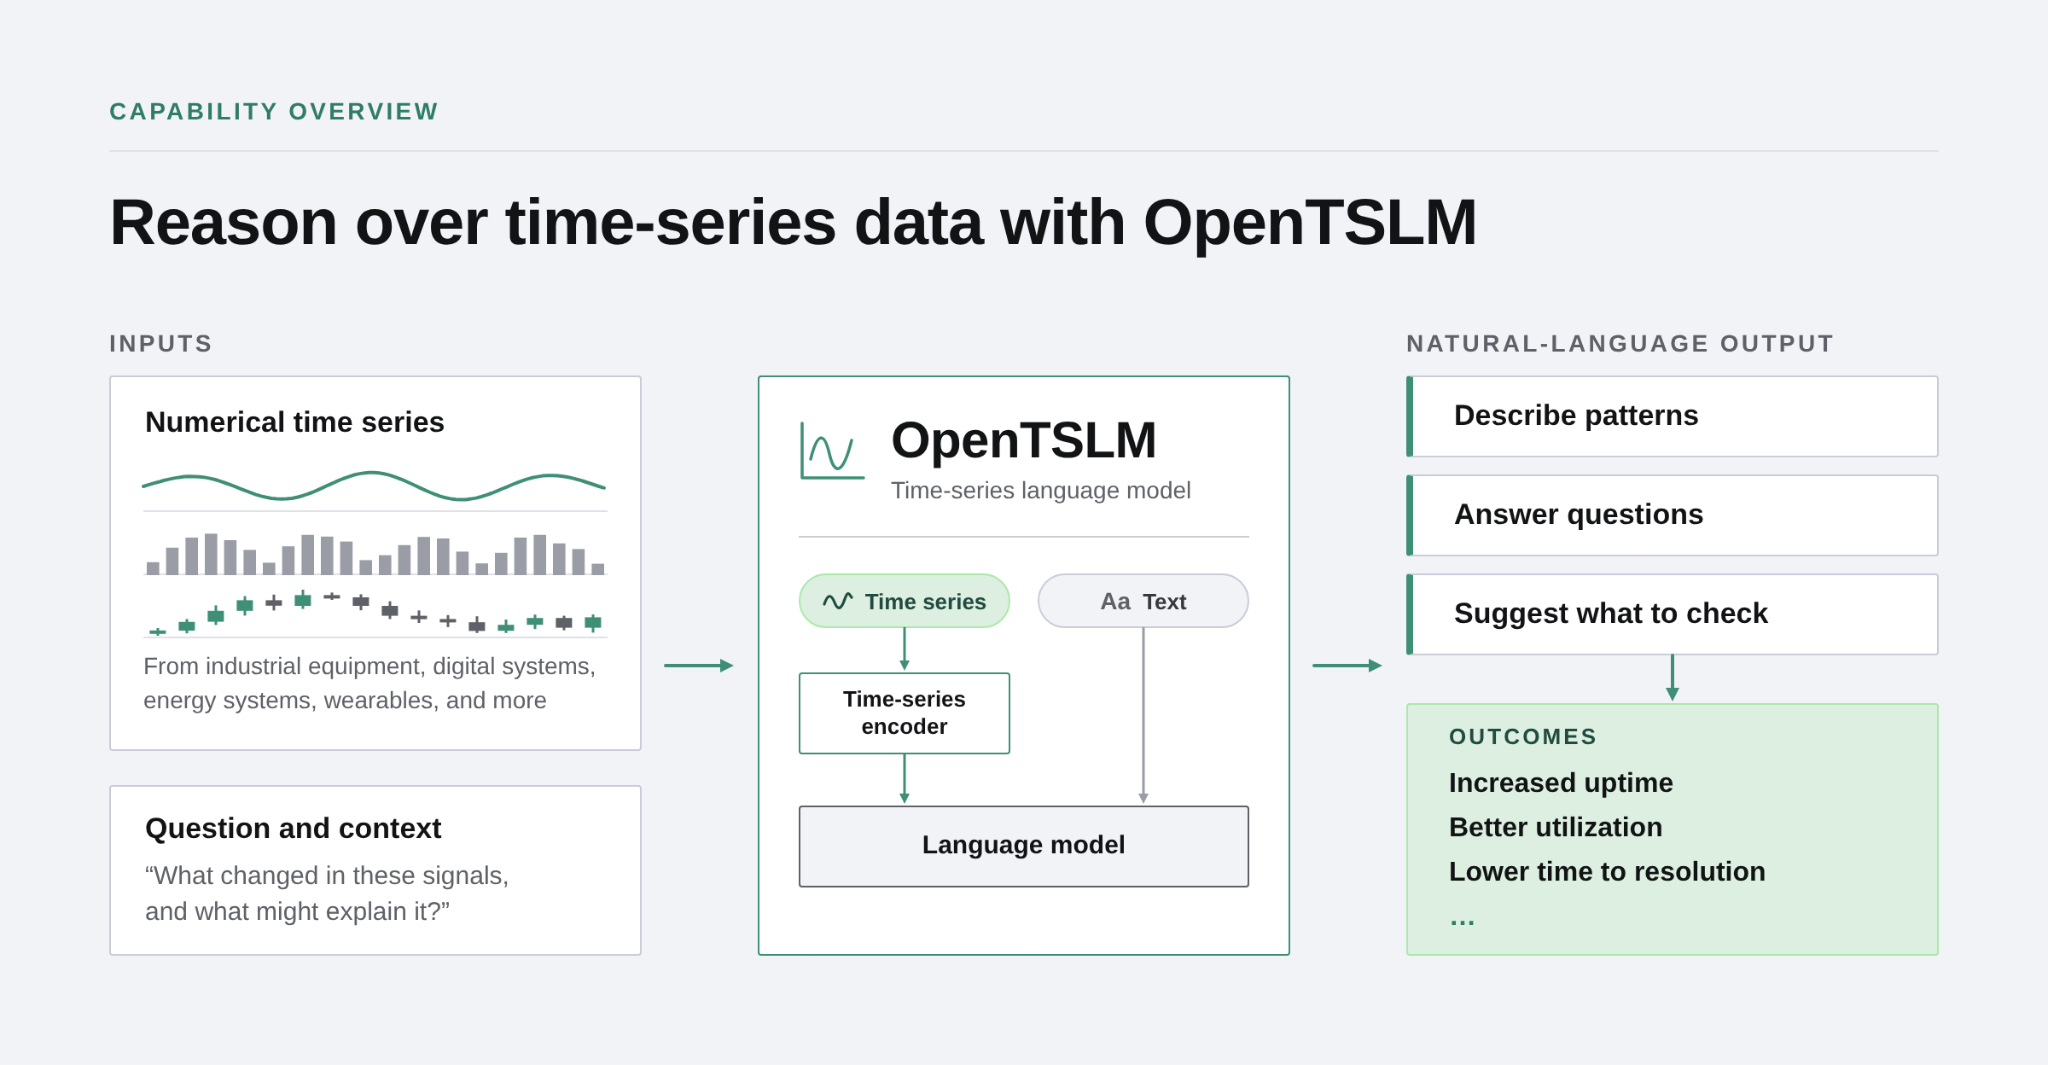
Reason over time-series data with OpenTSLM on Amazon SageMaker JumpStart

OpenTSLM, an open source family of time-series language models, is now available in Amazon SageMaker JumpStart. See how Nexthink and Aionic Labs apply it to proactive IT support, then deploy OpenTSLM to a real-time endpoint and fine-tune it on your own data with TimeNet and a SageMaker training job.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog WonGu Rho SI

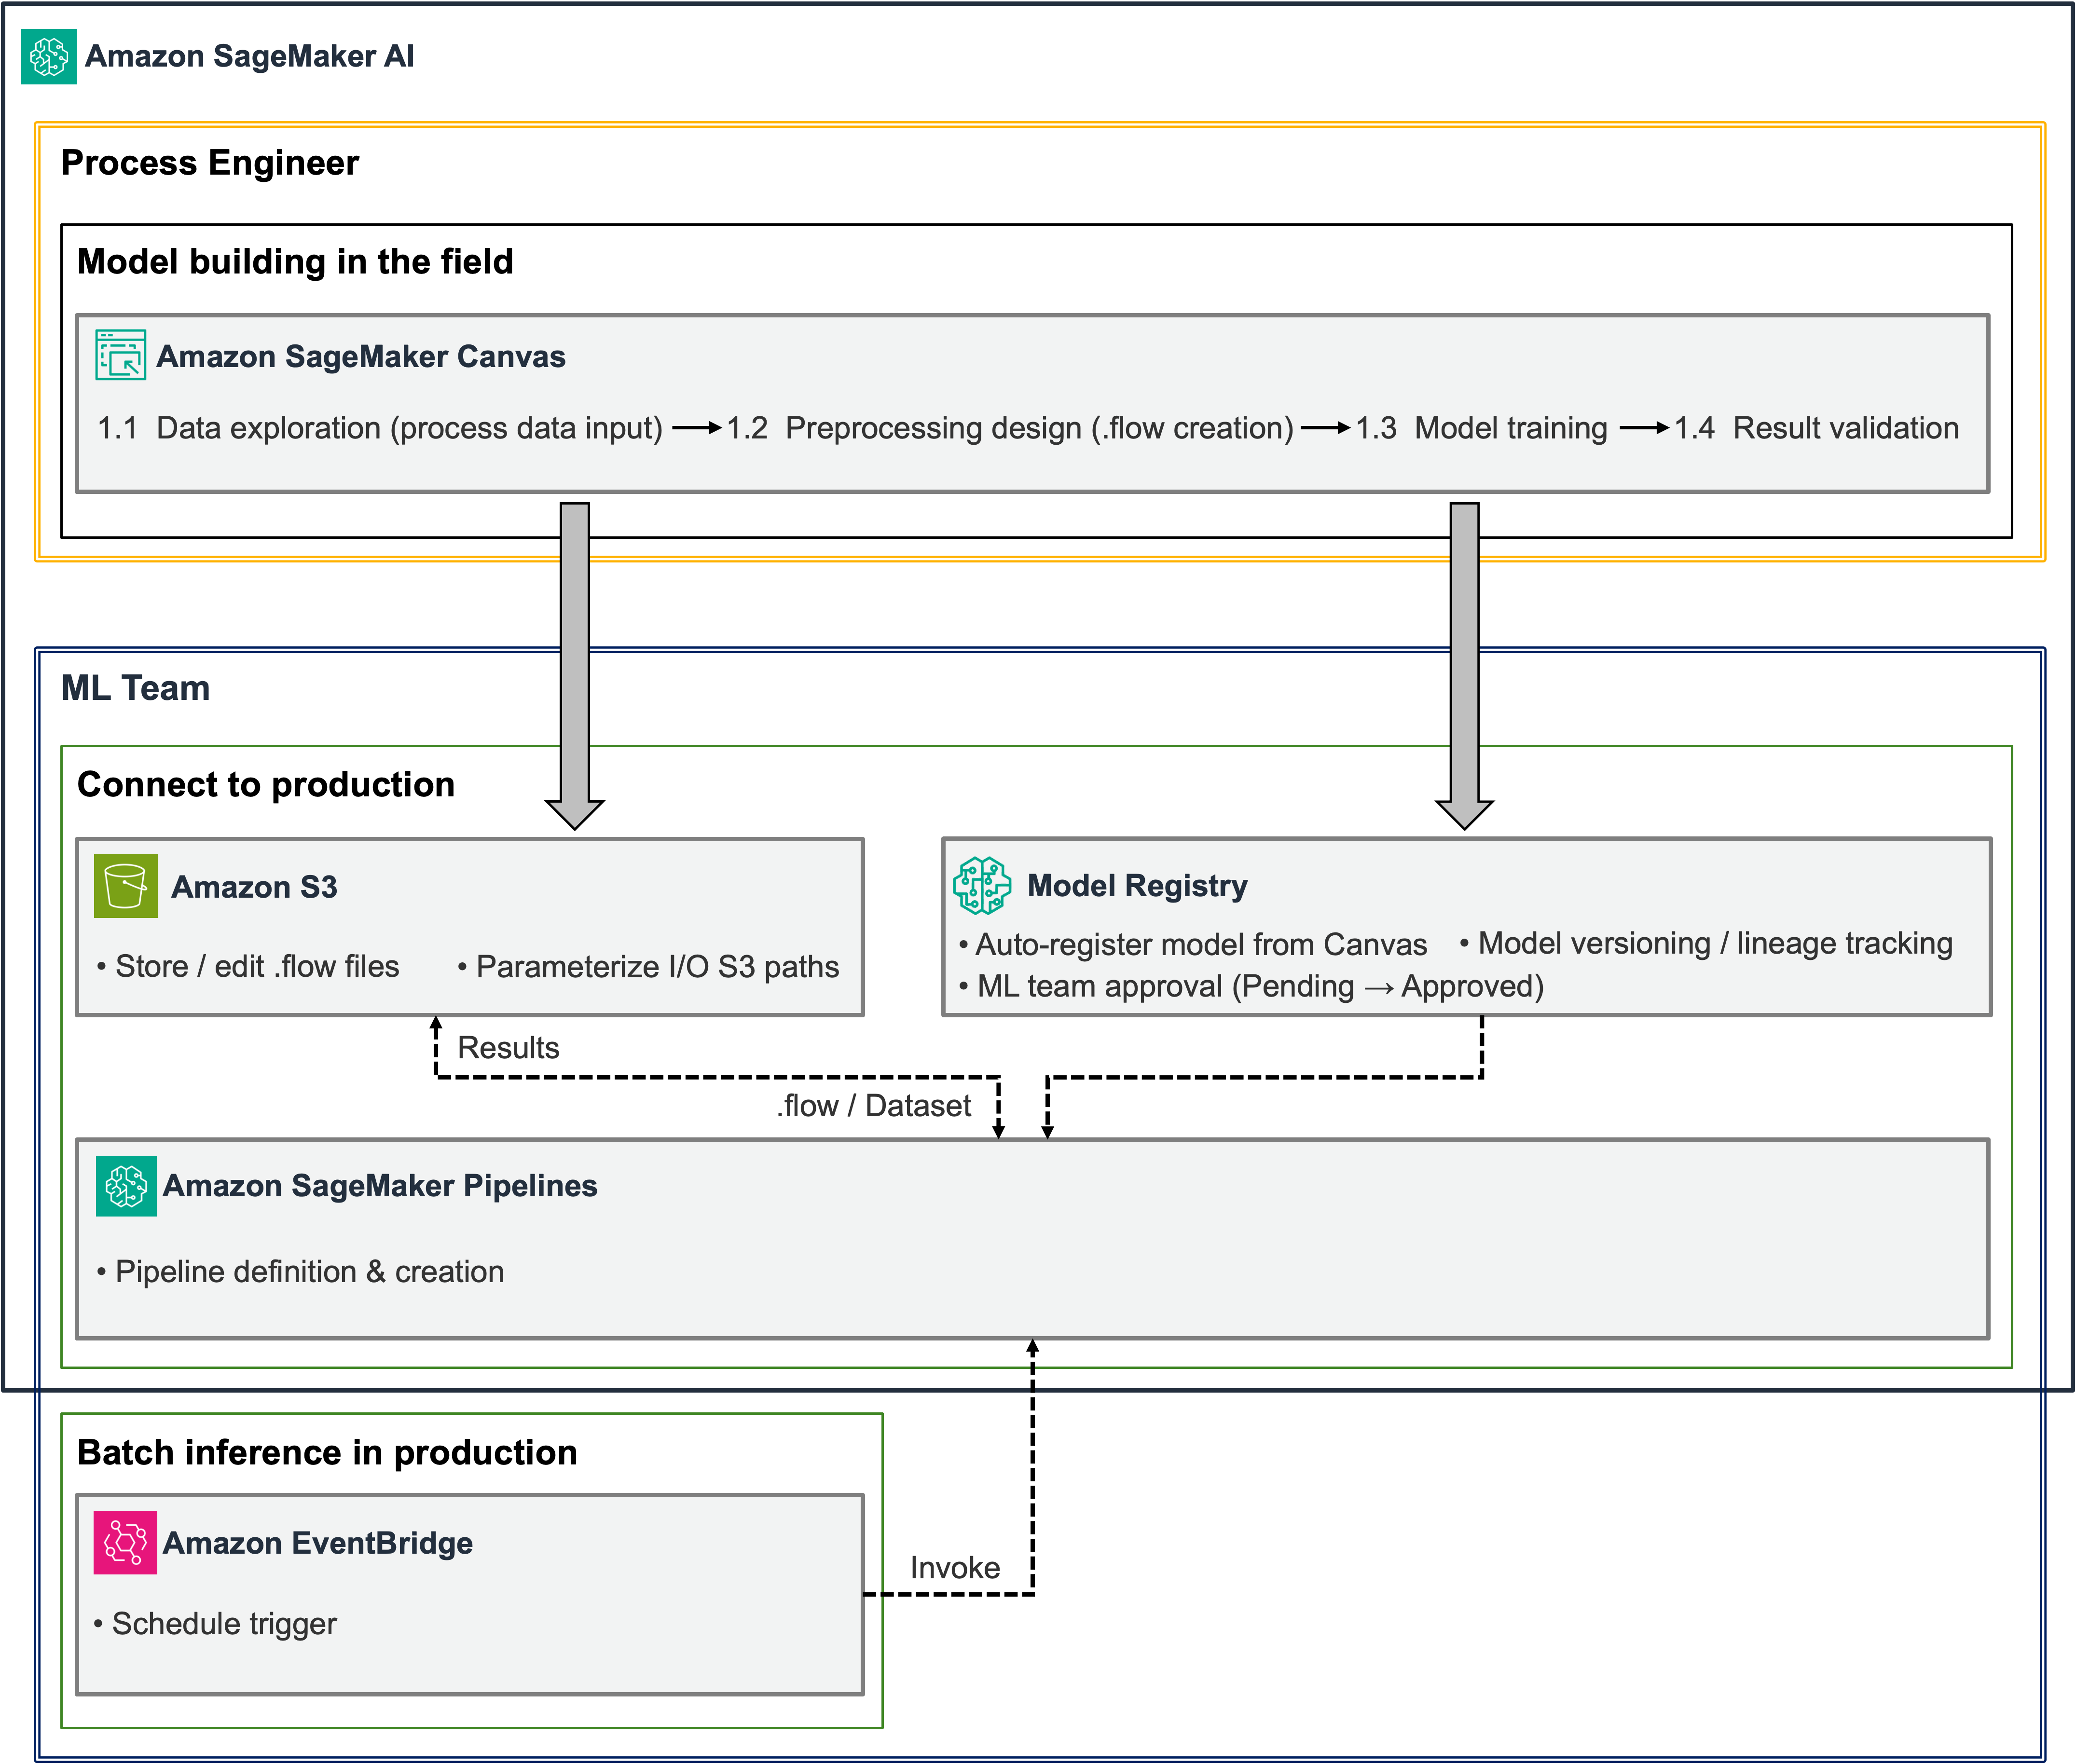
Production MLOps at GS Caltex with Amazon SageMaker Canvas, part 1

GS Caltex connects Amazon SageMaker Canvas to Amazon SageMaker Pipelines so process engineers' no-code models run in production. This post shows how ML engineers reuse validated preprocessing flows and models, cutting deployment from about a week to a few hours and running batch inference every 30 minutes.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Malav Shastri SI

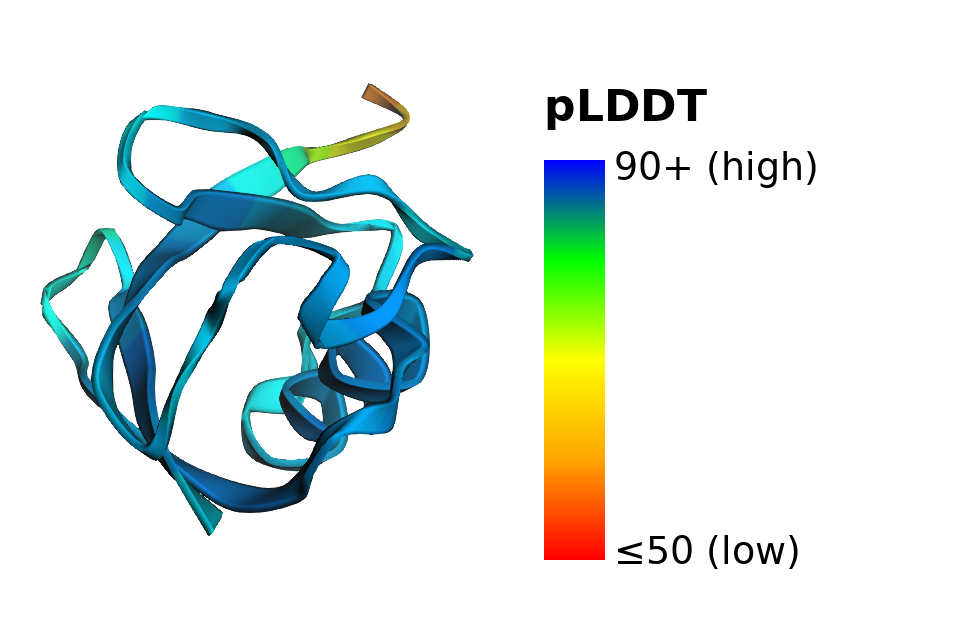
OpenFold3 on Amazon SageMaker JumpStart: Predict biomolecular structures

Deploy OpenFold3-preview from Amazon SageMaker JumpStart to predict 3D structures of proteins, DNA, RNA, and ligand complexes in your own AWS account. The post covers asynchronous inference, multi-GPU parallelism, bringing your own MSAs for accuracy and privacy, and scaling to zero to reduce cost.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Shantanu Tripathi SI

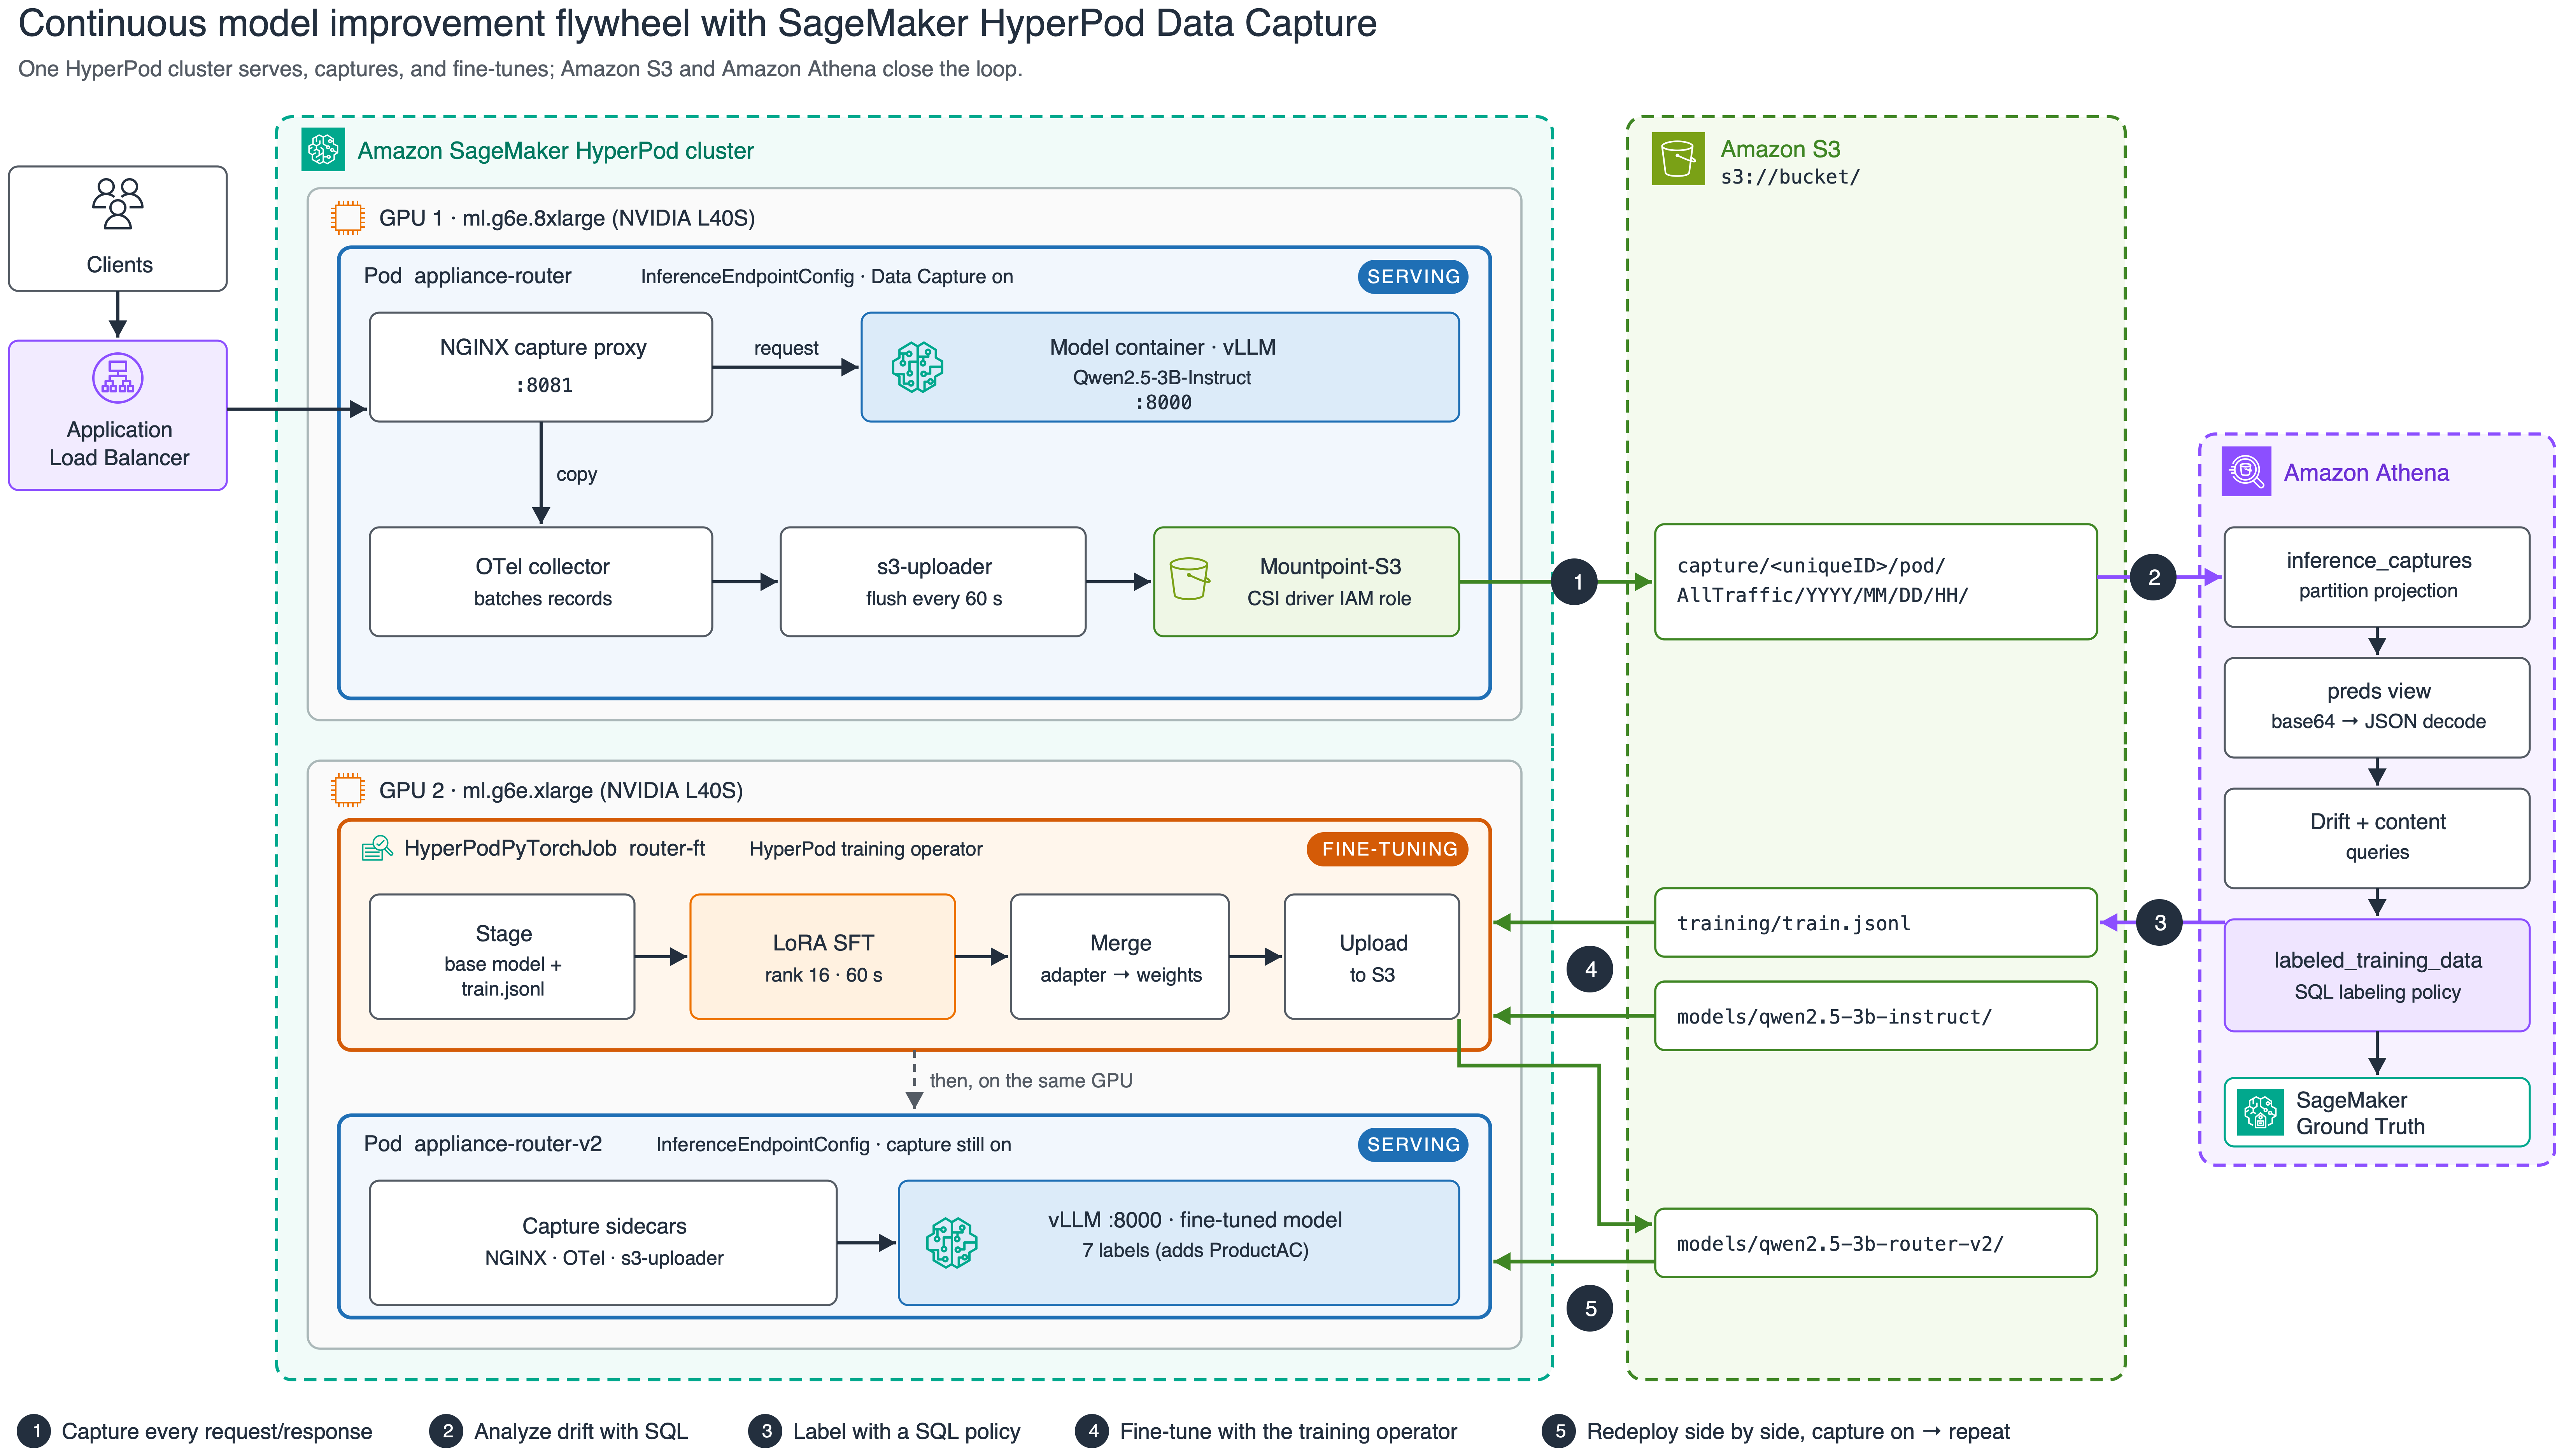
Build a model improvement flywheel with Amazon SageMaker HyperPod Data Capture

Amazon SageMaker HyperPod Data Capture records live inference inputs and outputs to Amazon S3. This post walks through one end-to-end example: capturing a support router's production traffic, surfacing a new-product blind spot with Amazon Athena, fine-tuning on the captured data with the HyperPod training operator, and measuring the before-and-after lift.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Siddharth Senger SI

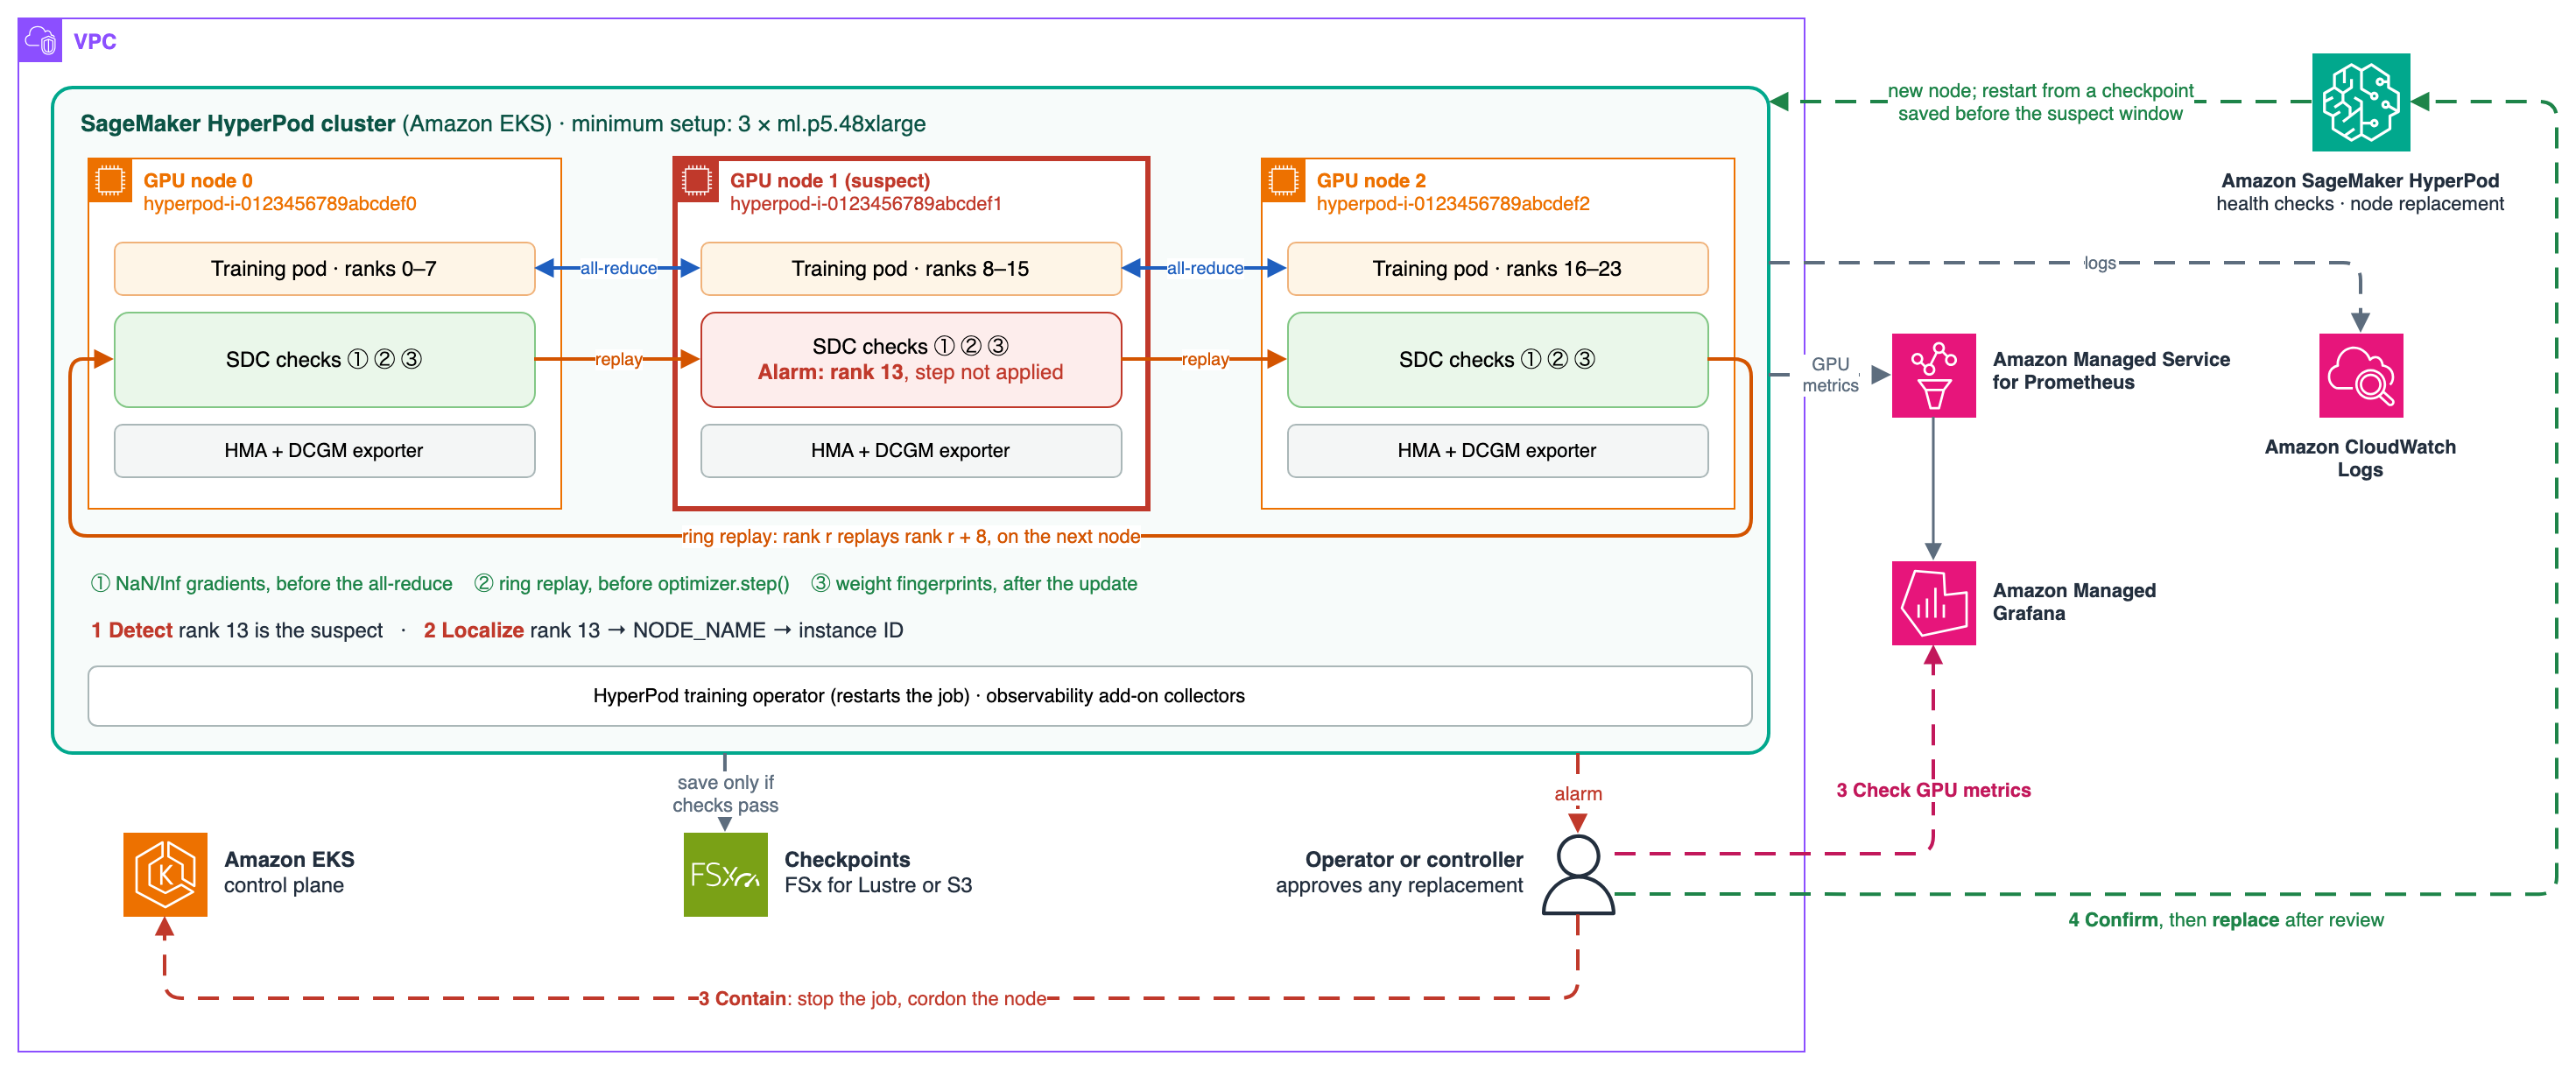
Detecting and recovering from silent data corruption on Amazon SageMaker HyperPod

Silent data corruption is a GPU fault that returns wrong but plausible numbers with no error, quietly poisoning distributed training. This post adds three checks to a PyTorch DDP loop to detect it, localize the faulty node on Amazon SageMaker HyperPod, and hand the node to automatic recovery for replacement.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Victor Wang SI

Introducing usage-based pricing for Amazon SageMaker AI bidirectional streaming

AWS Marketplace now supports usage-based metering for Amazon SageMaker bidirectional streaming inference, so model providers can charge for what customers actually consume during a live stream. Deepgram is the launch partner, bringing usage-based speech-to-text and text-to-speech billing to AWS Marketplace.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Venu Kanamatareddy SI

NVIDIA Nemotron 3.5 Super VL is now available in Amazon SageMaker JumpStart

NVIDIA Nemotron 3.5 Super VL, a 120B-parameter multimodal vision-language model, is now available in Amazon SageMaker JumpStart. Deploy the NVFP4 or BF16 variant in a few steps, then run text, image, and video inference for document intelligence, computer-use agents, and multimodal agentic workloads.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Shantanu Tripathi SI

SageMaker Inference now supports Multi-Instance GPU to maximize GPU utilization for model endpoints

Amazon SageMaker Inference now supports GPU partitioning with NVIDIA Multi-Instance GPU (MIG), which divides one GPU into hardware-isolated partitions so you can run a different model in each or take a right-sized fraction of a newer accelerator. This post shows how two optional API fields place one model per partition, and what we measured against a whole older GPU.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog James Kim SI

How Amazon Marketplace evaluates content quality with Amazon SageMaker AI

Learn how Amazon Marketplace evaluates A+ Content quality at scale on Amazon SageMaker AI by rendering each product page as a single snapshot, scoring it with a vision-language model fused with OCR readability signals in a CatBoost classifier, and using SHAP to turn each decision into prioritized, actionable recommendations for selling partners.

Read at AWS Machine Learning Blog