Robotics: research

Journal articles, academic blogs, think-tank reports and papers in this section, newest first. Back to the news.

arXiv (research papers) Guillaume Bellegarda

Learning optimal gaits and styles for terrain-adaptive quadruped locomotion

Animals use many different gaits to locomote at different speeds across varying terrains. A longstanding question in biology and robotics is: which gait is best? This question is most often addressed from an energy-efficiency perspective on flat terrain, leaving open how the answer depends on terrain and on the criterion optimized. Here we show that gait optimality is determined jointly by terrain, performance metric, and velocity. We use deep reinforcement learning and…
Read at arXiv (research papers)

arXiv (research papers) Yao Zhang

Fast-JEPA: Advancing the Success-Latency Frontier for Latent World Models

Latent world models predict the outcomes of action sequences, but comparing candidate plans through recursive rollout remains expensive at test time. We introduce Fast-JEPA, a latent world model planning framework that advances the success-latency Pareto frontier of predictive search. Fast-JEPA reorganizes predictive computation to support effective action-sequence search at low planning cost. It constructs a goal-directed plan to guide search and directly predicts the…

Read at arXiv (research papers)

arXiv (research papers) Frédérick Martin

Multiple-Camera Tracking of Rigid Objects

In this paper we describe a method for tracking rigid objects using one or several cameras. The tracking process consists of aligning a 3-D model representation of an object with image contours by measuring and minimizing the image error between predicted model points and image contours. The tracker behaves like a visual servo loop where the internal and external camera parameters are updated at each new image acquisition. We study in detail the Jacobian matrix associated…

Read at arXiv (research papers)

arXiv (research papers) Ziyang Xu

From Sequence to Space: Explicit Spatial Belief with Vision-Language Distillation for Active Geo-Localization

Active geo-localization (AGL) asks an agent to navigate a small aerial search grid and reach a target specified by an aerial image, a ground-level photograph, or text. Existing methods align the goal modalities well, but they keep the navigation state inside a large sequential Transformer and train with a dense distance reward that uses the hidden goal location. This paper proposes EAGLE, an Explicit spatial-belief Agent for Geo-Localization and Exploration. Offline training…

Read at arXiv (research papers)

arXiv (research papers) Mingxi Zhou

Learning-Based System Identification for DVL-Constrained AUV Localization

Nowadays, most AUVs utilize Doppler velocity logs (DVLs) and inertial measurement units (IMUs) to achieve satisfactory dead-reckoning results. However, the DVL bottom lock may not be available in some scenarios, such as moving over a soft bottom or traveling further away from the seafloor beyond the DVL's range. As a result, the localization system solely reliant on the IMU data will experience significant drift. The relatively high cost of DVLs also inhibits multirobot or…

Read at arXiv (research papers)

arXiv (research papers) Jinkun Cao

Fast and Accurate Body Estimation in Pixels, World Space and Scenes

We present FAB (Fast and Accurate Body estimation), a human body estimator that jointly improves inference efficiency and body-recovery fidelity. Rather than predicting only parametric mesh-model parameters, FAB directly predicts human skeleton joints and dense surface points. In images, it predicts dense 2D and 3D body points alongside a parametric Momentum Human Rig (MHR) head, then fits SMPL in one learned pass followed by two Gauss-Newton steps. Its ViT-L student, FAB-L…

Read at arXiv (research papers)

arXiv (research papers) Yasuhiro Fukuoka

Design and Validation of a Telescopic Chassis-Assisted Stair-Climbing Mechanism for Powered Wheelchairs

We propose a simple stair traversal mechanism that augments a four-wheel wheelchair with an auxiliary telescopic chassis actuator. The proposed mechanism provides the following key contributions during stair ascent: (A) enhanced safety by ensuring that either the front or rear wheels remain stationary at all times; (B) primary reliance of the required force and mechanical work on the telescopic chassis rather than the wheels; (C) insensitivity of the required force and…

Read at arXiv (research papers)

arXiv (research papers) Wai Ka Sun

Collision-Free Is Not Enough: Passage-Conditioned Navigation for Wheeled-Legged Robots

A collision-free detour can still bring a legged robot to the next stair or ledge a few centimetres or degrees off, and a fixed locomotion skill, factory or learned, can stall or fall. Existing methods prevent this with a robot model or extensive trial and error, but on a new site with unknown skills neither is available, so they cannot be used. We find that a single 27-minute teaching session already supplies what these methods have to derive or learn: for every stair and…

Read at arXiv (research papers)

arXiv (research papers) Xingyi Wang

ECHO: In-Context Behavior foundation model for Humanoid Whole-Body Control

Humanoid behavior foundation models (BFMs) acquire diverse skills through large-scale motion imitation and massively parallel reinforcement learning, yet broad behavioral capability does not ensure precise execution across physical conditions. Without distinguishing the underlying dynamics, policies may favor conservative compromises over environment-specific precision. We introduce ECHO, an in-context BFM that turns interaction experience into environment-specific control…

Read at arXiv (research papers)

arXiv (research papers) Haisen He

Hindsight Self-Distillation: Teaching Robots to Act from the Present

A robot must choose an action before it can see the outcome. In a recorded demonstration, later camera frames show what happened after the robot moved. Hindsight Self-Distillation (HSD) uses these later frames to teach a policy what to extract from current images. During training, a teacher sees both the current and later frames, while a student sees the current frames. They share a visual encoder and an action predictor. Each branch summarizes its images with a small set of…

Read at arXiv (research papers)

arXiv (research papers) Andreas Müller

On the Hamel Coefficients and the Boltzmann-Hamel Equations for the Rigid Body

The Boltzmann-Hamel (BH) equations are central in the dynamics and control of nonholonomic systems described in terms of quasi-velocities. The rigid body is a classical example of such systems, and it is well-known that the BH-equations are the Newton-Euler (NE) equations when described in terms of rigid body twists as quasi-velocities. It is further known that the NE-equations are the Euler-Poincare, respectively, the reduced Euler-Lagrange equations on SE(3) when using…

Read at arXiv (research papers)

arXiv (research papers) Xudi Ge

TipDex-VTLA: Learning When to Refine Actions with Touch for Dexterous Manipulation

Changes in illumination can induce action drift in dexterous manipulation even when the physical state remains unchanged. Although existing vision--tactile--language--action (VTLA) policies incorporate tactile feedback, when and how touch refines actions under changing visual conditions remains challenging. We introduce \textbf{TipDex-VTLA}, a VTLA policy that combines estimated visual action reliability and tactile forecast verification to regulate execution-time…

Read at arXiv (research papers)

arXiv (research papers) Kai Shi

LeCompass: Task-Level Execution through State-Indexed Interfaces

Action-conditioned joint-embedding predictive architectures (JEPAs) offer a foundation for predictive decision-making by modeling the consequences of actions in representation space. Yet evaluating local reachability in latent space does not by itself provide a task-level execution interface: intermediate targets must be generated, local inference has finite budgets, and execution requires spatial feedback and persistent interaction state. We introduce LeCompass, a…

Read at arXiv (research papers)

arXiv (research papers) Xu Pan

CauSyncVLA: Causal Latent World Modeling for Asynchronous Robot Control

Vision-Language-Action (VLA) policies must react while visual inference is still running. Overlapping computation and execution reduces waiting, yet leaves perceptual memory stale and successive action chunks disconnected. We present CauSyncVLA, an asynchronous dual-system controller that aligns perceptual-memory prediction and trajectory correction with actual robot execution. Rather than forecasting pixels or physical states, a Causal Latent World Model predicts current…

Read at arXiv (research papers)

arXiv (research papers) JiaXu Chee

GNetSS: Towards Learning GNSS Corrections without Ground Truth

We present GNetSS, a self-supervised GNSS position correction framework that improves the robustness of single point positioning (SPP) without requiring ground-truth locations for training. GNetSS combines a transformer-based network with a deterministic differentiable positioning solver. The network predicts satellite-wise pseudorange corrections by modelling inter-satellite geometry and temporal context, while the solver converts these corrected measurements into receiver…

Read at arXiv (research papers)

arXiv (research papers) Chenyuan Zhou

A$^2$-VLA: Adapting Vision-Language-Action Policies to New Tools through Agentic Affordance Discovery

Tools with different shapes can have similar functions, but transferring manipulation skills across tools requires understanding how tool geometry relates to the specific task and adjusting the manipulation strategy accordingly. The key challenge is to discover the common affordances that contribute to task completion across different tools and verify whether they support new tools in performing similar work. We present A$^2$-VLA, a tool-adaptation framework that combines an…

Read at arXiv (research papers)

arXiv (research papers) Ye Lin Tun

Beyond Easy Clients: Difficulty- and Improvement-Aware Aggregation for Federated Reinforcement Learning in Robot Navigation

Federated reinforcement learning enables a fleet of robots to jointly learn a shared navigation policy without exchanging raw experience. In practice, however, the robots rarely operate in the same conditions: an open aisle is far easier to navigate than a cluttered room, and takes less learning to master. Standard federated aggregation rules ignore this. Uniform averaging weights every client equally, whether or not it is still learning, and weighting by episode return is…

Read at arXiv (research papers)

arXiv (research papers) Chengkai Xu

PAD: Policy-Aware Data Valuation for Autonomous Driving

End-to-end autonomous driving increasingly depends on scaling training demonstrations, yet data growth does not guarantee proportional gains. However, additional data do not guarantee better policies: a demonstration that benefits one planner may be redundant or harmful to another. Existing curation methods typically infer data value from intrinsic sample properties or training-dependent proxies that do not measure downstream policy utility. To address this, we introduce…

Read at arXiv (research papers)

arXiv (research papers) Anh Dao

LoopedWAM: Looped World Action Models for Elastic Inference

World action models (WAMs) couple generative video modeling with robotic action prediction but typically require large video and action transformers, limiting deployment efficiency. We present LoopedWAM, a compact WAM that recurrently applies a shared six-block core in each expert, executing 30 transformer layers while storing only 12 blocks per expert. To account for their asymmetric inference costs, the video and action experts can operate at different depths: visual…

Read at arXiv (research papers)

arXiv (research papers) Zezhi Liu

GraF-VTA: Neuro-Symbolic Trajectory Generation from Vision and Temporal Logic via Graph-Based Fusion

Robotic planning from visual observations and signal temporal logic (STL) requires grounding task requirements in scene evidence while adapting plans to execution feedback. We present GraF-VTA, a graph-based framework that extends Vision-TL-Action with structured task representations, causal observation history, and closed-loop trajectory generation. Bidirectional cross-attention fuses STL syntax tokens with visual features, while an optional frozen automaton embedding…

Read at arXiv (research papers)

arXiv (research papers) Yuseon Choi

FlashX: Scaling Robotic Experience Reuse for Embodied Agents with CBA-Based NAND Flash

Embodied agents are emerging as a promising paradigm for complex robotic tasks, leveraging Vision-Language-Action (VLA) and World Action Models (WAMs) to generate actions through Diffusion Transformer (DiT)-based iterative denoising. However, existing models often struggle to generalize to out-of-distribution (OOD) environments. We observe that retrieving successful experiences and using them to warm-start denoising enables agents to better adapt to unfamiliar situations…

Read at arXiv (research papers)

MIT News AI Adam Zewe | MIT News SI

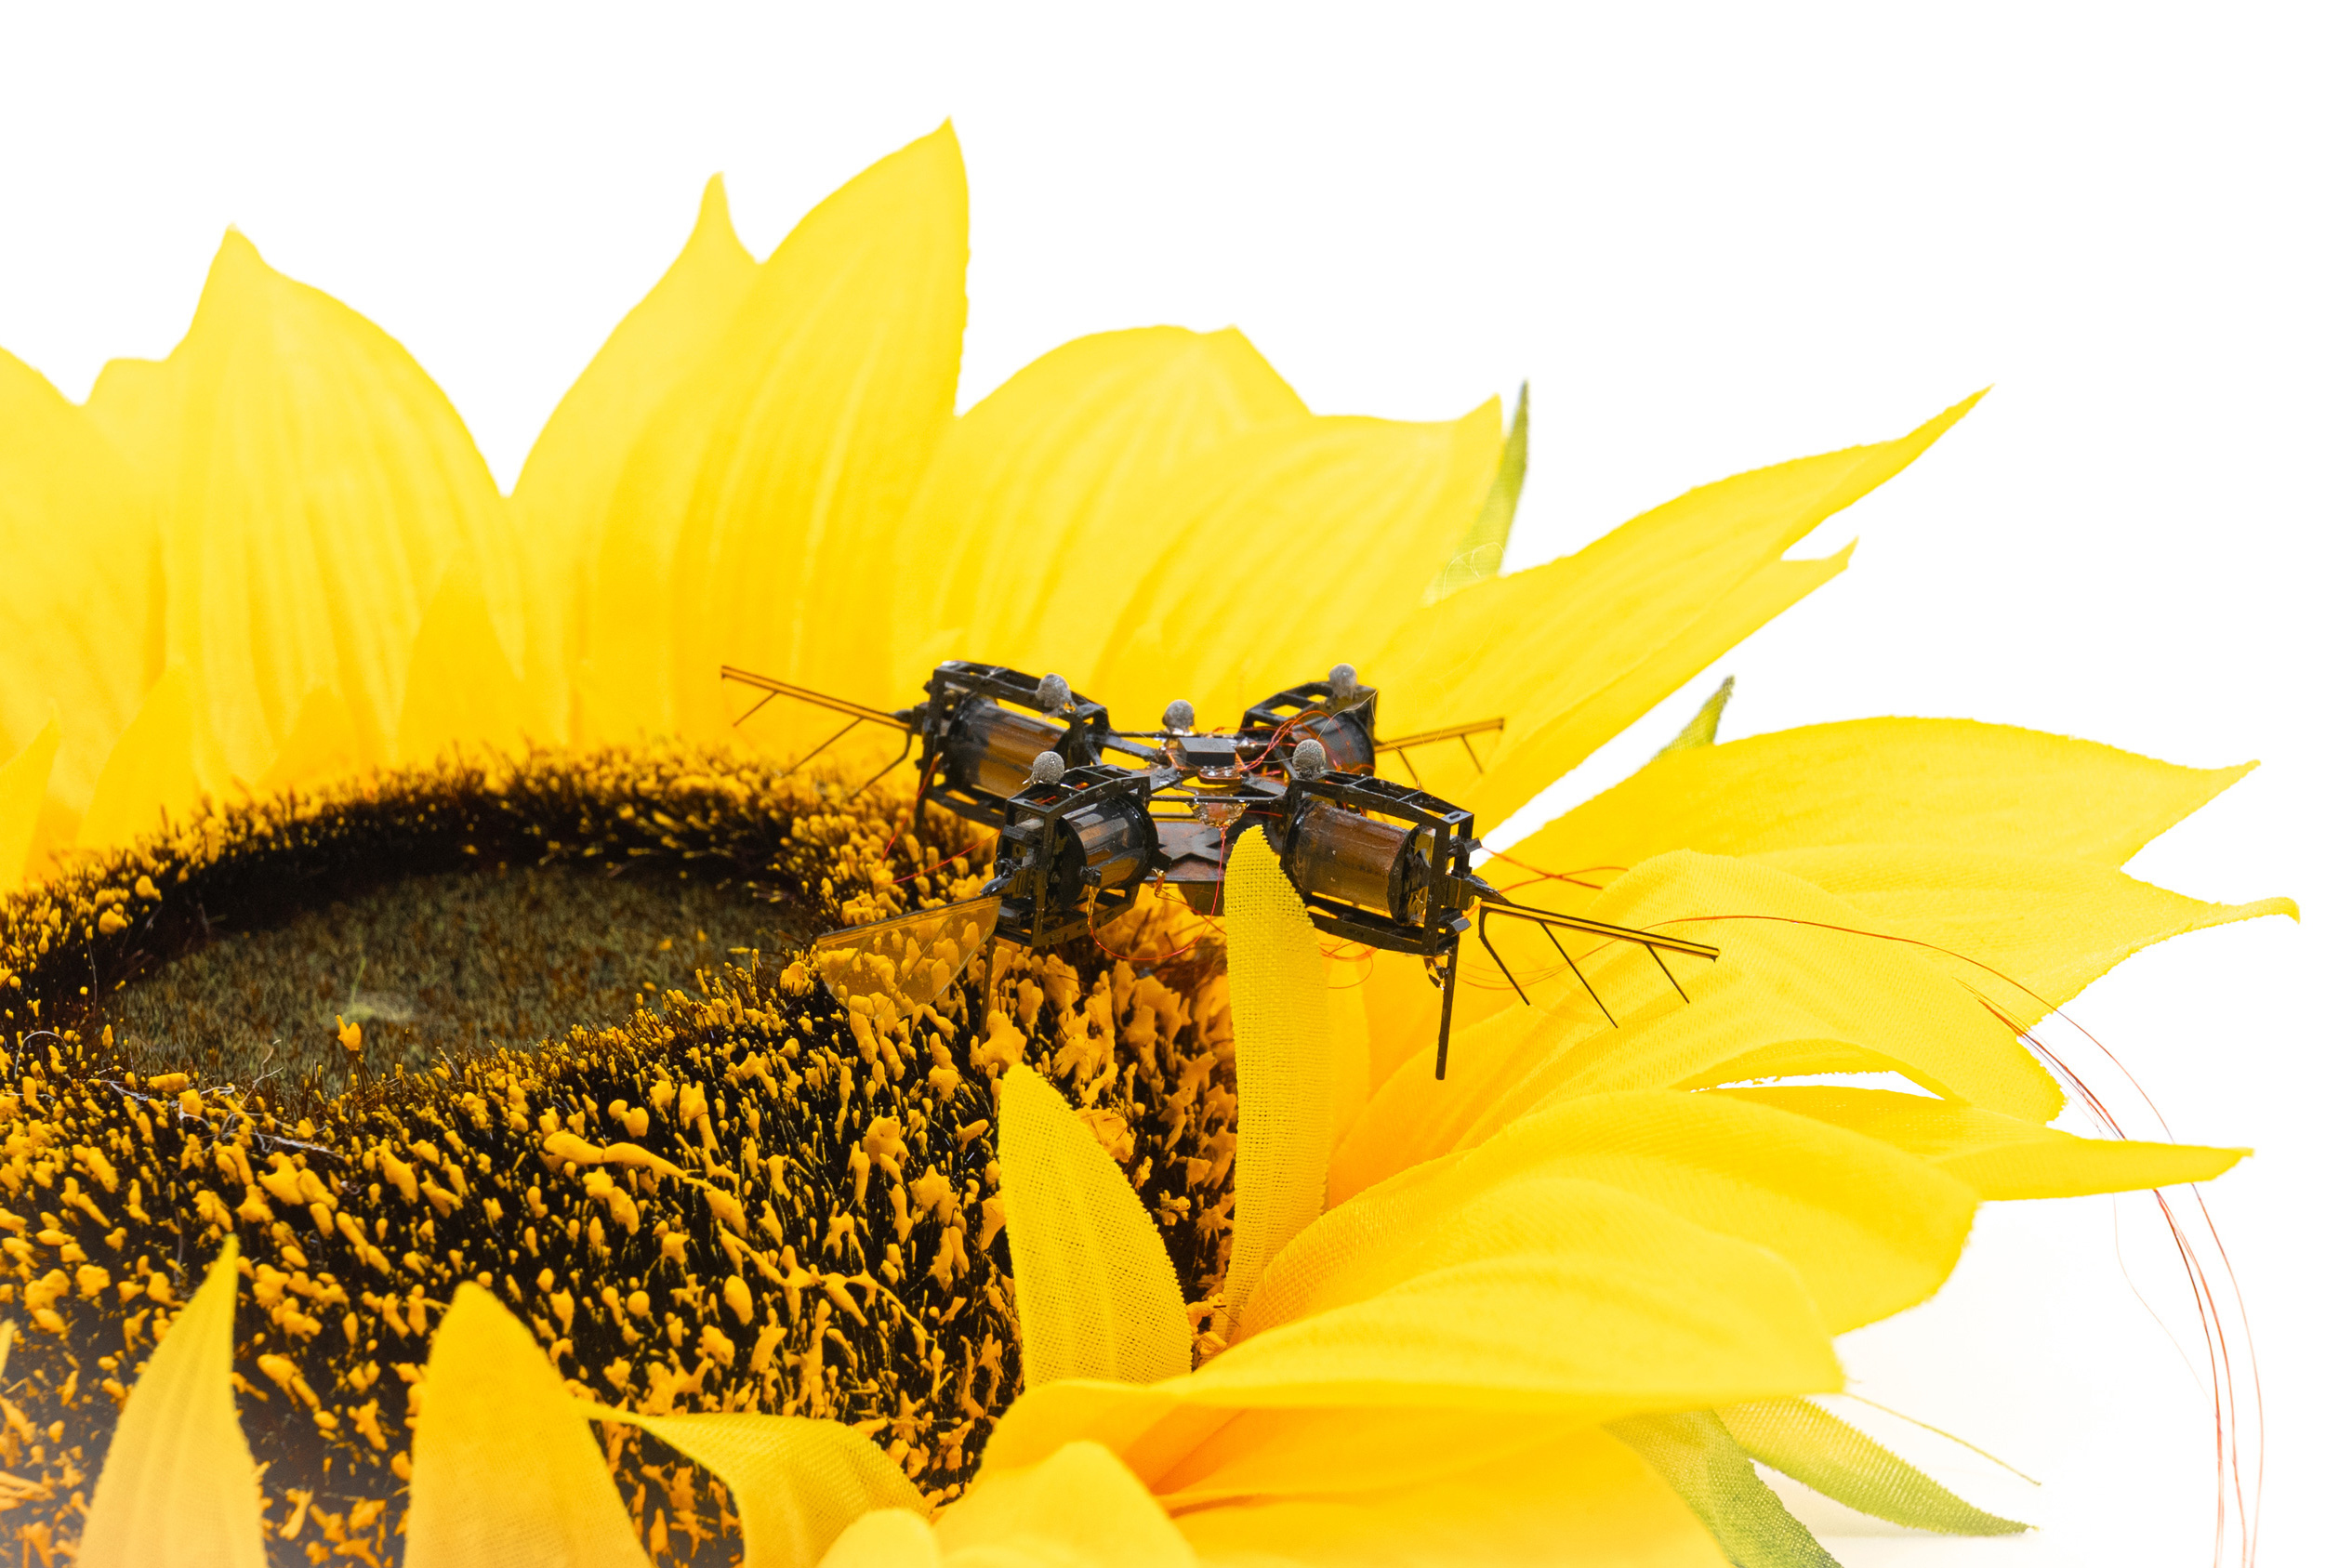
This featherweight, flying robot carries its own sensors and computers

The speedy microrobot flies without an attached motion-capture system, moving it closer to applications like agriculture or industrial surveillance.

Read at MIT News AI

arXiv (research papers) Junjie Ye

$Z$-sight: Unifying Vision-Language-Action and Latent World Modeling

We introduce $Z$-sight, a unified robot foundation model that couples vision-language-action (VLA) and generative latent world modeling. Video-based world action models (WAMs) show the value of joint future-and-action generation for control, yet inherit the heavy cost of video generators. Recent latent-space policies avoid pixel generation, yet typically align intermediate features or rely on frozen target encoders, decoupling future prediction from the VLM's native feature…

Read at arXiv (research papers)

arXiv (research papers) Yupeng Zheng

Phoenix: Learning Scene Structure Representations for Generalizable World-Action Models

World-action models jointly predict future observations and actions, yet reconstruction-oriented visual representations do not explicitly emphasize the spatial relationships and object-state changes needed for manipulation. We introduce Phoenix, which learns representations of scene structure for world-action modeling. Specifically, Phoenix Encoder enriches DINOv3's general visual semantics through dual-teacher distillation of geometric and spatiotemporal semantic knowledge…

Read at arXiv (research papers)

arXiv (research papers) Zi-ang Cao

Grana: Compositional Reward Modeling for Long-Horizon Robot Manipulation

Robot reward modeling faces two challenges: generalizing across tasks and accurately tracking progress in long-horizon manipulation. General-purpose reward models demonstrate broad task transfer, but transfer from short-task pretraining to long-horizon tasks remains underexplored. Long-horizon progress models often rely on task-specific subtask classifiers or fixed action vocabularies, limiting the reuse of learned progress knowledge when adapting to new tasks. To address…

Read at arXiv (research papers)

arXiv (research papers) Yash Jangir

Render the Robot, Generate the World: One Video World Model Across Embodiments

Predicting the consequences of an agent's actions requires modeling both the body's motion and the environment's response. Most video world models attempt to learn both from numerical actions, even though geometry and kinematics already specify the intended motion. We introduce Doppel, an embodiment-agnostic video world model conditioned on camera-aligned renderings of future body configurations and numerical action trajectories. By explicitly providing the intended motion…

Read at arXiv (research papers)

arXiv (research papers) Viridiana Luna-Zempoalteca Steven

Teleoperated Haircutting with Delay Compensation and Passivity-Based Control for Unilateral Internet Teleoperation under Real Communication Uncertainties

Robotic haircutting requires accurate motion execution and reliable communication to safely reproduce the operator's commands. Internet-based teleoperation is a key enabling technology to remotely perform precise manipulation tasks such as haircutting. However, communication uncertainties, including variable transmission delays and packet jitter, degrade synchronization between the master and slave systems and affect tracking performance. This paper presents a unilateral…

Read at arXiv (research papers)

arXiv (research papers) Beyazit Yalcinkaya

Learning to Interact in Multi-Agent Self-Play for Controllable Autonomous Driving Scenario Generation

Large-scale, multi-agent self-play trains robust driving policies effectively in simulation, but controlling these models to generate specific, safety-critical edge cases remains a key challenge. Existing goal-conditioned self-play frameworks rely primarily on static map-location goals and fail to reliably produce complex agent interactions such as aggressive tailgating or adversarial cut-offs. These agent interactions are necessary for rigorous autonomous vehicle (AV)…

Read at arXiv (research papers)

arXiv (research papers) Chenjie Zhao

NereidVLA: Learning to Understand and Navigate the Underwater World

Underwater navigation requires translating visual spatial cues into motion, yet marine vision-language datasets rarely include paired robot trajectories. We present NereidVLA, a vision-language-action model that transfers marine spatial knowledge to language-conditioned 3D navigation. We first train Sea2Know on approximately two million marine examples to learn target grounding, spatial relations, and scene structure without paired robot-motion supervision. We then adapt it…

Read at arXiv (research papers)

arXiv (research papers) Cameron Mehlman

Communications-free Collective Intelligence Via Allocentric Belief

A team of skilled card players share no information amongst each other, and yet still are able to coordinate their play by watching the same players and reading the same tells. Autonomous systems have failed to exploit this logic, relying instead on explicit communication or complex state estimation schemes that can fail when it matters most. Without it, decentralized agents diverge in their world beliefs, and coordination collapses. Here we show that anchoring all agents to…

Read at arXiv (research papers)

Older stories