Results for “model”

arXiv (research papers) Cheol-Hui Lee SI

A Cardiorespiratory Foundation Model Pretrained on Ten Physiological Signals for Perioperative and Critical Care

Arterial, venous, pulmonary artery and intracranial pressures and ventilator waveforms guide decisions in operating rooms and intensive care units, yet foundation models for physiological waveforms have been built almost entirely on the electrocardiogram and photoplethysmogram. We present CARMEN, a single encoder pretrained without labels on ten cardiorespiratory waveforms (2.27 million modality-hours). CARMEN accepts any combination of co-recorded signals from 10 s to 5…

Read at arXiv (research papers)

arXiv (research papers) Wentao Zhang SI

Same Task, Different Statement: When and How Reformulation Helps LLM Problem Solving

When people face a hard problem, they often restate it in a clearer way before solving it. We study whether the same habit helps large language models by rewriting the statement of a problem. A legal rewrite must keep the meaning, the constraints, and the correct answer unchanged. We test three kinds of rewrites. Decomposition makes hidden subgoals explicit. Typed Reformulation casts the task into a more suitable solving frame. Concept Reduction removes surface detail and…

Read at arXiv (research papers)

arXiv (research papers) Natalia Fischl-Lanzoni SI

Breaking Bad: "Going Badly" Activations Drive Reward Hacking

Humans often cheat when a task is going badly and a goal feels out of reach. We explore and validate an analogous idea in language models: they exhibit a similar internal pressure state that precedes reward hacking. Using everyday stories (crucially, without any hacking examples), we extract a task badness direction that rises as failures accumulate across three models we study (Qwen3.6-27B, GPT-OSS-20B, and Gemma-4-31B). On impossible or difficult coding tasks, task badness…

Read at arXiv (research papers)

arXiv (research papers) Guofu Liao Security

VRMaaS: Verifiable Reward-Model-as-a-Service for Trustworthy LLM Alignment

Reward models (RMs) are increasingly deployed as service components in LLM alignment pipelines, where payment, audit, moderation, and governance workflows act on the scores they return. An inference proof alone does not show whether a score belongs to the intended request, model checkpoint, numerical configuration, and verifier: in a controlled comparison that isolates the accepted statement from prover scale, a generic inference proof wrapped for on-chain checking remains…

Read at arXiv (research papers)

arXiv (research papers) Qixuan Jin Security

Poison-then-Hide: Finetuning-Activated Backdoor Attack on Pretrained Vision Encoders

Backdoor attacks threaten the integrity of machine learning models by allowing attackers to control model behavior through triggers. Models can be compromised during finetuning by backdoor attacks through either poisoned data or adversarial training objectives. Because existing finetuning-activated attacks assume limited domain shift or frozen encoder layers, they often fail under full-model finetuning. We target a stealthy finetuning-activated attack where a dormant…

Read at arXiv (research papers)

arXiv (research papers) Jie Ren SI

Early Signals, Strong Decisions: Prefix-Guided Sampling for Parallel Test-Time Scaling

Parallel test-time scaling (TTS) has been shown to enhance reasoning in large language models by generating and aggregating multiple independent reasoning paths. Internal confidence scores can further improve this process by identifying paths of varying quality. However, existing methods remain computationally inefficient, as low-quality paths are fully expanded before being evaluated. In this work, we aim to improve the use of internal confidence signals for better model…

Read at arXiv (research papers)

arXiv (research papers) Musa Cim SI

Termination Lag: Coding Agents Solve Early but Stop Late

Coding agents can solve a task well before they stop working on it. We characterize \emph{termination lag}--the number of steps between an agent's first correct patch and the end of its run--across five models, two agent frameworks, and three SWE-bench datasets by recording and testing every distinct repository patch generated during execution. Our analysis reveals that 38--82% of successful runs achieve a correct solution on their initial source-code edit. However, agents…

Read at arXiv (research papers)

arXiv (research papers) Tech policy

The hidden solar cost of urban unfamiliarity

Unfamiliar walkers may follow the shortest route and miss nearby shade, indoor passages and multilevel connections. We define the resulting hidden solar cost as the direct-sun exposure avoidable through shade-informed routing without substantial detours. We developed a time-specific three-dimensional model of Hong Kong Island that combines indoor and outdoor walking networks with building geometry, vegetation mapped by light detection and ranging (LiDAR), and solar position…

Read at arXiv (research papers)

arXiv (research papers) Jaerock Kwon SI

The Posterior-Prior Epistemic Gap: When World Model Imagination Fails to Carry Task-Relevant Signals

Model-based planners that roll out imagined futures assume the transition model faithfully propagates task-relevant signals---a property rarely measured directly. In a single-seed case study of a Recurrent State Space Model world model with active-inference planning in the CARLA driving simulator, we identify a \textbf{posterior-prior gap}---posterior (observation-filtered) states retain obstacle information that imagined rollout states progressively lose: a supervised…

Read at arXiv (research papers)

arXiv (research papers) Bhoj Rani Soopal Security

Stress-Testing Sandbagging Detection Under Adaptive Attack

Developers, auditors and researchers read evaluation scores as evidence of what a model can do. A model that sandbags, scoring low on purpose while keeping the capability, turns a low score into false reassurance. Sandbagging detectors are usually tested once against a fixed attack, but a real attacker sees what gets flagged and adapts. We build sandbagging models by fine-tuning small open-weight models to fail math word problems (GSM8K) they can otherwise solve, but only…

Read at arXiv (research papers)

arXiv (research papers) Binghang Lu SI

RSI-PDEbench: A Benchmark for Self-Improving Agents in PDE Solving

Identifying and solving partial differential equations (PDEs) from sampled solution data often requires substantial expert effort in equation discovery, coefficient estimation, and numerical solver configuration, especially under noise and distribution shifts. Can large language model (LLM) agents automate this workflow accurately and efficiently? To investigate this question, we introduce \bench{}, a benchmark of 1,001 cases spanning 42 equation templates, including both…

Read at arXiv (research papers)

The Japan Times

Microsoft presses Trump to scuttle ban on Chinese data center tech

At stake are imports new models of Chinese optical transceivers, which allow data to travel over fiber-optic cables within data centers.

Read at The Japan Times

arXiv (research papers) Craig Gidney

CSS Circuits: useful quantum circuits that can be simulated with $O(1)$ cost per gate

"CSS circuits" are quantum circuits generated by $X$, $Z$, $M_X$, $M_Z$, and CNOT gates. Although CSS circuits are extremely restrictive, they can implement important quantum protocols like teleportation, error correction, and entanglement purification. We present a simple CSS circuit simulator that uses $O(1)$ work per gate. The simulator corresponds to a local hidden variable model, so we use Bell inequalities to prove the simulator can't also support Hadamard gates, CZ…

Read at arXiv (research papers)

arXiv (research papers) Qi Zhang SI

Emergent Vision-Shaped Thinking in Text-Only Reasoning through Multimodal Training

Does multimodal training shape how a language model thinks, even when the input is text only? We test this with targeted causal ablations across 10 multimodal configurations from 6 model families, with matched text-only backbones and cross-family transfer controls. We contrast spatial-imagery tasks that invite mental scene construction with symbol-manipulation tasks solvable by symbolic rules alone. We identify a vision-language axis in hidden-state space and ablate its…

Read at arXiv (research papers)

arXiv (research papers) Richard J. Young SI

Do Large Language Models Show Racial and Sex Bias in Pain Management? A Counterfactual Audit of GPT, Claude, Gemini, Llama, DeepSeek and Qwen

Racial and ethnic minority patients receive less pain treatment than non-Hispanic White patients, and large language models (LLMs) used as medical AI could reproduce that bias. Prior audits tested a few proprietary models, stated race explicitly and rarely measured the models' own response instability. In exploratory, non-preregistered analyses, Study 1 had four open-weight LLMs assess six acute-pain vignettes in every combination of four races and two sexes, with identity…

Read at arXiv (research papers)

arXiv (research papers) Kunze Jiang SI

Hint-Informed Self-Distillation for Reasoning Segmentation

Reasoning segmentation requires identifying the target referred to by a query among visually similar objects, yet trajectory-level rewards cannot directly indicate which tokens provide relevant visual evidence. We propose Hint-Informed Self-Distillation (HISD), which uses target-disambiguation evidence for token-level credit assignment. An external model generates Segment Hints offline from training images, queries, and ground-truth target annotations, organizing target…

Read at arXiv (research papers)

arXiv (research papers) Zhisheng Zhang Security

Speech Tokenizers are Vulnerable: Transferable Semantic Attack and Robust Tokenizer

Speech tokenizers serve as speech front ends, encoding input speech signals into representations for downstream models, such as automatic speech recognition (ASR) systems and large audio-language models (LALMs). In this paper, we find that speech tokenizers are fragile at the semantic level: small perturbations can disrupt their semantic encoding process and consequently cause severe degradation in downstream ASR and LALM performance. To study this vulnerability, we propose…

Read at arXiv (research papers)

South China Morning Post Biman Mukherji Geopolitics

India moves to retain military recruits amid border risks and troop gaps

Thousands of Indian soldiers who would otherwise leave the military after four years will be kept on duty, in a major rethink of the country’s controversial recruitment model as New Delhi grapples with persistent manpower shortages and security concerns along its borders with China and Pakistan, analysts say. Under revisions approved by the federal cabinet last Tuesday, more than 18,000 recruits from the inaugural batch of the Agnipath (“Path of Fire”) scheme will be granted…

Read at South China Morning Post

arXiv (research papers) Zahraa Selim SI

Edge-Native Multimodal RAG: Hardware-Aware Quantization and Architectural Optimization for Consumer GPUs

Deployment of retrieval-augmented generation (RAG) for Edge-AI is constrained by memory and bandwidth limitations. A standard 7B parameter model consumes 14 GB Video Random Access Memory (VRAM) in half-precision (FP16), precluding co-location of vector indices and Key-Value (KV) caches. This paper presents an engineering integration and empirical evaluation of a multimodal RAG framework optimized for consumer-grade Turing hardware (e.g., NVIDIA Tesla T4). Our system-level…

Read at arXiv (research papers)

arXiv (research papers) Nhut-Minh Ho Security

CuEVM: Scaling Smart Contract Execution on GPUs

Smart contracts on Ethereum blockchain process transactions worth billions of US dollars daily. They run on top of Ethereum Virtual Machine (EVM) which executes transactions sequentially. This execution model creates a performance bottleneck, especially for new blockchain workloads with large numbers of transactions, such as security testing. We present CuEVM, a GPU-native and semantically complete EVM execution engine that treats transaction execution as a massively…

Read at arXiv (research papers)

The Register Simon Sharwood SI

Australia may make knowingly selling unsafe AI a crime

New regulator will require modelmakers to test and allow inspection, but not much

Read at The Register

arXiv (research papers) Yunlong Hou SI

Rethinking "RL Generalizes, SFT Memorizes": The Role of SFT Data

Large language models trained with Reinforcement Learning (RL) with verifiable rewards exhibit strong reasoning ability and broad generalization, whereas models trained with Supervised Fine-Tuning (SFT) are often viewed as more prone to memorization and limited transfer. This paper rethinks this distinction through the lens of SFT training data on widely used Qwen2.5 and Qwen3 series models. First, we study the role of data source and show that it is critical: a carefully…

Read at arXiv (research papers)

arXiv (research papers) Songshi Liang SI

MuEdit: An efficient multi-task editing method towards inter-domain knowledge conflicts

Large language models (LLMs) require frequent knowledge updates across heterogeneous domains, but existing editing methods fail when applied sequentially to multi-task settings. We trace this collapse to inter-domain null-space misalignment: heterogeneous tasks induce distinct Jacobian geometries, causing their common null space to shrink dramatically and leaving insufficient admissible directions for conflict-free updates. We propose the Conflict Index to quantify this…

Read at arXiv (research papers)

Quantum Computing Report Mohamed Abdel-Kareem

Colorado Partners with IBM to Deploy AI-Driven Quantum Ecosystem Mapping and Workforce Tools

In a two-year initiative, Colorado has partnered with the IBM Impact Accelerator to advance quantum technology. This collaboration, coordinated by the Colorado Office of Economic Development and International Trade (OEDIT), aims to enhance quantum readiness, analyze the ecosystem, and develop the workforce across the Mountain West. The project will utilize IBM's AI-driven analytics to map supply chains, model talent requirements, and provide public access to IBM Qiskit…

Read at Quantum Computing Report

AWS Machine Learning Blog Aris Tsakpinis SI

Introducing Kimi K3.1 Pro on Amazon Bedrock

Kimi K3.1 Pro from Moonshot AI is now available on Amazon Bedrock. Learn how to get started through the OpenAI-compatible Chat Completions, Responses, and Converse APIs, optimize inference with explicit prompt caching, and use the model as a coding assistant in OpenCode.

Read at AWS Machine Learning Blog

Viet Nam News (state-run daily)

Technology changes production mindsets in mountainous areas

Technology application models achieved an average increase in economic value of more than 30 per cent compared with older technologies, contributing to improved product quality and enabling products to join sustainable consumption value chains.

Read at Viet Nam News (state-run daily)

UnHerd Michal Kranz Geopolitics

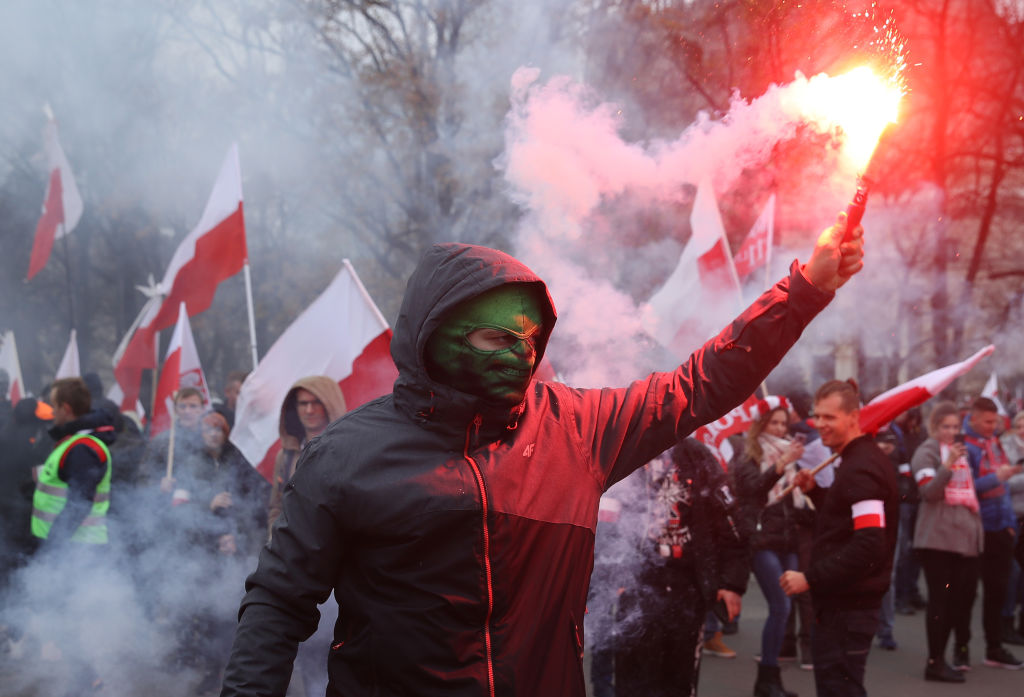
Poland's anti-migrant backlash

The country's multiethnic model is history

Read at UnHerd

UnHerd Michal Kranz Geopolitics

Poland’s anti-migrant backlash

The country’s multiethnic model is history

Read at UnHerd

Frontiers in Sustainable Food Systems Yifan Xu

Low-carbon city pilot policy, carbon emission reduction effect of agricultural inputs, and transmission pathways: evidence from a quasi-natural experiment at the prefecture level in China based on multi-period DID

IntroductionLow-carbon city pilot policies constitute an important institutional practice for advancing the green and low-carbon transition of agriculture and achieving the “Dual-Carbon” goals. Scientific assessment of the agricultural emission-reduction effects of this policy is critical for land and food security.MethodsBased on prefecture-level panel data of China spanning 2005–2024, this paper adopts a multi-period staggered Difference-in-Differences (DID) model to…

Read at Frontiers in Sustainable Food Systems

Older stories