Results for “model”

arXiv (research papers) Cong Xu

The State Is Not the Bottleneck: A Paged-State Gated-DeltaNet Tile on a Tri-Mode Multicast Mesh, Bit-Exact from RTL to Silicon

Linear-attention language models replace a growing key-value cache with a recurrent state of fixed size. On an edge FPGA, this state can exceed the on-chip memory and must be paged to external memory. This paper asks whether such paging dominates the cost of decoding (generating tokens). We built a hardware tile that computes one complete layer of a custom 369-million-parameter hybrid Gated DeltaNet model on an Agilex 5 FPGA and pages its recurrent state. The model state…
Read at arXiv (research papers)

Quantum Computing Report Mohamed Abdel-Kareem

Rigetti Computing Integrates Quantum Elements Constellation Platform into Error Correction Pipeline

Rigetti Computing has integrated Quantum Elements' Constellation simulation environment into its quantum error correction (QEC) workflow. This allows Rigetti to model processor behavior and predict system performance, including single and two-qubit gate fidelity, on their 36-qubit and 108-qubit quantum processing units. This integration helps Rigetti characterize device physics and optimize hardware designs before running on actual quantum processing units, aiding in the…

Read at Quantum Computing Report

arXiv (research papers) Jimin Mun SI

LECAT: Measuring LLM Category Learning from Pretraining Data

Humans know that airplanes are fast, that this extends to red airplanes, but that it does not hold for broken airplanes. How do LLMs acquire category knowledge that humans learn and apply effortlessly? We introduce LeCat, a two-part framework to analyze LLM's Learning of Category knowledge. First, we use LeCat to evaluate models on their ability to learn category knowledge, distinguishing between three cases: memorization of in-domain category knowledge, generalization to…

Read at arXiv (research papers)

arXiv (research papers) Tao Hu SI

CoPre-MoE: Consolidating and Preserving MoE for Multimodal Continual Instruction Tuning

Multimodal continual instruction tuning requires multimodal large language models to sequentially acquire new capabilities without catastrophic forgetting. Mixture-of-experts (MoE) architectures offer a promising way to mitigate task interference through expert specialization and combination. However, while existing MoE-based methods avoid overwriting shared parameters by allocating separate experts for each task, this progressive expansion incurs severe cross-task…

Read at arXiv (research papers)

arXiv (research papers) Run Luo SI

Gamer: A Generalist Vision-Language-Action Foundation Model for Long-Horizon Real-Time Game Agent

We introduce Gamer, a generalist agent framework built for long-horizon tasks in complex interactive environments. Its end-to-end architecture combines perception, memory management, and multi-step reasoning. A shared training and deployment pipeline supports interaction with both conventional 2D graphical interfaces and complex 3D simulated worlds. We first continue pre-training on a dataset constructed from tens of thousands of hours of device-level keyboard and mouse…

Read at arXiv (research papers)

The Decoder Manuel Uth SI

Anthropic's Claude for Manufacturing plugs AI directly into factory software to automate industrial workflows

Anthropic's new Claude for Manufacturing plugin connects the AI directly to Autodesk Fusion, Oracle NetSuite, and Infor. Its 17 specialized skills let the AI draft quotes, compare suppliers, and place backup orders when deliveries are delayed, all after human approval. The plugin doesn't control physical machines yet, but Anthropic is separately developing the Model Hardware Standard for that. The article Anthropic's Claude for Manufacturing plugs AI directly into factory…

Read at The Decoder

arXiv (research papers) Yashwanth Kumar Nakka

CS-MPC: Contraction-Certified Sampling-Based MPC for Nonlinear Systems Under Uncertainty

We present contraction-certified sampling-based model predictive control (CS-MPC) for tracking and safety of nonlinear robotic systems under parametric uncertainty, disturbances, and safety constraints that are revealed online. CS-MPC uses a contraction-certified tracking feedback inside every sampled rollout, which concentrates the rollouts around the reference, and an execution layer that verifies the applied input using a quantile-tightened discrete-time control barrier…

Read at arXiv (research papers)

arXiv (research papers) Wenbo Xie

Structure makes quantum circuits trainable

The scalability of variational quantum algorithms is limited by barren plateaus, where gradients vanish exponentially in system size. This worst-case result raises fundamental questions about the trainability of quantum AI models. We present a major advance towards resolving this trainability question by answering whether a given quantum circuit has a barren plateau. We do this using an analytical framework that bounds the gradient variance for arbitrary input states $ρ$ and…

Read at arXiv (research papers)

ReliefWeb

World: El Niño | Seasonal temperature and rainfall multi-model forecast (December 2026 – February 2027) - DG ECHO Daily Map | 13/11/2026

Country: World Source: European Commission's Directorate-General for European Civil Protection and Humanitarian Aid Operations Please refer to the attached Map.

Read at ReliefWeb

arXiv (research papers) Suvarna Kadam Witsense AI SI

Vision-Language-Action Models: A Life-Cycle Survey of Design, Training and Deployment

Vision-language-action (VLA) models adapt web-pretrained vision-language models to output robot actions, so that web knowledge carries over to physical control. In under 4 years the field has moved from RT-2, the first VLA, to open models that fine-tune on a single consumer GPU and to proprietary generalists that clean unseen homes. This survey reviews 88 works from December 2022 to October 2026, mainly on manipulation and navigation, plus humanoid control, world-action…

Read at arXiv (research papers)

arXiv (research papers) Mehrdad Saberi Security

Adaptable Watermarking: Transforming Image Watermarking Models via Lightweight Adapters

We explore the adaptability of neural image watermarking models; the extent to which one watermarking method can be transformed into another through lightweight adaptation. We introduce a framework that enables encoder-decoder watermarking architectures to become modular and upgradable, supporting multiple watermarking styles without re-training full models. Adaptation is performed by attaching a compact parameter-efficient adapter and fine-tuning under a multi-domain…

Read at arXiv (research papers)

MarkTechPost Asif Razzaq SI

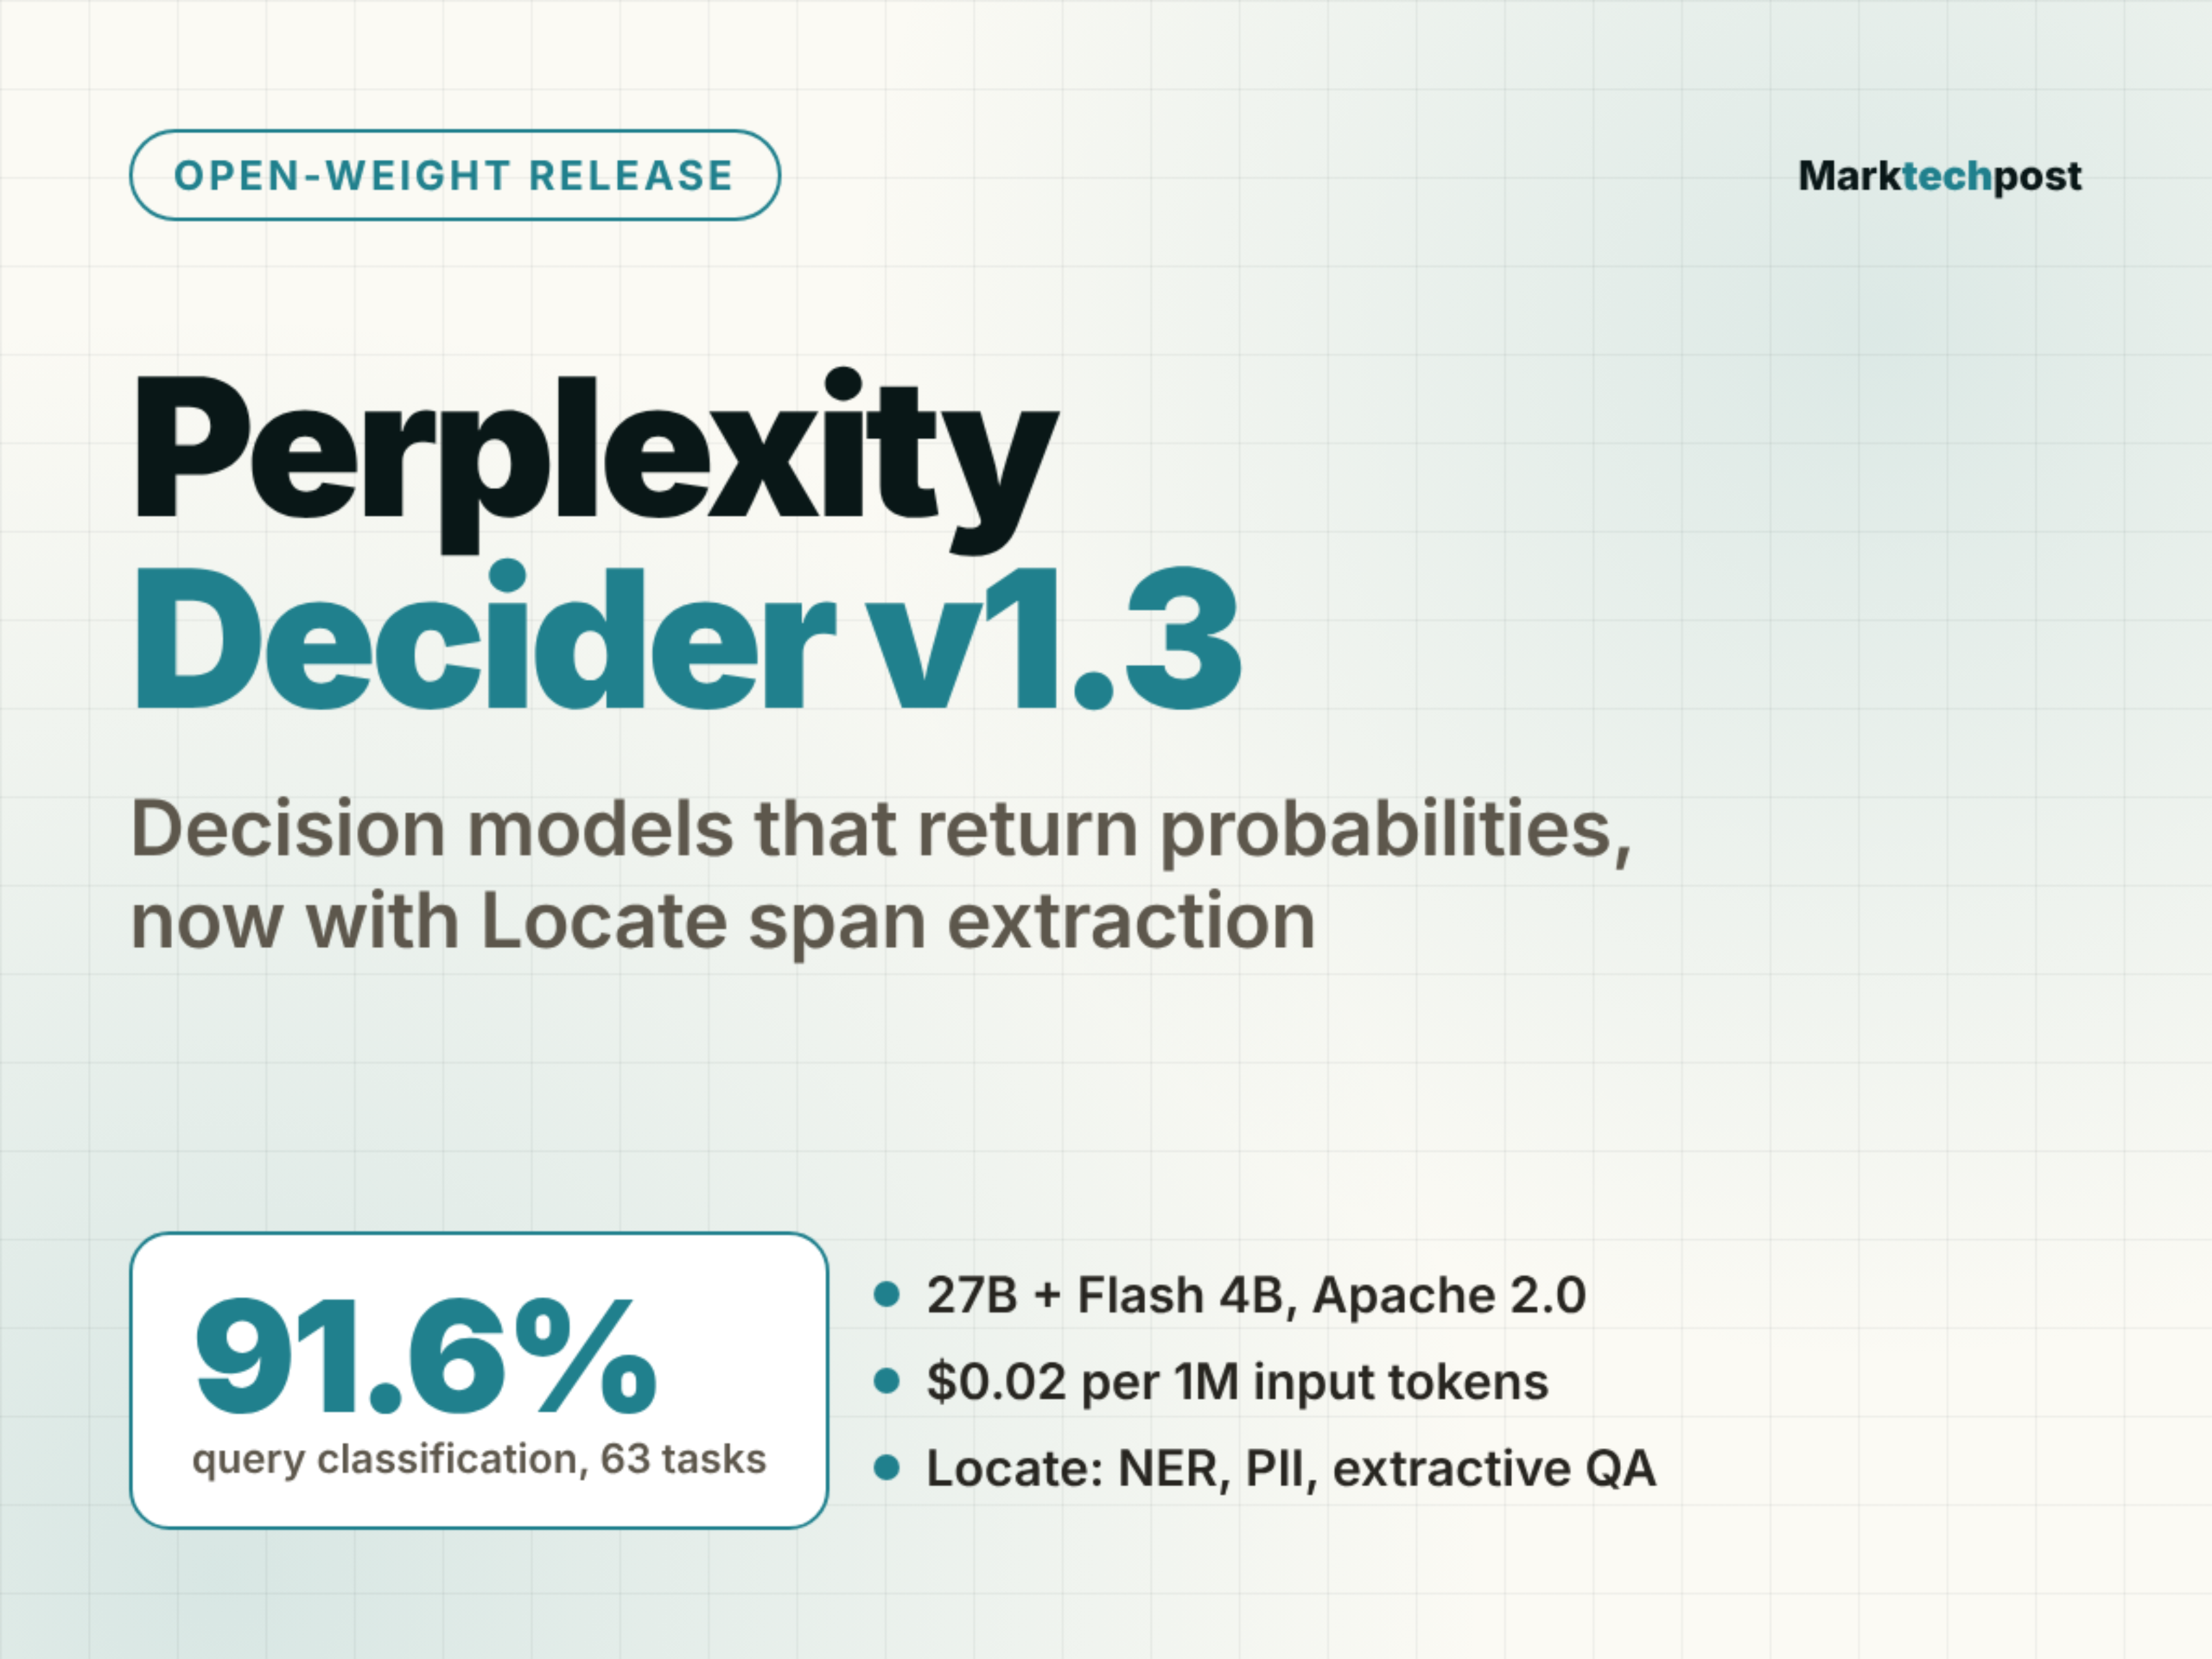
Perplexity Releases Decider v1.3: Open-Weight Decision Models Add Locate

Perplexity Decider v1.3 and Flash v1.3 are open-weight decision models that return probabilities, not text. Version 1.3 adds Locate for span extraction and reports 91.6% mean accuracy on 63 query-classification tasks.

Read at MarkTechPost

arXiv (research papers) Grid Robotics

Envisioning Agentic Robotics: A New Era of Robotic Systems

The release of GPT-6 Astra marks the emergence of a new paradigm in robotics: agentic robotics. Within weeks, frontier models with agentic harnesses matched or exceeded task-specific policies on many embodied benchmarks. Instead of training a dedicated policy for each family of tasks, an agentic robotic system applies a foundation model to open-world embodied tasks. It operates in a closed loop: observing the environment, interpreting user intent, reasoning about the task…

Read at arXiv (research papers)

arXiv (research papers) Dingwei Zhao

Efficient Parameter Estimation through Quantum Extreme Learning

Quantum sensing protocols rely on the efficient processing of measurement outcomes to infer unknown physical parameters. Conventional optimal estimators, such as Bayesian inference and maximum likelihood estimation, require to construct a likelihood function whose efficient classical construction requires full knowledge of the dynamics, which may practically be infeasible. Model-free experimental construction of the likelihood is also very resource intensive. Here, we…

Read at arXiv (research papers)

Al-Monitor Geopolitics

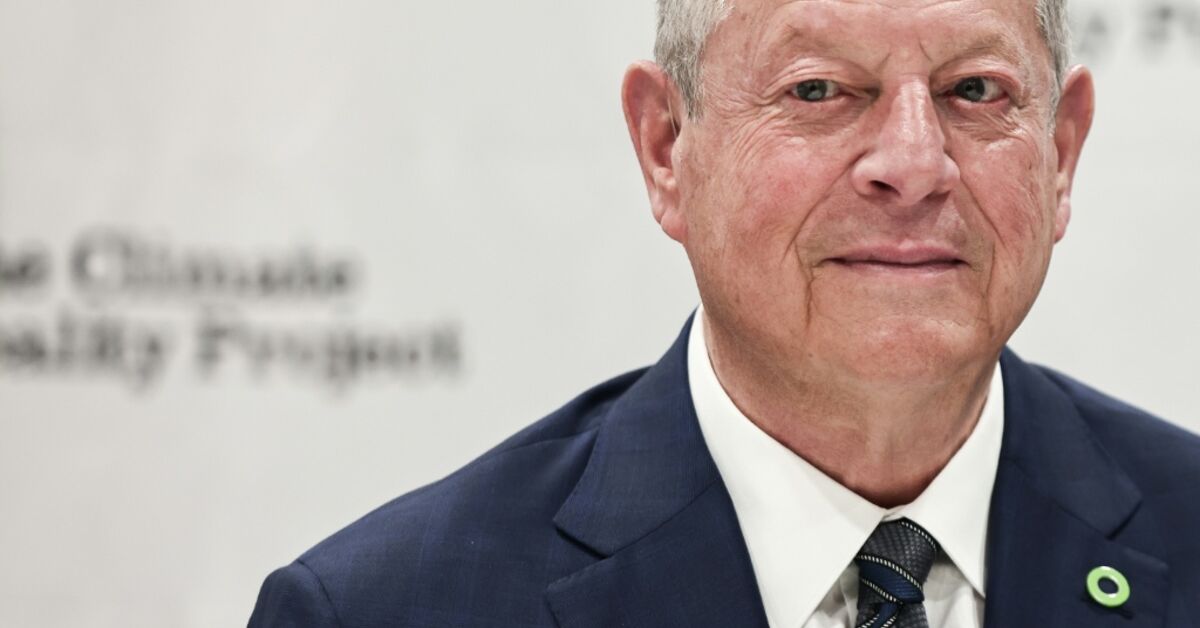
Gore blasts 'insane' Saudi veto power at climate talks

Former US vice president Al Gore said it was "literally insane" that oil-producing nations such as Saudi Arabia could block global action against climate change, calling for sweeping reforms to UN negotiations. Speaking to AFP on the sidelines of the COP31 summit in Antalya, Turkey, Gore said UN climate talks needed to replace the consensus-based decision-making system with a supermajority model.

Read at Al-Monitor

arXiv (research papers) Zihao Lu

Objectives as Policies: Vision-Language Model Cost Programs for Contact-Rich Manipulation

Vision-language models (VLMs) have shown strong semantic and spatial reasoning capabilities in 3D environments. Recently, connecting VLMs with model-predictive controllers (MPC) has emerged as a paradigm for combining strong semantic reasoning with physics-based planning. However, connecting these two for contact-rich robotic manipulation requires a task representation that bridges the two and captures how physical interactions can be reasoned by VLMs. In this work, we…

Read at arXiv (research papers)

arXiv (research papers) Anthony Abou Mrad Tech policy

When evaluation becomes intervention in clinical AI

AI judges, models that grade another system's output against a rubric, extend clinical review to the scale at which clinical AI writes. When teams use judge assessments to select a prompt or train a model, the judge becomes part of the intervention. Selection can then favor errors the judge overlooks. We describe what a judge's report must contain and the independent clinical test each judge-driven change needs.

Read at arXiv (research papers)

The Decoder Maximilian Schreiner SI

Former OpenAI researcher says he found Nvidia Blackwell fingerprints hidden inside six Chinese AI models

Former OpenAI researcher Will DePue says he has produced the first technical evidence that DeepSeek, Moonshot AI, MiniMax, and Ant Group are using Nvidia's latest Blackwell GPUs despite US export controls. His forensic method reads characteristic chip signatures directly from published model weights. He estimates the hardware behind the five training runs cost more than half a billion dollars. The article Former OpenAI researcher says he found Nvidia Blackwell fingerprints…

Read at The Decoder

SecurityWeek SecurityWeek News Security

In Other News: New CISA Director Nominee, Connected Car Hacking, Baker Tilly Data Breach

Noteworthy stories that might have slipped under the radar: Siemens details security advisory policy, OpenAI Codex backdoor risk, Microsoft warns of model weight backdoors.

Read at SecurityWeek

MacRumors Mitchel Broussard Gadgets

Apple Watch Ultra 3 Gets Big $250 Discounts Ahead of Black Friday

Amazon and Best Buy today have a big collection of Apple Watch Ultra 3 models on sale, starting at $549.00, down from $799.00. This is a massive $250 discount on the previous-generation device, and it's a match for the all-time low price on these models. Note: MacRumors is an affiliate partner with some of these vendors. When you click a link and make a purchase, we may receive a small payment, which helps us keep the site running. You'll find both Black and Natural Apple…

Read at MacRumors

arXiv (research papers) Jonathan Pan Security

From Bytes to Behavior: Request-Level Attribution from Live GPU Hidden States

Existing memory forensics for machine learning systems typically targets static artifacts, such as model weights or prompt logs, rather than the transient computational states of a live inference process. This gap limits an examiner's ability to analyze the specific behavior of a running large language model (LLM) service that cannot be restarted or modified. We present a method for acquiring per-layer residual-stream activations from a live GPU process using a non-modifying…

Read at arXiv (research papers)

arXiv (research papers) Eleanor Pike Space

JWST/NIRISS-SOSS Spectroscopic Variability and Auroral Modelling of Warm Ultracool Dwarf LSR J1835+3259

Auroral variability in ultracool dwarfs (UCDs) has been proposed as a key source of optical and infrared modulation, yet its physical origin remains poorly understood. We present JWST Near Infrared Imager and Slitless Spectrograph/Single Object Slitless Spectroscopy (NIRISS/SOSS) time-series spectroscopy of the M8.5 UCD LSR J1835+3259. These observations probe the object's wavelength-dependent rotational variability, providing insight into the atmospheric processes…

Read at arXiv (research papers)

arXiv (research papers) Julian Kauk Tech policy

Large language models put existential risk from artificial intelligence at 10%

How likely is it that advanced artificial intelligence (AI) will cause human extinction or a similarly permanent disempowerment of humanity? Humans, including AI experts, frequently disagree on this question. Yet one important perspective is missing from this debate: that of AI systems themselves. We put the question to 241 large language models (LLMs) at every available reasoning setting. The models converged on a median risk of 10.0%, with the middle 90% of their estimates…

Read at arXiv (research papers)

9to5Mac Ryan Christoffel SI

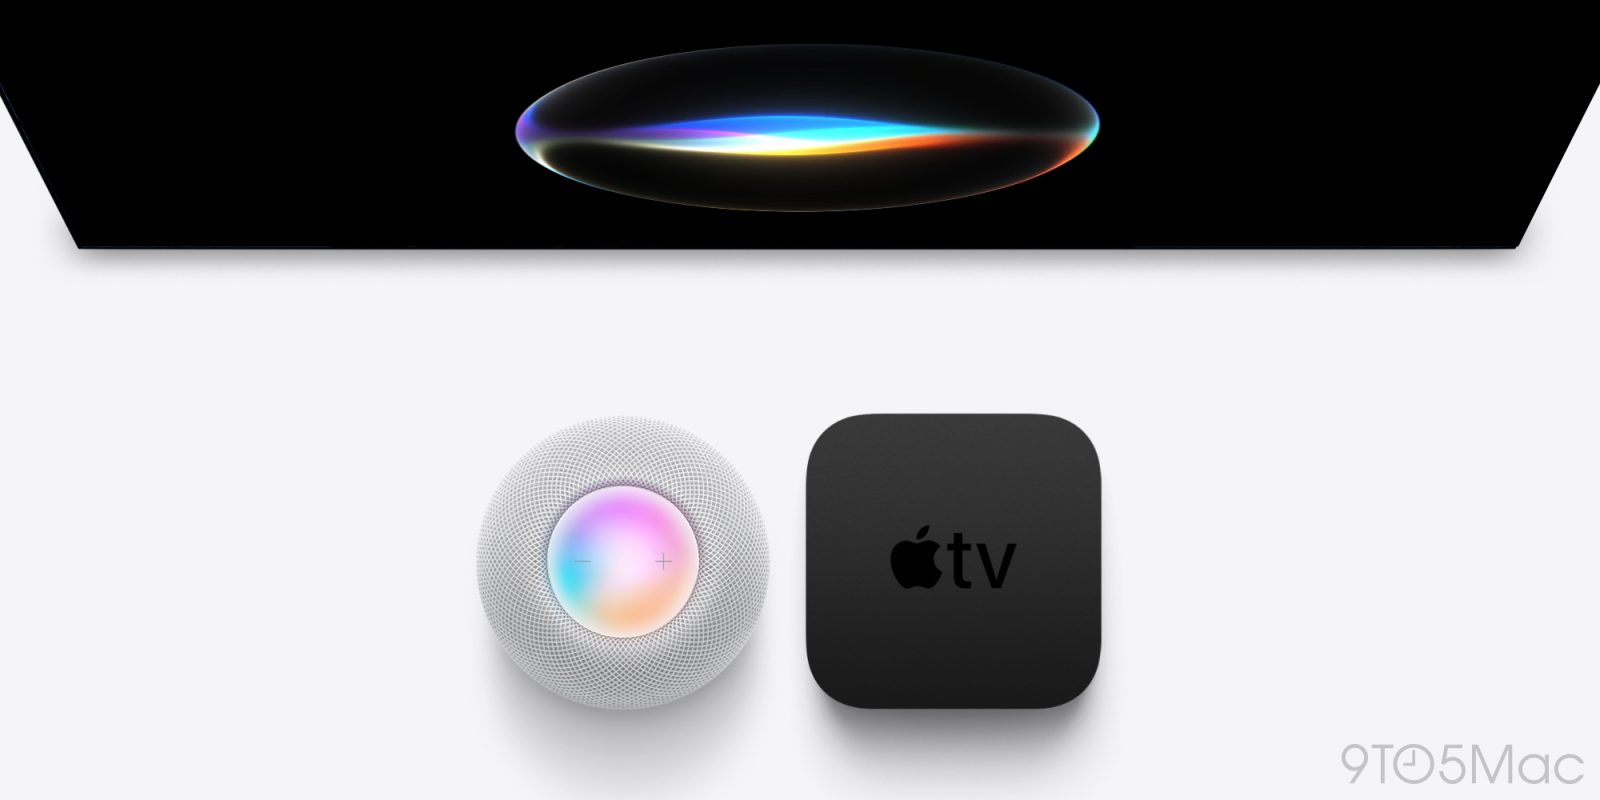
tvOS 27.2.1 launching soon with Siri AI for older Apple TV 4K models

Today the new Apple TV 4K has arrived (order here) with Siri AI as a major tentpole feature. But older Apple TV 4K models are about to get Siri AI too via a tvOS 27.2.1 software update.

Read at 9to5Mac

Just Security Russell E. Travers Geopolitics

Preparing for 2029: A Reconversion Strategy

The next U.S. administration should adopt a planning model of centralized strategic coordination and decentralized substantive execution.

Read at Just Security

South China Morning Post Chong Ming Lee,Minxiao Chang Geopolitics

Will Jensen Huang’s downfall tip the scales against open-source AI?

Jensen Huang’s abrupt resignation from Nvidia has cast uncertainty over the US chip giant’s multibillion-dollar investments in open-source artificial intelligence, while potentially depriving Chinese developers of one of their most influential advocates in Washington. His departure could prompt Nvidia to scale back spending on open-weight models and their supporting infrastructure, analysts said, although strong commercial incentives would likely keep the company committed…

Read at South China Morning Post

arXiv (research papers) Yundi Cai

ESI: An Embodied Self-Improvement Flywheel for LLM-VLA Agents

Independently pretrained language models and vision-language-action (VLA) policies provide complementary building blocks for embodied agents, but connecting them does not automatically produce coordinated behavior. The VLA may generate actions that diverge from the LLM's intended subtask and, upon regaining control after a correction, undo the promising state restored by the LLM. We introduce ESI (Embodied Self-Improvement), an automated flywheel that uses environmental…

Read at arXiv (research papers)

arXiv (research papers) Yulliwas Ameur Security

Forget the Lineage: Forward-Secure, Lineage-Complete Cryptographic Erasure for LLM-Agent Memory

Large language model (LLM) agents keep a long-term memory that the model itself writes: summaries, extracted facts and embeddings derived from what users said. Deleting a message is therefore not enough: its derivatives, storage residue and backups survive. We define lineage-complete forward-secure erasure: after a forget request, an adversary that later obtains all storage and the agent's current keys learns nothing about the forgotten input or any memory derived from it…

Read at arXiv (research papers)

VietnamPlus (Vietnamese state media) Geopolitics

Deputy PM urges stronger Vietnam–Kanagawa cooperation in preventative healthcare

Deputy PM Pham Thi Thanh Tra said that as Vietnam is entering a period of rapid population ageing, there is practical significance in studying and adopting a healthcare model that focuses on prevention and early detection of disease risks. Party General Secretary, President To Lam receives Kanagawa Governor Kuroiwa Yuji Top Vietnamese leader visits Japan’s Kanagawa prefecture, promotes bilateral cooperation Vietnam Festival in Kanagawa connects hearts, looks to future

Read at VietnamPlus (Vietnamese state media)

arXiv (research papers) Jun Miura

Evaluating Language Models as Spatial Priors for Object-Goal Navigation

Semantic exploration methods for object-goal navigation use large language models (LLMs) to score how strongly a target object is associated with a room type or with a nearby object. This paper considers obtaining from the LLM a spatial prior instead: a distribution over the position of the target in a room. We evaluate whether two open-weight LLMs, Qwen3.5-27B and Gemma-4-31B-it, can provide such a prior. Using real room layouts from CubiCasa5K and ScanNet, we measure the…

Read at arXiv (research papers)

Older stories