Results for “GPU”

arXiv (research papers) Ben Howe

TCBP-JOBS: GPU-Accelerated Quantum Error Correction Decoding and Noise Learning with Near-Optimal Accuracy

Achieving near-optimal quantum error correction (QEC) decoding accuracy often requires computationally expensive searches that limit both large-scale simulation and real-time operation. We introduce trajectory-calibrated belief propagation (TCBP), which learns calibrated fault probabilities from BP trajectories, and jittered OSD beam search (JOBS), which uses these probabilities to guide parallel GPU searches. Across surface, color and bivariate-bicycle code memory and…
Read at arXiv (research papers)

NVIDIA Blog Brian Sparks SI

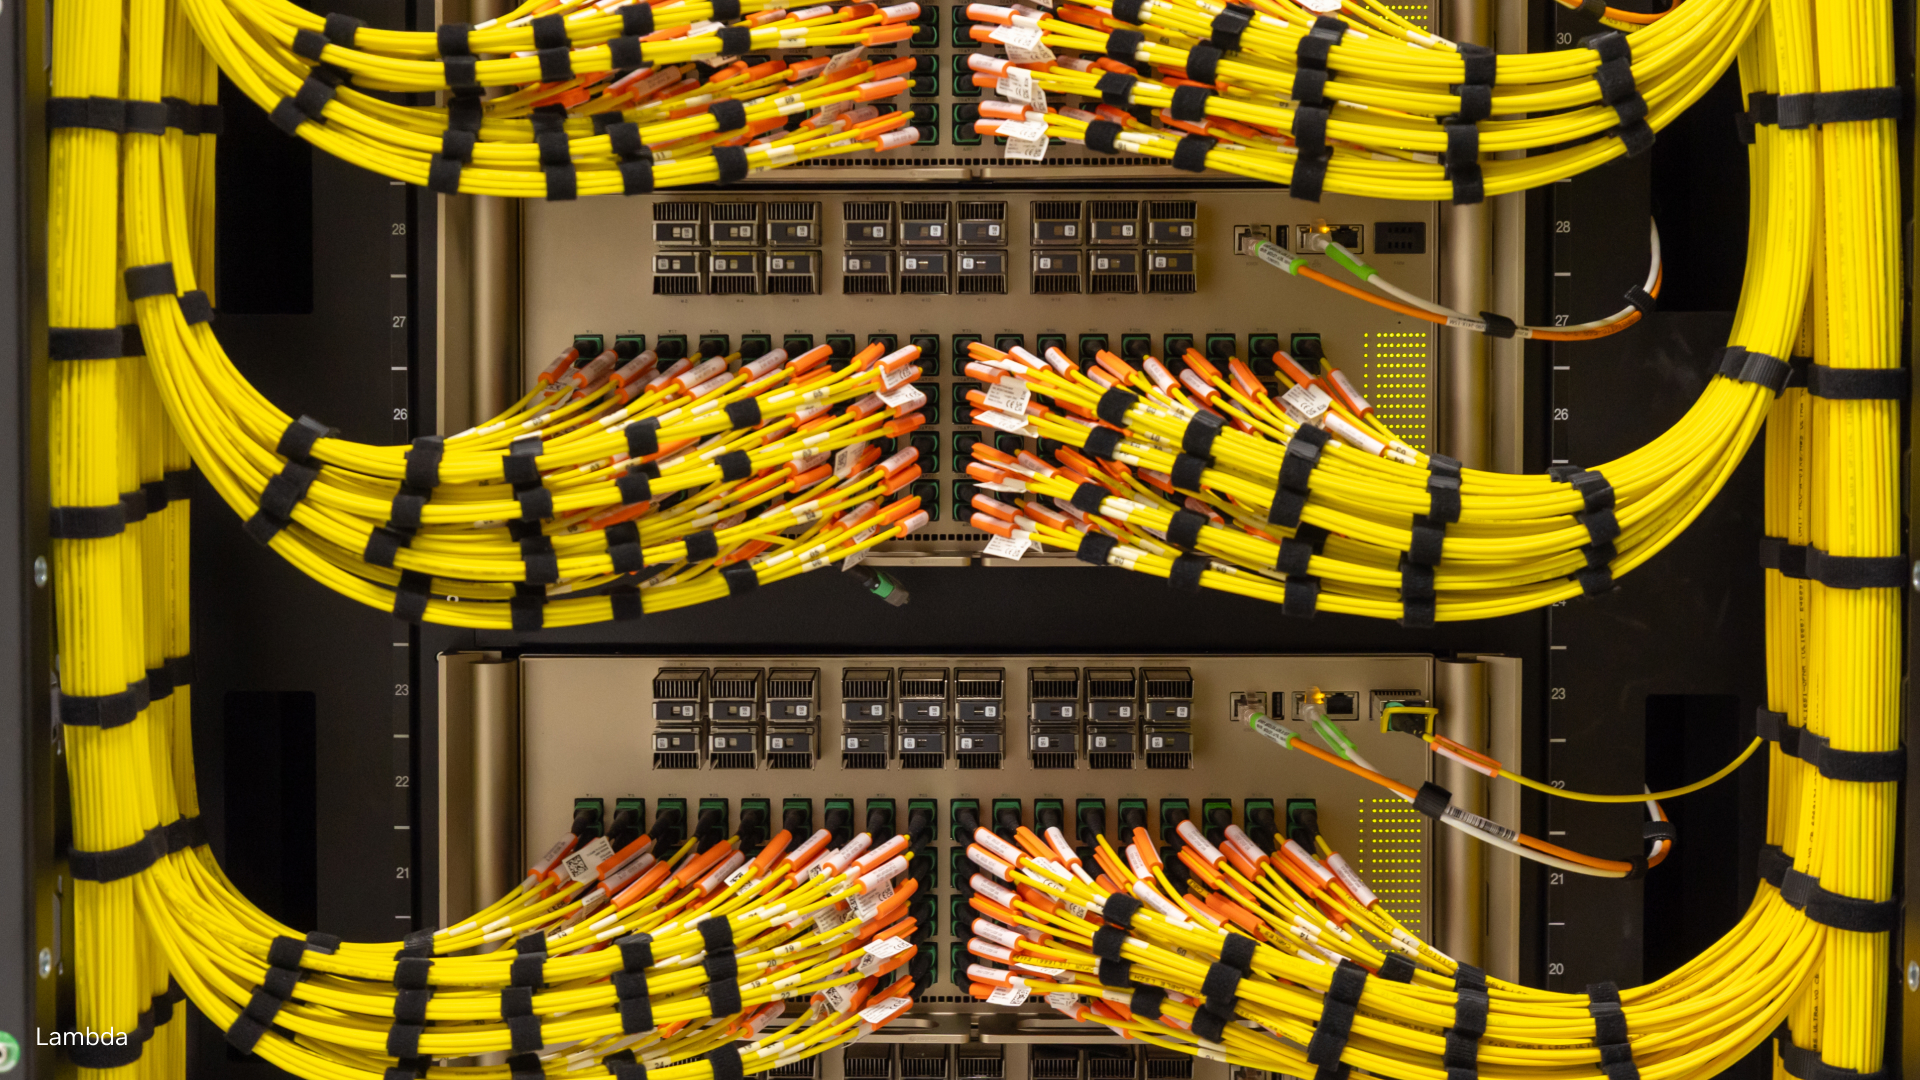
Lambda Boosts AI Factory Resiliency and Efficiency With NVIDIA Photonics

To train an AI model, thousands of GPUs have to work together, requiring a network that’s fast, efficient and resilient. Lambda is tackling the network piece of the puzzle with NVIDIA Photonics co-packaged optics (CPO) switches. The cloud provider is using the switches to connect NVIDIA GB300 NVL72 racks with more than 10,000 GPUs, delivering

Read at NVIDIA Blog

NVIDIA Blog Brett Murray SI

CUDA at 20: How the Platform Transformed Scientific Computing

This week at SC26, NVIDIA is marking two decades of CUDA by honoring the researchers, developers and engineers who helped make GPU computing a foundation for modern science and AI. CUDA’s 20th anniversary presents an occasion to reflect across computing eras, from the people who wrote the very first CUDA programs to the AI developers

Read at NVIDIA Blog

NVIDIA Blog Dan Ernst SI

NVIDIA Announces Rubin HPC — A New GPU to Accelerate Agents for Science, Engineering and Analytics

Announced today at SC26, NVIDIA Rubin HPC is a new GPU in the NVIDIA Vera Rubin platform designed to accelerate simulation and data processing for science, engineering and analytics workflows. As agents help scientists and engineers explore more candidate materials, molecules and designs, they rely on simulations to test those ideas and guide their next

Read at NVIDIA Blog

Google (The Keyword)

New AI training performance benchmarks for Google TPUs

In the latest MLPerf Training v6.1 benchmark round, Google Cloud published 10 results across seventh-generation Ironwood TPUs and NVIDIA Grace Blackwell GPUs, spanning f…

Read at Google (The Keyword)

arXiv (research papers) Lei Tian

GNoF: A Low-SM-Overhead GPU-Native NVMe-over-Fabrics Completion Path for Data-Intensive GPU Workloads

GPUs are the main compute engine for data-intensive workloads whose datasets exceed device memory and reside on remote flash. The conventional host CPU orchestrates every NVMe-over-Fabrics (NVMe-oF) transaction and stages data through host memory, costing high CPU usage, repeated CPU-GPU synchronization, and redundant data movement. GPU-initiated storage removes the CPU from the I/O path, but existing designs leave two problems: synchronous lock-step completion pins…

Read at arXiv (research papers)

arXiv (research papers) Haoran Shang

SURMA: Efficient Fine-Grained Communication Offload for SuperPOD

GPU SuperPODs underpin large language model (LLM) serving, but growing bandwidth and round-trip times make inter-GPU communication consume increasing compute resources. SM-driven remote memory access occupies shared memory or registers for in-flight data and competes for SM-to-NoC bandwidth. Dedicated engines can free these resources, but must handle fine-grained transfers, down to a 576\,B KV-cache entry. NVIDIA's CopyEngine uses less than 1\% of NVLink bandwidth at 7\,KB…

Read at arXiv (research papers)

3D InCites Sriram Nithin Gopal Lanka SI

When Memory Is Scarce, Every Good Die Counts: Test, Repair, and Reliability Across SRAM, DRAM, HBM, and Emerging Memories

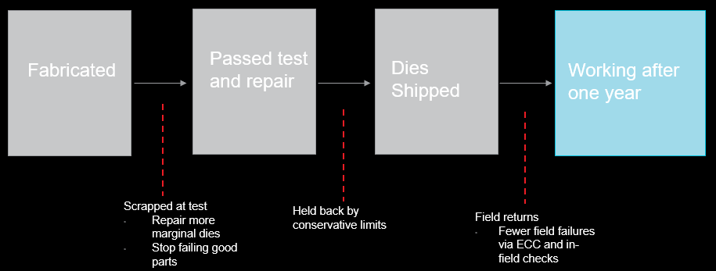
AI accelerators and data‑center GPUs are using memory faster than the industry can add capacity. IEEE Spectrum has said that high‑bandwidth memory is one of the bottlenecks of the AI build‑out [1], [2]. Reuters have reported that AI demand is driving memory shortages and price increases [3], [4]. Micron and SK hynix have both publicly

Read at 3D InCites

TechPowerUp Nomad76 SI

(PR) Penguin Solutions Unveils Industry's First Photonics-Based HBM-Class Memory Appliance

Penguin Solutions, Inc. (Nasdaq: PENG), the AI Factory Platform Company, today unveiled the MemoryAI Photonic Appliance, the industry's first photonics-based HBM-class memory appliance designed to overcome GPU memory capacity constraints for agentic AI workloads. Using silicon photonics, the appliance is built to enable CPUs and GPUs to transparently share memory at high bandwidth memory (HBM)-class data rates. Penguin is showcasing the appliance at SC26 in Chicago…

Read at TechPowerUp

The Quantum Insider Matt Swayne

Altera, OQC and NVIDIA Link Quantum Processor to GPU Computing

Insider Brief PRESS RELEASE — Altera Corporation, the largest pure-play FPGA provider with a full-spectrum portfolio, today announced the development of an end-to-end FPGA-based quantum system controller reference design in collaboration with Oxford Quantum Circuits (OQC) and NVIDIA. Built on an Agilex® 9 Direct RF FPGA, the design runs real-time system control in the FPGA,

Read at The Quantum Insider

The Register Tobias Mann

Los Alamos boffins to put NextSilicon's Maverick-2 through natural selection in Darwin testbed

Tiny test system opens door to a new generation of GPU-less supers

Read at The Register

MacRumors Tim Hardwick Gadgets

New Apple TV 4K's A19 Chip Has One Core Switched Off

Apple's new Apple TV 4K uses an A19 chip with one efficiency core disabled, according to system diagnostic data shared by code explorer pdfu. That suggests a five-core CPU with two performance cores and three efficiency cores, compared with the six-core CPU in the iPhone 17. The reported maximum clock speeds are 4.26GHz for performance cores and 2.592GHz for efficiency cores, with a five-core GPU reaching 1.47GHz. (These are maximum frequencies, not measurements of sustained…

Read at MacRumors

The Hacker News Security

SANSAR Linux Cryptomining Malware Uses Modified NVIDIA Library to Hide GPU Activity

A financially motivated threat activity cluster tracked as REF3364 has been attributed to a Linux-focused cryptocurrency mining operation that tampers with the readings used to detect high GPU workloads. Central to the intrusion is a toolkit called SANSAR, a Rust-based orchestrator that receives commands over the TOR anonymity network to manage CPU and GPU miners. The activity was observed in

Read at The Hacker News

arXiv (research papers) Linliang Chen SI

GEAR$^2$: Pruned Experts Live On through Gated Reuse of Activated Experts and a Missing-Mass Residual

Mixture-of-Experts (MoE) Large Language Models (LLMs) activate only a few experts per token while generally keeping all the experts in GPU memory for high efficiency. Expert pruning reduces this GPU memory footprint cost, yet discards the contribution of pruned experts. Existing remedies either rely on static substitutes, merge experts at the cost of altering their functions, or require costly recovery training. In this paper, we find that the functionalities of pruned…

Read at arXiv (research papers)

arXiv (research papers) Shiva Raja

Integrated GPU Core for Mamba-3

Mamba-3, the latest Mamba state-space model (SSM), enables efficient long-context modeling, matching Mamba-2 perplexity with half the state size and increasing decoding arithmetic intensity. However, its multi-input multi-output (MIMO) computation, exponential-trapezoidal discretization, and rotary positional embeddings (RoPE) introduce dense, element-wise, and sequential operations. Despite kernel fusion, conventional GPUs execute these operations inefficiently. Our…

Read at arXiv (research papers)

Tech in Asia Naomi Li Gan Startups

Firmus plans $3b fundraising after pulling IPO plans: source

In September, Firmus agreed to supply Meta with GPU capacity in Southeast Asia.

Read at Tech in Asia

TechPowerUp DrUsmanSaleem

Thermal Grizzly Details WireView Pro II Extended GPU Warranty Conditions

Thermal Grizzly has published an FAQ clarifying the conditions of its WireView Pro II extended GPU warranty, covering cables, settings, adapters, and claims. Neither the USB cable nor the motherboard Y-splitter has to be connected for coverage. The Y-splitter lets the WireView shut the PC down through the power-button header, but Thermal Grizzly only recommends it. Monitoring has to stay enabled, though. Lowering the current, temperature, or power thresholds is fine, but…

Read at TechPowerUp

arXiv (research papers) Yousef Elbrolosy

feedback-grape: A JAX-based Python Package for GPU-Accelerated GRAPE with Feedback

Modern quantum technology applications require accurate control of quantum systems, including a feedback loop in the control process. While open-loop control can be performed using well established gradient methods like GRadient Ascent Pulse Engineering (GRAPE), it was until recently unclear how to combine these with feedback from measurements, which are inherently non-differentiable. Recent work has successfully demonstrated how feedback can be incorporated into GRAPE using…

Read at arXiv (research papers)

arXiv (research papers) Jianglong Ye

RoboKit: Accelerating Parallel Differentiable Optimization for Robot Learning

We present RoboKit, a high-performance, general-purpose toolkit for parallel differentiable optimization in robotics, built on three principles: (i) Performance and flexibility: GPU-parallel multi-seed solvers pair sampling with versatile optimizers, running 2-60$\times$ faster than task-specific baselines across seven tasks; (ii) Geometry, rendering and physics: hybrid and coarse-to-fine representations accelerate collision, differentiable rendering and simulation…

Read at arXiv (research papers)

The Decoder Jonathan Kemper SI

Meituan releases a 1.6-trillion-parameter agent model that never touched an Nvidia GPU

Meituan has released the weights for LongCat-2.5, a 1.6-trillion-parameter model built for AI agents and trained entirely on Chinese hardware. On Terminal Bench, it scores 88.4 points, landing just behind Claude Opus 5. The sample deployment runs on 194 Huawei Ascend chips, and Meituan makes no mention of Nvidia GPUs. The article Meituan releases a 1.6-trillion-parameter agent model that never touched an Nvidia GPU appeared first on The Decoder.

Read at The Decoder

arXiv (research papers) Aritra Bagchi

Rethinking KV Caching for LLM Decode: Free-Space Optical KV Regeneration for Reduction of Memory Traffic

Long-context large language model (LLM) decoding repeatedly reads the historical key-value (KV) cache, making multi-head attention (MHA) memory-bandwidth-bound. Caching layer-input activations instead halves historical-cache storage and traffic, but requires regenerating KV from each cached activation. On digital accelerators such as GPUs, this regeneration takes far longer than fetching the activation from HBM. The KV regeneration overhead outweighs the savings from reduced…

Read at arXiv (research papers)

arXiv (research papers) Jieyuan Pei

SuperGlance: Driving at a Glance with a Vision-Language Model

Autonomous driving is turning to vision-language-action models (VLAs). They answer and plan by decoding, one step at a time. Each step is another forward pass, so a plan can take over a second of GPU time. Embodied AI often pairs such a slow, reasoning System 2 with a fast System 1 that acts. Human drivers plan at a glance, with System 1. Faster designs usually put System 1 outside the vision-language model (VLM), in a planner without its abilities. Yet before a VLM writes…

Read at arXiv (research papers)

arXiv (research papers) Spencer H. Bryngelson

A predictive, per-engine energy roofline of the Apple Neural Engine

The Apple Neural Engine (ANE) is in over a billion devices, but is characterized indirectly via CoreML. Using a CoreML-free fused-graph dispatch path, we measure the ANE, along with the Apple GPU and CPU on the same device, with per-engine energy accounting. The consumer-available roofline does not predict the ANE in practice. A critical correction is that the ANE sees two effective memory bandwidths: a slow activation path and a fast weight-stream path. Two roofline ridges…

Read at arXiv (research papers)

TechPowerUp DrUsmanSaleem Gadgets

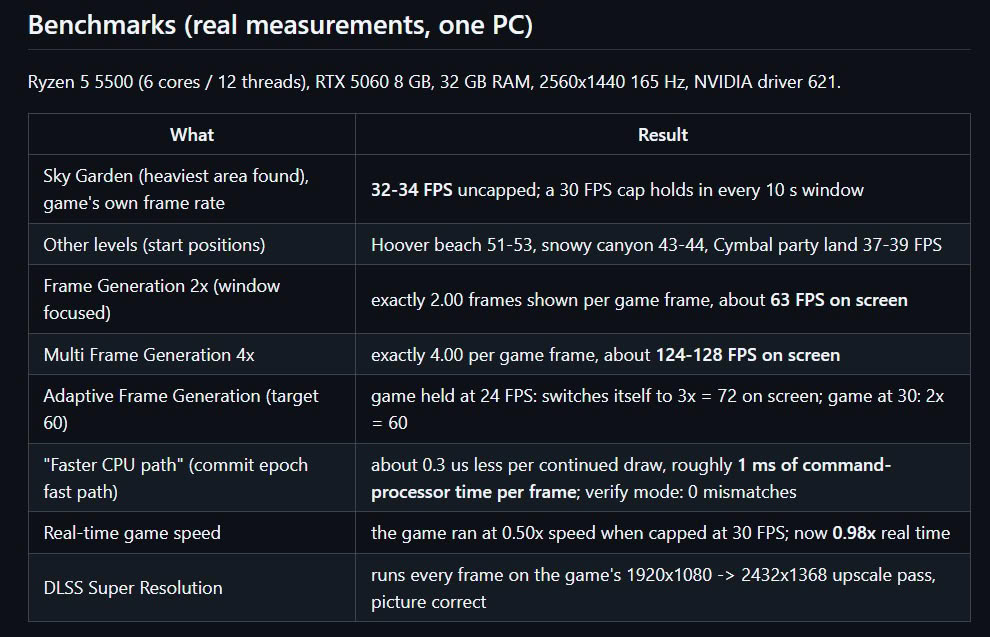
Astro Bot Runs Natively on PC Through AnyPS5, With DLSS Frame Generation

PlayStation 5 exclusive Astro Bot now runs on Windows with DLSS Super Resolution, DLSS Frame Generation, and Reflex support, thanks to an unofficial port from GitHub user imnotsharingmyname. Technically, it's a port, not running through any PS5 emulator. AnyPS5 relinks the PS5 game's x86-64 code into a Windows executable and swaps in native versions of the console's system libraries, while a GPU layer borrowed from the KytyPS5 emulator translates the graphics work to Vulkan…

Read at TechPowerUp

TechPowerUp Cpt.Jank SI

NVIDIA Allegedly Engineered Scarcity By Funding AI Startups To Buy Its GPUs

Following the departure of now-former NVIDIA CEO, Jensen Huang, a new report by The Wall Street Journal (via Wccftech) has emerged alleging that NVIDIA artificially inflated the ongoing GPU and memory shortage by investing in AI startups that would go on to buy NVIDIA GPUs and build data centers. The reason behind this was to maintain the perception of ongoing high demand and to move an oversupply of semiconductors from TSMC. The WSJ report cites an August meeting between…

Read at TechPowerUp

AWS Machine Learning Blog Malav Shastri SI

OpenFold3 on Amazon SageMaker JumpStart: Predict biomolecular structures

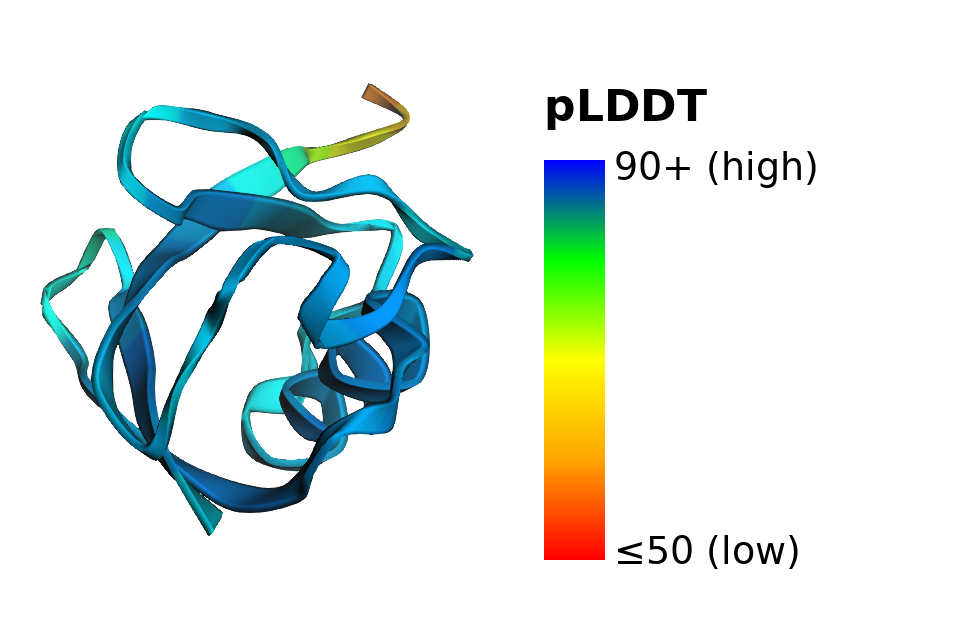
Deploy OpenFold3-preview from Amazon SageMaker JumpStart to predict 3D structures of proteins, DNA, RNA, and ligand complexes in your own AWS account. The post covers asynchronous inference, multi-GPU parallelism, bringing your own MSAs for accuracy and privacy, and scaling to zero to reduce cost.

Read at AWS Machine Learning Blog

AWS Machine Learning Blog Belair Albahagwi SI

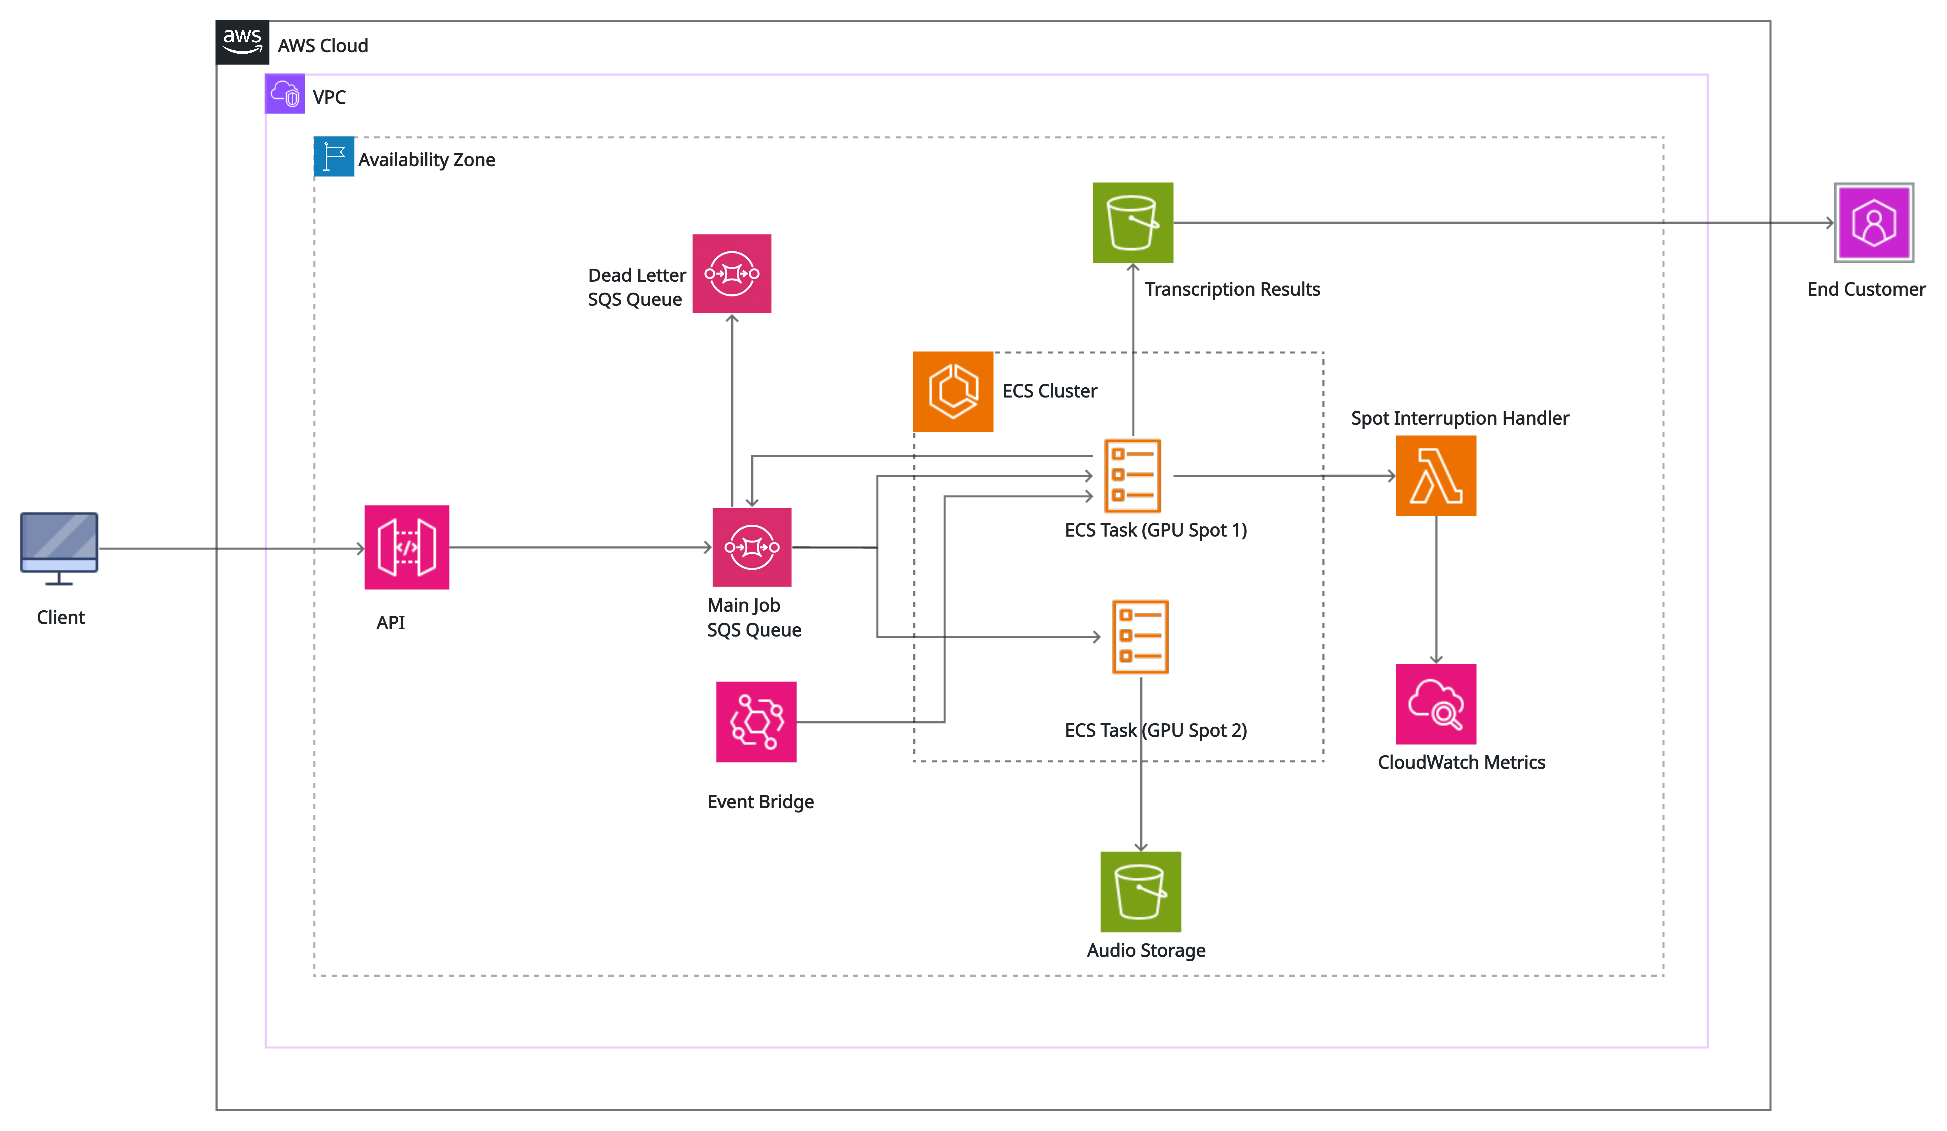
Cost-optimizing AssemblyAI speech-to-text inference on AWS with Amazon EC2 Spot

Learn how AssemblyAI runs cost-optimized speech-to-text inference at scale on AWS, using Amazon ECS, Amazon EC2 Spot GPU instances, and an Amazon SQS-based retry architecture to achieve 70% cost savings while maintaining SLA commitments across European Regions.

Read at AWS Machine Learning Blog

arXiv (research papers) Suvarna Kadam Witsense AI SI

Vision-Language-Action Models: A Life-Cycle Survey of Design, Training and Deployment

Vision-language-action (VLA) models adapt web-pretrained vision-language models to output robot actions, so that web knowledge carries over to physical control. In under 4 years the field has moved from RT-2, the first VLA, to open models that fine-tune on a single consumer GPU and to proprietary generalists that clean unseen homes. This survey reviews 88 works from December 2022 to October 2026, mainly on manipulation and navigation, plus humanoid control, world-action…

Read at arXiv (research papers)

TechPowerUp btarunr

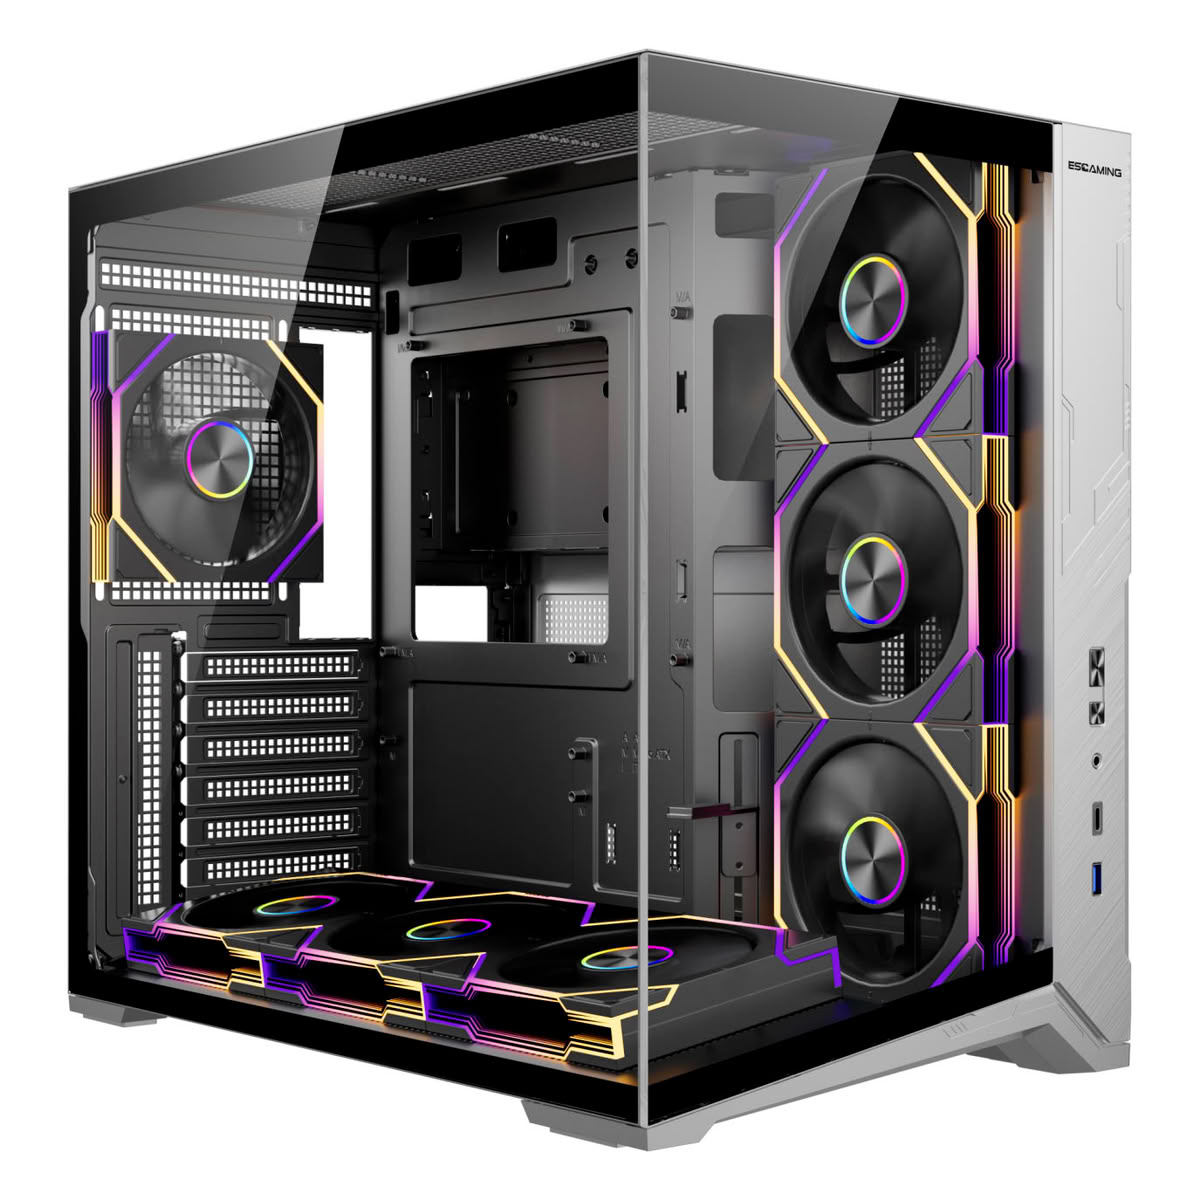
(PR) ESGAMING Debuts ZERO MAX Gaming PC Case with Novel 8° Tilted GPU Airflow Design

ESGAMING is spotlighting its ZERO MAX gaming PC case, available in black and white, which features an innovative 8° tilted bottom airflow structure that directs cool air toward the GPU area. With 270° panoramic tempered glass, clearance for graphics cards up to 415 mm, and flexible cooling configurations, the ZERO MAX offers high-performance custom PC builders a solution that balances thermal layout, hardware display, and component compatibility. The ZERO MAX has already…

Read at TechPowerUp

The Decoder Maximilian Schreiner SI

Former OpenAI researcher says he found Nvidia Blackwell fingerprints hidden inside six Chinese AI models

Former OpenAI researcher Will DePue says he has produced the first technical evidence that DeepSeek, Moonshot AI, MiniMax, and Ant Group are using Nvidia's latest Blackwell GPUs despite US export controls. His forensic method reads characteristic chip signatures directly from published model weights. He estimates the hardware behind the five training runs cost more than half a billion dollars. The article Former OpenAI researcher says he found Nvidia Blackwell fingerprints…

Read at The Decoder

Older stories