Results for “model”

arXiv (research papers) Robin Geens

Kameleo: In-Situ Activation-Precision Selection for Bit-Serial LLM Accelerators

Weight-only quantization keeps the activations of large language models (LLMs) in a higher-precision format, pushing the on-chip inference cost to the activation arithmetic. Bit-serial, variable-length accelerators offer a promising path to reduce this cost by lowering activation precision while preserving model quality. They process only the mantissa bits that each layer needs. The length has to be chosen per layer and operator, and today it is chosen by offline…
Read at arXiv (research papers)

The Quantum Insider Matt Swayne

BMO Reports Quantum Utility in Machine Learning Application Using IBM Quantum Computers

Insider Brief PRESS RELEASE — BMO today announced it has demonstrated quantum utility in a machine learning application using IBM quantum computers, meaning the work was performed reliably at a scale beyond what exact traditional computing methods can practically reproduce. The work explores how quantum computing could help AI models identify which information matters most

Read at The Quantum Insider

arXiv (research papers) Francisco W. Kerche Tech policy

Web search in Latin America: language models use less local and diverse news than search engines

AI platforms are becoming a major gateway to news and current events. This shift risks amplifying existing geographical biases that favour narratives from wealthier countries over those from the Global South. This is particularly relevant in Latin America, which accounts for the largest share of AI usage in the Global South. We examine how information about Latin America changes when users shift from conventional search engines to LLM-based search. We construct a dataset of…

Read at arXiv (research papers)

arXiv (research papers) Luca Colombo

Matching Architecture to Workload: Comparing RISC-V Parallel Accelerators for Energy-Efficient Embedded Computing

Embedded computing demands high performance and energy efficiency across workloads with widely different computational characteristics. Choosing the most suitable execution model therefore requires a quantitative understanding of how each model maps to different workload classes. In this paper, we compare three execution models for energy-efficient embedded computing: scalar multicore, stream ing multicore, and vector processing. We use three open-source RISC-V accelerators…

Read at arXiv (research papers)

arXiv (research papers) Qifan Wang Security

BlockJack: Cross-Tenant Redirection Fault Attacks on Paged KV Cache Address Translation in LLM Serving

Large language model (LLM) serving frameworks accelerate inference by retaining previously computed states in a key-value (KV) cache. Paged serving frameworks such as vLLM organize this cache through block tables analogous to OS page tables, which map each request's logical KV blocks to physical KV blocks, forming a software-managed address translation layer. Although fault attacks such as Rowhammer have exploited OS page tables to redirect memory accesses, prior fault…

Read at arXiv (research papers)

Android Authority Aamir Siddiqui Gadgets

Exclusive: Samsung’s upcoming 14-inch and 16-inch Android laptops are codenamed ‘Origin’

One UI 9.5 beta code reveals Wi-Fi-only XE940 and XE960 models powered by Qualcomm's Snapdragon X Elite chip.

Read at Android Authority

The Decoder Maximilian Schreiner SI

Google's latest AI model is faster, cheaper and smarter than its flagship predecessor from just weeks ago

Google DeepMind has released Gemini 4 Neon, its fourth model in seven weeks, which is nearly 2x faster than its sibling Carbon, outperforms it on most benchmarks and comes in at a significantly lower price. The article Google's latest AI model is faster, cheaper and smarter than its flagship predecessor from just weeks ago appeared first on The Decoder.

Read at The Decoder

arXiv (research papers) Yao Zhang

Fast-JEPA: Advancing the Success-Latency Frontier for Latent World Models

Latent world models predict the outcomes of action sequences, but comparing candidate plans through recursive rollout remains expensive at test time. We introduce Fast-JEPA, a latent world model planning framework that advances the success-latency Pareto frontier of predictive search. Fast-JEPA reorganizes predictive computation to support effective action-sequence search at low planning cost. It constructs a goal-directed plan to guide search and directly predicts the…

Read at arXiv (research papers)

arXiv (research papers) Hyunjun Park

CRAFT: Analog Circuit Design by Reasoning LLM Agents from Pre-Computed Lookup Tables

Automated analog circuit sizing methods, from black-box optimizers to recent large language model (LLM) agents, typically search the design space with a SPICE simulator in the loop, whereas an experienced designer works out a design by hand analysis. This paper presents CRAFT, a flow in which an LLM agent designs a given topology by calculation, as a designer does, and without an initial sizing. The agent works only through DeX, a service that uses pre-computed lookup tables…

Read at arXiv (research papers)

arXiv (research papers) Frédérick Martin

Multiple-Camera Tracking of Rigid Objects

In this paper we describe a method for tracking rigid objects using one or several cameras. The tracking process consists of aligning a 3-D model representation of an object with image contours by measuring and minimizing the image error between predicted model points and image contours. The tracker behaves like a visual servo loop where the internal and external camera parameters are updated at each new image acquisition. We study in detail the Jacobian matrix associated…

Read at arXiv (research papers)

arXiv (research papers) Youssef ElNahas Tech policy

Verifiable Logic in Medical LLMs: A Critical Review of Agentic Clinical Reasoning Optimization and Neuro-Symbolic Grounding

Clinical large language models are usually judged by whether the final answer is right. Yet a model can reach a fluent, plausible output through invalid reasoning that static benchmarks do not detect, and confident hallucination, causally invalid inference, and spurious demographic shortcuts can pass conventional evaluation. This critical review covers four paradigms in turn: how clinical hallucination arises and why static metrics miss it; the agentic hallucination cascade…

Read at arXiv (research papers)

arXiv (research papers) Xinzhuang Xiong

Meta-RTL: Evolving Agent Harnesses for RTL Optimization

Large language models enable agents to optimize RTL using EDA feedback, yet their executable search procedures remain largely hand- engineered. We present Meta-RTL, an EDA-grounded framework that evolves RTL optimization harnesses from a minimal loop while keeping the optimization model, EDA flow, and per-design budgets fixed. Compared with Dr. RTL, Meta-RTL* reduces aggregate WNS/TNS violations by 7.8%/11.0% across 20 development designs, with area reductions on 70% of…

Read at arXiv (research papers)

ReliefWeb HALO Trust

Quarter of a Million Landmines Removed from Zimbabwe - The HALO Trust has destroyed four mines per person in north-east Zimbabwe

Countries: Zimbabwe, Afghanistan, Angola, Colombia, Sri Lanka, Syrian Arab Republic, Ukraine, Yemen Source: HALO Trust Harare, Zimbabwe, 19 Nov. The world’s largest landmine clearance charity, the HALO Trust, has reached a significant milestone in Zimbabwe, destroying 250,000 landmines since 2013. Dense belts of landmines, including the highly sensitive R2M2 models, were laid along Zimbabwe’s borders with Mozambique and Zambia during the Liberation War in the 1970s. They’ve…

Read at ReliefWeb

Help Net Security Industry News Security

Palo Alto Networks to acquire Applied Compute for $4.5 billion

Palo Alto Networks will acquire Applied Compute, a platform for post-training and inference of open-weight AI models. The all-stock transaction is valued at $4.5 billion, subject to adjustments. The acquisition will bring Applied Compute’s platform and world-class AI research team to Palo Alto Networks to help enterprises adopt AI securely, whether they choose open-weight models, closed frontier models, or both. Palo Alto Networks believes the future of enterprise AI is…

Read at Help Net Security

Tech.eu John Reynolds Startups

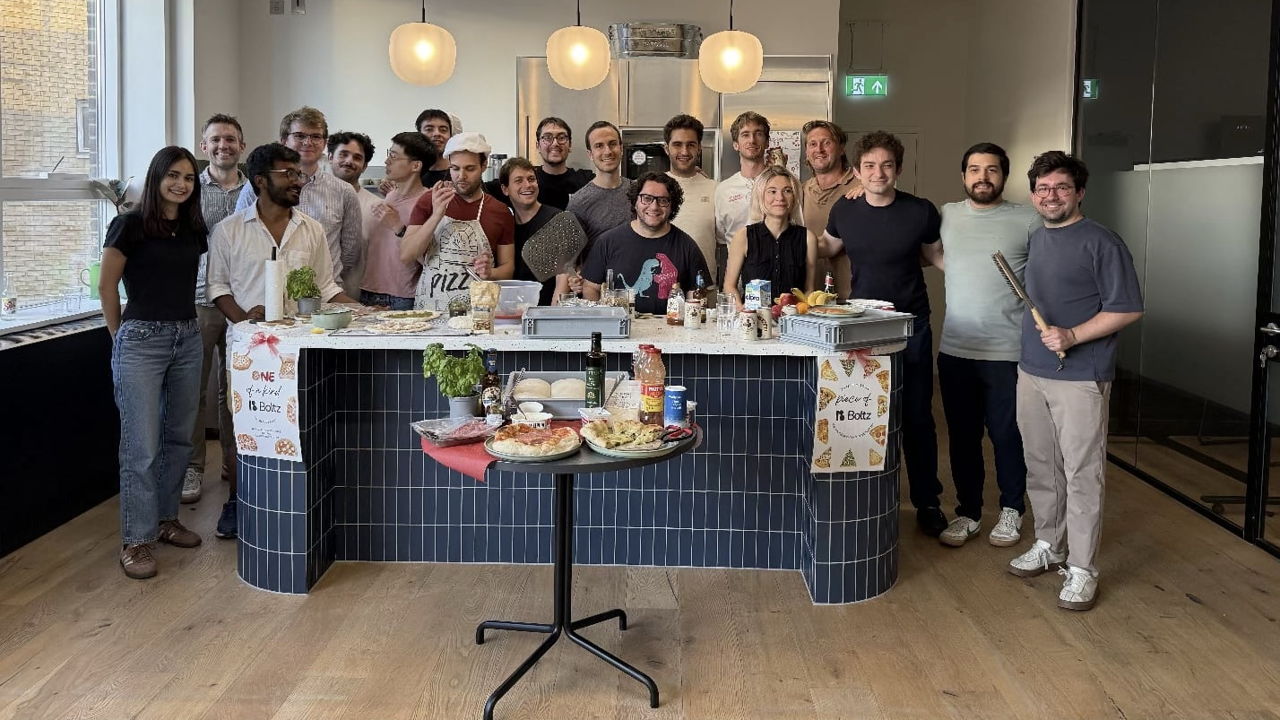
London-based Boltz raises $110M Series A

London-based AI drug discovery startup Boltz has raised a $110m Series A round, less than a year after emerging out of stealth.Boltz is an AI research startup that develops AI models to speed up drug ...

Read at Tech.eu

VietnamPlus (Vietnamese state media)

Vietnam poised to bridge differences among APEC economies

Vietnam’s two previous APEC host years demonstrate its ability to translate shared priorities into action programmes. At the 2006 forum in Hanoi, members adopted a plan outlining specific measures and timelines to facilitate trade. In Da Nang in 2017, cooperation expanded to cover inclusive development and human resource training in the digital era. Vietnam officially takes over as APEC 2027 host Phu Quoc targets model security, civility status as APEC 2027 host Hai Phong to…

Read at VietnamPlus (Vietnamese state media)

NPR John Ruwitch

AI giant Anthropic raises more than $100 billion in record-setting IPO

Shares in the maker of the popular Claude artificial intelligence model will start trading on the Nasdaq Thursday.

Read at NPR

Analytics India Magazine Ridhika Basnet SI

Can Simulated Users Replace Weeks of Testing Products? Vectorial AI Thinks So

The startup is targeting businesses in India, the US, and Canada with AI-generated audience simulations. It plans to expand its behavioural models and product

Read at Analytics India Magazine

Digital Trends Vikhyaat Vivek

Microsoft’s new AI coder is gunning for Claude and ChatGPT. It’s coming with a price advantage

Microsoft has launched two homegrown AI coding models that promise performance comparable to expensive OpenAI and Anthropic alternatives at a fraction of the cost, with both already available in GitHub Copilot.

Read at Digital Trends

arXiv (research papers) Pironti Francesco Aurelio Security

ALIoTh: Orchestrating Multi-Agent LLMs for Autonomous IoT Penetration Testing

Penetration testing in Internet of Things (IoT) environments, especially those composed of various different devices, e.g., smart plugs, smart cameras, and smart doors, presents great challenges across the phases of information gathering, attack surface enumeration, privilege escalation, and lateral movement. This paper introduces ALIoTh, a multi-agent, workflow-driven penetration testing framework that integrates Large Language Models agents within a…

Read at arXiv (research papers)

The Decoder Jonathan Kemper SI

OCR models now digitize a million pages for under $130 as costs drop fivefold in 18 months

Pulling text out of scanned books and records has gotten a lot cheaper with freely available AI models. The article OCR models now digitize a million pages for under $130 as costs drop fivefold in 18 months appeared first on The Decoder.

Read at The Decoder

arXiv (research papers) Xianyu Tan Space

The Atmospheric Circulation of Cloudy Hot and Ultra-hot Jupiters: the Need for Dissipation of Large-scale Flows to Reduce the Nightside Brightness Temperatures of Ultra-hot Jupiters

We perform general circulation modeling of hot and ultra-hot Jupiters across equilibrium temperatures of T_eq=1600 to 2800 K, incorporating cloud formation and its feedback on atmospheric dynamics. This study specifically examines whether clouds explain the systematically low nightside brightness observed in Spitzer thermal phase curves of ultra-hot Jupiters. We found that clouds generally increase phase-curve amplitudes and reduce eastward offsets, and these effects are…

Read at arXiv (research papers)

arXiv (research papers) Jinkun Cao

Fast and Accurate Body Estimation in Pixels, World Space and Scenes

We present FAB (Fast and Accurate Body estimation), a human body estimator that jointly improves inference efficiency and body-recovery fidelity. Rather than predicting only parametric mesh-model parameters, FAB directly predicts human skeleton joints and dense surface points. In images, it predicts dense 2D and 3D body points alongside a parametric Momentum Human Rig (MHR) head, then fits SMPL in one learned pass followed by two Gauss-Newton steps. Its ViT-L student, FAB-L…

Read at arXiv (research papers)

arXiv (research papers) Wai Ka Sun

Collision-Free Is Not Enough: Passage-Conditioned Navigation for Wheeled-Legged Robots

A collision-free detour can still bring a legged robot to the next stair or ledge a few centimetres or degrees off, and a fixed locomotion skill, factory or learned, can stall or fall. Existing methods prevent this with a robot model or extensive trial and error, but on a new site with unknown skills neither is available, so they cannot be used. We find that a single 27-minute teaching session already supplies what these methods have to derive or learn: for every stair and…

Read at arXiv (research papers)

arXiv (research papers) Xingyi Wang

ECHO: In-Context Behavior foundation model for Humanoid Whole-Body Control

Humanoid behavior foundation models (BFMs) acquire diverse skills through large-scale motion imitation and massively parallel reinforcement learning, yet broad behavioral capability does not ensure precise execution across physical conditions. Without distinguishing the underlying dynamics, policies may favor conservative compromises over environment-specific precision. We introduce ECHO, an in-context BFM that turns interaction experience into environment-specific control…

Read at arXiv (research papers)

The Register Thomas Claburn

Google continues model chemistry experiment with Neon

Which model to choose? It's elementary but not obvious

Read at The Register

Semiconductor Engineering Taeyeon Oh SI

How Virtual Twins And Machine Learning Optimize DRAM Yield

Model process variation, detect multiple failure modes, and evaluate solutions with less wafer experimentation.

Read at Semiconductor Engineering

Semiconductor Engineering Silvaco

Simulation of Plasma Chambers for Predictive Simulation of Semiconductor Manufacturing

Linking plasma chamber simulation with feature-scale process modeling to predict etch profiles, evaluate wafer uniformity, and optimize plasma etching processes.

Read at Semiconductor Engineering

arXiv (research papers) Kai Shi

LeCompass: Task-Level Execution through State-Indexed Interfaces

Action-conditioned joint-embedding predictive architectures (JEPAs) offer a foundation for predictive decision-making by modeling the consequences of actions in representation space. Yet evaluating local reachability in latent space does not by itself provide a task-level execution interface: intermediate targets must be generated, local inference has finite budgets, and execution requires spatial feedback and persistent interaction state. We introduce LeCompass, a…

Read at arXiv (research papers)

Older stories