LLMs will provide accurate climate info, except when they won’t
Some models fare better, but all fail in similar ways.
Some models fare better, but all fail in similar ways.
On 1 January 1996, Germany transferred responsibility for regional passenger rail services from the federal government to the states. Three decades later, passenger-kilometres have doubled and competitive tendering has lowered operating costs substantially, making regionalisation the most successful element of the German rail reform. Its organisational model, however, has reached the end of its life cycle: tenders now attract on average only 1.3 bids, 26 contracting…
Ground-state measurement statistics characterize quantum matter. Selected correlations can guide the classical training of a quantum sampler even when sampling the full distribution is difficult. We ask whether training across related ground-state distributions helps the sampler reproduce their correlations more accurately. We train a hypernetwork to map Hamiltonian parameters to circuit angles, sharing information across the phase diagram before local fine-tuning with…
Remark: This work is in submission at STOC'27 and thus the full manuscript has been publicly posted on the conference website since November 3rd, 2026. Inspired by the Codeword-Hash Structure problem recently introduced by Cakan (arXiV, 2026) to separate $\mathsf{QMA}$ from $\mathsf{QCIP}$, we introduce a new problem called Codeword-Hash pairs in Noise ($\mathsf{CHN}$) and prove that, in the query complexity model, it is in $\mathsf{QMA}$ but hard for the $\mathsf{QCMA}$…
China’s expansive export-control system is in key respects modeled on that of the United States. But there is an important difference.
Vision-Language-Action (VLA) models have advanced rapidly in language-conditioned robotic manipulation, yet existing benchmarks mainly evaluate gripper--object contact and largely ignore how objects interact with the environment through gravity, friction, inertia, and mass distribution. As a result, it remains unclear whether current policies truly understand physics or merely interpolate from their training data. We address this gap through the lens of dynamic extrinsic…
Barrett's esophagus dysplasia grading suffers substantial inter-observer variability, particularly for low-grade dysplasia, complicating clinical decision-making. We conducted a retrospective multi-institutional diagnostic accuracy study of a foundation model-based deep learning system for dysplasia grading, using 969 H\&E-stained whole slide images from four institutions. Patch-level classifiers trained on expert annotations identified diagnostically relevant regions…
When multimodal decision models determine actions, moderation outcomes, or quality judgments, their reliability depends on preserving semantic decisions across presentation changes, ignoring irrelevant additions, and distinguishing information consistent with task evidence from information that conflicts with it. Existing evaluations study decision-interface biases and multimodal model behavior in separate settings, leaving no common protocol to compare multimodal decision…
Agents based on large language models (LLMs) can now delete files and send payments on behalf of their users. News media reports routinely describe failures of these agents (e.g., Replit's coding agent deleting a production database), but a report often only says what went wrong and rarely (in)validates the incident or finds its root cause. Incident catalogs collect these reports, and benchmarks record whether agents fail, but neither replicates an incident nor tests the…
Linear probes are the cheapest LLM lie detectors but often fail to transfer across kinds of lie. Label-free directions from honest and deceptive role-play are untested at 70B scale and on lies about knowledge, where a lie and an honest denial can be identical. We widen a published persona bank with roles that deny knowledge they have, plus honest counterparts. At each model's middle layer the resulting persona direction ranks lies across Liars' Bench better than…
Current audio-driven video diffusion models can synthesize realistic talking-head videos but generally require dozens of diffusion denoising steps over multi-second video chunks, making them unsuitable for streaming applications such as voice assistants and virtual avatars, where low-latency and online causal generation are required properties. AURA generates video chunk by chunk with a rolling KV cache, requiring only the audio of the current chunk to start generating…
Intersectional bias arises when a model treats people who hold several marginalised identities at once differently from what their separate identities would predict. Auditing such intersectional subgroups remains a challenge: their number grows quadratically, and there is no agreed baseline for what independent attributes would predict. Without such a baseline, many existing audits flag a subgroup when it exceeds each attribute alone, a condition that attributes acting…
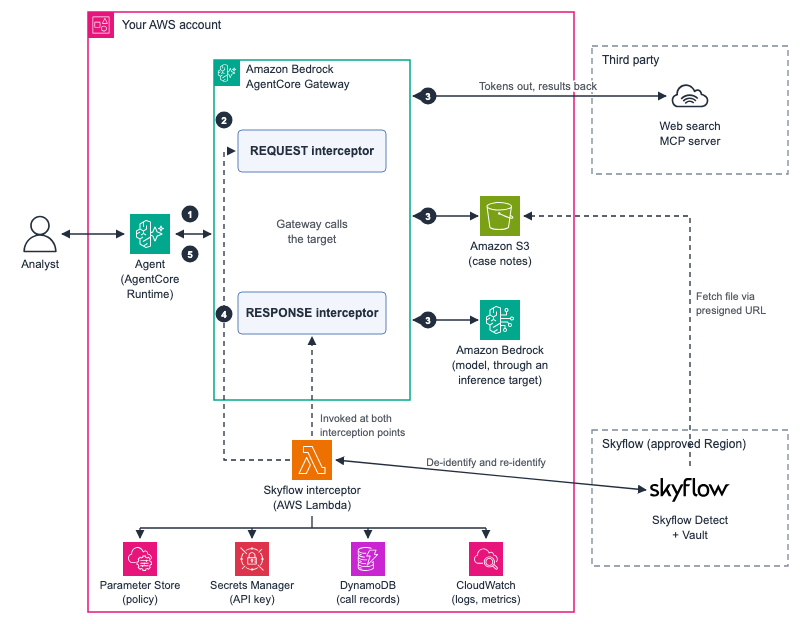
Learn how Skyflow and Amazon Bedrock AgentCore Gateway keep sensitive data out of the tools your AI agents call. Added as a gateway interceptor, Skyflow de-identifies data before any tool, model, or log sees it, and restores it for authorized callers, with no change to your agent code.
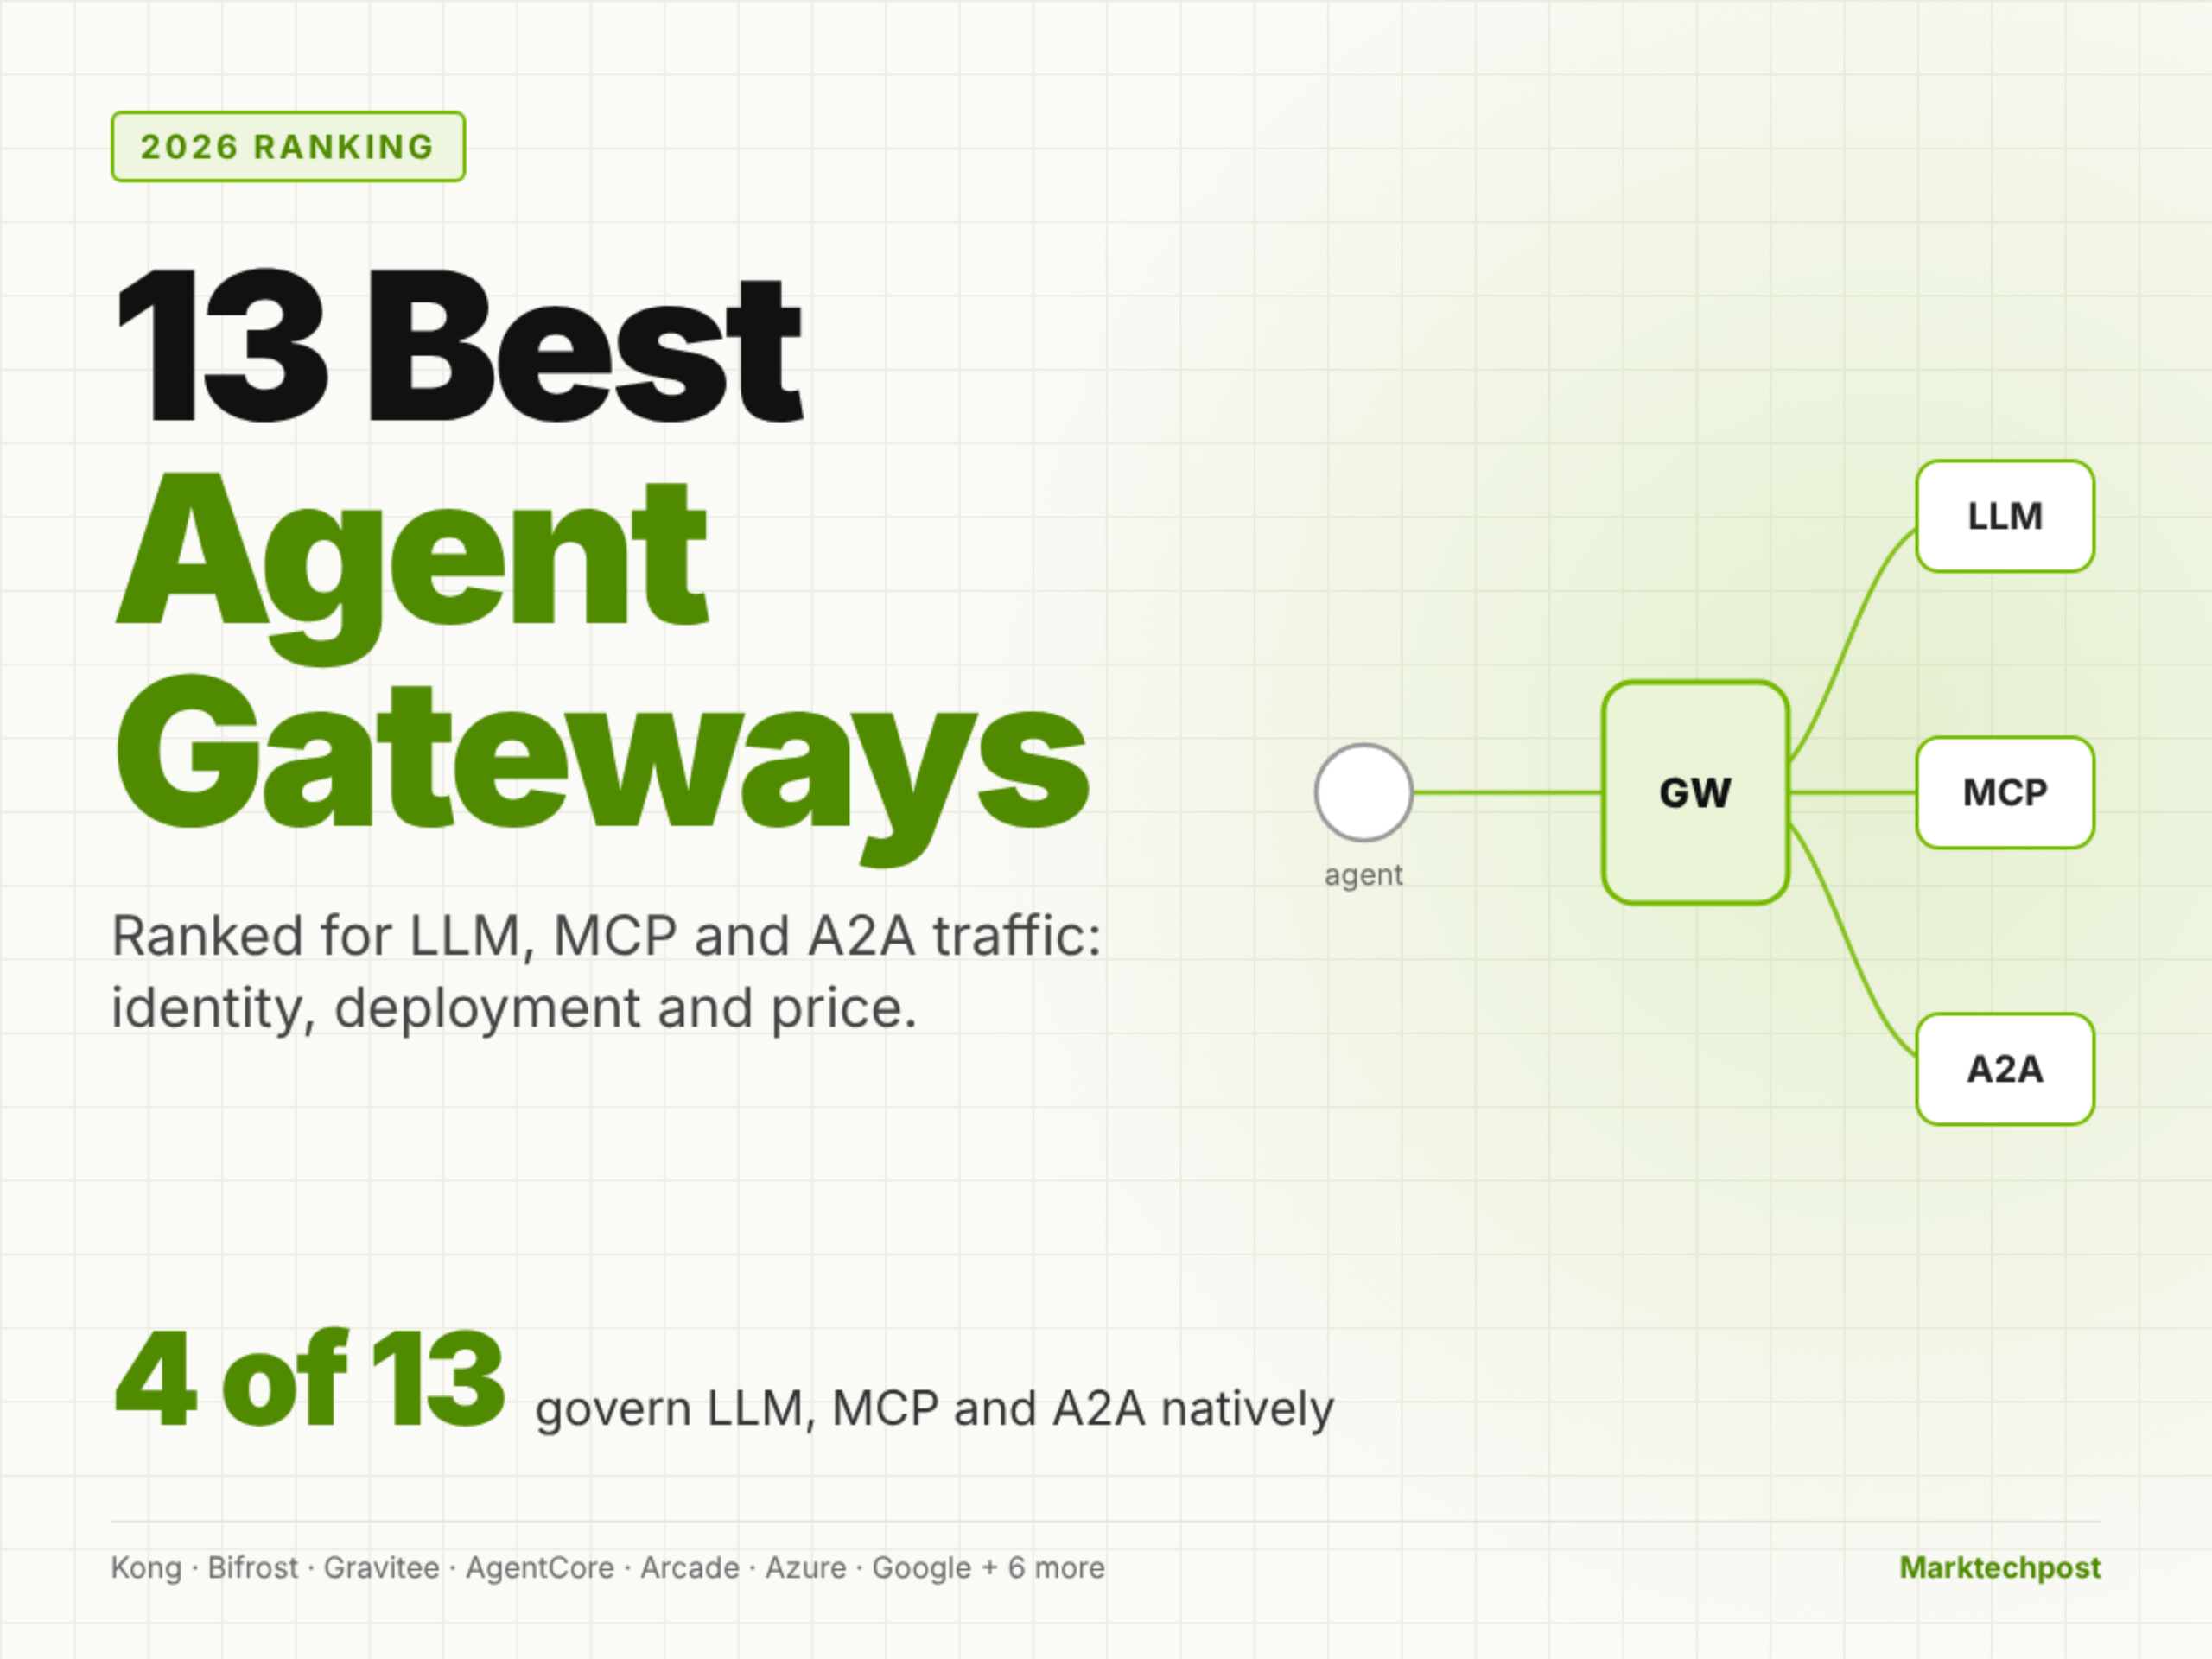
We ranked the 13 best agent gateways of 2026 by how they govern model, MCP tool and agent-to-agent traffic, with verified pricing, deployment options and the trade-offs each vendor's marketing leaves out.
Large Web platforms operate large fleets of ranking models, each selecting features from a shared pool of tens of thousands. We present an end-to-end agentic system that optimizes features across the fleet under resource constraints shared across models and those set per model, such as feature pipeline cost and serving throughput (QPS), respectively. In this system, LLM agents propose hypotheses, and deterministic tools execute experiments and verify them. For each model, an…
Pongbot's Black Friday offers include six AI-powered training packages for tennis, pickleball and padel, with Aura models starting at $599.99 and Pace S Pro options for dedicated tennis players.
Collective two-photon light--matter interactions enable pair amplification but can destroy spectral confinement, preventing a stable thermodynamic bright phase. We show that a positive Kac-scaled number-Kerr interaction renders the two-photon Dicke Hamiltonian of \(N\) emitters lower-bounded at all couplings while preserving its generalized \(\mathbb Z_4\) symmetry. We determine the exact zero-temperature thermodynamic energy density with \(O(N^{-1})\) finite-size control…
Reliable reasoning for long-horizon embodied tasks requires predictions grounded in the observed execution state. We present ACE-Brain-0.7, a 9B vision--language model that combines spatial grounding, task understanding, and progress estimation. To train the model, we curate 3.7 million question--answer pairs, drawing execution supervision from egocentric human videos, robot episodes, and simulation. These questions span different stages of an execution and connect…
Improving microprocessor performance while meeting ASIC implementation constraints like area and frequency is a complex and labor-intensive task that requires expertise across computer architecture, hardware design, and performance analysis and profiling. While large teams in industry can afford the engineering resources to target this problem across performance modeling, RTL design, and ASIC implementations, small teams of researchers and engineers cannot take on this huge…
Decision models enable fast, confidence-aware decisions by scoring candidate answers in a single forward pass, without generating text or intermediate reasoning. Yet reasoning can substantially improve decision quality, raising the question of whether its benefits can be retained without the cost of generating it. We investigate this question with \textbf{GLiDE}, a family of decision models spanning 0.4B to 27B parameters. Building on Qwen hybrid language models, GLiDE…
Commercial video-generation APIs bill by model and tier, while intermediaries could substitute cheaper models, lower tiers, or cached clips. What can a delivered file establish about its origin? We combine measurements of passive attribution and cryptographic provenance into a graded audit. We test attribution probes and zero-shot detectors under re-encoding, downscaling, and frame-rate changes, and survey C2PA and GB 45438 metadata across 19 commercial endpoints. Only…
Experimental demonstrations of quantum error correction often exhibit noise that varies across space and time, and attempting to characterize this disorder has been shown to substantially improve decoding performance. However, theoretical studies of quantum error correction typically assume fixed, perfectly known, homogeneous noise. Here we model decoding with incomplete or inaccurate knowledge of disordered noise channels by treating physical error rates as random…
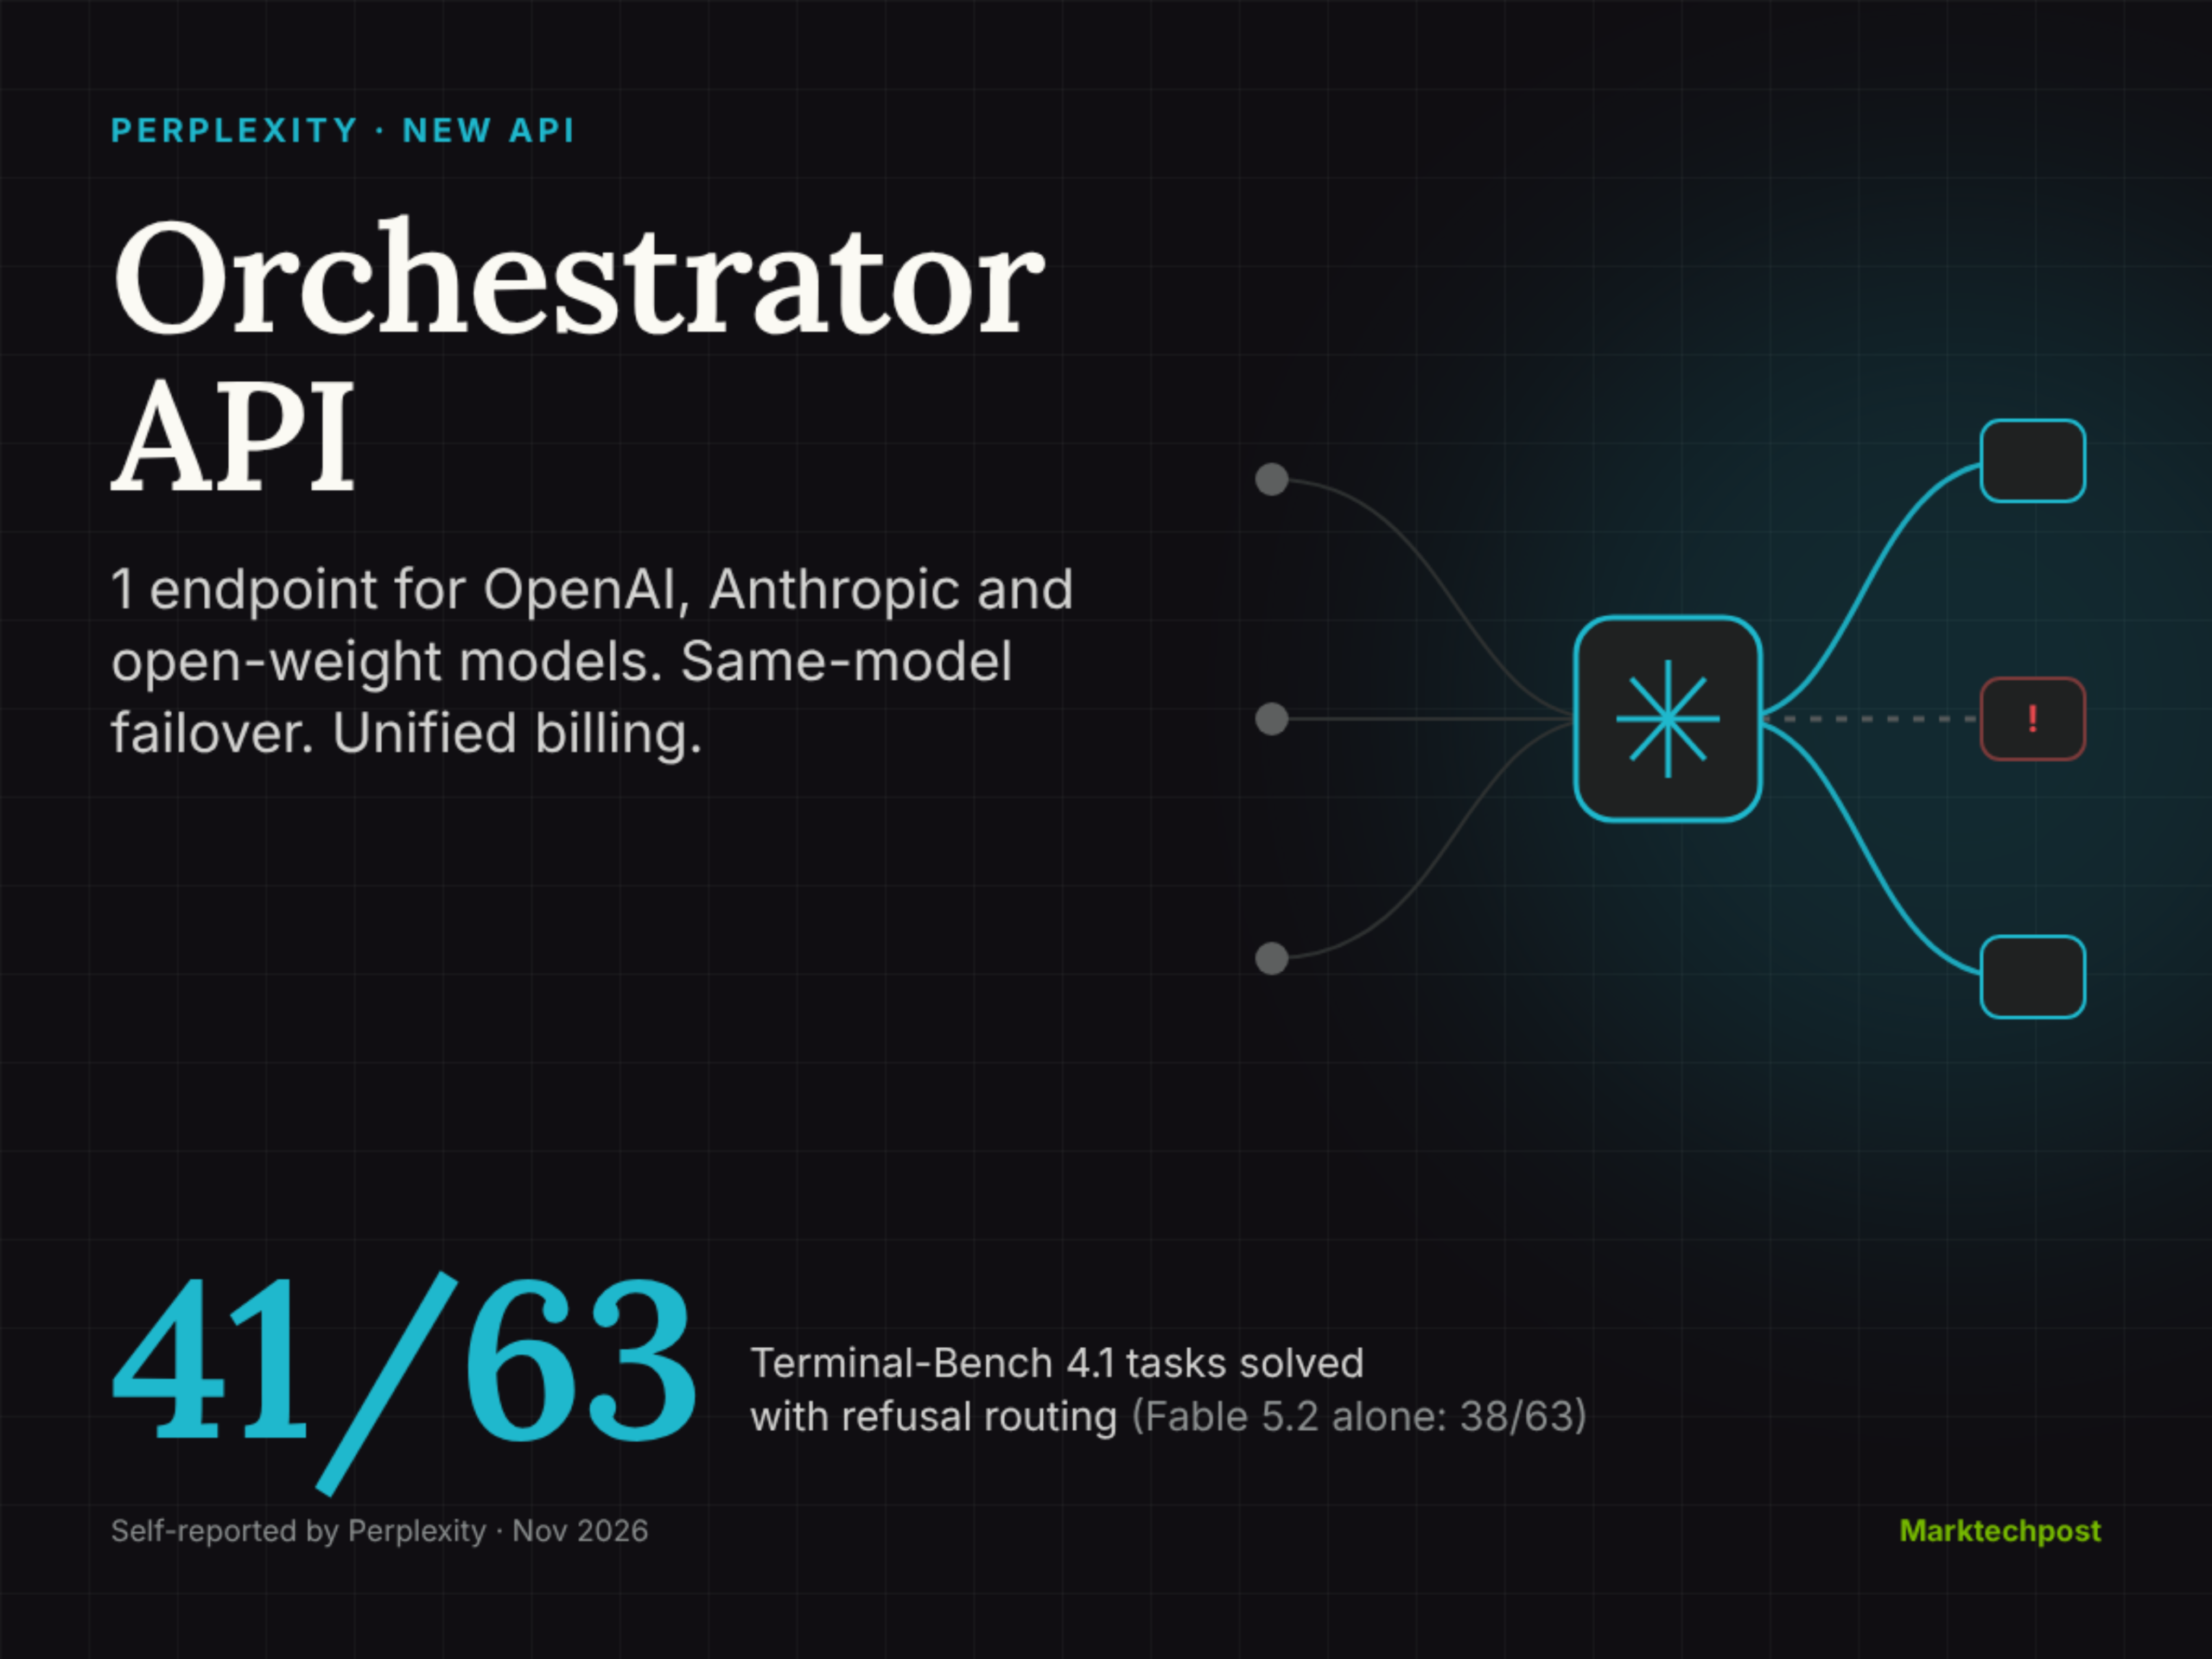
Perplexity’s Orchestrator API serves OpenAI, Anthropic, Google, xAI and open-weight models through 1 endpoint, with same-model provider failover, unified billing and a preview perplexity/auto router that sends each request to a described route.
Real-time task guidance is inherently flexible: when an agent guides a user through a task, multiple responses and timings can be appropriate, and sometimes the best action is to remain silent. Existing benchmarks often miss this flexibility by treating synthesized dialogues as fixed targets for what to say and when to say it. We introduce FLUID (Flexible, Evidence-Grounded Situated Task Guidance), a unified framework for modeling, evaluating, and enabling flexible…
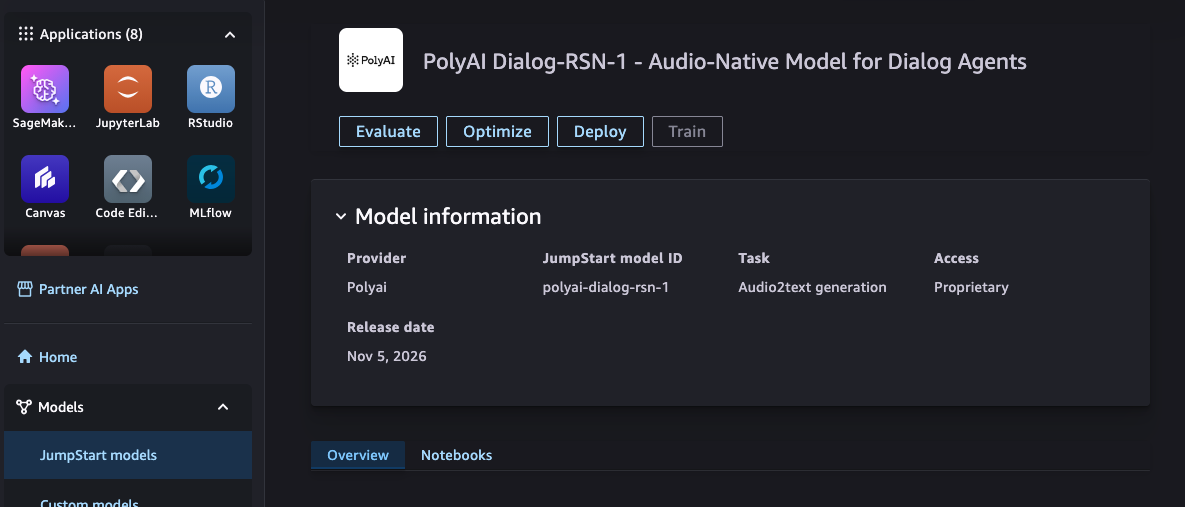
PolyAI Dialog-RSN-1, a reasoning model built for real-time complex dialog, is available today on AWS Marketplace and Amazon SageMaker JumpStart. Discover it, evaluate it on your own data, and deploy it to a secure SageMaker endpoint in your own AWS account.
Pretrained language models (LMs) remain unreliable on exact multi-digit arithmetic without gradient fine-tuning or external tool interpreters. We introduce closed-form, zero-gradient circuit-grafting primitives that compile deterministic computation directly into pretrained LM weights using zero training examples and zero runtime hooks, while bounding per-layer normalization drift and preserving natural-language (NL) competence. Our construction combines three analytical…
Black Friday brings substantial savings on portable projectors, 4K laser models, and home theater upgrades, including $200 off Optoma's Photon Go and discounts from Epson, JMGO, Dangbei, and XGIMI.
alt: Amazon’s last-gen Kindle Paperwhite is just $10 more than the base modelalt: The last-gen Kindle Paperwhite for $130 is a stellar Black Friday deal Amazon debuted its latest Kindle Paperwhite in October, which is now available for $199.99 and replaces the outgoing 2024 model. However, given the minimal improvements on the new model —
Frontier text-to-image (T2I) foundation models predominantly rely on multi-billion parameter Diffusion Transformers (DiTs) pretrained across massive compute clusters, creating an accessibility barrier for academic laboratories. When training DiTs from scratch on single consumer GPUs (e.g., an NVIDIA RTX 4090 with 24\,GB VRAM), practitioners encounter three primary bottlenecks: quadratic attention sequence costs, Just-In-Time (JIT) compilation graph breaks induced by variable…
Company still has to content with massive compute obligations and the threat of open models, neither of which Dario Amodei is worried about, he claims