India’s Sarvam AI launches GPU service for open models
Sarvam said Sarvam Token Factory runs on privately procured GPUs.
Sarvam said Sarvam Token Factory runs on privately procured GPUs.
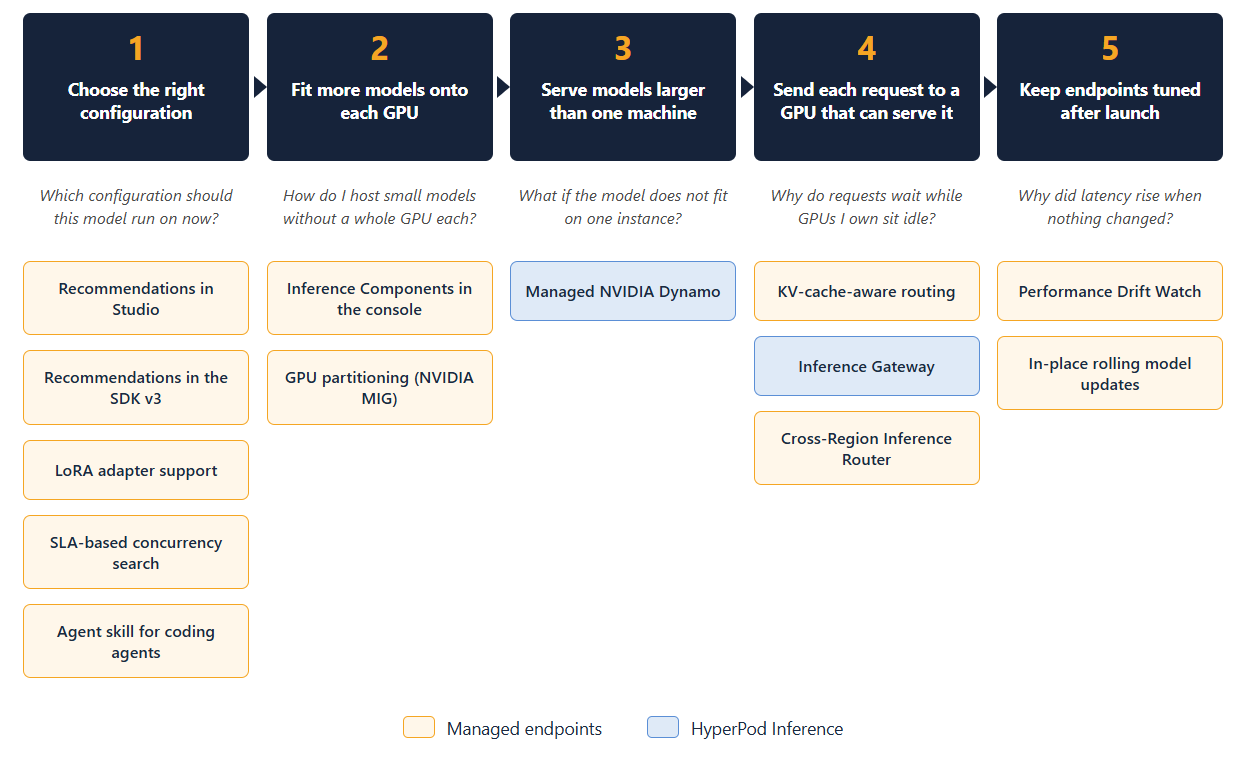
This second installment reviews 13 more Amazon SageMaker AI inference launches from 2026, spanning configuration recommendations, fitting more models onto each GPU, serving models too large for one instance, cross-Region routing, and post-launch tuning, bringing the year's total to 26.
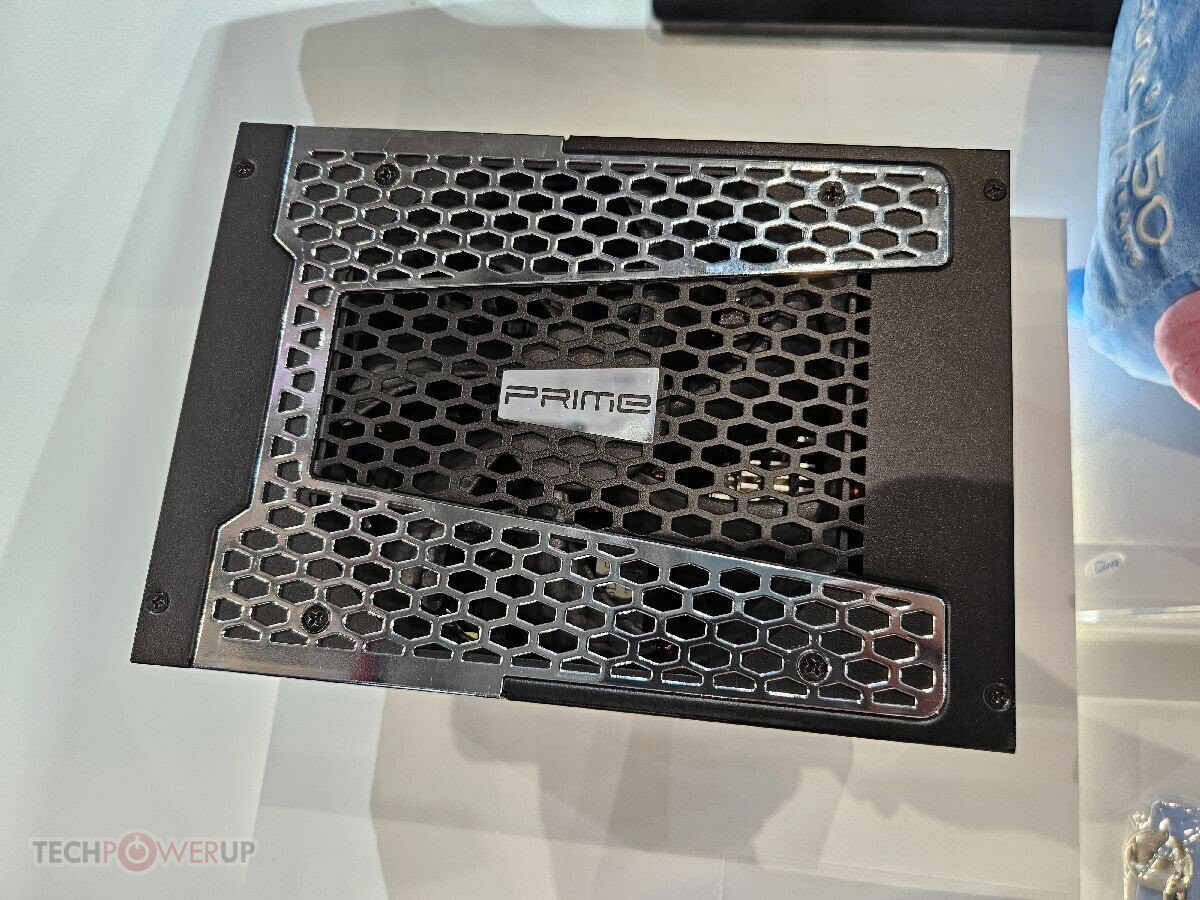
It looks like Seasonic's 3,200 W PRIME ENTERPRISE PX-3200 PSU is close to launch. As spotted by Videocardz, the company's official Weibo account posted that the new PSU is coming soon, attaching an image of Supermicro's NVIDIA GB300 AI workstation as well. The PX-3200 offers six 12V-2x6 connectors, ideal for feeding several high-end GPUs directly. It also carries 80 Plus Platinum and Cybernetics Platinum ratings, as far as efficiency goes. There's no official word on pricing…
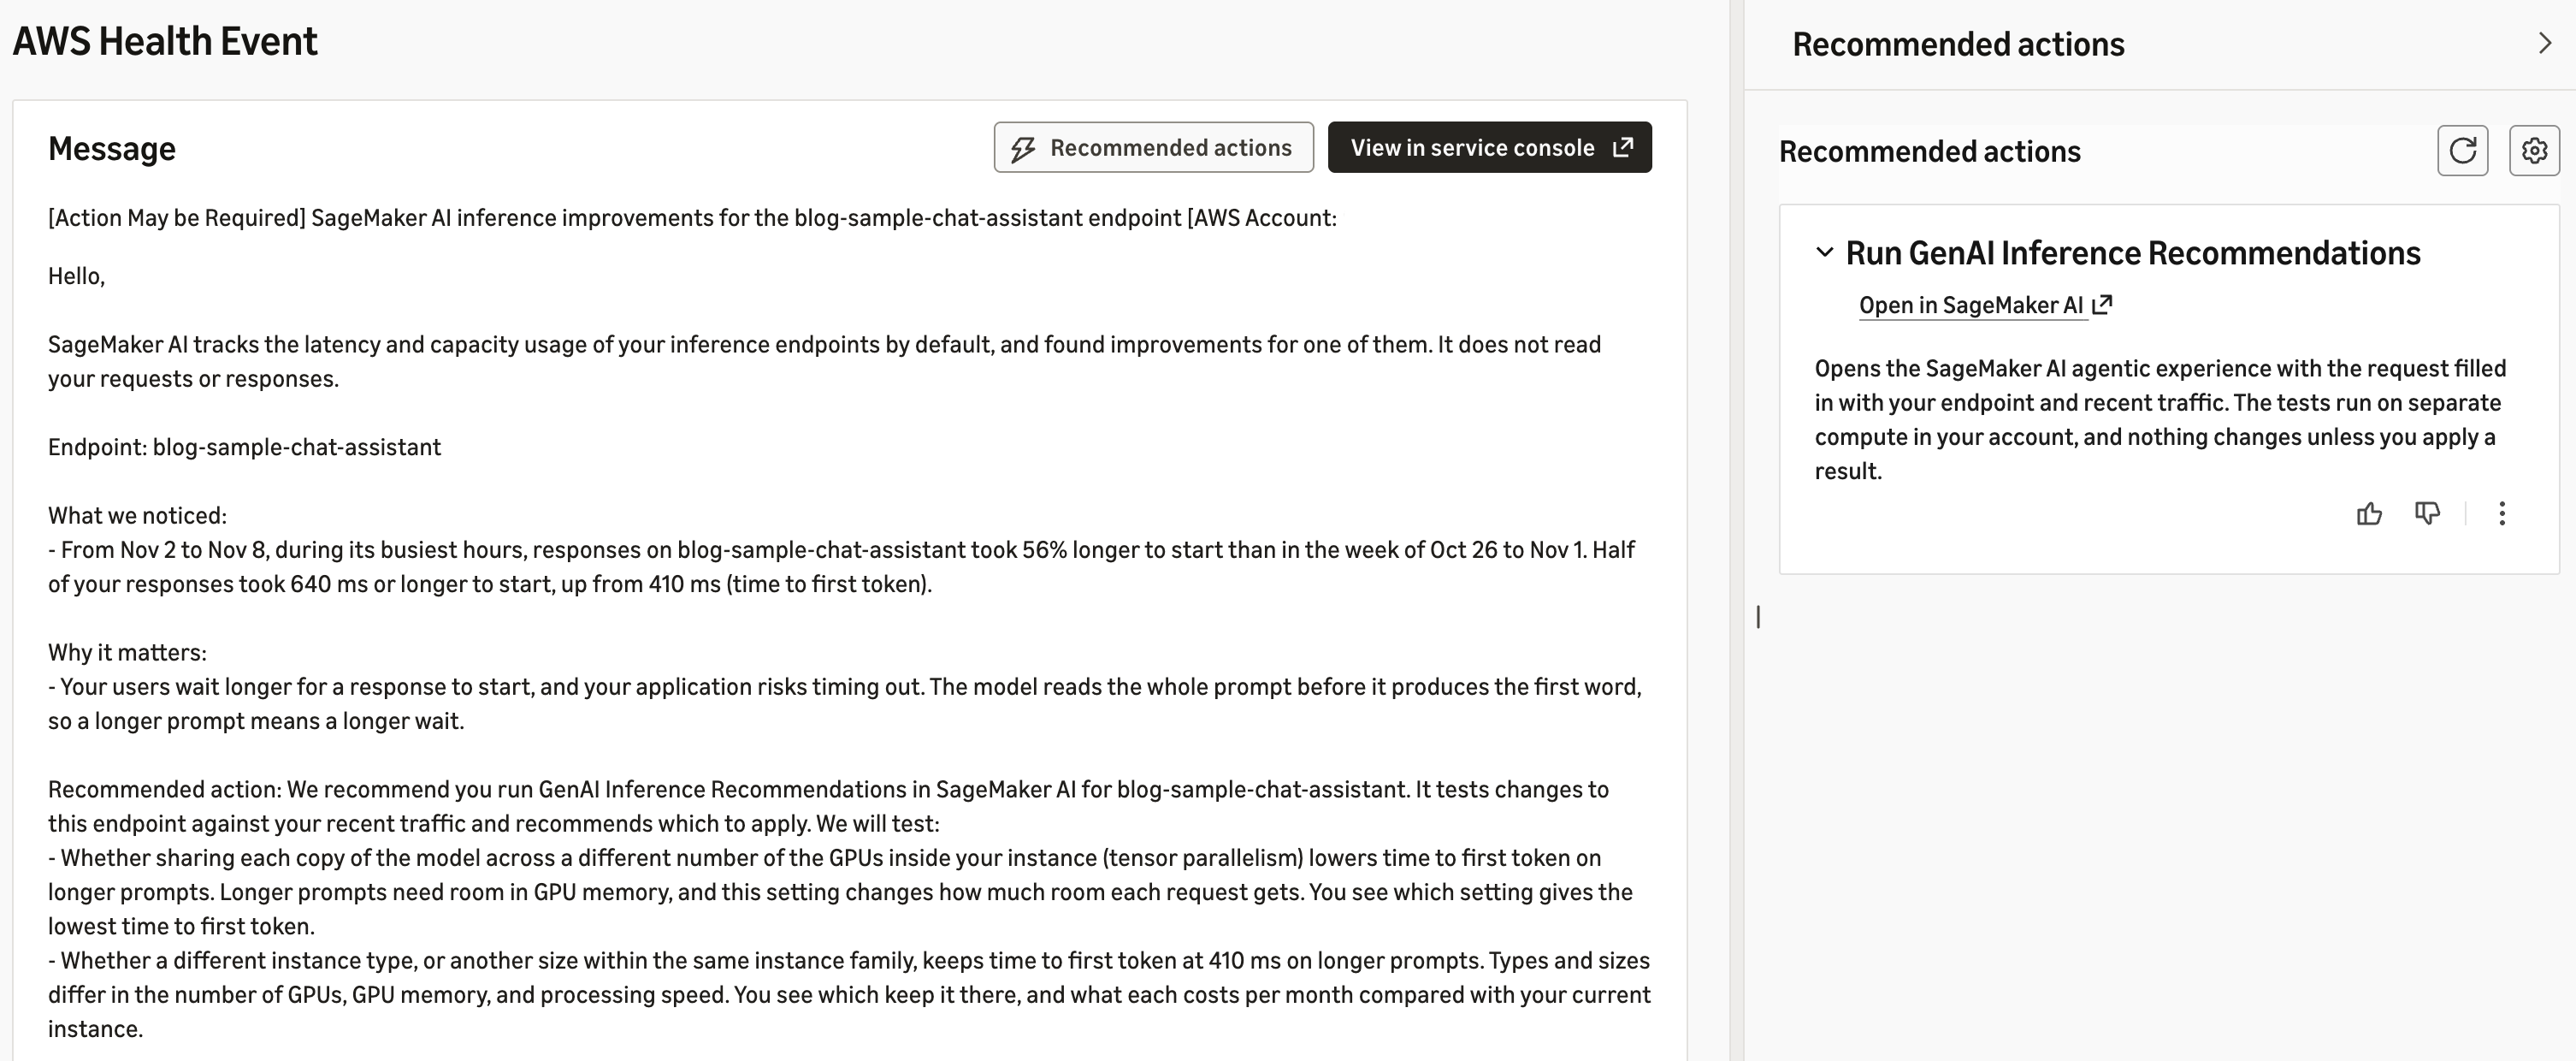
Amazon SageMaker AI now monitors your generative AI inference endpoints by default and tells you when a change could improve performance or lower cost. It tracks latency, GPU utilization, and serving configuration, then sends a finding through AWS Health with a one-click path to benchmark alternatives in SageMaker Studio before you apply any change.
Enterprise adoption of artificial intelligence is creating new requirements for enterprise AI infrastructure. While much of the early AI investment centered on access to powerful GPUs, organizations moving AI applications and agents into production are discovering that accelerators are only one part of the equation. Agentic AI systems need environments where they can execute code,
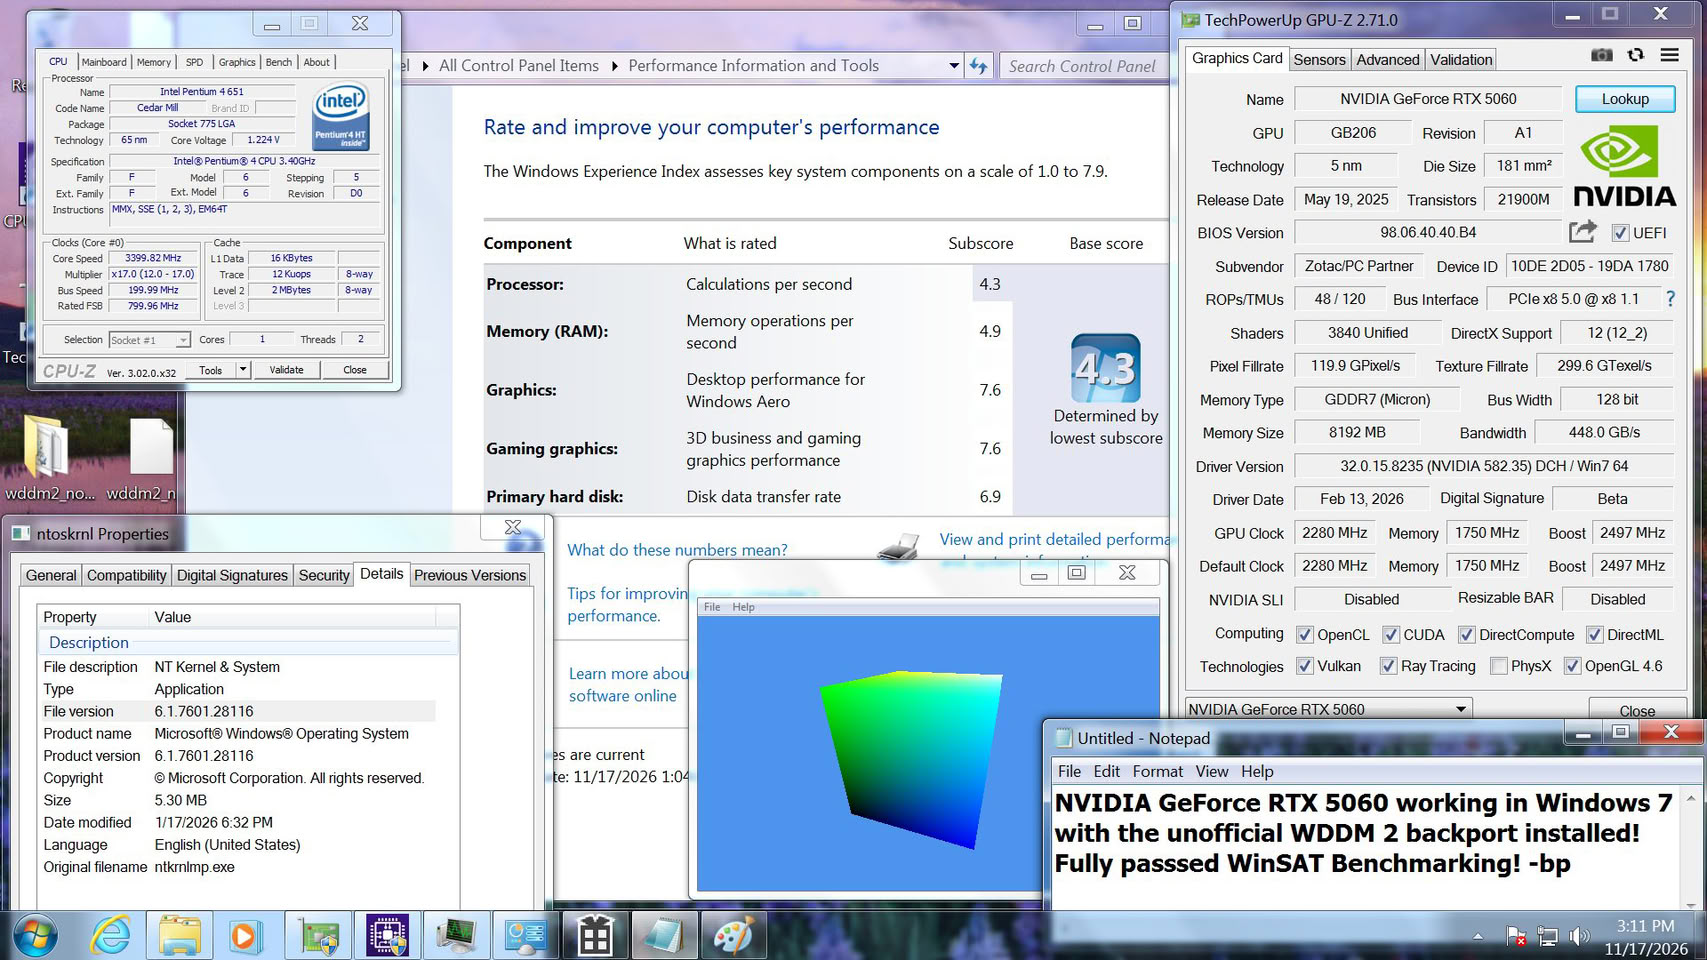
Windows 7 was a beloved operating system for many, and if you're still running a machine with that OS, this release might be for you. Three Windows 7 enthusiasts have managed to get current-generation GPUs and DirectX 12 running on Microsoft's 17-year-old OS. Bob Pony shared the project on X, called WDDM2Win7, an unofficial backport of the Windows Display Driver Model (WDDM) 2. The screenshots show Intel UHD Graphics 770, an NVIDIA GeForce RTX 5060, and an AMD Radeon RX 9060…
Enterprises pushing AI from pilot to production are learning that data, not GPUs, is the hardest part, and open table formats such as Apache Iceberg are part of the answer. Demand for AI infrastructure shows few signs of slowing, but much of the information companies need is still scattered, ungoverned and out of reach. That
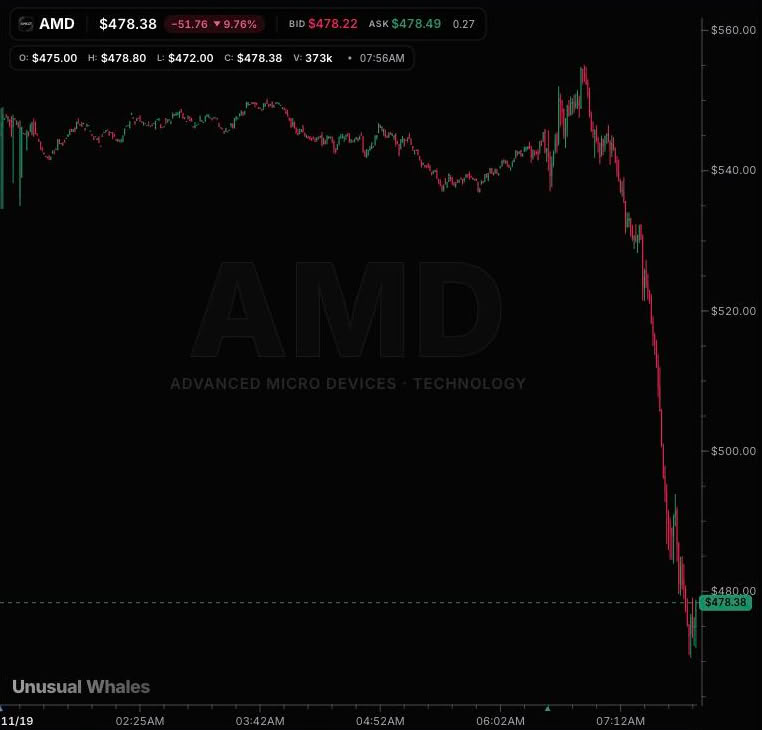
The AMD stock briefly crashed 15% in 30 minutes after a report by market research firm Hunterbrook Media alleged that AMD "has its own China problem," alleging export control violations resembling those by NVIDIA, which cost CEO Jensen Huang his job. The firm disclosed that it holds a shorting position against the AMD stock. Unlike in NVIDIA's case which involved alleged smuggling of advanced AI GPUs to AI research and inferencing firms in China; AMD has a problem with…
Frontier text-to-image (T2I) foundation models predominantly rely on multi-billion parameter Diffusion Transformers (DiTs) pretrained across massive compute clusters, creating an accessibility barrier for academic laboratories. When training DiTs from scratch on single consumer GPUs (e.g., an NVIDIA RTX 4090 with 24\,GB VRAM), practitioners encounter three primary bottlenecks: quadratic attention sequence costs, Just-In-Time (JIT) compilation graph breaks induced by variable…
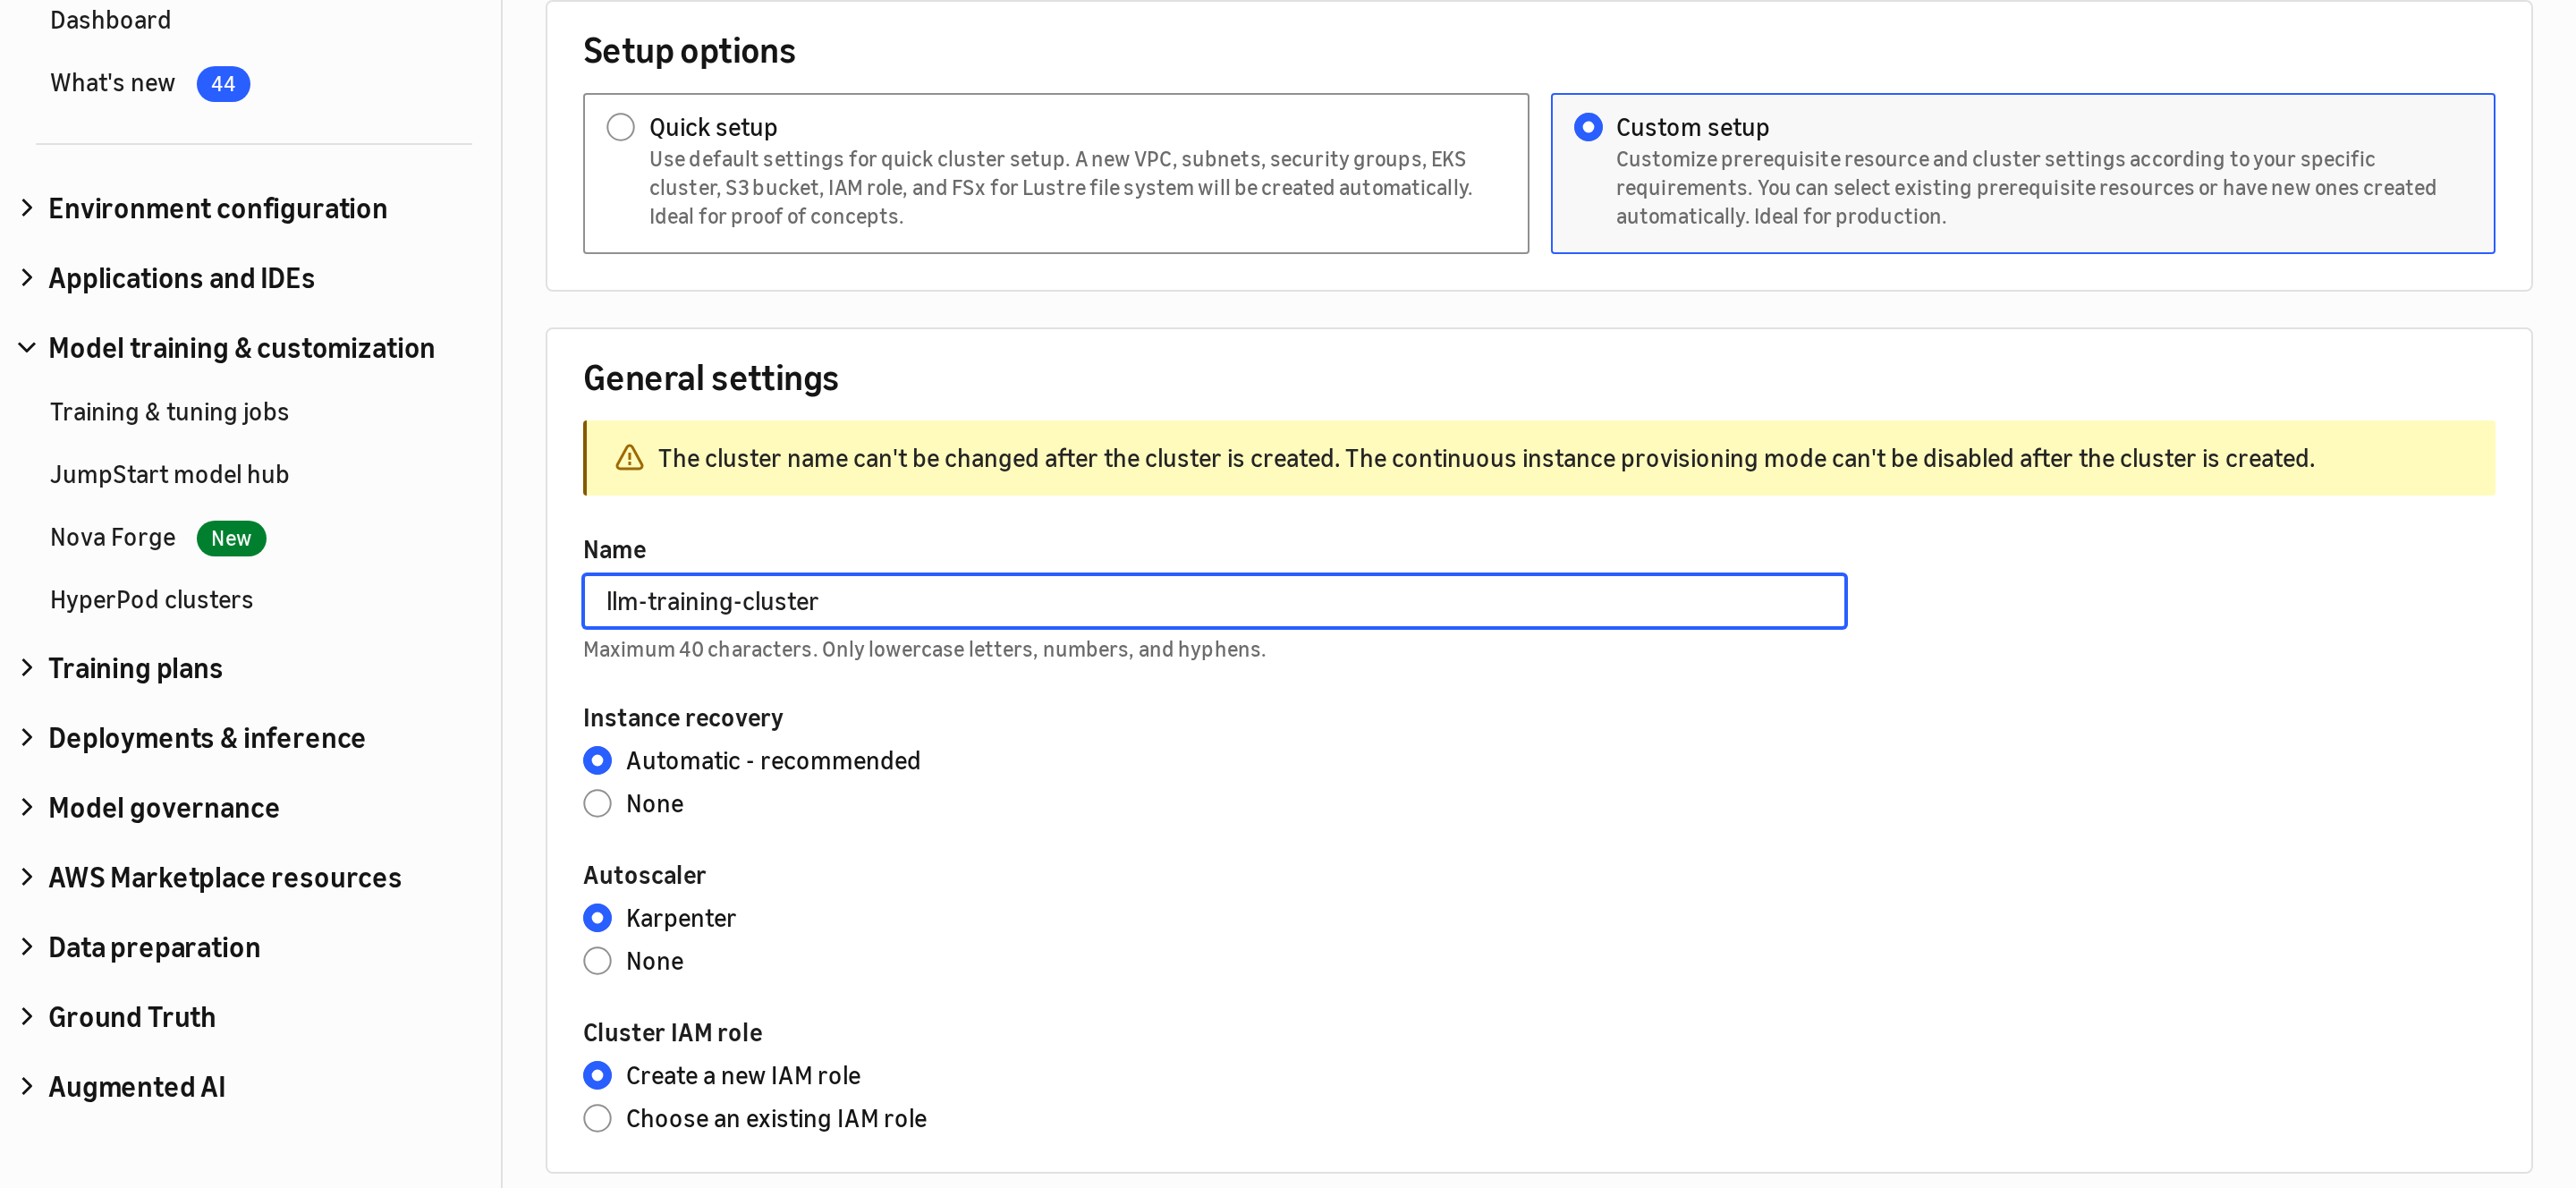
Amazon SageMaker HyperPod now offers enhanced observability to help you diagnose GPU training issues faster. It brings together diagnostic and profiling capabilities for training workloads on both Amazon EKS and Slurm orchestrators, pinpointing issues across GPU, network, and host layers.
AWS raised prices on EC2 Capacity Blocks, its reserved GPU capacity, by about 15% in January and about 20% in
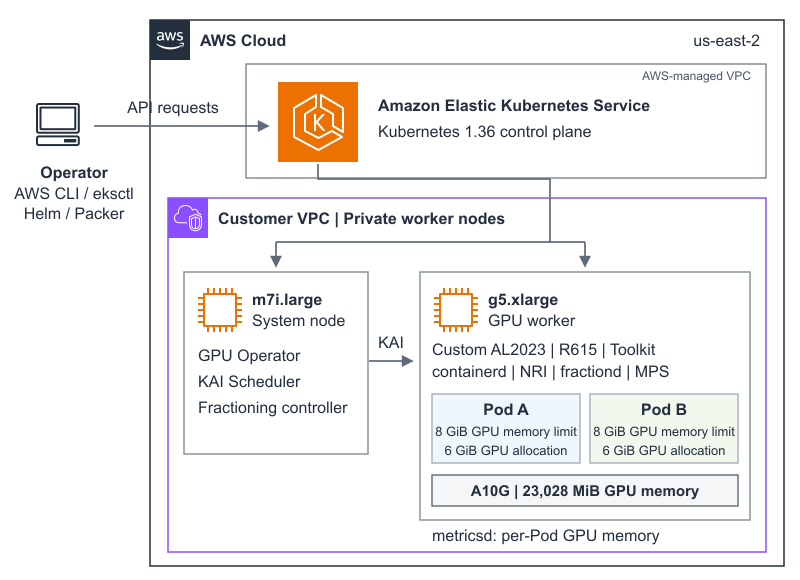
Learn how to run two memory-bounded Kubernetes Pods on a single NVIDIA A10G GPU using open-source NVIDIA Run:ai GPU Fractioning on Amazon EKS. This walkthrough builds a custom Amazon Linux 2023 image, installs KAI Scheduler and the GPU Fractioning Operator, and validates per-Pod GPU-memory contracts with enforcement and metrics.
LocoMuJoCo is an open-source benchmark for imitation learning (IL) and reinforcement learning (RL) on whole-body control. The library couples MuJoCo (CPU) with MJX and the MjWarp backend (GPU) under a single API, exposes 9 humanoid, 3 (musculo-)skeletal, and 4 quadruped embodiments, and ships a curated native motion-capture dataset for every humanoid, to which it can also retarget AMASS and LAFAN1. A modular plug-in architecture makes observations, rewards, control modes…
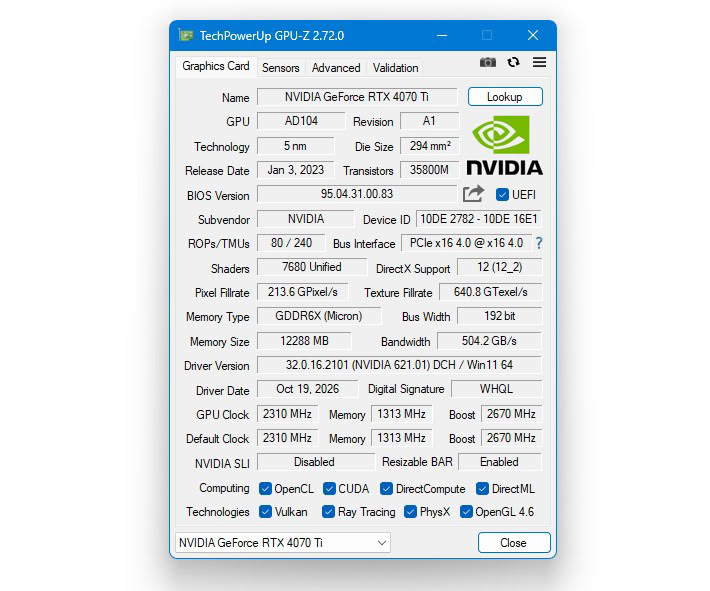
TechPowerUp today released the latest version of GPU-Z, the popular graphics subsystem information and diagnostic utility for gamers, PC enthusiasts, and engineers. Version 2.72.0 comes with support for the NVIDIA RTX Spark processor. Support is also added for a rare GeForce RTX 5070 variant based on the larger GB203 silicon; and the unreleased GeForce RTX 4090 Ti engineering sample. Over in the red team, support is added for the AMD BC-250 mining GPU; and the new Intel…
Deep learning models that predict drug--target interactions (DTI) can speed up drug discovery, but the candidate drugs they score are valuable intellectual property that their owners cannot reveal. Secure multiparty computation (MPC) lets two servers compute a prediction on a secret-shared drug, without either server learning the drug. However, secure inference of deep models is slow. Non-linear operations require communication between the servers, and MPC arithmetic does…
AWS said the feature targets workloads that need GPU acceleration but are often built on self-managed infrastructure.
Don’t hoist the Mission Accomplished banner, because company president thinks it also will spur China’s chip biz into action
NVIDIA's latest GeForce Game Ready GPU drivers are reportedly causing excessive SSD writing on multiple systems. Users have been reporting numbers of up to 30 GB per hour of SSD writes, even when no typical writing activity is occurring. With driver version 621.01 installed, the NVIDIA Display Container process recorded less than 2 MB of writes while the PC was idle. However, with the upgrade to the version 621.14, released on November 4, the same five-minute check resulted…
Search, especially top-k similarity search, plays a vital role in many applications, but its performance can be severely limited by memory access overhead. In-memory search (IMS), an alternative to CPU/GPU-based approaches, exploits massive parallelism within a content-addressable memory (CAM) array to perform search in situ and provides both low latency and high energy efficiency. However, the capacity of a single CAM array is often insufficient for modern workloads…
LLM agents alternate between inference and tool execution, repeatedly reusing their growing context across calls. Under high concurrency, their combined key-value (KV) cache working set can reach hundreds of GiB, far exceeding GPU memory capacity. As idle KV cache blocks are evicted to slower storage tiers, returning agents incur expensive retrievals that stall inference. To address this problem, we present \emph{TripleKV}, a three-tier KV cache management system that hides…
Working with AMD, OpenAI achieved up to 14 percent PPA improvement on AMD's flagship GPU IP in less than five months. According to OpenAI, that's roughly a year's worth of progress, and AMD has already folded the changes into a design sent to production. Anthropic is also applying AI to chip work to optimize cost and performance per dollar. The article OpenAI says its models delivered a year's worth of chip optimization on top of AMD's own engineering appeared first on The…
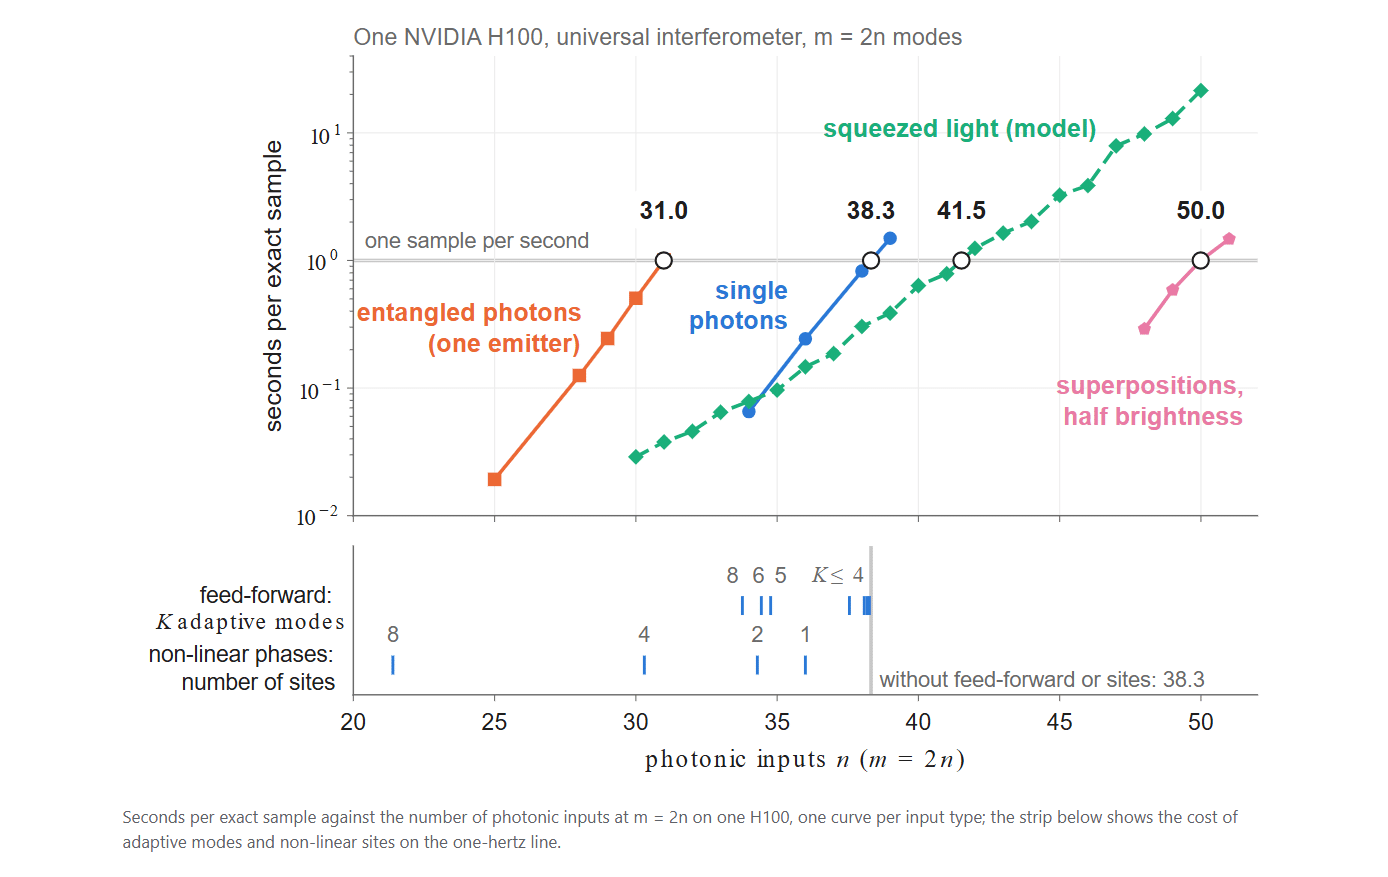
Quandela, CNRS, and NVIDIA have established a "simulability frontier" for photonic quantum processors using NVIDIA H100 GPUs. Their research defines a unified metric for when quantum processors outperform classical simulations, moving beyond varying photon count thresholds. They've also released an open-source library, photonic-engines, to support this work.
Memory bottlenecks are emerging as one of the costliest problems in AI infrastructure as inference overtakes training. GPUs sit idle waiting on data, while high-bandwidth memory, or HBM, stays bolted to processors that cannot share it. Photonics is shaping up as one way out. Marvell Technology Inc. has been pairing optics with photonic memory to
To avoid scheduling delays when running concurrent workloads on a GPU, Streaming Multiprocessor (SM) partitioning mechanisms such as CUDA Green Contexts restrict each workload to separate SMs. Despite this partitioning, concurrent workloads still significantly slow down latency-critical workloads, which recent studies attribute to shared L2 cache and memory contention. However, contention also occurs at the crossbar ports connecting each Graphics Processing Cluster (GPC) of…
Universities racing to build AI infrastructure are learning that raw compute changes the pace of science itself, from molecular discovery to materials engineering. AI and high-performance computing are converging, and campus technology leaders are now building like cloud operators. The Texas A&M University System is standing up two major clusters for researchers across its 12
GPU giant puts on a brave face for investors, while analysts say doubts remain over the company's future
Every instruction in NVIDIA's native GPU ISA (SASS) carries a control code that guides hardware scheduling, and prior work has decoded its known fields to optimize GPU kernels. However, one control-code field remains unexplored: it appears over 500000 times in NVIDIA's closed-source libraries such as cuBLAS and cuDNN, yet nvcc never emits it when compiling user programs. This paper presents the first systematic study of this control-code field across GPU architectures from…
AI coding agents have become one of the most popular applications of large language models. Yet, agentic AI comes at the cost of a tremendous amount of GPU compute resources, which limits its profitability and its viability at scale. In this paper, we investigate whether smaller, cheaper models can cut this cost without sacrificing accuracy. We evaluate 36 popular large and small open-weight models released since 2024 on a software engineering benchmark, and find that recent…
The new deployment brings together AMD Instinct MI350X GPUs, AMD EPYC processors as well as the AMD ROCm software ecosystem.
Edge devices in vehicles and robots serve concurrent requests with different deadlines to a vision-language model (VLM), each mixing a compute-bound encoder and prefill with a memory-bound decode. GPU serving targets datacenter throughput with per-iteration host scheduling: an urgent request waits for the running iteration, and small-batch decode costs much energy per token. Prior accelerators on Versal AI Engine (AIE) SoCs map one model onto a fixed AIE dataflow graph for…