Results for “Agent”

arXiv (research papers) Shiyu Fang

CoopDistill: Equilibrium-Guided Multi-Agent Policy Distillation for Cooperative Driving

Cooperative driving extends autonomous driving from individual vehicle decisions to joint maneuvers that improve traffic safety and efficiency. Optimization-based methods impose safety constraints but often fix paths to simplify multi-vehicle planning, limiting spatial flexibility. Multi-agent reinforcement learning (MARL) explores alternatives through interaction, but coordinated learning and safe execution remain challenging. Their integration nevertheless faces challenges…

Read at arXiv (research papers)

MIT Technology Review AI MIT Technology Review Insights SI

Building AI that can work across the enterprise

For years, enterprises have approached AI as a series of discrete experiments. Now, as AI agents begin to move into the workflows that run the business, that model is starting to look inadequate. Organizations moving from isolated pilots toward AI agents and autonomous workflows are confronting a deeper challenge: rethinking how data, business processes, governance,…

Read at MIT Technology Review AI

NASA Science Patricia Tyler Space

AI/ML STIG Lecture Series, 30 Nov 2026

Ethics and Challenges of Agentic AI Speaker Paul Ginsparg, Cornell University Meeting Connection Join the Lecture

Read at NASA Science

Crunchbase News Judy Rider Startups

In The AI Era, Keep Hiring New College Grads — And Make Them Managers From Day One

As AI takes over entry-level knowledge work, guest authors Bob Morse of Strattam Capital and Michael Quoia of KSE Leadership argue that these workers should begin their careers managing AI agents, developing skills in delegation, oversight and judgment traditionally learned later.

Read at Crunchbase News

Ukrainska Pravda Ivan Diakonov

Russians detain Sumy native in Crimea for alleged work for Ukrainian intelligence

Russian FSB agents have remanded a 55-year-old Sumy native in custody in the Simferopol district amid a sharp surge in fabricated treason cases across occupied Crimea in 2026.

Read at Ukrainska Pravda

arXiv (research papers) Guanqi Lyu Security

ProcReverser: Multi-Agent Black-Box Microarchitectural Reverse Engineering for Processor Vulnerability Analysis

When processor implementation details are unavailable, black-box microarchitectural reverse engineering helps security researchers identify hardware conditions related to security vulnerabilities. However, this process requires substantial manual effort to design experiments, develop test programs, and analyze results for each processor. We present ProcReverser, a multi-agent system that automates this process. ProcReverser uses execution feedback to improve experimental…

Read at arXiv (research papers)

arXiv (research papers) Zhe Dong

Building Fully On-Device GUI Agents with Mobile NPUs

Mobile GUI agents are increasingly used to automate everyday smartphone tasks, but most existing systems still rely on cloud-hosted models or remote inference, introducing repeated communication latency, privacy exposure, and dependence on network availability. Modern smartphones integrate neural processing units (NPUs) that provide an attractive substrate for fully on-device LLM inference. However, directly deploying conventional GUI-agent pipelines on mobile NPUs is…

Read at arXiv (research papers)

ReliefWeb International Committee of the Red Cross

World: From Principles to Practice – AI in Humanitarian Organizations (AI Alignment Guideline, 2026)

Country: World Source: International Committee of the Red Cross Please refer to the attached file. This practical guide helps humanitarian organization integrate the principles of humanity, impartiality, neutrality and independence into the design, deployment and use of AI systems, with a focus on large language models and agentic AI. Building on existing AI policy and ethical guidelines, it helps humanitarian practitioners explore, assess and improve the alignment of AI…

Read at ReliefWeb

MarkTechPost Michal Sutter SI

Hark Releases Handoff², a 2x Faster Computer-Use Agent for Hark Pro

Hark has released Handoff², the computer-use agent inside Hark Pro. It averages 2x faster than v1, completes 82% of 478 internal web tasks, and learned to batch actions through latency-penalized RL.

Read at MarkTechPost

The Guardian World Penry Buckley NSW state reporter Geopolitics

NSW halts new law to crack down on underquoting by real estate agents at 11th hour

Backdown is one of several premier Chris Minns has announced in recent weeks as state prepares for election in March Get our breaking news email, free app or daily news podcast The Minns government has mothballed laws intended to protect homebuyers from underquoting after the premier said real estate agents in his Sydney electorate had raised concerns about their effect amid a housing market downturn. Changes due to come into effect on Tuesday would have banned agents in New…

Read at The Guardian World

arXiv (research papers) Kangwen Zhao SI

GainCtrl: Predicting Remaining Gains for Efficient LLM Agent Execution

Large language models (LLMs) are widely used to power agents that interact with tools and environments to solve complex tasks. Repeated attempts improve the quality of tool-using agents, but continued execution incurs additional costs even when it is unlikely to improve the best result ultimately returned. This raises the question of when to stop an attempt to reduce execution cost while preserving task-level Best-of-N quality. To address this question, we introduce…

Read at arXiv (research papers)

arXiv (research papers) Sachin Gupta SI

AgentFaultBench: State-Verified Evaluation of Tool-Fault Recovery

Does recovery advice help an agent finish a task after a tool fails? AgentFaultBench evaluates LangGraph and CrewAI agents performing specified tasks in an isolated GitLab installation. We inject tool errors and check both the resulting files and issues and the required reads, verification and final response. The prompt supplies the expected issue and report text, so the task tests execution rather than content generation. In the primary comparison of 1,944 planned runs…

Read at arXiv (research papers)

Semiconductor Engineering Ed Sperling SI

Are AI Agents The New Semiconductor IP?

Agents are emerging as reusable design tools, but trust and use models remain challenging.

Read at Semiconductor Engineering

arXiv (research papers) Wenhan Yu SI

VIVID: A Visual Harness for Agentic Video Editing

Video editing requires agents to make editing decisions grounded in audiovisual observations and precise temporal localization, and to evaluate their effects in rendered outputs. General-purpose coding agents possess strong comprehension, reasoning, and code execution capabilities, while media interaction and evidence management mechanisms tailored to video tasks can further unlock their editing potential. We introduce VIVID, a visual harness that supports multiple native…

Read at arXiv (research papers)

arXiv (research papers) Fengmin Wu Tech policy

UbiHearo: Bringing Scenario-Aware Sound Guidance to DHH Users with Mobile Agents

For Deaf and Hard-of-Hearing (DHH) users, effective sound awareness goes beyond detecting \emph{what} sound occurs; it requires understanding \emph{what it means}, \emph{how urgent it is}, and \emph{what to do}. However, existing mobile assistants largely reduce acoustic scenes to isolated labels or generic alerts, failing to provide contextual guidance when the same sound implies different risks across scenarios. We present \sysname, a mobile hearing assistant agent that…

Read at arXiv (research papers)

The Hacker News Security

Amazon Uncovers AI Agent Campaign Targeting LiteLLM, Dify, and Other Apps for API Keys

Attackers' AI agents have been hunting for weak spots in internet-exposed AI apps such as LiteLLM, One API, and Dify to steal the AI provider keys stored inside, according to the agents' own records. The records, which Amazon's threat intelligence team captured with decoy servers, describe stolen keys being used to run the AI models that powered the search for more keys. The team said this

Read at The Hacker News

arXiv (research papers) Yongkang Xiao Security

MASTA: A Feedback-Scheduled Multi-Agent System for End-to-End Tamarin Modeling and Analysis

Tamarin-based formal verification of security protocols requires expert-authored multiset rewriting rules and temporal-logic lemmas. Translating a natural-language protocol description into a complete formal model with an LLM is hard because syntactic, reachability, and property-level errors compound across the multi-step modeling process, and a single agent that both authors and self-evaluates cannot reliably localize them. We present MASTA, a multi-agent system that…

Read at arXiv (research papers)

arXiv (research papers) Nicola Fabiano Tech policy

Who Bears the Excess? Imputing the Acts of AI Agents to Those Who Delegate

When an AI agent acts outside the authority conferred on it, the actor is not a legal subject and the legal subjects did not act. The literature of 2026 agrees that the agent cannot bear responsibility and that the burden falls on those who deploy it, but it leaves open where that duty sits in positive law and how it is proved. This paper proposes a rule of imputation. The excess is imputed to whoever conferred the delegation, to the extent of the perimeter it documented and…

Read at arXiv (research papers)

arXiv (research papers) Michael Kingston SI

Instrumenting Failure: Scoring Language Model Agents at Every Decision Node in Imperfect-Information Games

Agent evaluations report task success and rarely say what an agent did at each decision. We score every decision node of three 12B to 14B instruct-tuned language models (LMs) playing five zero-sum imperfect-information games against four opponents on eight properties from decision and game theory, five of them against a CFR+ equilibrium reference. At each node, the LM also states a belief about the opponent's hidden state in a separate call. Without memory and at temperature…

Read at arXiv (research papers)

Help Net Security Mirko Zorz Security

You can now self-host Kitesurf, Cloudflare’s open-source browser for AI agents

Kitesurf is Cloudflare’s browser for AI agents, built to load web pages and run their JavaScript on Cloudflare Workers without starting up a full desktop browser. Cloudflare has published its source code so developers can inspect it, modify it, test it on their own machines, and deploy a copy to their Cloudflare account. A browser without Chromium Kitesurf needs no browser container, and it can return screenshots of the pages it loads. It supports the … More →

Read at Help Net Security

arXiv (research papers) Runzhe Wang SI

AdMem: Expectation-Grounded Procedural Memory for Long-Horizon Task-Solving Agents

An agent that carries memory across tasks is only as good as the entries it keeps. We begin from an observation that is easy to reproduce and uncomfortable for the field: naively accumulating cross-task experience can make an agent \emph{worse} than one with no memory at all. On AgentBoard, a workflow-induction memory solves fewer tasks than a memoryless ReAct agent in seven of eight domains, and a per-step procedural store with no surrounding structure loses half of ReAct's…

Read at arXiv (research papers)

OpenAI News SI

More ways to move care forward with ChatGPT for Healthcare

Introducing computer-use agents, improved clinical answers, and new healthcare plugins that work across healthcare software to get real work done.

Read at OpenAI News

arXiv (research papers) Ke Shen SI

ToolGraph as a Q-Function for Test-Time Scaling of Tool-Use Agents

Tool-use agents must chain interdependent calls, yet which outputs satisfy which later inputs in a deployed catalog is not something a general-purpose language model reliably infers from tool descriptions alone. We compile that structure once into a reusable external representation. ToolGraph is a directed, weighted dependency graph over a tool catalog: parameter matching and interventional probes, which execute a candidate chain with and without its proposed predecessor…

Read at arXiv (research papers)

arXiv (research papers) Chaitanya Garware Security

Beyond the Patch: Reconstructing an Incomplete-Fix Patch Bypass in LLM Agent Frameworks with Control-Gated, Benign Probes

Replaying a vulnerability's original proof-of-concept after patching tests whether its reported trigger remains reproducible, but does not establish that the underlying security invariant holds on other code paths. We present a benign, control-gated reconstruction method and a pilot study across four LLM agent frameworks and four invariant classes. For PraisonAI, we compare original-trigger replay (B0) with a distinct sibling-path probe (M). We also perform five before/after…

Read at arXiv (research papers)

arXiv (research papers) Marjan Beheshti Security

KVMARK: Fragile Watermarking for KV-Cache Integrity in Latent Multi-Agent Systems

Latent multi-agent communication directly transfers Key-Value (KV) cache tensors between transformer-based agents, bypassing text serialization entirely. While computationally efficient and reasoning accurate, this communication channel is opaque and vulnerable to man-in-the-middle tampering, a threat vector unaddressed by existing text-based or behavioral watermarks, which cannot operate on continuous internal representations. To address this vulnerability, we propose…

Read at arXiv (research papers)

CBS News

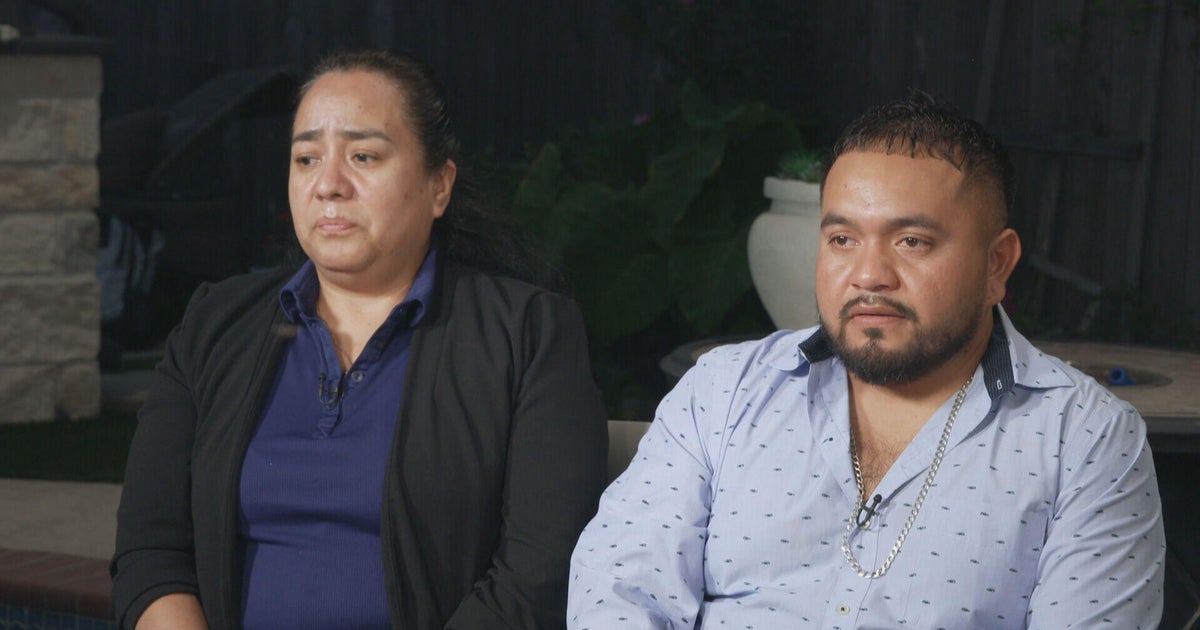
Siblings of man run over by ICE agent say incident was "intentional"

Miguel Parra Hernandez was hit by Immigration and Customs Enforcement agent Mario Alberto Morales in Houston on Oct. 10.

Read at CBS News

CBS News

Siblings of man run over by ICE agent allege that "it was not an accident"

Last month, an Immigration and Customs Enforcement agent in an unmarked SUV struck and injured a Mexican construction worker. Now, his siblings are speaking with Camilo Montoya-Galvez about the incident, alleging that "it was not an accident."

Read at CBS News

arXiv (research papers) Chang Xu Security

Where the Evidence Lives: Measuring Privacy and Diagnosability of Exported AI-Agent Traces

Execution traces help diagnose AI-agent failures, but sharing them can expose customer identities. For example, detecting that an agent handled the wrong customer's records requires knowing whether the records belong to the requested customer, but not necessarily knowing who that customer is. Our executable benchmark measures what a trace export reveals and whether a proposed repair restores the correct output in synthetic multi-tenant workflows. Conventional redaction can…

Read at arXiv (research papers)

Tech in Asia Elyssa Lopez Startups

Grab thinks AI agents can handle grocery shopping. Will SEA bite?

Retailers’ limited margins and expensive AI token costs, however, could hamper its full implementation, analysts say.

Read at Tech in Asia

Older stories